Delta Lake: A Transaction Log Format That Depends on Storage Guarantees
Project brief: An open-source storage framework that enables building a Lakehouse architecture with compute engines including Spark, PrestoDB, Flink, Trino, and Hive and APIs.
At a glance
- What is it?
- Delta Lake is an open-source storage framework that adds ACID transactions, schema enforcement, and time travel to data lakes, with connectors for Spark, Flink, PrestoDB, Trino, and Hive. The core value is the transaction log protocol, but adopting it means accepting storage system requirements and a protocol that can break forward compatibility.
- Who is it for?
- Adopt Delta Lake if you run Spark-centric data pipelines and need ACID transactions on cloud object storage, and you can live with the storage system's atomic visibility and mutual exclusion requirements. Do not adopt it if your storage cannot guarantee atomic file visibility or consistent listing, or if you need forward compatibility for older readers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
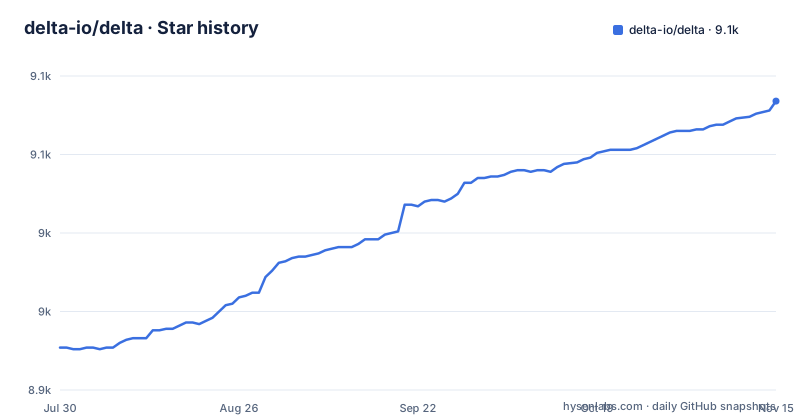
- delta-io/delta9,084 ★ · +157
| Repository | 2026-07-30 | 2026-11-15 |
|---|---|---|
| delta-io/delta | 8.9k | 9.1k |
157 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Data Lakes Without Transactions
Data lakes built on object storage like S3 or ADLS have a well-known weakness: they lack the transactional guarantees of a database. Concurrent writers can overwrite each other, readers can see partial writes, and schema drift can corrupt downstream jobs. Delta Lake addresses this by adding a transaction log, a write-ahead log that records every change to a table. The framework is aimed at teams building a Lakehouse architecture, where the same storage serves both BI workloads and machine learning pipelines. The target user is a data engineer who already uses Spark or another engine and wants ACID semantics without moving to a proprietary warehouse. The README lists Spark, PrestoDB, Flink, Trino, and Hive as supported engines, which signals a deliberate multi-engine strategy. But the transaction log is the real product, not the connectors.
The Transaction Log Protocol: How Delta Lake Works
The core mechanism is the Delta Transaction Log Protocol, specified in PROTOCOL.md. The protocol defines a Protocol action that carries minimum reader and writer versions, and breaking changes in the protocol are indicated by incrementing them. The README states that backward compatibility is guaranteed, meaning newer versions always read older tables. But forward compatibility is not: an older version may not read a table written by a newer version. This is a deliberate trade-off, and it means upgrading Delta Lake is not optional if you want to use new features. The protocol is public and documented, which is a strength: you can implement a reader without using the full Spark integration.
Storage Requirements: The Hidden Cost of ACID
Delta Lake's ACID guarantees are not free. The README is explicit about three requirements for the underlying storage system: atomic visibility, mutual exclusion, and consistent listing. Atomic visibility means a file must appear in full or not at all. Mutual exclusion means only one writer can create or rename a file at the final destination. Consistent listing means once a file is written, all future directory listings must include it. These are strong guarantees. Not every storage system provides all three. If your storage does not meet these requirements, Delta Lake cannot provide transactional guarantees, and the framework will not work as documented. This is a critical constraint to verify before adoption. The README points to the online documentation on Storage Configuration for details, but the core requirement is clear: you cannot bolt Delta Lake onto a filesystem that lacks atomic rename semantics. For a team using a local HDFS cluster, the guarantees may hold, but for a custom object store, they may not.
Getting Running: Commands and Configuration
The README points to a Quick Start Guide for Scala, Java, and Python. The typical path is to add the delta-spark package to your Spark session. For Python, the README links to the PyPI project delta-spark, so the command is likely pip install delta-spark. The most recent releases are v4.4.1, v4.4.0 and v3.3.3. The API is exposed through Spark's DataFrameReader and Writer: you use spark.read.format("delta").load(path) and df.write.format("delta").save(path). The README confirms that these Spark-based APIs are stable within a major release, meaning options will not break between minor versions. For Scala and Java projects outside Spark, the README points to the Delta Standalone library, a single-node Java library that implements the transaction log protocol directly. The README describes it as providing APIs to interact with a table's metadata, which is useful for Flink or Hive integration.
Concurrency Control: Serializability and Its Limits
Delta Lake claims to ensure serializability for concurrent reads and writes, according to the README. Serializability is a strong isolation level, meaning the result of concurrent transactions is equivalent to some serial order. The README points to a separate concurrency control document, but the key point is that the storage requirements are what make this work. Mutual exclusion prevents two writers from creating the same file, and atomic visibility ensures readers never see partial commits. Every write must be recorded in the transaction log, so for very high write throughput it is worth testing how the log behaves under your concurrency pattern.
API Compatibility: Stable Public APIs, Internal Churn
Delta Lake makes a clear distinction between stable public APIs and internal classes. The direct Java, Scala, and Python APIs documented in the API docs are stable. Everything else is internal and subject to change across releases. The Spark-based APIs, such as DataFrameReader and Writer options, are stable within a major release. This is a practical approach: it protects users who rely on the high-level interface while allowing the project to evolve internals. This is a promise that minor version upgrades will not break your existing read and write code. However, the README does not say how long a major release is supported. The release list shows v4.4.0 and v3.3.3, which suggests parallel maintenance lines. That is a maintenance cost: you need to track which line matches your Spark version. The README points to an online releases page for compatibility with Spark versions, which is the authoritative source. This is not a project you can ignore after installation; you must track version updates.
Alternatives: Iceberg and Hudi Take Different Paths
The main alternatives to Delta Lake are Apache Iceberg and Apache Hudi. Iceberg also uses a table format with a metadata layer, but it separates the metadata from the data files and uses a catalog to track table snapshots. The key difference is that Iceberg's metadata is managed through a catalog, which can be a Hive Metastore or a REST catalog, whereas Delta Lake stores the transaction log inside the table directory. That means Delta Lake does not require a separate catalog service, which is simpler to deploy. Hudi, on the other hand, focuses on record-level updates and incremental processing, with a different write path that uses base and log files. For a team that already uses Spark heavily, Delta Lake is the most direct integration. For a team that needs a catalog-based approach or has existing Iceberg infrastructure, the difference is significant. The repository tree does include iceberg/ and hudi/ directories, so check what interoperability the current release offers before treating the formats as exclusive.
Maintenance and License: What You Sign Up For
Delta Lake is licensed under Apache-2.0, which is permissive and allows commercial use without copyleft obligations. The project is actively maintained, with a recent release v4.4.1 in October 2026 and a default branch of master. The repository is not archived, and the last push is recent. Maintenance cost comes from the versioning scheme: you must align Delta Lake releases with your Spark version, and the README warns that forward compatibility can break. That means you cannot use a new feature without upgrading all readers, which is a coordination burden. The README also mentions that internal APIs are subject to change, so if you rely on any class not in the documented API, you must expect breakage. The Roadmap section points to external links, with the high-level roadmap labelled Delta Lake 2022H1. The community and contributing sections are standard, but the key takeaway is that this is a fast-moving project with a clear protocol, and you should treat the version compatibility matrix as a critical maintenance document.
Editorial conclusion
Adopt Delta Lake if you run Spark-centric data pipelines and need ACID transactions on cloud object storage, and you can live with the storage system's atomic visibility and mutual exclusion requirements. Do not adopt it if your storage cannot guarantee atomic file visibility or consistent listing, or if you need forward compatibility for older readers. Before committing, verify your storage meets the three stated guarantees, check the compatibility matrix for your Spark version, and test the transaction log behavior under your exact concurrency pattern.
Frequently asked questions
Does delta-io/delta guarantee backward compatibility?
In the direction that matters for reading old data, yes: newer versions of Delta Lake can always read tables written by older versions. Forward compatibility is explicitly reserved to be broken, and breaking protocol changes are signalled by incrementing the minimum reader and writer version in the Protocol action.
Which compute engines can write to Delta Lake?
Spark reads and writes, Trino reads and writes, and Delta Standalone gives Scala and Java projects both directions. Apache Flink is marked Preview and write only, while PrestoDB and Apache Hive are read only.
What does delta-io/delta require of the underlying storage?
Three things, because the ACID guarantees depend on them: a file must be visible in its entirety or not at all, only one writer must be able to create or rename a file at the final destination, and once a file is written in a directory all future listings of that directory must return it.
How do I install delta-io/delta?
The README sends you to the documentation and its Quick Start Guide. The Python distribution is published as delta_spark, with PySpark bounded between 4.0.1 and 4.2.0 and Python 3.10 or newer required.
Where is the Delta Lake protocol specification?
In this repository. PROTOCOL.md specifies the transaction protocol, and the compatibility section states the reading guarantees and how a breaking change is signalled through the Protocol action's minimum reader and writer version.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/delta-io-delta)Star history chart for your README
[](https://hysenlabs.com/projects/delta-io-delta)Was this useful?