AutoMergePublicNodes: a Python pipeline that harvests and merges public proxy nodes
Automatically scrapes and merges public proxy nodes from the internet: free nodes and subscriptions for v2ray, SSR and Clash, free VPN/proxy access for ss, v2ray, trojan and clash, plus Google Play access.
At a glance
- What is it?
- AutoMergePublicNodes is a fork of NoMoreWalls that scrapes public proxy nodes, merges them into list.txt and list.meta.yml, and ships Clash routing rules. It suits readers who want a self-hosted subscription feed and can tolerate a repository whose licence is not a standard SPDX identifier.
- Who is it for?
- Adopt it if you want a self-hosted merge pipeline rather than a hand-curated node list, and if you accept that the licence is a custom anti-996 text rather than a standard SPDX identifier. Do not adopt it if you need a supported commercial service, an SLA, or a subscription your organisation can audit against a recognised open source licence.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
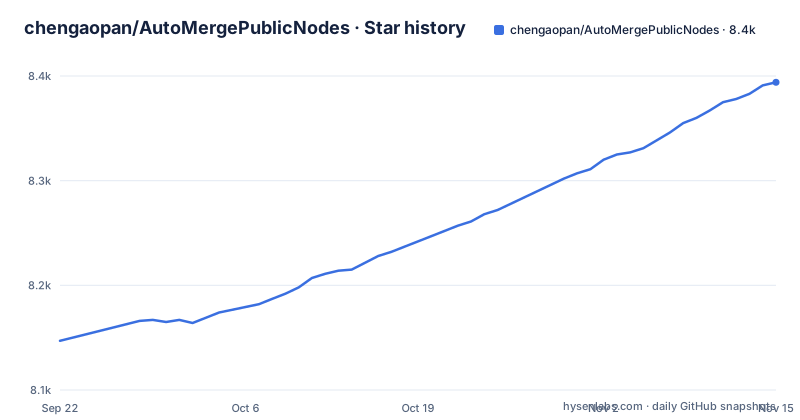
Star history
- chengaopan/AutoMergePublicNodes8,394 ★ · +247
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| chengaopan/AutoMergePublicNodes | 8.1k | 8.4k |
247 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What AutoMergePublicNodes actually collects
The repository describes itself as automatically fetching and merging public nodes from the internet. That is the whole product: a scheduled job that pulls node data from sources listed in sources.list, normalises it, and writes the result to list.txt, list.meta.yml, list.yml and list_raw.txt. The README states the project is a fork of NoMoreWalls and asks readers to star the upstream project first, so the merge logic and much of the configuration design originate upstream rather than here.
The audience is narrow but real. You are the target user if you already run Clash Meta or a compatible client and you want a subscription URL you control, refreshed on a schedule, rather than a link someone else maintains. The README also markets the project to people who want free access to blocked sites, but the mechanics are a data pipeline, not an access service. Nothing here provides a server. It aggregates endpoints that already exist somewhere else on the public internet, and the quality of your connection is the quality of whichever of those endpoints happens to be alive when your client connects.
The fetch, merge and publish loop
Two Python files carry the work. fetch.py is the entry point described in the local deployment steps. dynamic.py and config.yml sit alongside it, and fetch_config.yml holds fetch-level settings. The dependency list is short: PyYAML, requests, requests-file and typing_extensions, which tells you the pipeline is HTTP fetching plus YAML parsing, with requests-file allowing file:// URLs to be read through the same code path as remote ones.
The data flow is linear. Sources are read and the merged set is emitted in several formats. list.txt is the Base64 subscription that clients consume directly. list.meta.yml is the Clash Meta configuration, and the README notes that plain Clash users should replace the trailing .meta.yml with .yml in the subscription URL. The snippets/ directory holds fragments split out of list.meta.yml so that you can graft the project's routing rules into a configuration you already maintain. That split is the most useful design decision in the repository: it means the routing rules are reusable even if you do not want the node list.
A GitHub Actions workflow at .github/workflows/fetch.yml runs the fetch on a schedule, and the README displays its status badge. So the published list is refreshed by CI, not by your machine, unless you run it yourself.
Installing it locally and running fetch.py
The README gives an explicit local deployment sequence. Clone with a shallow history first, because the README warns that the full commit history is very large.
git clone https://github.com/chengaopan/AutoMergePublicNodes.git --depth=1Then install the four dependencies from requirements.txt.
pip install -r requirements.txtThe README then branches on your network situation. If you are not behind a blocking network, or you are already running TUN mode or a transparent proxy, it tells you to skip ahead to the final fetch step. Otherwise you need a working HTTP or HTTPS proxy before the fetch can reach its sources. The README's procedure is to create an empty local_proxy.conf, run fetch.py once, import the generated subscription into your proxy client and configure it, then write the proxy address into that file.
http://127.0.0.1:7890/After that, running fetch.py again produces the complete subscription. The README is explicit that if your local clone is stale you should delete the directory and re-clone rather than run git pull, because the history makes pulling impractical. That is an unusual instruction and worth taking literally: the project treats a local checkout as disposable.
Subscription URLs and the mirror problem
The README lists several ways to consume the published output, and the list itself is a warning about availability. The raw.githubusercontent.com URLs are the canonical ones. GhProxy.cn mirrors are offered as an alternative. Then there is a set of jsDelivr URLs across Fastly, Cloudflare and GCore, described as possibly not the newest but never blocked.
That trade-off is stated plainly, and it is the honest part of the documentation. A CDN-cached copy of list.meta.yml can lag the CI run, so you may be importing nodes that were already removed upstream. The README's own instruction is to try every link from top to bottom if the subscription fails to update. For a tool whose value depends on node freshness, a caching layer that guarantees availability at the cost of staleness is a genuine compromise, not a footnote.
The Sing-Box path is different in kind. The README points to a third-party conversion service and states directly that it does not support this project's node selection or routing rules. If you use Sing-Box through that link, you get the nodes and lose the routing logic that the project spends most of its README explaining. That is a meaningful downgrade, and the documentation says so.
The routing rules are the part worth keeping
The Clash configuration is not a flat proxy list. The README describes designed routing rules, automatic detection of blocked domains, and a Google Play download path. It names specific policy groups: keeping the catch-all group on DIRECT, and switching a suspected-domestic group to a proxy selector if you hit a redirect to an anti-fraud page, a problem the README attributes to unregistered domains being blocked by Jiangsu Telecom and China Mobile.
The project also blocks BootCDN and Staticfile, citing a report that those services were acquired by a company it calls a virus company, and it exposes a virus-site category you can switch to DIRECT. The README attaches an explicit risk warning to that switch, listing ad harassment, account theft and device infection. Whatever you think of the framing, the mechanism is a routing rule with a documented escape hatch and a documented cost.
This is where the snippets/ directory earns its place. If you already have a Clash configuration you trust, you can lift the routing fragments rather than adopt the whole subscription. The README presents snippets as the way to integrate the project's configuration into your own, which is a more defensible use than replacing your entire client config with a list of endpoints of unknown provenance.
Where this pipeline breaks down
The first limitation is structural. Every node in the output comes from somewhere else on the public internet, and the project has no control over whether any of them are operated honestly. A public proxy endpoint sees your traffic. The README's own argument against paid providers, that they can collect and resell personal information, applies with equal force to free endpoints whose operators are unknown. The project does not claim to vet them, and the disclaimer states that all resources come from the internet and that the project takes no responsibility for illegal use.
The second limitation is operational. The README says the project is time-sensitive and that old versions are basically unusable, which is why forks are told to sync and stale clones are told to be deleted. A pinned or vendored copy of list.meta.yml decays. If your workflow depends on a frozen artifact, this is the wrong tool.
The third is licensing. The badge and README refer to an Anti 996 licence, and the repository's LICENSE.md is a custom text rather than a standard SPDX identifier. The README states the licence strictly forbids use by companies operating a 996 work schedule. That is a use restriction, and it is the kind of term that needs reading before adoption in a corporate setting, not skimming.
Compared with a maintained commercial subscription
The obvious alternative is a paid proxy subscription, and the README argues against it at length: payment risk if the operator disappears, account registration that exposes personal data, and a small node pool where a single block removes everything. Its counter-argument is volume, claiming the merged public pool is roughly ten times the size of a paid subscription and therefore more likely to retain survivors.
The difference in approach is real. A commercial subscription is a curated, small, operated set with a support channel and a billing relationship. AutoMergePublicNodes is an uncurated, large, automated set with no operator and no support. The first trades money for accountability; the second trades accountability for redundancy. Neither is strictly better, and the choice depends on whether you need someone to complain to when a node dies.
A closer alternative is simply running the upstream NoMoreWalls repository, which this project forks. The README directs readers to star upstream and points to an upstream mirror page, noting that the mirror serves upstream data rather than this repository's. If the fork adds nothing you need, upstream is the smaller dependency.
Maintenance reality and what to verify
The repository is not archived, and the last push was on 2026-11-02. That is a strong recency signal for a project whose output decays quickly, and it is consistent with the scheduled Actions workflow the README badges. The repository has no published releases. You can pin the source to a Git commit, but the public proxy data fetched by the pipeline can still change or become stale.
Upgrade cost is therefore low in the mechanical sense and high in the attention sense. A pinned commit can make the source reproducible, but updating it still requires checking for changes in configuration and behavior. There is instead a standing requirement that the fetch keeps running, either through the project's CI or through yours. If you fork it, the README asks you to sync regularly, and the local workflow asks you to re-clone rather than pull.
On licensing, the custom anti-996 text is not a standard identifier, and the README states it prohibits use by companies running 996 schedules. Whether that term binds your organisation is a question for someone qualified to answer it. What can be said without legal advice is that a non-standard licence with a conduct-based restriction is harder to clear internally than MIT or Apache-2.0, and that this friction is part of the adoption cost.
Editorial conclusion
Adopt it if you want a self-hosted merge pipeline rather than a hand-curated node list, and if you accept that the licence is a custom anti-996 text rather than a standard SPDX identifier. Do not adopt it if you need a supported commercial service, an SLA, or a subscription your organisation can audit against a recognised open source licence. Before wiring it into anything, run fetch.py once locally with a working proxy and confirm that list.txt and list.meta.yml are regenerated, then check the LICENSE.md terms against your own employment and redistribution situation.
Frequently asked questions
How do I install AutoMergePublicNodes and run it locally?
Clone the repository with --depth=1, since the README warns the full commit history is very large, then run pip install -r requirements.txt. If your network needs a proxy, create local_proxy.conf, run fetch.py once, write your proxy address into that file in the form http://127.0.0.1:7890/, then run fetch.py again to produce the subscription.
What is the difference between list.txt and list.meta.yml in AutoMergePublicNodes?
list.txt is the Base64 subscription format for clients that consume a plain subscription URL. list.meta.yml is the Clash Meta configuration, and the README says users of the original Clash should replace the trailing .meta.yml in the subscription URL with .yml.
Does AutoMergePublicNodes work with Sing-Box?
The README offers a third-party conversion link for Sing-Box but states that it does not support this project's node selection or routing rules. Using that path means you get the merged nodes without the routing configuration the project provides.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chengaopan-automergepublicnodes)Star history chart for your README
[](https://hysenlabs.com/projects/chengaopan-automergepublicnodes)Was this useful?