darkdevil3610/100-AI-Machine-learning-Deep-learning-Computer-vision-NLP: A Link Index, Not a Codebase
100+ AI Machine learning Deep learning Computer vision NLP Projects with code
At a glance
- What is it?
- The repository markets itself as 100+ AI projects with code, but the README is a numbered table of outbound links to other people's repositories and blog posts. Here is what that means for anyone deciding whether to clone it.
- Who is it for?
- Adopt this only as a bookmark list if you are a student or career switcher hunting for a final-year project idea and you are willing to open each entry to check whether it still resolves. Do not adopt it if you need runnable code, pinned dependencies, or a reproducible environment, because the README does not supply any of those.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
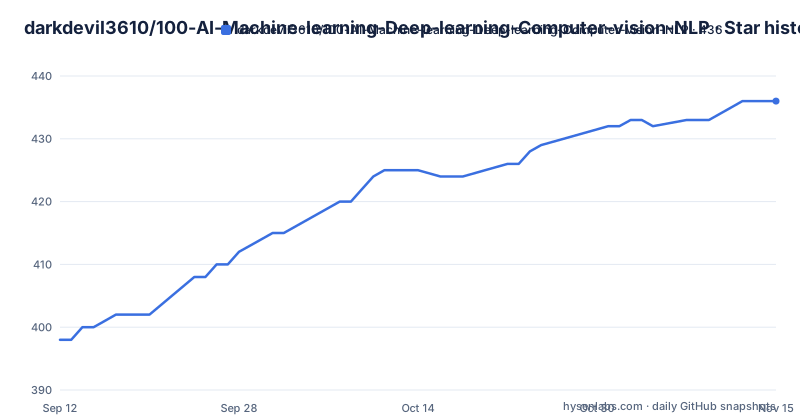
Star history
- darkdevil3610/100-AI-Machine-learning-Deep-learning-Computer-vision-NLP436 ★ · +38
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| darkdevil3610/100-AI-Machine-learning-Deep-learning-Computer-vision-NLP | 398 | 436 |
38 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the repository actually is
The name promises 100+ AI, machine learning, deep learning, computer vision and NLP projects with code. The README does not deliver that. It delivers a table. The header banner reads "100 AI + ML + DL Projects" with a subtitle about "a decade of real-world AI experience in one repository," and the body text repeats the pitch as "100 + AI Machine learning Deep learning Computer vision NLP Projects with code !!!" Below that, the content is a single numbered table with columns Sr No, Name and Link, where every Link cell is a pointing-hand emoji hyperlinked to an external destination. Row 1 points to ashishpatel26/365-Days-Computer-Vision-Learning-Linkedin-Post. Row 2 points to ashishpatel26/Treasure-of-Transformers. Row 4 points to a Medium article about time series forecasting. Row 24 points to data-flair.training. The repository does not contain any first-party source files, notebooks or directories. So the honest description is: a curated index of AI learning resources, hosted under a repository that reads like a portfolio page. The audience implied by the topics list is students and job seekers. Tags include collageproject (a misspelling of college project), final-year-project and final-year-projects, alongside streamlit, yolo and yolov11. Those tags describe the subject matter of the linked material, not the contents of this repository. If you arrived expecting to clone and run something, the first thing to verify is whether any code exists at all outside the README.
The link table and its six category blocks
Above the table, the README lays out six categories in an HTML table, each with a short description. Machine Learning covers "traditional algorithms, ensemble methods, statistical modeling, feature engineering, and advanced regression/classification pipelines." Deep Learning lists "CNNs, RNNs, LSTMs, GANs, Transformers, Autoencoders." Computer Vision covers "real-time image processing, object detection, segmentation, pose estimation, and visual anomaly detection." NLP covers "contextual embeddings, sentiment analysis, text classification, language modeling." Generative AI covers "LLM integrations, prompt engineering, LangChain pipelines, and RAG-based applications." Hybrid Solutions covers "cross-domain AI integrations." These six blocks are badges and captions, not an index into the numbered table. That matters if you are searching for, say, a RAG example: the category promises one, the table does not label which row provides it, so you would be scanning row names manually. The table itself is heterogeneous. Some rows are GitHub repositories, some are Medium posts by authors such as Aman Kharwal, some are commercial training sites. A row named "All Unsupervised learning Projects" points to an article about unsupervised algorithms rather than a project collection. The naming is loose enough that you cannot infer the destination type from the row title.
Getting it running, and what that phrase means here
There is no install step. The repository has no requirements.txt, no environment.yml, no Dockerfile and no pyproject.toml. Primary language is listed as unknown, and the license field is empty. The only operational action the README describes is cloning or reading it: the text says the list is continuously updated, that you can take pull requests and contribute, and that "All Links are tested and working fine. Please ping if any link doesn't work." That last sentence is the entire maintenance model. There is no CI badge shown, no link-checker configuration, no scheduled job referenced. The homepage field points to http://gourav.is-a.dev/100-AI-Machine-learning-Deep-learning-Computer-vision-NLP/, which the README does not describe or explain, so what renders there is not something I can confirm from this material. The practical commands are therefore the generic ones: git clone the repository and open README.md, or fetch the raw file directly. If you want to contribute a row, the README says pull requests are accepted, but it does not state a format requirement, a row-numbering convention for insertions, or whether entries must be first-party. That absence is itself a constraint on anyone planning to maintain a fork.
Where this breaks down as a tool
Link rot is the obvious failure mode, and the README pre-empts the complaint rather than solving it. "Please ping if any link doesn't work" places verification on the reader. The claim that links are tested is a statement of intent at the time of writing, not a property you can rely on later. A second problem is depth. A row title like "20 Deep Learning Projects Solved and Explained with Python" tells you a count and nothing about difficulty, framework version, dataset availability or whether the code still runs against a current PyTorch or TensorFlow release. You cannot filter the table by framework, by dataset size, or by whether a project needs a GPU. A third problem is licensing. The repository's own license is unknown from the repository metadata, and the linked destinations carry their own licenses, which vary. If you plan to reuse a linked project inside coursework or a product, the license of that upstream repository governs, not this one. Nothing here grants you rights to the linked code, and the README does not discuss the question. Treat the index as a starting point for your own license review, not as a cleared bundle.
How it compares with Awesome lists and with tutorial repositories
The closest structural analogue is the Awesome-list pattern: a README-only repository whose value is curation and whose unit of content is a hyperlink. The difference in approach is that mature Awesome lists usually state inclusion criteria, group entries under headings that match the table, and run a link checker in CI. This repository states no inclusion criteria, and its six category blocks are decorative rather than navigational. The other comparison is a tutorial repository such as the ones it links to, for example ashishpatel26/365-Days-Computer-Vision-Learning-Linkedin-Post or the Medium series by Aman Kharwal. Those carry prose, code and dependencies; you can run them. This repository carries neither. If your goal is to learn by executing, the linked destinations are the product and this index is at best a discovery layer. If your goal is to build a reading list quickly, the index has a real if modest advantage: one file, numbered rows, mixed media, covering classical ML through LLM and RAG topics in a single scroll. That is a genuine convenience and also the whole of the value proposition.
Maintenance, licensing and what a fork inherits
The last push date in the metadata is 2026-09-10, and the repository has no published GitHub releases, which is consistent with a README-only repository: there is nothing to version. Upgrading means re-reading the README, not bumping a dependency. The cost of maintaining a fork is therefore editorial rather than technical. You would be re-checking outbound URLs, deciding whether a dead Medium post should be replaced, and settling the inclusion rules the upstream README never states. That is a few hours a quarter of link checking, not a build pipeline, and the work scales with the number of rows rather than with code complexity. On licensing: the repository metadata does not name a license, so the terms under which the README text itself may be copied are unclear. This is not legal advice, and if you intend to republish the table you should confirm the license with the maintainer rather than assume one. The linked projects each carry their own terms, and the README says nothing about them, so a fork that copies rows inherits a list of obligations it has not audited.
Who should open this repository and who should close the tab
Open it if you are a student looking for a final-year project direction and you want a single page that mixes computer vision, NLP and generative AI pointers without having to assemble them yourself. The topic tags suggest that audience was the intent. Open it if you are assembling a reading list and you accept that each row needs your own verification before you trust it. Close the tab if you need a runnable baseline, a pinned environment, or a dataset you can download today, because none of those are in this repository. Close it too if you need to know the license before you copy anything, since the metadata does not answer that question. The middle case is the interesting one: you might use the numbered table as a checklist and ignore the six category blocks entirely, since the blocks do not index the rows. That is a reasonable way to use the file, and it is also an admission that the marketing framing oversells what is underneath.
Editorial conclusion
Adopt this only as a bookmark list if you are a student or career switcher hunting for a final-year project idea and you are willing to open each entry to check whether it still resolves. Do not adopt it if you need runnable code, pinned dependencies, or a reproducible environment, because the README does not supply any of those. Before relying on it, open the raw README on the main branch, pick three or four rows from the table, and follow the outbound links yourself to confirm they load, since the README's own claim that all links are tested is the only maintenance signal available.
Frequently asked questions
Does the 100 AI Machine learning repository contain any code?
No. The top-level entries are README.md and an images directory, so the repository holds a table of links and no source files. The projects themselves live in the repositories and blog posts that the table points at.
How many projects are listed in this AI machine learning collection?
The repository description and the banner both say 100 plus, and the table numbers its rows with a serial number column. The rows visible in the text run from 1 to 32, and the text cuts off inside row 32, so the full count is not visible here.
Can I contribute to this list of AI projects?
Yes, with links rather than code. The README says the list is continuously updated, invites pull requests, and asks readers to ping the author when a link does not work.
What topics does the What is Inside table cover?
Six areas: classical methods with ensembles and regression pipelines, modern architectures such as CNNs, RNNs, LSTMs, GANs, Transformers and Autoencoders, computer vision work, text work including embeddings and language modeling, LLM integrations with prompt engineering and LangChain pipelines, and cross-domain combinations of all four.
Where else is this list of machine learning projects published?
The repository names a homepage on a personal is-a.dev address that carries the same long project title. There is no separate documentation site and no tagged release history to fall back on.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/darkdevil3610-100-ai-machine-learning-deep-learning-computer-vision-nlp)Star history chart for your README
[](https://hysenlabs.com/projects/darkdevil3610-100-ai-machine-learning-deep-learning-computer-vision-nlp)Was this useful?