LLM-Aided OCR: Post-Processing Tesseract Output with Local or API LLMs
Enhances Tesseract OCR output using LLMs (local or API) for error correction, smart chunking, and markdown formatting of scanned PDFs
At a glance
- What is it?
- This Python project pipes raw Tesseract OCR text through an LLM for error correction, chunking, and markdown formatting. It targets scanned PDFs where plain OCR output is too noisy for downstream use.
- Who is it for?
- Adopt llm_aided_ocr if you already use Tesseract on scanned PDFs and need cleaner, structured text for archival or retrieval, and you can tolerate API costs or have a local GGUF model. Skip it if your scans are clean or you need a production pipeline with formal releases, since the repository shows no tagged releases and the license is marked NOASSERTION, so verify licensing and dependencies before relying on it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
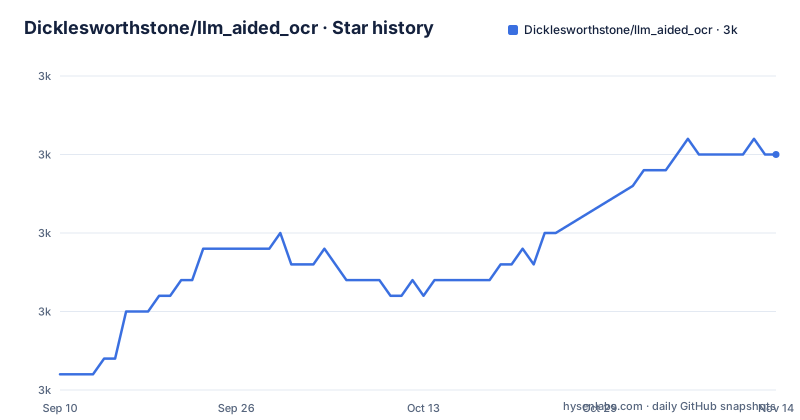
- Dicklesworthstone/llm_aided_ocr3,010 ★ · +14
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Dicklesworthstone/llm_aided_ocr | 3k | 3k |
14 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What It Fixes: Raw OCR Noise in Scanned PDFs
Tesseract produces decent text on clean images, but scanned pages with fonts, smudges, or complex layouts come out with character errors, broken words, and stray headers. This project treats that output as a first pass and sends it through an LLM to repair errors, reflow content, and optionally convert it to markdown. The intended user is someone who has a pile of scanned PDFs, already has Tesseract in the stack, and wants a higher-quality text layer without building a custom correction pipeline. It is not an OCR engine itself; it is a post-processor that assumes Tesseract has already run.
The Pipeline: Images to Tesseract to LLM Chunks
The flow is visible in the README. First, convert_pdf_to_images() uses pdf2image to turn each PDF page into an image, with parameters like max_pages and skip_first_n_pages to limit the run. Then ocr_image() calls pytesseract, but before that it runs preprocess_image(), which converts to grayscale, applies Otsu thresholding, and dilates the image to make text clearer. The raw OCR text is saved as a file. Next, process_document() splits the full text into chunks at sentence boundaries, with overlap between chunks to preserve context. Each chunk goes through process_chunk(), which first asks the LLM to correct OCR errors while keeping original structure, then optionally asks it to format the corrected text as markdown, handling headings, lists, and emphasis. A duplicate-content removal step runs inside the markdown formatting to drop repeated paragraphs, which is useful for scanned books where headers or footers repeat. The final corrected output is written as a markdown or text file.
LLM Backends: Local GGUF or Cloud APIs
The project supports three ways to reach an LLM. For local inference, generate_completion_from_local_llm() uses the llama_cpp library, which means you need a GGUF model file and a machine that can run it, with optional GPU acceleration. For cloud, there are separate functions for OpenAI and Anthropic, each with retry logic and dynamic token adjustment. The README shows a .env file with USE_LOCAL_LLM, API_PROVIDER, and API keys. You pick one path. Local models avoid per-token costs but require you to source a compatible model and have enough RAM or VRAM. API models are simpler to start but incur usage charges, and the project does not estimate those costs. The code also has an estimate_tokens() function that uses model-specific tokenizers when available, falling back to a rough approximation. That feeds into dynamic adjustment of max_tokens, with TOKEN_BUFFER and TOKEN_CUSHION settings to stay under model limits.
Getting It Running: Commands and Configuration
The README gives a concrete setup path. It assumes Python 3.12 and suggests using pyenv to install it if missing. The commands clone the repository, create a virtual environment with python -m venv venv, activate it, and install requirements.txt. You also need the Tesseract engine itself, installed via apt on Ubuntu, brew on macOS, or a Windows installer. Then you create a .env file. The example shows USE_LOCAL_LLM=False, API_PROVIDER=OPENAI, and OPENAI_API_KEY. To run, you place a PDF in the project directory and call the script with an input file argument. The README is truncated at that point, so the exact CLI invocation is not visible, but the pattern is clear: point the script at a PDF, and it produces two outputs, a raw OCR text file and a corrected markdown file. The configuration keys for token limits, markdown options, and header suppression are mentioned but not enumerated in the visible portion.
Where It Can Break: Token Limits and Quality Variance
The biggest limitation is that correction quality depends entirely on the chosen LLM and its prompt. The README does not publish benchmark results or sample outputs beyond linked examples, so you cannot know in advance how a given model will handle your document's quirks. Token management is a real constraint. The code adjusts max_tokens dynamically, but long documents still get split into chunks, and each chunk requires an LLM call. With an API provider, that multiplies cost and latency. If a chunk exceeds the model's context window after adjustment, the process may fail or truncate, and the README does not describe fallback behavior. Another failure mode is that the LLM might over-correct, changing content that was actually correct, especially with historical documents where spelling differs from modern usage. The header suppression option is a heuristic, and if it misidentifies body text as a header, it could remove legitimate content. The project also requires Tesseract to be installed separately, and the image preprocessing steps are fixed; a scan with unusual contrast might not benefit from Otsu thresholding.
Alternatives: Dedicated OCR Engines vs. This Post-Processor
The obvious alternative is to skip Tesseract and use a modern OCR engine that outputs structured text directly, such as OCRmyPDF, which wraps Tesseract and adds PDF metadata, or a commercial service like Google Cloud Vision or Azure Form Recognizer. Those services often include layout analysis and table detection out of the box, so you might not need an LLM correction step at all. The difference in approach is that llm_aided_ocr separates OCR from correction, letting you keep Tesseract as the front end and apply an LLM only where errors are likely. That can be cheaper than a full commercial OCR API if you already have local GPU capacity, but it adds a moving part: you must manage the LLM prompt and model. A tool like OCRmyPDF gives you a more deterministic pipeline with no per-page LLM cost, at the expense of not fixing semantic errors that an LLM can catch.
Maintenance and Licensing: What the Repository Does Not Tell You
The repository metadata shows a last push date in August 2026, but there are no recent releases listed, and the license field reads NOASSERTION. That means the legal terms are not clearly defined, which is a red flag for any commercial deployment. The README does not mention a license file or contribution guidelines. The code depends on several external libraries, including pdf2image, pytesseract, llama_cpp, and API SDKs, so upgrade costs track those projects. Python 3.12 is a specific requirement, so you cannot run this on older system Python without pyenv or a manual install. The project appears to be a single-maintainer effort with no visible release cadence. You should expect to read the source yourself if you need to debug token handling or prompt behavior, because the README is descriptive but not exhaustive. For a one-off conversion of a few documents, that is acceptable. For a long-term production system, the missing license and release tags are enough reason to pause.
Editorial conclusion
Adopt llm_aided_ocr if you already use Tesseract on scanned PDFs and need cleaner, structured text for archival or retrieval, and you can tolerate API costs or have a local GGUF model. Skip it if your scans are clean or you need a production pipeline with formal releases, since the repository shows no tagged releases and the license is marked NOASSERTION, so verify licensing and dependencies before relying on it. First check the .env configuration, confirm Python 3.12 and Tesseract are installed, and test on a single PDF with max_pages set to a low value to measure quality and token usage before processing a full corpus.
Frequently asked questions
What is llm_aided_ocr?
A pipeline that enhances Tesseract OCR output using large language models, either locally or through an API, for error correction, smart chunking and Markdown formatting of scanned PDFs. Pages are converted to images, preprocessed with grayscale conversion, Otsu thresholding and dilation, run through Tesseract, split at sentence boundaries with overlap, and each chunk is corrected and optionally formatted.
How do I install llm_aided_ocr?
Python 3.12 or newer is required. The documented steps install Pyenv with a long apt-get line and three export lines appended to a zsh startup file, then clone the repository, set a local Python version, create and activate a virtual environment, upgrade pip and wheel in three separate invocations, and install from requirements.txt. Tesseract is then installed per operating system, and a dotenv file carries the provider settings.
Does llm_aided_ocr run the language model locally or in the cloud?
Both are supported. Local inference goes through a library binding with custom grammars for structured output, requires a compatible GGUF model, and is listed with GPU acceleration. API mode covers OpenAI and Anthropic. However the dotenv example sets USE_LOCAL_LLM to false and selects OpenAI as the provider, so the shipped configuration is the cloud path.
Which LLM is best for OCR in llm_aided_ocr?
The README does not rank models. It documents model selection as a per-provider setting, token estimation that uses model-specific tokenizers where available with an approximation as a fallback, and dynamic adjustment of the maximum token parameter based on prompt length and model limits, with a buffer and a cushion.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dicklesworthstone-llm-aided-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/dicklesworthstone-llm-aided-ocr)Was this useful?