XRAG: A Benchmarking Harness for Individual RAG Components
XRAG: eXamining the Core - Benchmarking Foundational Component Modules in Advanced Retrieval-Augmented Generation
At a glance
- What is it?
- XRAG is a Python evaluation framework that isolates retrievers, embeddings, LLMs and orchestrators so you can measure each piece of a RAG pipeline separately. It is useful for controlled comparisons, and awkward if you want a production serving stack.
- Who is it for?
- Adopt XRAG if you are a researcher or evaluation engineer who needs to hold a RAG pipeline fixed and vary one component at a time, and you are comfortable with a research-grade tool whose roadmap still lists Semantic Perplexity, Entropy, Self-RAG and FLARE as open items. Do not adopt it as a production retrieval service.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
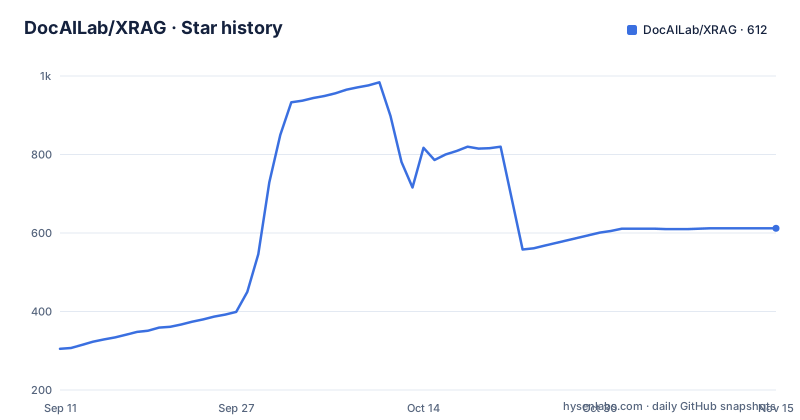
- DocAILab/XRAG612 ★ · +307
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| DocAILab/XRAG | 305 | 612 |
307 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Component-Isolation Problem XRAG Targets
Most RAG evaluation tooling scores an end-to-end pipeline. You feed a question in, you get an answer out, and a metric tells you whether the answer was good. That number hides everything. A drop could come from the chunker, the embedding model, the retriever, the reranker, the prompt template, or the generator. XRAG exists to break that apart. Its stated purpose is to evaluate the foundational components of advanced RAG systems by dissecting each core module and measuring how different configurations and components affect overall performance. The audience is narrow and identifiable: researchers who need to attribute a performance delta to a specific module, and engineers who want to justify a retriever or embedding choice with numbers rather than intuition. The project is published as the PyPI package examinationrag, carries an Apache-2.0 licence, and the accompanying paper was accepted at ICDE 2026 according to the repository updates.
How XRAG Splits a Pipeline Into Measurable Pieces
The architecture is modular by design. Retrievers, embeddings and LLMs are pluggable components, and the README lists the retrieval methods as Vector, BM25, Hybrid and Tree-based, with keyword-based and document-summary retrieval also named in the features list. Text splitters arrived in a July 2025 update and include SemanticSplitterNodeParser, SentenceSplitterNodeParser and SentenceWindowNodeParser. Sitting above the components are orchestrators, which the README describes as the layer that organises and manages execution logic and workflow, producing agentic RAG behaviour. Five orchestrator types are named: sequential, conditional, iterative, parallel and hybrid. The update log records self-rag and adaptive-rag orchestrators added on 2025-11-05 and SIM-rag added on 2025-11-18. The evaluation side is similarly layered. Traditional metrics cover F1, EM, MRR, Hit@K, MAP and NDCG. LLM-based metrics cover Faithfulness, Relevancy and Correctness. A third tier, labelled deep evaluation, covers Contextual Precision and Recall, Hallucination and Bias, and the README attributes these to LlamaIndex, DeepEval and custom metrics. That three-tier split is the substantive design decision here: it lets you report a cheap lexical score and an expensive LLM-judged score for the same run.
Installing and Driving XRAG From the Command Line
The package is distributed on PyPI as examinationrag, so installation follows the usual pip path, and the README's installation section is the place to confirm the exact extras you need. Two entry points are documented. The WebUI starts with the command xrag-cli webui, which opens an interface that walks through dataset upload and configuration, index building, RAG strategy configuration, interactive testing and comprehensive evaluation in that order. The WebUI supports benchmark datasets named as HotpotQA, DropQA and NaturalQA, plus custom dataset integration with automatic format conversion. The second entry point is a generate command, added in January 2025, which produces QA pairs from a folder of documents. Configuration is handled through a config file, and the June 2025 update notes that the configuration file was revised so parameters appear clearer, with a default config added in release v0.1.4. The README also documents API support added in January 2025, which turns XRAG into a backend service rather than only a CLI. LLM backends include OpenAI models and local models such as Qwen and LLaMA, with Ollama support added in January 2025.
Where XRAG Is the Wrong Tool
The README's own roadmap is the clearest limitation statement. Semantic Perplexity, Entropy and Semantic Entropy, Auto-J and Prometheus are all listed as unchecked items under novel evaluation metrics. Adaptive Retrieval, Multi-step Approach, Self-RAG and FLARE appear as unchecked under agent workflows, even though the update log separately records self-rag and adaptive-rag orchestrators as added. That contradiction between the roadmap checkboxes and the changelog means you should test the specific orchestrator you need rather than trusting either document. Late Chunking is also unchecked. Beyond the roadmap, the deeper constraint is that XRAG is an evaluation harness, not a serving layer. The API support turns it into a backend service. If your question is how to serve ten thousand queries per second, XRAG is answering a different question. The LLM-judged metrics also carry the usual cost and variance of model-based scoring.
How XRAG Differs From Running Ragas or DeepEval Directly
DeepEval and Ragas are the obvious comparison points, and XRAG's relationship to them is not adversarial. The README states that XRAG's built-in evaluation models include LlamaIndex, DeepEval and custom metrics, so DeepEval is a dependency of the evaluation layer rather than a rival to it. The difference in approach is what sits above the metric. Ragas and DeepEval take question, context, answer triples and score them. XRAG takes a pipeline definition, including the splitter, the retriever, the post-processor and the orchestrator, and lets you swap those pieces while holding the dataset and the metric fixed. That is the whole value proposition: the unit of comparison is the component, not the output. If you already have a fixed pipeline and only need to know whether answers are faithful, calling DeepEval or Ragas directly is less machinery. You reach for XRAG when the pipeline itself is the variable under study.
Maintenance, Releases and Licence Terms
The release cadence is modest and front-loaded. v0.1.2, v0.1.3 and v0.1.4 all landed within about a month between January and February 2025, and the last recorded push to the default branch is June 2026, so the repository is active rather than archived. Feature updates continued through 2025 with text splitters in July and three orchestrators between November 2025 and the ICDE 2026 acceptance. That pattern suggests a research project tracking a paper rather than a library with a compatibility guarantee. The configuration file format changed in June 2025, which matters across the 0.1.x releases. The licence is Apache-2.0, which permits commercial use and modification and includes a patent grant, but it also requires that you preserve copyright and licence notices and state significant changes. This is a description of the licence text, not legal advice; if you plan to redistribute XRAG inside a product, have counsel read the NOTICE requirements.
Editorial conclusion
Adopt XRAG if you are a researcher or evaluation engineer who needs to hold a RAG pipeline fixed and vary one component at a time, and you are comfortable with a research-grade tool whose roadmap still lists Semantic Perplexity, Entropy, Self-RAG and FLARE as open items. Do not adopt it as a production retrieval service. Before committing, verify three things: that the exrag CLI subcommands you need exist in the installed version, that your target LLM is reachable through the OpenAI-compatible or Ollama path, and that the DeepEval-based metrics you intend to rely on are the ones actually wired into the config you copy.
Frequently asked questions
How do I install XRAG?
Create a Python 3.11 environment, install the distribution named examinationrag, and then apply three corrective steps the documentation lists: install jury without its dependencies, pin requests to 2.27.1, pin urllib3 to 1.25.11, and keep jiwer below 4.0.0. The pins come after the main install on purpose, to keep the rest of the stack resolvable.
What command does XRAG install?
A console script named xrag-cli, which takes a command followed by options. The benchmarking run accepts overrides in key=value form so you can change configuration values from the command line instead of rewriting the config file, and a separate subcommand launches the web interface.
What is an orchestrator in XRAG?
It is the object that holds the execution logic and workflow between RAG components, and there are five kinds: sequential, conditional, iterative, parallel, and hybrid. Because the orchestrator is swappable while the components stay fixed, you can attribute a result to the shape of the control flow rather than to the pipeline as a whole.
Which retrieval methods does XRAG support?
Vector, BM25, hybrid and tree-based retrieval, plus keyword-based retrieval, document summary retrieval, and a slot for custom strategies. Retrievers, embeddings and models are the three pluggable component slots, with separate index packages for Hugging Face, LangChain and OpenAI embeddings and three rerank post-processors.
What metrics can XRAG compute?
Three tiers. Traditional ones: F1, exact match, MRR, Hit@K, MAP and NDCG. Model-judged ones: faithfulness, relevancy and correctness. And deep evaluation: contextual precision and recall, hallucination, and bias. The framework lists LlamaIndex, DeepEval and custom metrics among its built-in evaluation models.
Which datasets does XRAG support?
Three multi-hop question answering benchmarks are named for the web interface, with custom datasets accepted and converted automatically. There is also a generate command that produces question and answer pairs from a folder of documents, and the repository ships a generated pair file as an example.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/docailab-xrag)Star history chart for your README
[](https://hysenlabs.com/projects/docailab-xrag)Was this useful?