PaperBanana: a five-agent pipeline for academic figures, forked from Google's PaperVizAgent
PaperBanana: Automating Academic Illustration For AI Scientists
At a glance
- What is it?
- PaperBanana turns method-section text and a figure caption into publication-style diagrams and plots using Retriever, Planner, Stylist, Visualizer and Critic agents. It is Apache-2.0 Python, installs with uv, and needs an OpenRouter or Google Gemini API key.
- Who is it for?
- Adopt PaperBanana if you already write method sections in Markdown and want candidate figures you can refine, and if you accept that retrieval quality depends on having PaperBananaBench under data/PaperBananaBench. Do not adopt it if you need a deterministic, offline figure generator, or if you cannot send your unpublished method text to Gemini or OpenRouter, since the Visualizer calls an external image model.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
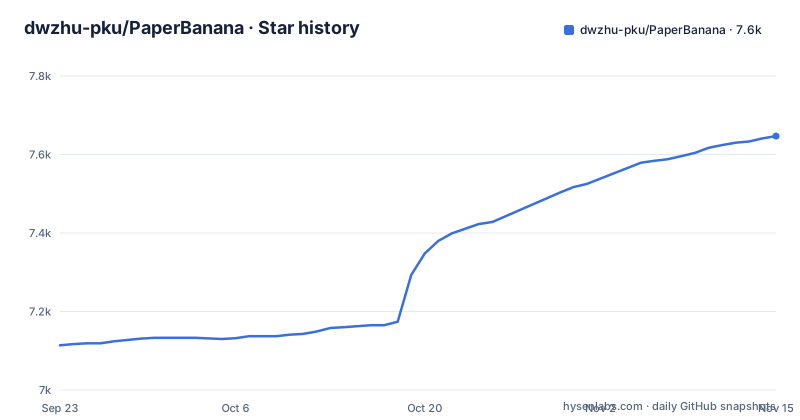
- dwzhu-pku/PaperBanana7,647 ★ · +533
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| dwzhu-pku/PaperBanana | 7.1k | 7.6k |
533 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What PaperBanana actually solves for AI researchers
The gap PaperBanana targets is the one between a written method section and a figure that a reviewer will accept. Most authors can describe an architecture in prose but cannot draw it, and the tools they reach for (generic image models, drawing software) either ignore the semantics of the method or require manual layout work. PaperBanana takes the method text plus a caption and returns candidate illustrations, which the README describes as "publication-quality diagrams and plots".
The intended user is someone writing an AI paper, not a designer. The README is explicit that the project is "dedicated to facilitating academic illustration for all researchers" and that there are "no plans to use it for commercial purposes". It also states the project was forked from Google Research's PaperVizAgent repository, so the pipeline's lineage is a research artifact rather than a product. The TODO list is honest about scope: statistical plots, style-guided improvement of existing diagrams, and reference sets beyond computer science are all still unchecked.
The five-agent pipeline and where the reference examples enter
The architecture is a fixed sequence of five agents. The Retriever Agent picks the most relevant reference diagrams from a curated collection. The Planner Agent converts method content and communicative intent into a textual description using in-context learning. The Stylist Agent rewrites that description against automatically synthesized style guidelines. The Visualizer Agent sends the description to an image generation model. The Critic Agent closes the loop with the Visualizer over multiple refinement rounds.
The mechanism that matters is the retrieval step. It is what makes this in-context learning rather than prompt-and-pray: the Planner's description is conditioned on real diagrams drawn from the same domain. That also means the pipeline degrades in a specific way when the reference set is absent. The README states that the framework "is designed to function gracefully without the dataset by bypassing the Retriever Agent's few-shot learning capability", so you get output, but the Planner is no longer grounded in examples. The Critic loop is the second lever: it is the only part of the design that can correct a bad first render rather than accept it.
Installing PaperBanana with uv and running the Gradio app
The README uses uv for package management and Python 3.12. Clone the repository and create the virtual environment first, then install the pinned requirements. On Windows the activation script is .venv\\Scripts\\activate instead of the source line below.
git clone https://github.com/dwzhu-pku/PaperBanana.git
cd PaperBanana
uv venv
source .venv/bin/activate
uv python install 3.12
uv pip install -r requirements.txt
Configuration comes next. The README recommends copying configs/model_config.template.yaml to configs/model_config.yaml, which is git-ignored so keys stay out of the repository. You fill in defaults.main_model_name and defaults.image_gen_model_name, and set at least one key under api_keys. Either google_api_key or openrouter_api_key is enough; if both are present, OpenRouter is preferred for routing.
With the environment ready, launch the web app with python app.py. The README says retrieval is on by default (auto) in both the Gradio and Streamlit Retrieval Setting controls and recommends leaving it there. If you prefer the other interface, streamlit run demo.py opens the Streamlit demo, which gained Main Model and Image Generation Model selection on 2026-03-11.
Where PaperBanana fails or is the wrong tool
The clearest limitation is dependency on external image models. There is no local diffusion path in requirements.txt; the Visualizer calls Gemini, OpenRouter or OpenAI. If your method section is under submission and cannot leave your network, this pipeline is not usable without a policy decision you have to make yourself.
The second limitation is the reference set. Downloading PaperBananaBench and placing it under data/PaperBananaBench/ is a manual step, and the README notes the framework bypasses retrieval when it is missing. A user who skips the dataset and then judges the output is evaluating a different system than the one described.
The third is coverage. The TODO list still has "Upload code for generating statistical plots" and "Upload code for improving existing diagrams based on style guideline" unchecked, and the reference set is not yet expanded "beyond computer science". The README does describe plots as an output, and PaperBananaBench has a plot subset, but the statistical-plot code is still on the TODO list and the reference set does not yet cover domains outside CS. Finally, the README warns that generating many candidates at once requires an API key that supports high concurrency, which is a practical ceiling on batch use.
PaperBanana versus PaperVizAgent and generic image models
The most direct alternative is PaperVizAgent, the Google Research repository PaperBanana was forked from. The difference is governance rather than mechanism: PaperBanana positions itself as the continuing, community-facing line, with the README stating the fork "aims to keep evolving toward better support for academic paper illustration". If you want the original Google-maintained artifact, that is where it lives; if you want the fork with the Streamlit model selection, OpenRouter routing and Hugging Face Spaces hosting added in March 2026, that is this repository.
The other alternative is a general image model used directly. The difference in approach is the reference-driven pipeline itself: a raw image prompt has no Retriever to ground it in domain examples, no separate Stylist pass against academic style guidelines, and no Critic to iterate. You trade a single API call for five agents and multiple rounds, which is slower and more expensive per figure, in exchange for output that is conditioned on real diagrams. For a quick schematic you may not want that trade; for a figure that has to survive review, the extra passes are the point.
Maintenance, licence and the cost of keeping it current
The repository is not archived, and the last push was on 2026-10-24. Releases are not listed, so there is no version tag to pin against; you track main. The README's news section is busiest in March 2026 (Hugging Face Spaces hosting, a ClawHub skill, Streamlit model selection, OpenRouter support), followed by acceptance to ICML 2026 as a Spotlight on 2026-04-30 and the PaperBanana-Interact follow-up on 2026-09-23.
Upgrade cost is dominated by the model names in configs/model_config.yaml, not by the Python code. Because main_model_name and image_gen_model_name are set in that file, changing image providers is a configuration change; re-check your output after any provider switch.
The licence is Apache-2.0, which permits commercial use, but the README states the maintainers themselves have no commercial plans. That is a statement of intent, not a licence restriction. If you need legal certainty about redistributing generated figures or the bundled reference data, read the LICENSE file and the dataset's own terms on Hugging Face.
Editorial conclusion
Adopt PaperBanana if you already write method sections in Markdown and want candidate figures you can refine, and if you accept that retrieval quality depends on having PaperBananaBench under data/PaperBananaBench. Do not adopt it if you need a deterministic, offline figure generator, or if you cannot send your unpublished method text to Gemini or OpenRouter, since the Visualizer calls an external image model. Before committing, verify three things: that your chosen model names exist under defaults.main_model_name and defaults.image_gen_model_name in configs/model_config.yaml, that your API key tolerates the concurrency implied by the number of candidates you request, and that the missing statistical-plot code on the TODO list is not something your paper depends on.
Frequently asked questions
What is PaperBanana?
It is a reference-driven multi-agent framework for automated academic illustration generation, built from Retriever, Planner, Stylist, Visualizer and Critic agents. It is a fork of Google Research's PaperVizAgent repository, licensed Apache-2.0.
How do I use PaperBanana?
Clone the repository, create a uv virtual environment with Python 3.12, install requirements.txt, then copy configs/model_config.template.yaml to configs/model_config.yaml and fill in the two model names plus at least one API key. Launch the Gradio app with python app.py, paste your method section and caption, and click Generate.
Is PaperBanana free?
The code is Apache-2.0 and the maintainers state they have no commercial plans, but the pipeline calls external image generation models, so you still need your own Google Gemini or OpenRouter API key and pay that provider.
How do I access PaperBanana?
You can try it online on Hugging Face Spaces without any setup, or run it locally from the repository using python app.py for the Gradio app or streamlit run demo.py for the Streamlit demo. The README also notes it was published as a ClawHub skill installable with clawhub install paperbanana.
How do I use Google Paper Banana?
The Google lineage is the PaperVizAgent repository PaperBanana forked from. In this repository you configure a Google key under api_keys as google_api_key in configs/model_config.yaml, and OpenRouter is preferred for routing when both keys are present.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dwzhu-pku-paperbanana)Star history chart for your README
[](https://hysenlabs.com/projects/dwzhu-pku-paperbanana)Was this useful?