spacy-llm: LLM prompting as a spaCy pipeline component
🦙 Integrating LLMs into structured NLP pipelines
At a glance
- What is it?
- spacy-llm wraps prompt-based NLP tasks in a serializable spaCy component, so you can prototype with an LLM and keep the rest of your pipeline rule-based or supervised. The trade-off is a prompt-parsing layer you now own, and an interface the README itself calls experimental.
- Who is it for?
- Adopt spacy-llm if you already run spaCy and want LLM-backed NER, textcat or summarization wired into the same nlp object as your rule-based components, without collecting training data first. Skip it if your task has a stable output schema and a few thousand labelled examples, because a trained spaCy component will be cheaper and more predictable at inference time.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 22 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
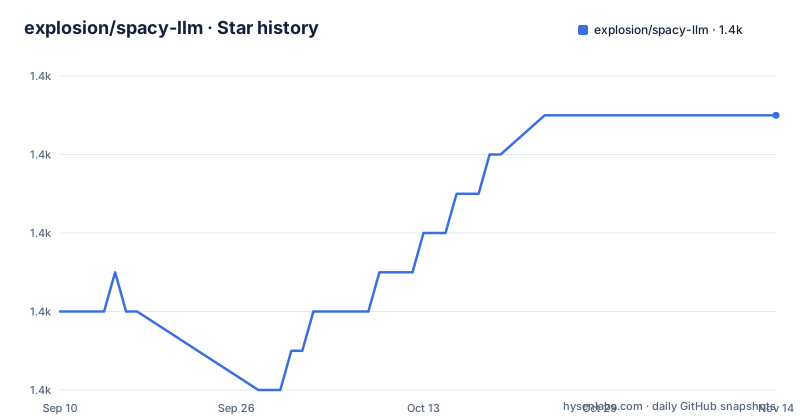
- explosion/spacy-llm1,399 ★ · +5
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| explosion/spacy-llm | 1.4k | 1.4k |
5 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap spacy-llm fills: prompting without leaving spaCy
Most teams that want an LLM to label entities or classify text end up writing a script: build a prompt, call the provider, scrape the JSON out of the reply, map it back onto spans or labels. That script is not a pipeline. It has no config, no serialization, and no place to sit next to the tokenizer, the lemmatizer or a rule-based matcher you already trust. spacy-llm puts that script inside spaCy as a component named llm, registered in spaCy's registry so it can be configured, saved and reloaded like any other pipe. The README frames the motivation plainly: supervised learning is worse than prompting for prototyping but better for production on well-defined outputs, and the package is meant to let you mix both in one pipeline and swap components out as a project matures. The audience is therefore narrow and specific: engineers who already know spaCy's config system and want prompt-based tasks available as nlp.add_pipe targets, not people shopping for a general LLM orchestration library.
Tasks and models: the two registries that do the work
The design splits every LLM-backed component into two independently registered pieces. A task defines prompting and parsing for one job: NER, text classification, lemmatization, relationship extraction, sentiment, span categorization, summarization, entity linking, translation, or a raw prompt task for cases the built-ins do not cover. A model defines how the request reaches a provider. The README lists interfaces for OpenAI, Cohere, Anthropic, Google PaLM and Microsoft Azure AI, plus open-source models hosted on Hugging Face including Falcon, Dolly, Llama 2, OpenLLaMA, StableLM and Mistral, and an integration path through LangChain. Because both halves are registry entries, you can pair any task with any model, and the README points at spaCy's registry documentation for writing your own prompting, parsing or model functions. That separation is the real mechanism here. Swapping GPT-4 for a locally hosted Mistral is a config edit, not a rewrite, and the parsing logic that turns a response into Doc annotations stays in one place. The cost is that the parser is now your responsibility whenever you leave the built-in tasks.
Getting a first pipeline running
Installation is a single command in the virtual environment where spaCy already lives: python -m pip install spacy-llm. The README notes the package will be installed automatically in future spaCy versions, which tells you the current setup is transitional. For a quick experiment, the Python path from 0.5.0 onward is short: create a blank English pipeline with spacy.blank("en"), add the llm_textcat pipe, call add_label for each category, and run a Doc through it. The README's example adds INSULT and COMPLIMENT, processes a one-line string, and reads doc.cats, which comes back with a score per label. Using the llm_textcat factory selects the latest built-in textcat task and the default GPT-3.5 model from OpenAI. API keys are set as environment variables; the README links to a documentation page on API key handling rather than listing the variable names inline. Anything beyond a scratch experiment moves to spaCy's config system, where the llm component's parameters are declared. The README's quickstart cuts off mid-sentence at that point, so the exact config block is not reproducible from this material alone and you should read the linked usage page before writing one.
Prompt sharding and the map-reduce path for long inputs
Context windows are the constraint that bites first in document-level tasks. spacy-llm addresses this with a map-reduce approach the README describes as splitting prompts that are too long for a model's context window and fusing the results back together, documented under task sharding. The shape of the trade-off is worth stating: sharding turns one call into several, so cost scales with the number of shards, and the reduce step has to merge partial outputs into a single Doc. For span-level tasks that merge is not free. Two shards can each report an entity that overlaps the boundary, and the fusion logic decides what survives. If your documents routinely exceed the window, treat the sharding behaviour as something to test against your own inputs rather than assume. For short texts, none of this applies and the component behaves as a single request per Doc.
Where the prompt-parsing layer breaks
The honest limitation is structural. Every task depends on a model returning something the parser can read, and models do not guarantee format. A textcat parser expecting a label and a score will do something arbitrary when the response is a sentence of prose, and the README's own framing of the package as turning unstructured responses into robust outputs is a statement of intent, not a guarantee. The mitigation is the registry: write a custom parsing function that handles your provider's actual output. That is real work, and it is work you redo whenever you change models, because the failure mode is model-specific. The second limitation is stated by the project itself. The README carries a warning that the package is still experimental and that interface changes in minor version updates may be breaking. That is unusual candour and it should shape how you depend on it: pin the version, and expect to read release notes before upgrading. The v0.7.3 release, which sandboxed Jinja to prevent code execution from untrusted configs, is a concrete example of a security-relevant change landing in a point release.
spacy-llm versus calling LangChain directly
spacy-llm integrates with LangChain rather than competing with it: the README states that all langchain models and features can be used inside spacy-llm. The difference is where the output lands. A LangChain chain returns whatever your chain is written to return, typically a string or a dictionary, and you decide what to do with it. spacy-llm returns annotations on a spaCy Doc, which means the LLM's output is immediately available to the components downstream of it in the same pipeline, and to anything that consumes Doc objects. That matters when the LLM is one step in a longer process: classify first, summarize the subset that passed, then run a rule-based check on the summary. The README describes exactly this pattern, suggesting a cheap text classification model to select texts for summarization and a rule-based system to sanity check the summary output. If your work is a single prompt-and-parse call with no surrounding NLP pipeline, the spaCy component adds a config layer and a Doc abstraction you will not use, and a direct API call or a plain LangChain chain is the smaller dependency.
Maintenance, versioning and the MIT licence
The release history shows a project that is maintained but moving in steps: v0.7.2 added Python 3.12 support and a Torch-related fix, v0.7.3 sandboxed Jinja, and v0.7.4 brought Python 3.14 support, a Pydantic v2 migration and updated dependencies. The Pydantic v2 migration in particular is the kind of change that can surface in code that touches the package's internals. Combined with the README's warning about breaking minor releases, the practical upgrade cost is not the pip install but the re-validation of your prompts and parsers after each bump. Budget for a test set of documents with known expected outputs, and run it after every version change. The licence is MIT, which permits commercial use and modification; the repository does not include a separate model or prompt licence, and the terms attached to whichever LLM provider you call are a separate matter that this package does not govern. Nothing here is legal advice, and if you redistribute the package you should read the MIT text in the repository yourself.
Editorial conclusion
Adopt spacy-llm if you already run spaCy and want LLM-backed NER, textcat or summarization wired into the same nlp object as your rule-based components, without collecting training data first. Skip it if your task has a stable output schema and a few thousand labelled examples, because a trained spaCy component will be cheaper and more predictable at inference time. Before committing, verify two things against your own data: that the task's parser handles your model's actual response format, and whether you can pin spacy-llm to an exact version, since the README warns that minor releases may break the interface.
Frequently asked questions
what is spacy llm
It is a package that integrates large language models into spaCy, providing a modular system for prototyping with prompts and for turning unstructured responses into well-formed outputs, with no training data required. Prompts become a serialisable component in the pipeline, and tasks and models are separate configurable pieces.
is spacy llm
It is described by its own documentation as still experimental, with interface changes that may be breaking in minor version updates. The current version is 0.7.4, and it is installed as a separate package into an environment that already has spaCy.
Which NLP tasks does spacy-llm support?
Ten are available out of the box: named entity recognition, text classification, lemmatization, relationship extraction, sentiment analysis, span categorization, summarization, entity linking, translation, and raw prompt execution. Semantic role labelling is listed as coming.
Which models does spacy-llm support?
Interfaces are listed for OpenAI, Cohere, Anthropic, Google PaLM, and Microsoft Azure AI, plus six open-source models hosted on Hugging Face: Falcon, Dolly, Llama 2, OpenLLaMA, StableLM, and Mistral. There is also a LangChain integration described as covering all its models and features.
How do I install spacy-llm?
Run python -m pip install spacy-llm in the same virtual environment where spaCy is already installed, because the project expects to be bundled into spaCy in future versions and is separate for now. Development uses the package manager uv with an editable install.
Does spacy-llm need training data?
No, that is stated as a design point. The documentation argues that prompting is better for prototyping while supervised learning is better for production, and the intended workflow is to start with prompted components and replace them as the project progresses.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/explosion-spacy-llm)Star history chart for your README
[](https://hysenlabs.com/projects/explosion-spacy-llm)Was this useful?