facebookresearch/sapiens: a 1024 x 1024 human vision model family for pose, segmentation, depth and normals
High-resolution models for human tasks.
At a glance
- What is it?
- Sapiens is a pretrained foundation model suite for human-centric vision, trained at 1024 x 1024 with a 16-pixel patch size. It ships a lite inference path and a full training setup, but the repository licence is not matched to a recognised SPDX identifier, so check it before you build on it.
- Who is it for?
- Adopt Sapiens if you need high-resolution human features and can host the checkpoints yourself, and start with the lite installation before committing to the full environment. Skip it if your task is not human-centric or if you cannot accept the licence terms as written.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 173 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
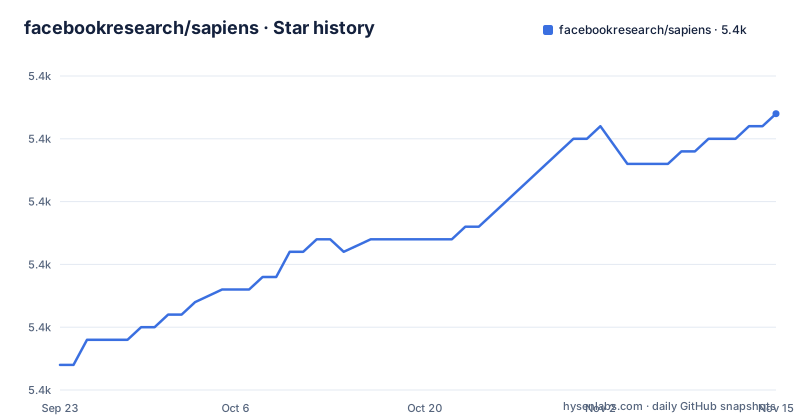
Star history
- facebookresearch/sapiens5,442 ★ · +20
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| facebookresearch/sapiens | 5.4k | 5.4k |
20 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Sapiens targets: humans at high resolution, not scenes in general
Most vision backbones are trained on general image datasets and then adapted. Sapiens takes the opposite route. According to the README, the model family is pretrained on 300 million in-the-wild human images and is natively trained at a 1024 x 1024 image resolution with a 16-pixel patch size. That combination is the pitch: a backbone whose features are dense enough for body parts and hands, and whose pretraining distribution is people rather than a mix of landscapes, objects and text.
The suite covers five downstream heads: image encoder, pose estimation, body part segmentation, depth estimation and surface normal estimation. Each has its own documentation page under docs/, and each also has a lite variant under lite/docs/. That structure tells you who this is for. If you are building avatar reconstruction, motion capture, virtual try-on or any pipeline where the subject is a person and the fine detail around the body matters, the pretraining target matches your data. If your images are mostly rooms, products or documents, the pretraining is aimed somewhere else and you are paying for resolution you will not use.
How the checkpoint layout and task heads fit together
The repository is organised by task rather than by model architecture. Top-level directories include det/, pose/, seg/, pretrain/, cv/ and engine/, with docs/ holding the per-task guides. The README's directory tree shows a single checkpoint root, referenced as sapiens_host, that contains subfolders for detector, pretrain, pose, seg, depth and normal. Inside pretrain/checkpoints/ the weights are grouped by parameter count: sapiens_0.3b, sapiens_0.6b, sapiens_1b and sapiens_2b, with files such as sapiens_0.3b_epoch_1600_clean.pth and sapiens_0.6b_epoch_1600_clean.pth.
That layout is the practical interface. You set SAPIENS_CHECKPOINT_ROOT to the sapiens_host folder, and the task scripts resolve weights relative to it. The detector folder holds an rtmpose checkpoints directory, which the README lists separately from the pretrained backbones. The README acknowledges OpenMMLab as the upstream project the code benefits from, which is consistent with the engine/ and det/ directories and with the rtmpose naming. In other words, this is not a self-contained framework; it is a set of task heads layered on conventions borrowed from a larger ecosystem, and you should expect to read those conventions rather than infer them.
Installing Sapiens with the lite setup first
The README recommends the lite installation for anyone whose goal is running existing models in inference mode. It states the lite setup offers optimized inference, described as 4x faster, with minimal dependencies limited to PyTorch, numpy and cv2. That is a meaningful reduction compared with the full training environment, and it is the path to take if you only want predictions.
Start by cloning the repository and exporting the root path, exactly as the README shows:
git clone https://github.com/facebookresearch/sapiens.git
export SAPIENS_ROOT=/path/to/sapiens
After that, follow lite/README.md for the inference-only environment. The lite task guides live under lite/docs/, with one page each for the image encoder, pose, segmentation, depth and normals. The README does not reproduce those steps in the top-level file, so the lite README is the place to look for the actual commands and for how the lite scripts expect checkpoints to be arranged.
For the full training setup, the README gives a single entry point:
cd $SAPIENS_ROOT/_install
./conda.sh
That script creates a new conda environment named sapiens and installs the dependencies needed to replicate the training setup. The README then directs you to download the original checkpoints from Hugging Face at huggingface.co/facebook/sapiens, notes that you can be selective about which checkpoints to download, and asks you to set SAPIENS_CHECKPOINT_ROOT to the sapiens_host folder. Getting that variable and the subfolder names right matters more than anything else in the install, because the per-task scripts read from that tree.
Where Sapiens is the wrong tool
The first limitation is scope. Every documented task is human-centric. There is no general object detection head, no scene parsing head, no OCR. If your pipeline needs both human parsing and general scene understanding, you are running two systems, and the README does not describe any integration between Sapiens and a general-purpose detector beyond the rtmpose folder under detector/.
The second is the dependency weight of the full installation. The README splits installation into a lite path with three dependencies and a full path that builds a conda environment from _install/conda.sh. Nothing in the README describes a supported middle ground, so if you need to finetune, you inherit the full environment and its build.
The third is licence clarity. The repository's licence field is NOASSERTION, and the README says only that the project is licensed under LICENSE, with portions derived from open-source projects licensed under Apache 2.0. The README does not state which portions, and it does not summarise the terms.
Sapiens against a general-purpose segmentation stack
The obvious alternative is a general vision backbone paired with a task head, the pattern most teams already have in place. Take a model trained on broad image data, attach a segmentation or depth head, finetune on your own annotations. The difference is where the resolution and the pretraining distribution sit. A general backbone is usually trained at lower resolution and upsampled at inference, and its pretraining corpus is not dominated by people. Sapiens is pretrained on human images and trained natively at 1024 x 1024 with a 16-pixel patch size, so the feature grid is fine-grained by construction rather than by interpolation.
That difference cuts both ways. A general backbone gives you one model for many subjects and a wider range of off-the-shelf heads. Sapiens gives you five human-specific heads and a checkpoint family split by parameter count, from 0.3b to 2b, so you can trade capacity against latency within the same architecture. If your workload is human bodies at high resolution, Sapiens provides task models for pose, body part segmentation, depth and surface normals, with finetuning guides for each. If your workload is mixed, the general stack is still the simpler answer.
Maintenance, licensing and the cost of adopting a research release
The repository is not archived, and the last push was on 2026-05-26. The README also points to a separate repository, facebookresearch/sapiens2, described as out. That pointer is the most important maintenance signal in the README: the project itself directs readers to a successor, and the README does not describe how long the current repository will continue to receive changes or whether checkpoints will keep being published here.
The repository has no published GitHub releases, so there is no published version history to pin against. In practice that means your upgrade unit is a git commit plus a checkpoint directory, and the README does not document a compatibility contract between the two. Budget for that: record the commit hash and the exact checkpoint filenames you validated, because nothing in the repository does it for you.
On licensing, the README states the project is licensed under LICENSE and that portions derived from open-source projects are under Apache 2.0. The licence identifier recorded for the repository is NOASSERTION, which means the terms were not matched to a standard identifier. The README does not enumerate the restrictions. Read the LICENSE file in full and get your own advice before shipping anything commercial; the README alone is not enough to decide.
Editorial conclusion
Adopt Sapiens if you need high-resolution human features and can host the checkpoints yourself, and start with the lite installation before committing to the full environment. Skip it if your task is not human-centric or if you cannot accept the licence terms as written. Verify the LICENSE file and the checkpoint directory layout before you write any integration code.
Frequently asked questions
What is the sapiens software from facebookresearch?
It is a suite of foundation models for human-centric vision tasks, covering 2D pose, body part segmentation, depth and surface normals, plus the image encoder itself. The README states the family is pretrained on 300 million in-the-wild human images at 1024 x 1024 resolution with a 16-pixel patch size.
How do I install sapiens?
The README recommends the lite installation for inference-only use, which it describes as having minimal dependencies of PyTorch, numpy and cv2, with details in lite/README.md. For the full training setup you clone the repository, set SAPIENS_ROOT, then run _install/conda.sh, which creates a conda environment named sapiens.
Which checkpoints does sapiens need and where do they go?
The README says to download the original checkpoints from huggingface.co/facebook/sapiens and to set SAPIENS_CHECKPOINT_ROOT to the sapiens_host folder. That folder holds detector, pretrain, pose, seg, depth and normal subfolders, with pretrain weights grouped as sapiens_0.3b, sapiens_0.6b, sapiens_1b and sapiens_2b.
Is sapiens a replacement for a general-purpose vision backbone?
No. Every documented task is human-centric, and the only detector checkpoint folder listed in the README tree is rtmpose. For general scene or object understanding you would still need a separate model, and the README does not describe an integration beyond that detector.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebookresearch-sapiens)Star history chart for your README
[](https://hysenlabs.com/projects/facebookresearch-sapiens)Was this useful?