GraphRAG-SDK: FalkorDB's Retrieval Harness for Grounded Answers
Build fast and accurate GenAI apps with GraphRAG SDK at scale 🌟
At a glance
- What is it?
- FalkorDB's GraphRAG-SDK turns documents into a typed knowledge graph on top of FalkorDB and returns cited answers from it. The interesting part is not the graph, it is the abstention path: the SDK lets an application inspect the retrieval trail and refuse to generate when the evidence is thin.
- Who is it for?
- Adopt GraphRAG-SDK if your questions need multi-hop traversal over typed entities and you are willing to run FalkorDB alongside your application, because the SDK does not abstract the database away. Skip it if a single-document question-answering bot over a few hundred chunks is all you need, since vector retrieval with reranking already scores 55.39 overall in the project's own comparison table.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
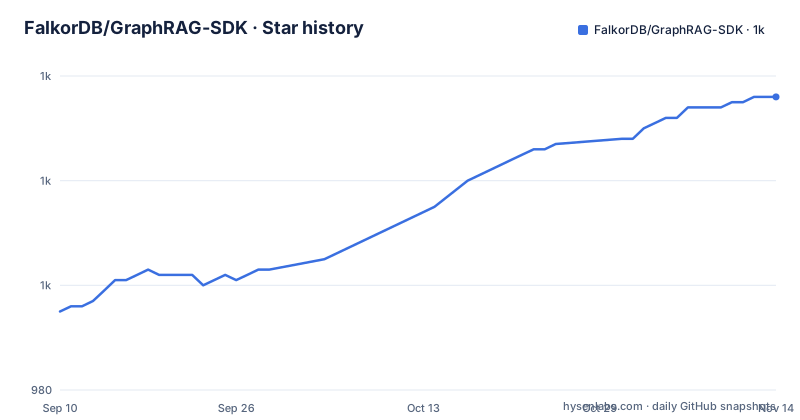
Star history
- FalkorDB/GraphRAG-SDK1,036 ★ · +41
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| FalkorDB/GraphRAG-SDK | 995 | 1k |
41 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem GraphRAG-SDK attacks: retrieval, not generation
The README makes a claim that is worth taking seriously because it reframes the usual complaint. Hallucinations in RAG, it argues, are usually a retrieval failure rather than a model failure: the model is asked to answer from context that never contained the answer. That framing determines who the SDK is for. It is for teams whose questions require facts spread across documents, where the connecting evidence is a relationship rather than a passage. A question about which supplier a subsidiary contracted with in a given quarter is not answered by the chunk that happens to embed closest to the question text. The README states this directly, noting that multi-hop facts rarely live in one chunk that happens to be similar to the question.
The second audience is teams that need to show their work. The SDK exposes MENTIONED_IN provenance edges that trace an entity mention back to the source chunk, and a return_context=True flag that returns the retrieval trail so the calling application can validate it. That is a different product from a chat wrapper. It assumes the caller will write code around the answer, not just display it.
The third audience is anyone running multiple tenants. ConnectionConfig takes a graph_name, and the README comments on that parameter with the phrase per-tenant isolation. In FalkorDB a graph is a named keyspace, so tenant separation is a naming decision rather than a filtering layer bolted onto shared tables.
Ingestion: ontology-constrained extraction into a typed graph
The pipeline visible in the README has three stages. Documents go in as raw text or, with the pdf extra installed, as file paths. An LLM extracts entities and relationships from them. Those land in FalkorDB as nodes and edges, and the ingest call returns counts: the example prints result.nodes_created and result.relations_created from the returned object.
The design decision that separates this from a generic extraction pipeline is the ontology. The README says the ontology constrains what can be extracted, so the graph stores typed, checkable facts instead of free-form model output. That is a real constraint with a real cost. You have to define the shape of your domain before ingestion, and anything the extractor encounters that does not fit the schema is either coerced or dropped. The payoff is that a later text-to-Cypher query has a closed vocabulary to generate against, which is a much smaller surface for the model to get wrong than open-ended graph construction.
One detail buried in the quick start is worth flagging because it speaks to production ingestion rather than demo ingestion. The README notes that ingestion sanitizes unsupported control characters in IDs and string properties before graph upserts, which helps avoid FalkorDB Cypher parse errors on noisy PDFs. That is the kind of line that appears after someone has run real PDFs through the system. Extraction is also configured with a model and a temperature: the benchmark configuration used gpt-4o-mini at temperature 0.7 for both graph construction and generation. Temperature 0.7 for extraction is high by the standards of most structured-output pipelines, and the README does not explain why that value was chosen for construction rather than a lower one.
Retrieval: text-to-Cypher traversal and the abstention gate
At query time the SDK offers relationship traversal, and the benchmark configuration lists text-to-Cypher retrieval as enabled. That means the question is translated into a Cypher query against the graph rather than into a vector search. The README contrasts the two approaches in one line: vectors match similar chunks, the graph traverses relationships.
The mechanism that matters most for reliability is what happens after retrieval. With return_context=True the caller receives the retrieval trail, and the README describes applications inspecting that context, validating generated claims, and gating generation when evidence is insufficient. The repository ships graphrag_sdk/examples/grounded_answers_with_abstention.py as a worked example of returning an explicit evidence-insufficient response instead of an answer.
This is the part of the design I would push a team to read first. An abstention path is only as good as the threshold that triggers it, and the README does not publish a default threshold or describe how one is calibrated. The example exists; the tuned policy does not. If you adopt the SDK for a high-stakes question-answering surface, the abstention rule is your code, not the library's, and it will need evaluation against your own data before it is trustworthy.
There is also a cost dimension the README raises but does not quantify. It claims predictable cost as an outcome of the design, and the fixed ontology plus Cypher generation is a plausible reason for that claim, since neither depends on how many chunks a vector index would return. Treat the claim as a design argument rather than a measurement.
Getting it running: three commands and one config object
The quick start is short. Install the SDK with the LiteLLM extra, start FalkorDB in Docker, and set an API key:
pip install graphrag-sdk[litellm] docker run -d -p 6379:6379 -p 3000:3000 --name falkordb falkordb/falkordb:latest export OPENAI_API_KEY="sk-..."
For PDF ingestion the README says to install the pdf extra instead, as pip install graphrag-sdk[litellm,pdf]. Python 3.10 or later is required according to the badge in the README.
The client is constructed as an async context manager. GraphRAG takes three arguments in the example: a ConnectionConfig with host and graph_name, an llm built from LiteLLM, and an embedder built from LiteLLMEmbedder. The example uses model="openai/gpt-5.5" for generation and model="openai/text-embedding-3-large" with dimensions=256 for embeddings. Note that 256 dimensions in the example differs from the 1024 dimensions used in the benchmark configuration, so embedding width is a parameter you are expected to tune rather than inherit.
Ingestion is a single awaited call: rag.ingest(text=..., document_id="my_doc"). The README shows the returned object carrying nodes_created and relations_created, though the excerpt cuts off mid-line at relations_created, so the full field list is not confirmed here. Passing a file path instead of text is how PDFs are ingested once the pdf extra is present. Beyond host and graph_name, authentication, TLS and connection pooling settings are not verifiable from the README alone.
The benchmark table and what it does not tell you
The README publishes a ranked table. FalkorDB GraphRAG SDK sits first with 66.09 on Novel (multi-document), 76.87 on Medical (single-document) and 71.48 overall. G-reasoner is second at 66.12 overall, HippoRAG2 fourth at 60.67, and plain vector RAG with reranking sixth at 55.39. MS-GraphRAG (local) is last at 48.05.
The methodology is disclosed in more detail than most vendor tables bother with, and that disclosure is the reason the numbers are worth reading at all. Accuracy per dataset is the unweighted mean of four task categories: fact retrieval, complex reasoning, contextual summarization and creative generation. The overall figure is the project's own average across the two datasets, and the README says so plainly, noting that the leaderboard ranks each dataset separately. The Novel set has 20 documents and 2,010 questions; Medical has 1 corpus and 2,062 questions. FalkorDB's run used gpt-4o-mini on Azure OpenAI at temperature 0.7, text-embedding-3-large at 1024 dimensions, text-to-Cypher retrieval enabled, and the benchmark's own generation_eval.py unmodified as the judge. Competitor numbers are taken from the published leaderboard unchanged.
Two things to hold onto. First, the comparison is not like for like in configuration: FalkorDB's entry was scored with text-to-Cypher enabled and a specific embedding width, and the README does not state that competitors ran with equivalent settings. Second, the four-category mean includes creative generation, which is a looser target than fact retrieval. A system that answers factual questions well but writes dull summaries can lose ground on a metric that has little to do with whether the retrieved evidence was correct. The per-category breakdown lives on the separate methodology page, which is where I would look before quoting the overall figure internally.
Where the graph approach loses to plain vector RAG
The honest answer is in the project's own table. Vector RAG with reranking scores 55.39 overall, and on the Medical single-document set it reaches 62.43 against FalkorDB's 76.87. The gap is real but it is not the order of magnitude the marketing framing implies, and the cost side of the ledger is not in the table at all.
Graph construction is an LLM pass over every document. You pay for extraction before you ever answer a question, and you pay again whenever the source material changes, because a re-ingest is another extraction run. A vector index is cheaper to build and cheaper to rebuild. If your corpus is a few hundred chunks and your questions are answerable from a single passage, the graph is overhead: you are buying traversal you will not use and paying an extraction bill for it.
The second case where the SDK is the wrong tool is when your schema is genuinely unknown. The ontology constrains extraction, which is the source of the reliability benefit, but it also means you must know your domain's entity and relationship types up front. Exploratory work over a corpus you do not yet understand fits a lighter pipeline better.
The third case is a team that cannot operate FalkorDB. The SDK is not a drop-in replacement for an existing Postgres or Elasticsearch retrieval layer. It needs a FalkorDB instance reachable at a host and port, and the README's own quick start assumes you can run Docker. That is a deployment commitment, not a library import.
Alternatives and the actual difference in approach
The closest named alternative is HippoRAG2, which scores 60.67 overall against FalkorDB's 71.48. The README does not describe HippoRAG2's architecture, so the comparison I can make is limited to what the table shows: a roughly eleven-point overall gap, with the larger share of it on the multi-document Novel set. HippoRAG2 is also a graph-based retrieval method, which means the choice between them is not graph versus no graph, it is whose graph construction and traversal you prefer.
The more instructive comparison is vector RAG with reranking at 55.39 overall, because the difference in approach is structural rather than incremental. A vector pipeline embeds chunks, retrieves the nearest ones at query time and reranks them. It has no extraction stage, no ontology and no traversal, and it cannot follow a relationship that spans two documents unless both documents happen to be retrieved. GraphRAG-SDK inverts that: the expensive work happens at ingestion, the query becomes a Cypher traversal over typed edges, and the answer can cite the specific chunks an entity was mentioned in. The trade is upfront cost and schema commitment against multi-hop reach and traceability.
LightRAG, at 53.84 overall, and Fast-GraphRAG, at 58.07, are also in the table. Anyone weighing them should read their documentation directly rather than infer from a single score.
Maintenance, licence and what to check before you commit
The repository is Apache-2.0 and not archived. The release cadence shows v1.2.0 and v1.3.0 in June 2026 and v1.4.0 in August 2026, with the last push to main in September 2026. That is a project moving on roughly a quarterly minor-release rhythm, which means upgrade work is a recurring cost rather than a one-off. The SDK sits between three moving surfaces: the FalkorDB server image, the LLM and embedding providers behind LiteLLM, and the SDK's own API. A minor release can shift any of the three.
Apache-2.0 is permissive and includes an explicit patent grant, which matters for a component that sits in your retrieval path. It does not obligate you to publish your application code. It also does not cover the models you call through LiteLLM or the FalkorDB server image, which carry their own terms. That is a description of the licence text, not legal advice; run your own review if the deployment is regulated.
What to verify first is narrow and concrete. Run the quick start against your own FalkorDB instance and confirm that graph_name isolation behaves the way your tenancy model assumes, since the README treats it as the isolation mechanism without spelling out the boundary. Then take grounded_answers_with_abstention.py and run it against a sample of your own documents, watching where it abstains and where it answers, because that file is an example rather than a calibrated policy. If the abstention behaviour is wrong on your data, the reliability story the README tells does not transfer, and you will have learned that before writing production code against the SDK.
Editorial conclusion
Adopt GraphRAG-SDK if your questions need multi-hop traversal over typed entities and you are willing to run FalkorDB alongside your application, because the SDK does not abstract the database away. Skip it if a single-document question-answering bot over a few hundred chunks is all you need, since vector retrieval with reranking already scores 55.39 overall in the project's own comparison table. Before committing, verify two things yourself: that the Cypher your ontology generates is valid against your own schema, and that the abstention threshold in grounded_answers_with_abstention.py behaves the way you want on your data, because the repository ships the example rather than a tuned default.
Frequently asked questions
What is the FalkorDB GraphRAG SDK used for?
It is a retrieval harness over a FalkorDB knowledge graph, built on the idea that the retrieval harness matters more than the model. Answers are grounded in context retrieved from the graph, `MENTIONED_IN` provenance edges trace entity mentions to their source chunks, and `return_context=True` hands the retrieval trail back to the application so it can validate claims and gate generation when evidence is insufficient.
How does the GraphRAG SDK benchmark compare with plain vector RAG?
The page gives it 71.48 overall against 55.39 for RAG with rerank and 48.05 for MS-GraphRAG local. Dataset accuracy is an unweighted mean of fact retrieval, complex reasoning, contextual summarize, and creative generation, and Overall is the mean of the Novel and Medical dataset scores. FalkorDB was scored in August 2026 with `gpt-4o-mini` at temperature 0.7 and `text-embedding-3-large` at 1024 dimensions, with the benchmark's own `generation_eval.py` unmodified as the judge, while competitor numbers are taken from the published leaderboard unchanged.
Does the GraphRAG SDK work with Neo4j or other graph databases?
The repository does not contain a Neo4j comparison or an adapter for another database. The SDK is built on FalkorDB and connects through `ConnectionConfig(host="localhost", graph_name="my_graph")`, with text-to-Cypher retrieval and the FalkorDB browser on port 3000.
What do you need before running the GraphRAG SDK?
A running FalkorDB and a model API key. The quick start installs `graphrag-sdk[litellm]`, starts `falkordb/falkordb:latest`, and exports `OPENAI_API_KEY`. PDF ingestion needs the extra, `pip install graphrag-sdk[litellm,pdf]`, and the sample configuration differs from the benchmark configuration, using `openai/gpt-5.5` and 256 embedding dimensions instead of `gpt-4o-mini` and 1024.
How does the GraphRAG SDK handle multiple tenants?
Through the graph name in the connection configuration, annotated in the sample as per-tenant isolation, so entities live in separate graphs inside one database. The documented samples show no per-tenant credential, database, or container, and the compose file defines a single FalkorDB service.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/falkordb-graphrag-sdk)Star history chart for your README
[](https://hysenlabs.com/projects/falkordb-graphrag-sdk)Was this useful?