Resume_Builder_AIHawk: tailoring a resume from a job URL
Resume_Builder_AIHawk is a powerful Python tool that allows you to automatically customize your resume based on a job URL, ensuring it perfectly aligns with the job requirements and skills. With an interactive command-line interface, this tool makes it easy to navigate through options and select from various pre-defined styles
At a glance
- What is it?
- Resume_Builder_AIHawk is a Python CLI that reads a job listing URL and rewrites your resume content to match it. The mechanism is simple and the setup is YAML-heavy, which is the real cost of using it.
- Who is it for?
- Adopt Resume_Builder_AIHawk if you apply to many similar roles and you are willing to maintain a single YAML source of truth for your history. Skip it if you need a stable, versioned output pipeline or if you cannot install Chrome, since the README treats a local Chrome install as a prerequisite.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 28 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
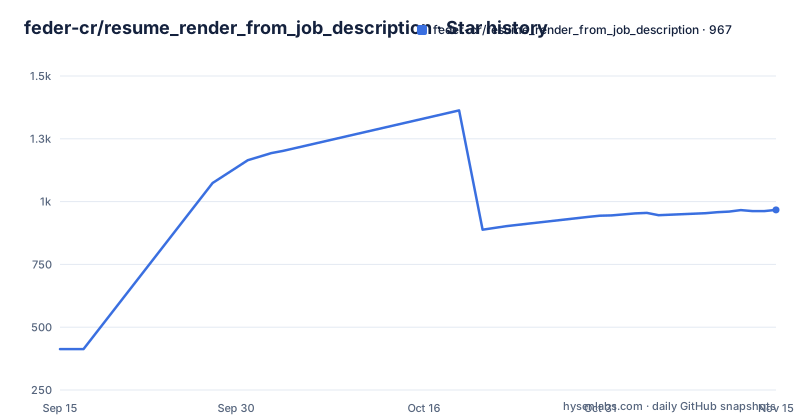
- feder-cr/resume_render_from_job_description967 ★ · +554
| Repository | 2026-09-15 | 2026-11-15 |
|---|---|---|
| feder-cr/resume_render_from_job_description | 413 | 967 |
554 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: one resume against many job descriptions
Most job seekers keep one resume and send it everywhere. The result is a document that mentions the right technologies in the wrong order, or omits the three keywords the listing repeats. Resume_Builder_AIHawk takes the opposite approach: you keep your history in one structured file, and the tool produces a resume aimed at a specific posting identified by its URL. The README frames this as the core feature, describing the tool as able to "tailor it perfectly based on a specific job description" after you input the job listing URL.
The audience is narrow and specific. This is for someone applying to many similar roles who is comfortable editing YAML and running a Python script from a terminal. It is not for someone who wants a web form, a hosted service, or a resume they never have to re-enter. The repository ships plain_text_resume_example.yaml precisely because the expected workflow is: copy the example, fill it in, keep it as your master record.
What the CLI actually does with the job URL
Three pieces are visible from the repository layout and the README. First, main.py is the entry point, and the README describes an interactive command-line interface where you "navigate through options and prompts" rather than passing flags. Second, plain_text_resume.yaml holds your personal information, education, experience and projects as structured data. Third, the real rendering work is delegated to lib_resume_builder_AIHawk, a separate package listed in requirements.txt alongside pyyaml, requests and inquirer.
That dependency split matters more than it looks. The repository itself contains no rendering logic; it contains the CLI wrapper, the YAML schema and the prompt flow. The resume output, the style templates and the job-description parsing all live in the library. So when you evaluate this project, you are really evaluating two things: the YAML contract defined here, and the library's behaviour, which the README does not document in detail.
The requests and inquirer dependencies are consistent with the described flow: fetch the job page, then ask you questions in the terminal. requests is HTTP only, so pages that render their content client-side will not be readable this way. The README does not discuss that case, and it does not describe any fallback when a URL returns nothing useful.
Installing Resume_Builder_AIHawk and generating a first resume
The README lists four prerequisites before any code runs: a current Python install, Google Chrome installed in its default location, a clone of the repository, and pip install of the requirements. Chrome is unusual enough to flag. The README does not explain why a browser is needed for a resume generator, but it is listed as step 2, before the clone.
Clone and install first:
git clone https://github.com/yourusername/resume_builder_AIHawk.git
cd resume_builder_AIHawk
pip install -r requirements.txt
The clone URL above is copied from the README, which still uses a placeholder username. Use the actual repository URL for feder-cr/resume_render_from_job_description instead. After install, the requirements file pulls pyyaml, requests, inquirer and lib_resume_builder_AIHawk.
Next, create your data file in the project root. The README says to create plain_text_resume.yaml there, and the repository ships plain_text_resume_example.yaml as a model. The top-level personal_information block looks like this:
personal_information:
  name: [Name]
  surname: [Surname]
  date_of_birth: "[DD/MM/YYYY]"
  country: [Country]
  city: [City]
  address: [Address]
  phone_prefix: "[+Country Code]"
  phone: "[Phone Number]"
  email: [Email Address]
  github: [GitHub URL]
  linkedin: [LinkedIn URL]
The README marks github and linkedin as optional. Everything else is expected. Note that date_of_birth, phone_prefix and phone are quoted strings, not numbers, which avoids YAML stripping leading zeros or plus signs.
The experience section is a list, so you can repeat the block for each job:
experience_details:
  - position: [Job Title]
    company: [Company Name]
    employment_period: "[MM/YYYY - MM/YYYY or Present]"
    location: [Location]
    industry: [Industry]
    key_responsibilities:
      - [Responsibility Description]
    skills_acquired:
      - [Skill]
The README shows three entries under both key_responsibilities and skills_acquired, but the list structure means the count is yours to choose. education_details and projects follow the same pattern: a list of mappings, with exam grades nested under each degree and a name, description and link under each project.
With the YAML in place, run the entry point and answer the prompts:
python main.pyThe README does not show a sample session, so what you see at each prompt is not documented. What you should expect, based on the feature list, is a choice of pre-defined styles and a prompt for the job URL. The repository does include created_resume_example.pdf, which is the only concrete picture of the output format available without running the tool.
The YAML file is the whole product, and that is the constraint
Everything the tool knows about you lives in one file that you hand-edit. That is a deliberate design choice with a real cost. There is no schema validation described in the README, no migration path if the expected keys change, and no way to keep two versions of a bullet point side by side. If you rewrite a responsibility line for one application and then want the original back, you need your own version control.
The README also does not document what happens when a field is missing or malformed. The example file uses bracketed placeholders like [Name] and [Company Name], which are valid YAML strings, so a half-filled file will parse and then produce a resume containing literal square brackets. Nothing in the README suggests the tool checks for this. Treat the example as a template to overwrite completely, not as a file to partially edit.
The employment_period field is a free-form string, not two dates. The README's own example includes "Present" as an accepted value, which means the tool is not computing durations or sorting roles by date. If your resume needs chronological ordering, you control it by the order of entries in the list.
Where this approach breaks down
The job-URL input is the weakest link. A URL is not a job description; it is a pointer to a page that may require a login, may be region-locked, may have expired, or may load its text with JavaScript. The README describes no handling for any of these. If you are applying through a portal that shows the posting only after sign-in, the fetch step has nothing to work with, and the README does not say what the tool does in that case.
There is also a subtler problem. Tailoring a resume to a single posting optimizes for one application and degrades your ability to compare versions. If you generate a different PDF for every listing, you lose the ability to answer "which resume did I send them?" without keeping the job URL and the YAML state alongside each output. The repository does not include a mechanism for that, and the README does not mention one.
Finally, the interactive CLI is a poor fit for automation. The README describes navigating options and prompts, which means a human at a terminal. If your goal is to generate twenty tailored resumes in a batch, this interface is the wrong shape, and nothing in the repository suggests a non-interactive mode.
How it compares to editing a resume by hand or with a template
The obvious alternative is a LaTeX or Markdown resume template plus a manual edit per application. The difference in approach is where the job description gets read. With a template, you read the posting, decide which of your existing bullets to promote, and edit the file. Resume_Builder_AIHawk moves that reading step into the tool: you supply the URL and the CLI drives the selection.
That trade is not automatically in the tool's favour. A manual edit gives you judgement about which experience to foreground, and it produces a diff you can review. The tool's advantage is speed and consistency across many applications, plus a single source of truth for your history. Its disadvantage is that you are trusting an automated pass over a scraped page to pick the right emphasis, and the README gives no detail about how that selection is made. The library is a black box from the README's point of view.
A second alternative is a plain YAML-to-PDF pipeline you write yourself, using the same plain_text_resume.yaml idea but your own rendering. That keeps the structured-data benefit and removes the URL-scraping step entirely. It is more work up front and gives you full control over the output, which matters if the generated PDF's layout is something you need to control precisely.
Licence, maintenance and what upgrading costs you
The project is MIT licensed, which permits commercial and private use, modification and redistribution provided the copyright notice and permission notice are retained. That is permissive and places few obligations on you. It does not, however, cover lib_resume_builder_AIHawk, which is a separate package installed from PyPI; its licence is not stated in the README, and if you plan to redistribute the tool or embed it in a product, you need to check that dependency's terms independently. Nothing here is legal advice.
The last push to the repository was on 2026-08-18, and the repository is not archived. The repository has no published GitHub releases, so there is no versioned artifact to pin against. That shapes the upgrade cost: you install from a clone of main, and pip install -r requirements.txt will pull whatever the current published versions of pyyaml, requests, inquirer and lib_resume_builder_AIHawk happen to be. There is no lockfile in the repository listing, so two installs a month apart can produce different environments.
The practical consequence is that an upgrade can change the resume output without any change on your side, because the rendering lives in a dependency. If you keep generated PDFs, keep the YAML state that produced them, or you will not be able to reproduce an older output. The README documents no rollback procedure and no version pinning guidance.
Editorial conclusion
Adopt Resume_Builder_AIHawk if you apply to many similar roles and you are willing to maintain a single YAML source of truth for your history. Skip it if you need a stable, versioned output pipeline or if you cannot install Chrome, since the README treats a local Chrome install as a prerequisite. Before committing, verify two things yourself: whether lib_resume_builder_AIHawk pulls in any LLM or API key requirement that secrets.yaml is meant to hold, and how the generated PDF handles a resume with more than two or three experience entries.
Frequently asked questions
What does Resume_Builder_AIHawk need before I can run it?
The README lists a current Python installation, Google Chrome installed in its default location, and the dependencies from requirements.txt. You also need to create plain_text_resume.yaml in the project root before running main.py.
How do I install Resume_Builder_AIHawk?
Clone the repository, change into the project directory, and run pip install -r requirements.txt. The README's clone command uses a placeholder username, so substitute the real repository URL.
Where do I put my resume details for Resume_Builder_AIHawk?
In plain_text_resume.yaml in the project root. It holds personal_information, education_details, experience_details and projects, and the repository includes plain_text_resume_example.yaml as a model to copy.
Does Resume_Builder_AIHawk work with any job URL?
The README does not say. It describes fetching a job listing from a URL but documents no handling for pages behind a login, region locks, expired postings, or content that loads with JavaScript.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/feder-cr-resume-render-from-job-description)Star history chart for your README
[](https://hysenlabs.com/projects/feder-cr-resume-render-from-job-description)Was this useful?