huggingface/smollm: SmolLM3 and SmolVLM for on-device text and vision
Everything about the SmolLM and SmolVLM family of models
At a glance
- What is it?
- The huggingface/smollm repository collects the SmolLM3 language model, the SmolVLM vision-language model, and the tooling around them. It is a good fit when you need a 3B model with published training data and configs, or a small multimodal model you can run locally.
- Who is it for?
- Adopt huggingface/smollm if you need a small text model whose training data mixture and configs are published, or a compact vision-language model for visual QA and image description. Skip it if your workload needs a much larger model, or if you need documented rollback and versioning procedures, which the README does not cover.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 40 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
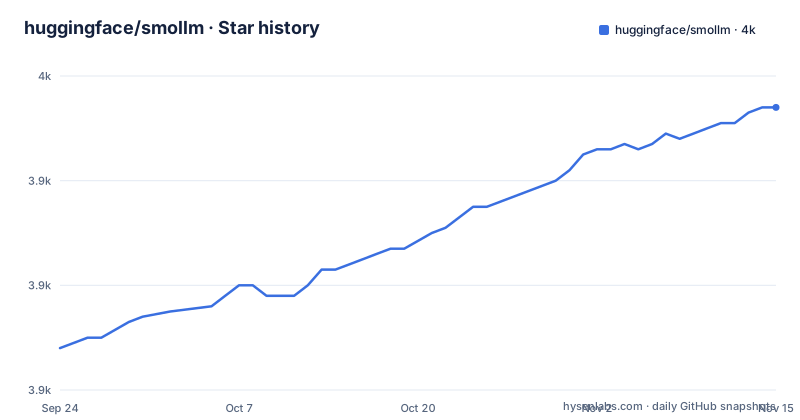
- huggingface/smollm3,954 ★ · +46
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| huggingface/smollm | 3.9k | 4k |
46 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What huggingface/smollm actually ships
This repository is a family, not a single artifact. The README describes SmolLM3, a 3B language model trained on 11T tokens, positioned as competitive with larger 4B alternatives, and SmolVLM, a compact multimodal model that processes images and text for visual QA, image description and visual storytelling. The top-level layout reflects that split: text/, vision/ and tools/, with tools/ holding shared utilities and inference helpers under smol_tools/, smollm_local_inference/ and smolvlm_local_inference/. The audience is engineers who want small models they can run on-device rather than call through an API. The README states the goal directly: fully open models for text and vision that run effectively on-device while maintaining strong performance. That framing matters more than any single benchmark, because the repository bundles weights, training details and local inference paths in one place.
SmolLM3's mechanism: dual-mode reasoning and long context
SmolLM3 is an instruct model with dual mode reasoning, supporting think and no_think modes. That is the most consequential design choice in the family, because it means the same weights can produce a reasoning trace or answer directly, and the caller chooses which. The README also lists long context up to 128k using NoPE and YaRN, and multilingual support for six languages: English, French, Spanish, German, Italian and Portuguese. The open claim is specific: open weights plus full training details, including the public data mixture and training configs. The datasets are named in the README, including SmolTalk for instruction tuning, FineMath for mathematics pretraining and FineWeb-Edu for educational content. If you have ever tried to reproduce a model release and found the data mixture withheld, that is the gap this repository is trying to close. The trade-off is scale. A 3B model with 11T tokens of training is still a 3B model, and the README's comparison set (Llama 3.2 3B, Qwen2.5 3B, and the larger Qwen3 and Gemma3 4B models) tells you the intended weight class.
Installing SmolLM3 and running a first prompt
The README's getting-started example uses the transformers library and pulls weights from the Hugging Face Hub, so no separate installer is documented. The model identifier is HuggingFaceTB/SmolLM3-3B and the device variable is set to cuda for GPU or cpu for CPU usage. Note that the README's snippet loads the model without an explicit dtype or quantization argument, so memory use follows the default loading behaviour of transformers rather than anything the repository pins.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "HuggingFaceTB/SmolLM3-3B"
device = "cuda"  # for GPU usage or "cpu" for CPU usage

tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
).to(device)
The chat template is applied before generation, with add_generation_prompt set to true. The README's example passes a single user message and generates with max_new_tokens=32768, which is a large ceiling; on a machine with limited memory you will want to lower it rather than copy it verbatim.
prompt = "Give me a brief explanation of gravity in simple terms."
messages_think = [
    {"role": "user", "content": prompt}
]

text = tokenizer.apply_chat_template(
    messages_think,
    tokenize=False,
    add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
Generation then slices off the prompt tokens before decoding, so the printed text is the model's answer only. The variable name messages_think hints at the dual-mode behaviour, but the README does not show how to switch to no_think.
generated_ids = model.generate(**model_inputs, max_new_tokens=32768)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]) :]
print(tokenizer.decode(output_ids, skip_special_tokens=True))
SmolVLM: images in the same conversation
SmolVLM takes a different input shape. The README's example builds a message whose content is a list of typed parts, an image entry followed by a text entry asking what is in the image. That structure is what allows multiple images in a single conversation, which the README lists as a capability alongside visual QA and image description. The example uses AutoProcessor and AutoModelForVision2Seq with the identifier HuggingFaceTB/SmolVLM-Instruct. What the README does not show is the generation step for vision: the snippet stops after constructing the messages list, so you will need the vision/README.md documentation to fill in how the processor output is passed to the model. Treat the root README as a pointer to the deeper docs rather than a complete tutorial for the vision path.
from transformers import AutoProcessor, AutoModelForVision2Seq

processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM-Instruct")
model = AutoModelForVision2Seq.from_pretrained("HuggingFaceTB/SmolVLM-Instruct")

messages = [
    {
        "role": "user",
        "content": [
            {"type": "image"},
            {"type": "text", "text": "What's in this image?"}
        ]
    }
]
Where the documentation goes quiet
The root README is a hub page, and several things you would want before adopting are simply not there. There is no documented rollback or version pinning procedure, no stated minimum RAM or VRAM figure for either model, and no guidance on quantizing SmolLM3 for smaller devices, even though on-device operation is the stated goal. The dual-mode reasoning is announced but the README does not show the token or flag that selects no_think. The multilingual claim names six languages, so anything outside English, French, Spanish, German, Italian and Portuguese is outside the documented scope. On the vision side, the README lists capabilities but stops short of a runnable generation example. None of this makes the project unusable, but it does mean the deeper per-directory READMEs under text/, vision/ and tools/ are where the real instructions live, and the root page is best read as an index. If you need a documented support matrix before you commit engineering time, that matrix is not on this page.
SmolLM3 versus Llama, Gemma and Qwen at the same size
The README makes its own comparison: the 3B SmolLM3 model is stated to outperform Llama 3.2 3B and Qwen2.5 3B while staying competitive with larger 4B alternatives such as Qwen3 and Gemma3. The difference in approach is not architecture so much as disclosure. For SmolLM3, the training data mixture and training configs are published, and the pretraining datasets are collected on the Hub, with SmolTalk, FineMath and FineWeb-Edu named by name. If your work requires tracing what a model was trained on, that is the practical distinction between this family and a weights-only release. The flip side is that a published mixture is a snapshot: it tells you what went in, not how the model will behave on your specific domain. For vision, SmolVLM competes in the small multimodal space rather than against large vision models, and the README's own framing is on-device efficiency, so evaluating it against a hosted multimodal API is a category error. Compare it against other small local vision models instead.
Licence, maintenance and what an upgrade costs you
The repository is licensed Apache-2.0, which is a permissive licence, though the README does not spell out per-model terms and the Hub model cards are the place to confirm them for SmolLM3-3B, SmolLM3-3B-Base and SmolVLM-Instruct. The repository is not archived, and the last push was on 2026-09-23, so the code is current as of that date. The repository has no published GitHub releases, which means there is no tagged version list to pin against; if you need reproducible builds you will have to pin the model identifiers and your own dependency versions rather than a repository tag. Upgrading across generations is not a drop-in: SmolLM2 and SmolLM3 are separate model collections with separate identifiers, and the README's own search-adjacent framing treats the generations as distinct. Budget for re-evaluating prompts and chat-template behaviour whenever you move between them, because the chat template is applied in your code, not inside the weights.
Editorial conclusion
Adopt huggingface/smollm if you need a small text model whose training data mixture and configs are published, or a compact vision-language model for visual QA and image description. Skip it if your workload needs a much larger model, or if you need documented rollback and versioning procedures, which the README does not cover. Before committing, verify the SmolLM3-3B and SmolVLM-Instruct weights load on your target hardware, and check that the multilingual support listed as six languages covers the ones you need.
Frequently asked questions
What is SmolLM good for?
The README describes it as a family of efficient, lightweight models for text and vision that run effectively on-device. SmolLM3 handles text generation and reasoning, while SmolVLM handles visual QA, image description and visual storytelling.
Who created SmolLM?
The repository is huggingface/smollm, and the README describes the family as models from Hugging Face. The model identifiers are published under the HuggingFaceTB organisation on the Hugging Face Hub.
What is a Smol VLM?
SmolVLM is the compact multimodal model in this repository, documented as processing both images and text. The README lists visual QA, image description and visual storytelling as its tasks, and notes it can handle multiple images in a single conversation.
how to use smollm
The README's getting-started example loads HuggingFaceTB/SmolLM3-3B with AutoTokenizer and AutoModelForCausalLM from transformers, applies the chat template with add_generation_prompt set to true, then calls model.generate. For vision, it loads HuggingFaceTB/SmolVLM-Instruct with AutoProcessor and AutoModelForVision2Seq.
is smollm open source
The repository is licensed Apache-2.0 and is not archived. The README also states that SmolLM3 is a fully open model with open weights plus full training details, including the public data mixture and training configs.
is smollm multilingual
SmolLM3 is documented as supporting six languages: English, French, Spanish, German, Italian and Portuguese. The README does not claim coverage beyond those six.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-smollm)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-smollm)Was this useful?