x-transformers: A Reference Transformer With Experimental Attention Flags
A concise but complete full-attention transformer with a set of promising experimental features from various papers
At a glance
- What is it?
- lucidrains/x-transformers packages encoder, decoder, encoder-decoder, and vision transformer variants behind a single attention-layer API, with Flash Attention and a long list of paper-derived options exposed as constructor arguments. It is a readable implementation to build on, not a training framework, and the README says little about long-run maintenance or numerical edge cases.
- Who is it for?
- Adopt x-transformers if you want a compact, MIT-licensed implementation of full attention where encoder, decoder, encoder-decoder and vision variants share one attention-layer interface, and you are comfortable reading the source when a flag's behaviour is unclear. Do not adopt it if you need a maintained training stack with checkpoint conversion, tokenizer integration and a documented compatibility policy.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
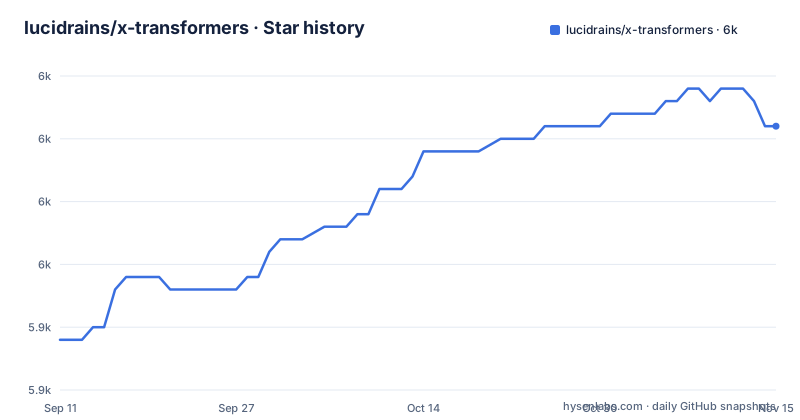
- lucidrains/x-transformers5,961 ★ · +17
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| lucidrains/x-transformers | 5.9k | 6k |
17 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem x-transformers Solves
Most transformer code is written once for one architecture. A BERT-style encoder, a GPT-style decoder, and a T5-style encoder-decoder end up as three separate repositories with three separate attention implementations, and a change to the attention mechanism has to be repeated in each. x-transformers puts the attention layers in one place and wraps them. The README describes it as "a concise but fully-featured transformer, complete with a set of promising experimental features from various papers." The audience is people who want to try a paper's attention variant without rewriting a model, and people who want to read a concise working transformer implementation. It is not aimed at teams that want a pretrained checkpoint and a fine-tuning script. The package gives you the architecture and the training loop is yours to write.
One Attention Layer, Four Wrappers
The API splits into two kinds of object. TransformerWrapper handles token embedding, positional handling and the output projection to vocabulary size. The attn_layers argument takes an Encoder or a Decoder, and that is where depth, heads, dimension and the attention variants live. XTransformer is the encoder-decoder combination, with separate enc_ and dec_ prefixed arguments for token counts, depth, heads and maximum sequence length. ViTransformerWrapper handles images by patchifying them and feeding the patches through an Encoder, so image classification is the same attention code with a different front end. The multimodal case is the clearest demonstration of the design. In the PaLI example the README gives, a ViTransformerWrapper and an XTransformer are composed into one language-vision model, and in the image-to-caption example the vision encoder is called with return_embeddings and feeds a Decoder built with cross_attend = True. That is the whole architecture story: one attention implementation, several ways of feeding it.
Getting It Running
Installation is a single command: pip install x-transformers. The README's decoder-only example is the shortest path to a working model. Build a TransformerWrapper with num_tokens = 20000, max_seq_len = 1024, and attn_layers = Decoder(dim = 512, depth = 12, heads = 8), then call .cuda() and pass a tensor of shape (1, 1024). The return is (1, 1024, 20000), logits over the vocabulary. The encoder-only form is the same wrapper with Encoder instead of Decoder, plus a boolean mask argument. For sequence-to-sequence, XTransformer takes enc_num_tokens, enc_depth, enc_heads, enc_max_seq_len and the dec_ equivalents, and the forward call returns a loss tensor when given source and target, so loss.backward() follows directly. The README's GPT-3 configuration is dim = 12288, depth = 96, heads = 96, attn_dim_head = 128, with the note that "you wouldn't be able to run it anyways." That is worth taking literally: the package scales the definition, not the hardware. Dropout is configured at construction. emb_dropout sits on the wrapper; layer_dropout, attn_dropout and ff_dropout sit on the attention layers, and the README labels layer_dropout as stochastic depth, meaning whole layers are dropped rather than individual activations.
Flash Attention as a Constructor Flag
The feature the README spends the most words on is Flash Attention. The explanation it gives is that the attention matrix is processed in tiles, keeping only a running softmax and exponentiated weighted sums, and that recomputing on the backward pass in the same tiled fashion keeps memory linear in sequence length. The README also notes that the same kernel is reachable through PyTorch 2.0's scaled_dot_product_attention, and that Llama was trained with it. Turning it on in this package is a single argument: set attn_flash to True on the attention layer. The important sentence is the caveat that follows: "The only reason to avoid it is if you require operating on the attention matrix (dynamic positional bias, talking heads, residual attention)." That is a real constraint, not a footnote. If your variant needs to read or modify the attention matrix itself, the fused kernel is the wrong path and you are back to the naive implementation with the memory profile that implies. Which of the package's own experimental attention features are compatible with attn_flash is something to verify in the source rather than assume.
Where the Documentation Runs Out
The README is a tour of examples, and examples are not a specification. Constructor arguments appear in code blocks, so the full set of options on Decoder or Encoder is best read from the source. The experimental features are mentioned in the project description. The version history is active, with 2.16.1 released 2026-02-12, 2.16.0 on 2026-02-07 and 2.15.2 on 2026-02-03, and the repository's last push is 2026-11-01, with pyproject.toml now at version 2.31.11. Frequent minor releases on a library like this usually mean the experimental surface moves. The practical consequence is that pinning a version is not optional if you depend on a specific flag. The MIT licence is permissive and places no conditions on how you use the code beyond retaining the notice, but this is not legal advice; check the licence file for the exact terms.
The Alternative: Hugging Face Transformers
The obvious comparison is Hugging Face Transformers, and the difference is not quality but scope. Hugging Face ships model definitions plus pretrained weights, tokenizers, configuration classes, checkpoint conversion utilities and a training stack. x-transformers ships model definitions. If you want to load a published checkpoint and fine-tune it, Hugging Face has the checkpoint and x-transformers does not. If you want to implement a paper's attention variant and see whether it trains, Hugging Face's model classes are large and opinionated, and adding a new attention path means working within its configuration system. x-transformers is the opposite trade: fewer moving parts and no pretrained weights to fall back on. The PaLI example in the README is a good illustration of the difference. It shows how to compose a vision transformer and an encoder-decoder and prepend image embeddings, but it does not provide a trained PaLI. What it provides is the architecture.
Who Should Adopt It
Use x-transformers if you are prototyping an architecture and want the attention layer to be the part you edit. The constructor-argument style means a variant is usually a new keyword rather than a new class, and the shared attention code means an encoder, a decoder and a vision model all exercise the same path. Use it if you want to read the implementation of Flash Attention integration or of an experimental attention mechanism in Python rather than in CUDA, and if you are prepared to read the source when the README is silent. Do not use it if you need pretrained weights, a tokenizer, a trainer, distributed training helpers or a documented compatibility guarantee across versions. Do not use it if your attention variant needs to operate on the attention matrix and you were planning to enable attn_flash, because the README states plainly that those two requirements conflict. Before adopting, pin the version, confirm which of the experimental features you need are present in that version, and check that attn_flash works on your PyTorch and CUDA build, since the README ties the kernel to PyTorch 2.0's scaled_dot_product_attention rather than describing a fallback path.
Editorial conclusion
Adopt x-transformers if you want a compact, MIT-licensed implementation of full attention where encoder, decoder, encoder-decoder and vision variants share one attention-layer interface, and you are comfortable reading the source when a flag's behaviour is unclear. Do not adopt it if you need a maintained training stack with checkpoint conversion, tokenizer integration and a documented compatibility policy. Before committing, check the release notes for the version you pin, verify that attn_flash behaves as expected on your PyTorch and CUDA combination, and read the attention module to confirm which experimental features are actually wired into the path you plan to use.
Frequently asked questions
Has a transformer ever fallen in love with a human?
Nothing in this library speaks to that. x-transformers is a PyTorch building library of Encoder and Decoder attention blocks, with experimental options such as persistent memory key values and layer dropout, and it contains no dialogue system or language model checkpoint that could converse with anyone.
What are the four types of transformers?
The library does not enumerate types, but its examples cover several shapes: a full encoder decoder through XTransformer, a decoder only stack for GPT like models, an encoder only stack for BERT like models, a vision wrapper for image classification, and a cross attending decoder paired with that vision wrapper for image to caption. GPT3 is shown as a size configuration of the decoder only form rather than as a separate class.
What are the 7 transformer types?
The project does not document a list of seven. What it documents is one outer wrapper taking an inner attn_layers block, with Encoder, Decoder and the paired XTransformer as the pieces, plus optional vision wrappers. The README names individual experimental attention mechanisms rather than fixed architecture categories, and a linked paper for persistent memory is one such mechanism.
What exactly are transformers?
In this library a transformer is assembled from blocks you configure yourself: a TransformerWrapper holding a num_tokens vocabulary size, a max_seq_len, and an attn_layers block given dim, depth and heads. Attention variants are then enabled by keyword arguments such as attn_flash, attn_num_mem_kv and cross_attend, with emb_dropout, layer_dropout, attn_dropout and ff_dropout covering regularization.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lucidrains-x-transformers)Star history chart for your README
[](https://hysenlabs.com/projects/lucidrains-x-transformers)Was this useful?