Llama Cookbook: Meta's Notebook Guide to Inference, Fine-Tuning, and RAG
Welcome to the Llama Cookbook! This is your go to guide for Building with Llama: Getting started with Inference, Fine-Tuning, RAG. We also show you how to solve end to end problems using Llama model family and using them on various provider services
At a glance
- What is it?
- Meta's llama-cookbook is a collection of Jupyter notebooks and recipes for building with the Llama model family. It covers inference, fine-tuning, RAG, and end-to-end use cases, but its recent refactor and API-centric focus require careful navigation.
- Who is it for?
- Adopt llama-cookbook if you are a developer or researcher who wants copy-paste notebook examples for Llama inference, fine-tuning, or RAG, especially if you plan to use the hosted Llama API or third-party providers. Skip it if you need a maintained library with stable APIs, because the repo is primarily a set of examples that change with each model release.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 179 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
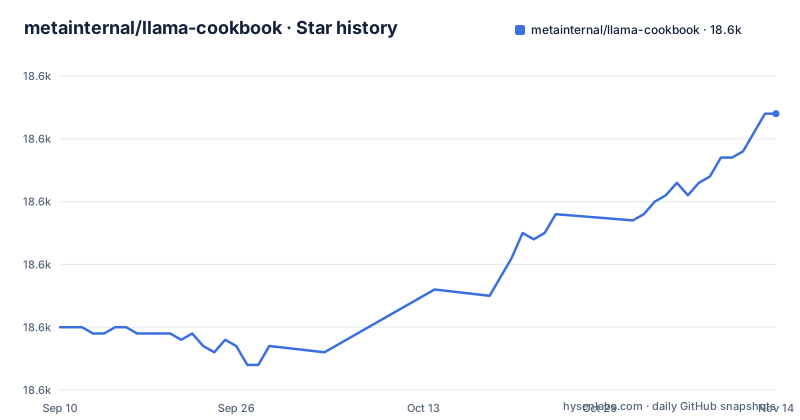
- metainternal/llama-cookbook18,594 ★ · +34
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| metainternal/llama-cookbook | 18.6k | 18.6k |
34 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What llama-cookbook actually is
The repository is Meta's official collection of Jupyter notebooks and guides for building with the Llama model family. It is not a software library in the traditional sense. It is a set of recipes that walk you through inference, fine-tuning, and retrieval-augmented generation, plus end-to-end use cases that span domains like WhatsApp bots, research paper analysis, and character mind maps. The README is explicit: it is the official guide to building with Llama. The primary audience is developers who want practical, runnable examples rather than reading API documentation. If you are evaluating it for adoption, understand that you are adopting a set of examples, not a framework. The repo was renamed from llama-recipes to llama-cookbook, which signals a shift from a package-like structure to a cookbook approach.
The refactor and the archive-main branch
The README notes a recent refactor of the repository. It points to an archive-main branch as a snapshot from before the refactor, and it answers FAQ questions about broken links by directing users to that branch. This is a significant maintenance signal. The refactor means that any external references to the old llama-recipes structure may break. The repository's default branch has changed its layout, and the archive branch preserves the old state. For anyone who relied on llama-recipes as a library, this is a breaking change. The README does not detail what changed beyond the rename and restructuring, so you cannot assume backward compatibility. If you find a notebook from an older tutorial that references llama-recipes, you may need to use the archive branch to get the matching code.
What the repository structure tells you
The README's structure section lists four main directories: 3p-integrations, end-to-end-use-cases, getting-started, and src. The 3p-integrations folder contains getting-started recipes and end-to-end use cases from various Llama providers. The getting-started folder is the core reference for inference, fine-tuning, and RAG examples. The end-to-end-use-cases folder shows complete applications, which is where you see the WhatsApp bot and research paper analyzer examples. The src folder contains the original llama-recipes library source and fine-tuning FAQs. This structure suggests that the repository is organized by learning path rather than by model version. That is useful for browsing, but it also means that recipes for different Llama versions coexist, so you must check which model each notebook targets.
Getting started: inference and the Llama API
The README highlights a notebook called build_with_llama_api.ipynb under getting-started, which is the entry point for using the Llama API. There is also a notebook for Llama 4 Scout that demonstrates a 5M long context, and one for Llama 4 Maverick for research paper analysis. To get started, you would open these notebooks in a Jupyter environment. The README links to the Llama API waitlist and documentation, so the first step is to obtain API access. The repository does include a pyproject.toml that defines a package named llama-cookbook (version 0.0.5.post1, built from src/llama_cookbook) with dependencies from requirements.txt, plus optional vllm and langchain extras.
Fine-tuning and the legacy src folder
Fine-tuning is a major focus. The getting-started/finetuning directory contains recipes, and the src folder holds the source for the original llama-recipes library along with fine-tuning FAQs. The src folder is a remnant of the library era. The README points to a Fine-Tuning FAQ in src/docs for questions. This suggests that the fine-tuning examples may rely on code from the src folder, which pyproject.toml packages as src/llama_cookbook. If you want to run fine-tuning, you may need to import from that local src directory. This is a maintenance burden because the src code may not be versioned with the notebooks. The releases show v0.0.5, titled Llama-cookbook v0.0.5 Release, from January 2025, after v0.0.4 releases under the name llama-recipes. No newer release is listed, while pyproject.toml now reads 0.0.5.post1.
End-to-end use cases and provider integrations
The repository is not just about getting started. It includes end-to-end use cases that solve concrete problems. The README lists examples: a WhatsApp bot integrated with Llama API, a research paper analyzer using Llama 4 Maverick, and a book character mind map generator. These are complete applications, not just model calls. The 3p-integrations folder adds recipes from various providers, which is useful if you want to run Llama models on a specific service like vLLM or LangChain. The presence of these folders shows that the cookbook aims to cover the full journey from a single inference call to a deployed application. However, the README does not provide details on how these use cases are deployed. You must open each notebook or README within those folders to see the actual steps. The value here is in seeing how to combine Llama with external tools, but the trade-off is that each use case may have its own dependencies and setup, making it less portable.
Licensing and model-specific terms
The repository itself is licensed under MIT, as shown in the repository metadata. However, the README is careful to link to separate license files for each Llama model version, from Llama 2 through Llama 4. This is a critical distinction. The code in the cookbook is MIT-licensed, but the models you use with it are not. Each model has its own license and acceptable use policy. When you adopt llama-cookbook, you are not getting a license to use Llama models. You must review the specific license for the model you intend to use, such as the Llama 4 license or the Llama 3.3 license, and comply with its terms. The README also links to an Acceptable Use Policy for each model. For an engineering team, this means legal review is required before using any recipe with a production model. The MIT license on the notebooks is permissive, but it does not extend to the model weights or the hosted API usage.
Limitations and when it is the wrong tool
The most obvious limitation is that this is a notebook collection, not a maintained library. The refactor broke links, and the archive branch is a stopgap. The README itself admits that links may be broken. If you need a stable API for fine-tuning or inference in a production pipeline, this repository is the wrong tool. The last listed release, v0.0.5, dates from January 2025. Another limitation is that the recipes are model-specific. A notebook for Llama 4 Scout may not work with Llama 3.1 without changes. The README emphasizes the latest Llama 4 recipes, but it also covers older models, so you must match the notebook to your model. Finally, the reliance on the hosted Llama API for many examples means you need to join a waitlist and obtain access, which may not be available in all regions or for all users. If you want to run models fully on-premises, you will need to adapt the examples to use local inference engines.
Alternatives and what to verify first
A real alternative is the Hugging Face transformers library, which supports Llama models through the meta-llama organization on Hugging Face. The difference is that transformers provides a unified API for model loading and fine-tuning, whereas llama-cookbook gives you notebook examples that may use various frameworks. Another alternative is vLLM for inference, which appears as an optional extra in pyproject.toml. vLLM offers a high-performance serving engine, but it is not a cookbook; it is a deployment tool. If you want fine-tuning, you might look at Axolotl or Unsloth, which are dedicated fine-tuning frameworks, but those are not mentioned in the repository. Before adopting any recipe, verify the Llama model version, the provider integration, and whether the notebook uses the Llama API or a local model. Check the archive-main branch if a link is broken. Confirm that your environment has the required dependencies, such as torch from requirements.txt or the optional langchain extra. The repository is a useful starting point, but it is not a substitute for a well-maintained library.
Editorial conclusion
Adopt llama-cookbook if you are a developer or researcher who wants copy-paste notebook examples for Llama inference, fine-tuning, or RAG, especially if you plan to use the hosted Llama API or third-party providers. Skip it if you need a maintained library with stable APIs, because the repo is primarily a set of examples that change with each model release. Before relying on any notebook, verify that it matches your target Llama version and provider, and check the archive-main branch if you encounter broken links after the refactor. The repository is a starting point, not a production toolkit, so treat every recipe as a template to adapt, not a drop-in solution.
Frequently asked questions
Is Llama ai free?
The repository does not describe the models as free. Its licence section links a separate licence and a separate acceptable use policy for each of six model generations, hosted in a models repository. The project's own package metadata classifies the licence as other or proprietary, even though the repository's recorded licence field reads MIT, so the terms come from the model rather than the example code.
How do I train a Llama?
The repository describes itself as a companion project to the models, providing examples to get started with fine-tuning for domain adaptation and how to run inference for the fine-tuned models. Its structure section names a getting started directory as the reference for inferencing, fine-tuning and retrieval examples, and the fine-tuning questions are answered by a FAQ inside the source directory.
Is Llama written in C++?
The repository says nothing about the implementation language of the models. It is a collection of notebooks and example projects, its primary language is recorded as a notebook format, and the one importable package it defines lives in a subdirectory of its source directory, built with a Python build backend.
Is Llama better than GPT?
The repository makes no comparison. It says it covers the most popular community approaches, use cases and the latest recipes for one model family's text and vision models, and it includes a directory of third-party integrations contributed by various providers, along with an optional extra for a LangChain integration and another for vLLM.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/metainternal-llama-cookbook)Star history chart for your README
[](https://hysenlabs.com/projects/metainternal-llama-cookbook)Was this useful?