microsoft/XPretrain: a directory of Microsoft's multimodal pre-training code
Multi-modality pre-training
At a glance
- What is it?
- XPretrain is not a framework but a monorepo that collects several Microsoft Research multimodal pre-training projects, including HD-VILA, LF-VILA, CLIP-ViP and VisualParsing. Each subdirectory is a separate codebase with its own setup, and the README is the only thing tying them together.
- Who is it for?
- XPretrain is worth cloning if you want the reference implementations behind HD-VILA, LF-VILA, CLIP-ViP or VisualParsing, and you are prepared to read each subdirectory's own instructions because the top-level README documents none of them. It is the wrong starting point if you want a pre-training framework you can point at your own data: there is no unified trainer, no release artefacts and no install path at the root.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 79 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
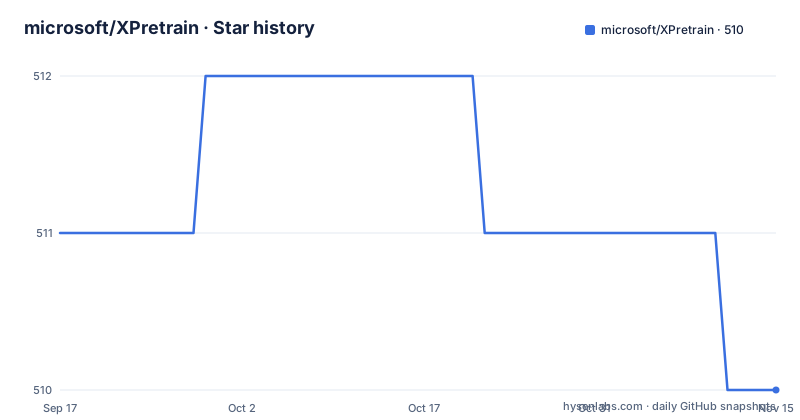
- microsoft/XPretrain510 ★ · -1
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| microsoft/XPretrain | 511 | 510 |
-1 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What XPretrain actually is, and who it is for
The name suggests a framework. The repository is a collection. Its top-level entries are directories named CLIP-ViP, LF-VILA, hd-vila, hd-vila-100m and visualparsing, alongside boilerplate files such as CODE_OF_CONDUCT.md, SECURITY.md, SUPPORT.md, RAI.md and LICENSE. The README describes the repository as including "some recent research works in multi-modality learning, especially with pre-training method from MSM group of Microsoft Research". That wording is accurate: XPretrain is a container for papers and their code, not an abstraction layer over them.
The audience follows from that. If you are reproducing a specific paper, the subdirectory for that paper is what you want, and the monorepo layout is convenient because one clone gets you several related codebases. If you are building a product and need a pre-training pipeline for your own video and text data, this repository does not present itself as that. There is no shared configuration format, no common training entry point, and no package published under the XPretrain name.
The projects span two modality pairs. Video and language: HD-VILA-100M as a dataset, HD-VILA (CVPR 2022), LF-VILA (NeurIPS 2022) and CLIP-ViP (ICLR 2023) as models. Image and language: Pixel-BERT, SOHO (CVPR 2021 oral) and VisualParsing (NeurIPS 2021). Note that Pixel-BERT and SOHO are listed as links to an arXiv PDF and to a separate repository, researchmm/soho, rather than to directories inside this one. So the monorepo is not even a complete index of the group's work; it is a partial one.
How the repository is organised, and what that means for reuse
Each project lives in its own directory with its own Python code, and the README links to those directories rather than describing their contents. There is no shared module imported across them. That is the central architectural fact: XPretrain is a filesystem convention, not a runtime.
The practical consequence is that anything you learn about one subdirectory tells you almost nothing about the next. Dependencies, checkpoint availability, dataset preparation and the shape of the training script are decided per project. The README does not state a common Python version, a common deep learning framework version, or a common set of environment variables. It does not document a shared data format between HD-VILA-100M and the models that consume it, beyond the dataset being described as a "high-resolution and diversified video-language dataset".
For a reader deciding whether to adopt this, the honest framing is that you are choosing a paper implementation, and the monorepo is just the shelf it sits on. Treat the top-level README as a table of contents with news dates. The news section is the closest thing to a changelog: it records that CLIP-ViP and LF-VILA code was released in March 2023, that HD-VILA code was released in September 2022, and that the HD-VILA-100M dataset was released publicly in March 2022. The repository has no published GitHub releases, so there are no version tags to pin against.
Installing XPretrain: there is no root install
Because the repository is a collection, the first step is cloning it, and the second step is choosing a subdirectory. The README gives no install command at the top level, so do not expect one to work.
git clone https://github.com/microsoft/XPretrain.git
cd XPretrain
ls
The listing should show the directories named in the README: CLIP-ViP, LF-VILA, hd-vila, hd-vila-100m and visualparsing, plus the repository's policy files. From there, every further instruction belongs to the subdirectory you picked. The README does not reproduce those instructions, so the correct next move is to open the README inside that directory.
cd CLIP-ViP
ls
What you see next depends entirely on that project. The top-level README is silent on whether any of these subdirectories ship a requirements file, a conda environment, a setup.py or a Dockerfile, and it is silent on where pre-trained weights are hosted. If a subdirectory turns out to have no installation documentation, that is a real gap you have to close yourself by reading its code.
The one artefact the README does describe at the root level is the dataset. HD-VILA-100M is presented as a released dataset with its own directory, and the README's news entries date that release to March 2022. Anything about how to download it, what the annotation format is, or what licence it carries is not in the top-level README.
Where XPretrain is the wrong tool
The clearest limitation is the absence of a supported path from the repository to a running model. There are no releases, no published package, and no root-level quickstart. A team that needs a pre-training pipeline running this week will spend its first days on per-project archaeology: reading each subdirectory to find out what it expects.
The second limitation is scope drift. If your interest is SOHO, the README points you at researchmm/soho, a different repository. If your interest is Pixel-BERT, the README points at an arXiv PDF. The XPretrain directory listing therefore overstates what is inside it relative to the research the README advertises.
The third is the licence. The repository metadata reports the licence as NOASSERTION, which means GitHub could not classify the LICENSE file automatically. The README itself discusses contribution mechanics (a Contributor License Agreement, the Microsoft Open Source Code of Conduct, trademark guidelines) but does not summarise the terms under which the code or the dataset may be used. For a dataset described as 100M-scale video and language data, that is the question to answer before anything else, and the top-level README does not answer it.
Finally, the maintenance signal. The last push to the repository was on 2026-08-28. The README's own news stops in March 2023, so the recent push activity is not reflected in the documentation you would read first.
A real alternative: separate repositories versus a monorepo
The obvious comparison is with the approach Microsoft itself uses elsewhere. SOHO lives in researchmm/soho, a standalone repository, and the README links to it as such. Pixel-BERT is represented by a paper link rather than a directory. So within this same research group, some work is published as its own repository and some is bundled here.
The difference in approach matters for how you consume it. A standalone repository can version itself, publish its own releases, and maintain a README that describes exactly one thing. A monorepo like XPretrain gives you one clone and one place to look, at the cost of a top-level README that can only ever be an index. If a subdirectory here had a serious dependency conflict with another, nothing in the repository structure would surface it, because the projects never share a build.
If you want an actively versioned implementation of one specific paper, the standalone repository pattern is easier to track: you can watch releases and pin a tag. If you want to survey what a research group has published across video-language and image-language pre-training, the monorepo is the faster way to see the set, which is exactly what the XPretrain README does well.
Licence, maintenance and the cost of upgrading
On upgrading: there is nothing to upgrade in the package-manager sense. The repository has no published GitHub releases, so there are no tags to move between and no changelog to read before a bump. Updating means pulling the main branch and re-reading whichever subdirectory you depend on, because the top-level README will not tell you what changed. The news section is the only dated record of additions, and its most recent entry is March 2023.
On maintenance: the last push was on 2026-08-28. That is recent activity, but the README does not describe what that activity was, and the documentation's own timeline ends in 2023. Treat the two signals separately rather than reading the push date as evidence that the projects are being extended.
On licence: the metadata reports NOASSERTION for the LICENSE file, and the README does not restate the terms. It does set out contribution requirements (a CLA, the Code of Conduct) and a trademark policy stating that use of Microsoft trademarks in modified versions "must not cause confusion or imply Microsoft sponsorship". None of that tells you what you may do with the code or the HD-VILA-100M dataset. This is not legal advice: read the LICENSE file and, for the dataset, whatever terms accompany it in the hd-vila-100m directory, before you build on either.
Editorial conclusion
XPretrain is worth cloning if you want the reference implementations behind HD-VILA, LF-VILA, CLIP-ViP or VisualParsing, and you are prepared to read each subdirectory's own instructions because the top-level README documents none of them. It is the wrong starting point if you want a pre-training framework you can point at your own data: there is no unified trainer, no release artefacts and no install path at the root. Before adopting anything here, open the subdirectory you actually need and confirm it documents its dependencies and checkpoints, and read the LICENSE file at the root rather than assuming a standard open source licence.
Frequently asked questions
What does pre-training mean in the context of XPretrain?
The README frames the repository as research works in multi-modality learning "especially with pre-training method from MSM group of Microsoft Research", and the projects it lists are video-language and image-language pre-training models such as HD-VILA, LF-VILA, CLIP-ViP and VisualParsing. The README does not give a definition of the term itself, so it is described here only as the repository uses it.
Is microsoft/XPretrain a framework I can install with pip?
No. The repository is a collection of directories, one per project, and the README documents no root-level install and no published package. You clone the repository and then work inside a specific subdirectory such as CLIP-ViP or LF-VILA.
Which projects are included in microsoft/XPretrain?
The README lists HD-VILA-100M (dataset), HD-VILA, LF-VILA and CLIP-ViP for video and language, and Pixel-BERT, SOHO and VisualParsing for image and language. Pixel-BERT is linked as an arXiv PDF and SOHO as the separate researchmm/soho repository, so not all of them live inside this repository.
How do I download the HD-VILA-100M dataset from microsoft/XPretrain?
The README states that HD-VILA-100M was released publicly in March 2022 and links to the hd-vila-100m directory inside the repository. The top-level README does not describe download steps or data terms, so those would have to come from that directory.
Is microsoft/XPretrain actively maintained?
The last push to the repository was on 2026-08-28, but the README's news section ends in March 2023 and the repository has no releases. The README does not describe what the later push activity covered.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-xpretrain)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-xpretrain)Was this useful?