ModelScope: the Python library behind the ModelScope model hub
ModelScope: bring the notion of Model-as-a-Service to life.
At a glance
- What is it?
- ModelScope's pip package is mostly a client for the ModelScope.cn hub: it resolves model ids, downloads weights, and runs inference, training and evaluation through layered APIs. It is a good fit if you are consuming hosted models, and a poor fit if you want a self-contained training stack or a mirror-free setup.
- Who is it for?
- Adopt ModelScope if your models live on modelscope.cn or you need the Damo CV, speech and OCR checkpoints that debuted there, and accept that the library is coupled to a remote hub by design. Do not adopt it as a general-purpose training framework or if your pipeline must run fully offline.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
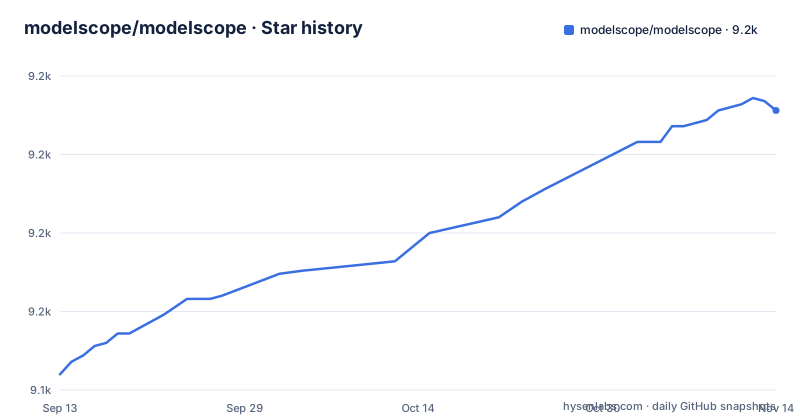
- modelscope/modelscope9,214 ★ · +84
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| modelscope/modelscope | 9.1k | 9.2k |
84 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem ModelScope solves is model distribution, not model training
The README frames the project around Model-as-a-Service: the stated goal is to bring together models from the AI community and reduce the work of putting them into applications. The interesting part is what the open-source library actually does. It provides interfaces and implementations for inference, training and evaluation, and it also handles the interaction with ModelScope backend services, specifically the Model-Hub and Dataset-Hub. Entity lookup, version control and cache management are listed as things that happen under the hood. So the library is a client with a model abstraction on top. The audience is developers who want a specific checkpoint (a Damo face detector, a Paraformer ASR model, an OCR line recognizer) running without writing download and preprocessing glue themselves. If you already have a training pipeline and a private artifact store, most of what this library offers is redundant for you.
Model ids resolve against a remote hub, and that shapes every call
The architecture described in the README is layered API abstraction. A model is referenced by an id, the library maps that id to an entry in the Model-Hub, fetches the weights and configuration into a local cache, and exposes a pipeline-style interface for inference, fine-tuning or evaluation. The README claims this takes a few lines of code and that components can be customized where necessary. The Dataset-Hub interaction follows the same pattern for datasets. Two consequences follow from this design. First, the id namespace is owned by the hub, so a model that is not registered there does not exist as far as the convenient path is concerned. Second, the first run of any model is a network operation, and cache management is the library's job rather than yours. Confirm cache layout, eviction policy and the cache root in the docs rather than assuming them.
Installing and running the documented inference path
The library is published on PyPI as modelscope, so installation is a pip install. The README's own summary of the workflow is that once a model is integrated, inference, fine-tuning and evaluation can be done with only a few lines of code. The README also points readers at the online experience and ModelScope Notebook for a hosted alternative to local setup, and its QuickTour section introduces the unified inference interface. Check the documentation for the current pipeline signature and task identifiers before you plan an integration.
The hub coupling is the real limitation
Every convenience in this library assumes reachable ModelScope backend services. In an air-gapped cluster, a CI runner with no egress, or a region where the hub is slow, the model-id path stops being convenient and you are left doing manual weight acquisition anyway. Check the documentation for any offline mode or local registry option before planning around one. There is a second, quieter constraint: the model list is curated. The README names 700+ public models and highlights LLMs, multi-modal models, CV models and audio models, many of which made their open-source debut on ModelScope. That is a strength for those specific checkpoints and a limitation for everything else. If your model is on another hub, adopting this library buys you nothing except an extra dependency. Version control is handled by the hub, which also means your reproducibility story is tied to the hub's revision semantics, not to a lockfile you control.
Compared with Hugging Face Transformers, the difference is where the models live
Hugging Face Transformers is the obvious reference point, and the difference is not the API shape. Both offer a hub, an id-based lookup, a local cache and pipeline-style inference. The divergence is catalogue and default ecosystem. Transformers' centre of gravity is the Hugging Face Hub and the surrounding libraries built on it; ModelScope's centre of gravity is modelscope.cn, and the README's representative examples (Yi-1.5-34B-Chat, Qwen1.5-110B-Chat, DeepSeek-V2-Chat, InternVL-Chat-V1-5, Paraformer, DuGuang OCR) show where the catalogue is deepest. If your work depends on Alibaba's Damo checkpoints or models that debuted on ModelScope, this library is the shortest path. If your work depends on the Transformers ecosystem, adopting ModelScope means maintaining two hub clients and two caches for no benefit. A team can reasonably use both, but should not expect the abstractions to be interchangeable.
Release cadence, licence, and what maintenance actually costs you
The release history shows a steady cadence: v1.40.0 on 2026-08-28, v1.40.1 on 2026-09-15 and v1.40.2 on 2026-10-09, with the last push to master on 2026-11-02. Three releases in roughly six weeks means releases arrive often, and the README's own framing (models made their open-source debut on ModelScope) implies that catalogue changes are part of the package. Pin the version in your requirements file rather than tracking latest, because a model-id or task-identifier change between minor versions is exactly the kind of breakage that is cheap to avoid and annoying to debug. The repository is Apache-2.0, which is permissive and generally straightforward for commercial use, but the licence covers this library, not the weights it downloads. Individual model cards can carry their own terms, and some of the listed models are derivatives of licences with usage restrictions. Verify per-model licence terms yourself; this is not legal advice.
Who should adopt ModelScope, and what to check first
Adopt it if you are building on modelscope.cn, if you want the CV, speech and OCR checkpoints that are strongest there, or if you want a hosted notebook path instead of provisioning GPUs yourself. Skip it if you need a fully offline pipeline, if your models live on another hub, or if you are looking for a training framework rather than a client. The first things to verify are concrete: whether the specific model you need is exposed as a supported task in the current docs, what the pipeline call and task identifier actually are, where the cache lands on disk and how large it grows for your target checkpoint, and whether the model card's licence is compatible with your distribution. If any of those four checks fails, the fallback is to download the weights directly and skip the abstraction.
Editorial conclusion
Adopt ModelScope if your models live on modelscope.cn or you need the Damo CV, speech and OCR checkpoints that debuted there, and accept that the library is coupled to a remote hub by design. Do not adopt it as a general-purpose training framework or if your pipeline must run fully offline. Before committing, verify which of the 700+ listed models actually expose a pipeline task you need, check the Apache-2.0 LICENSE file against your distribution plans, and confirm that the cache directory fits your disk and container image budget.
Frequently asked questions
Is ModelScope open source?
Yes for the library. The core ModelScope library is open-sourced in this repository under the Apache-2.0 license, with the README published in English, Chinese and Japanese, while the hub service itself runs at modelscope.cn.
How do I install ModelScope?
The distribution is published on PyPI under the name modelscope, and the source tree builds through setup.py, which only calls setup(). The metadata requires Python 3.10 or newer, and the build runs an AST template generation step before sdist and bdist_wheel.
Is ModelScope API free?
The library is Apache-2.0 licensed, and that models can be experienced online and run in a cloud notebook with CPU or GPU environments on modelscope.cn.
what is modelscope cn
It is the website of the service behind the library. Models are published there for online experience, and the ModelScope Notebook runs in a cloud environment with ready-to-use CPU or GPU capacity one click away.
is modelscope like huggingface
The repository frames ModelScope as Model-as-a-Service, combining a Model-Hub and a Dataset-Hub with a library of layered APIs for inference, training and evaluation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/modelscope-modelscope)Star history chart for your README
[](https://hysenlabs.com/projects/modelscope-modelscope)Was this useful?