NirDiamant's Prompt_Engineering: 22 OpenAI notebooks pinned to one tested Python 3.11 environment
22 prompt engineering techniques with hands-on Jupyter Notebook tutorials, from fundamental concepts to advanced strategies for leveraging LLMs.
At a glance
- What is it?
- NirDiamant/Prompt_Engineering is a set of 22 Jupyter tutorials that run from basic prompt templates to chain-of-thought, self-consistency and tree-of-thought. The notebooks are tied to OpenAI and LangChain 1.x, share one heavy requirements file, and come with no releases and an unresolved license field.
- Who is it for?
- Prompt_Engineering is a sound way to learn prompting techniques by running code, if you have an OpenAI key and are happy working in a Python 3.11 virtual environment. It is a weak fit if you need provider-neutral examples, current LangChain idioms in every notebook, or code you can lift into a product without a licence check.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 16 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
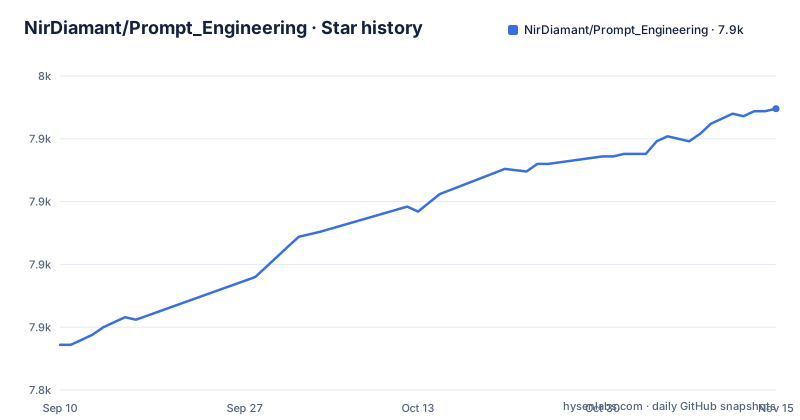
- NirDiamant/Prompt_Engineering7,937 ★ · +94
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| NirDiamant/Prompt_Engineering | 7.8k | 7.9k |
94 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One requirements file, tested once in a fresh Python 3.11 venv
The repository is not a library. It is a folder, all_prompt_engineering_techniques/, holding 22 Jupyter notebooks, plus a single requirements.txt that states exactly what those notebooks import and nothing else. The header of that file records the test that backs it: in a fresh Python 3.11 virtual environment on 2026-10-31, all 22 notebooks ran top to bottom.
The version ranges follow one rule. Each line allows minor and patch updates and stops at the next major version, because a major bump is the kind of change that can break a notebook. So openai is constrained to >=3.41,<4, langchain-core to >=1.7,<2, numpy to >=2.4,<3, and so on.
That gives you a clear starting point: create a Python 3.11 environment, install the file, and the notebooks are expected to run. The limits follow from the same sentence. Python 3.11 is the only interpreter named in that test, so a different version is your own experiment. And because the ranges cap at the next major release, the environment will age: once a dependency ships a new major version, these notebooks stay on the old one until someone updates and re-tests them.
Every notebook assumes an OpenAI key
The provider dependencies in requirements.txt are openai and langchain-openai, alongside python-dotenv for loading settings from a .env file. No other model provider's SDK appears in the file.
For a reader, this has two consequences. First, running the tutorials costs money against an OpenAI account; every chain-of-thought or self-consistency example that calls a model is a billed request, and techniques like self-consistency call the model more than once by design. Second, if you work with a different model, the notebooks will not run as shipped. You will be adapting client code and LangChain model classes yourself, and the 2026-10-31 test run says nothing about how the prompts behave on another provider.
That matters more for prompt engineering than for most topics. A prompt that produces a clean result in one model can behave differently in another, so the outputs shown in these notebooks are evidence about OpenAI models, not a general guarantee. Treat the techniques as transferable and the specific outputs as provider-specific.
Three notebooks teach helpers that now live in langchain-classic
The notebooks are on LangChain 1.x: langchain-core, langchain-openai and langchain-text-splitters, each capped below version 2. A fourth package, langchain-classic >=1.0.8,<2, is there for a specific reason. It keeps the older helpers that three notebooks teach with: ConversationChain, RegexParser and load_summarize_chain.
This is a sensible way to keep those notebooks running without rewriting them. The consequence for a learner is that those three tutorials show an older style of LangChain code. The patterns still work in this environment, but if you copy them into a new project you are building on the classic compatibility package rather than the core 1.x interfaces the other notebooks use.
If your goal is to learn the prompting idea, such as summarising long text or parsing structured output with a regular expression, the classic helpers are fine as teaching aids. If your goal is code you will maintain, rewrite those parts against current LangChain interfaces, or against the provider SDK directly, before putting them anywhere that matters.
PyTorch arrives with the evaluation notebook, for everyone
Because there is only one requirements file, installing it pulls in the dependencies of every notebook at once. Most are small: Jinja2 >=3.1,<4 for the prompt-templates-variables-jinja2 notebook, and ipykernel >=7.4,<8 so the environment can serve as a Jupyter or VS Code kernel.
The heavy entry is sentence-transformers >=6.2,<7, required by evaluating-prompt-effectiveness and prompt-optimization-techniques. The comment next to it notes that it pulls in PyTorch. scikit-learn >=1.9,<2 and numpy >=2.4,<3 sit in the same group.
The practical cost is install size and time. A reader who only wants the basic templates or chain-of-thought notebooks still gets PyTorch unless they trim the file by hand. On a laptop that is an inconvenience; in a constrained environment, such as a small cloud notebook instance or a CI job that just wants to execute one tutorial, it can be the main cost of trying the repository. If you only need a subset, it is worth building a smaller environment from the lines the comments tie to the notebooks you plan to run.
A curriculum from templates to tree-of-thought, not a reusable package
The 22 tutorials are pitched as running from fundamental concepts to advanced strategies: basic prompt templates and variables at one end, chain-of-thought, self-consistency and tree-of-thought prompting at the other, with notebooks on evaluating prompt effectiveness and on prompt optimization in between. The repository presents itself as a place for beginners and practitioners alike, and invites contributions of new techniques.
What you get is teaching material. There is no package to install and import, no API, and no versioned interface. Each notebook is meant to be read and executed in order, and its value is in seeing a technique applied end to end.
The same 22 techniques are also sold as a book, Prompt Engineering: Master the Art of AI Interaction, which adds step-by-step breakdowns and exercises. The notebooks are the free, runnable half of that pairing. For adjacent topics the author keeps separate repositories: RAG Techniques with more than 40 notebooks on retrieval-augmented generation, GenAI Agents, Agents Towards Production, and Agent Memory Techniques with 30 notebooks. Prompting questions that cross into retrieval are covered there rather than here.
No releases to pin, and a license field GitHub cannot resolve
The repository has no GitHub releases. Changes land directly on main, and the most recent push was on 2026-10-31, the same date as the requirements test. If you build a course or internal training on these notebooks, pin a specific commit; otherwise a notebook you referenced can change under you with no version number to mark it.
The license situation needs a manual check. A LICENSE file sits at the top of the repository, but GitHub's license detection reports NOASSERTION, meaning it could not match the file to a standard license. There is also a CITATION.cff for academic citation.
For personal study this does not matter. For anyone who wants to copy notebook code into a commercial product, republish the tutorials, or adapt them into paid training, it does: read LICENSE yourself and confirm what it allows before reusing anything. An unrecognised license is not the same as a permissive one, and the safe assumption until you have read it is that reuse terms are whatever that file says, not what a standard licence would grant.
The README doubles as a storefront with tracked links
Before the tutorials, the README carries a launch banner for a separate book, AI Agents Made Simple, at a $0.99 launch price, a card for the Prompt Engineering book, sponsor logos for CodeRabbit and Qodo, a newsletter pitch claiming more than 50,000 subscribers, and three YouTube explainers.
The book and video links do not point straight at Amazon or YouTube. They go through a Google Cloud Function named rag-techniques-views-tracker, with parameters naming the notebook and the specific button clicked, before redirecting. Clicking them records that click.
None of this changes the notebooks, but it changes how to read the page. The claims in the banner and newsletter block are marketing, and the useful material starts in all_prompt_engineering_techniques/. If you are passing this repository to students or colleagues, link them to the notebook folder rather than the README if you would prefer they skip the sales layer. The repository also ships an AGENTS.md and an llms.txt, which give coding assistants and LLM tools a direct entry point to the content.
Editorial conclusion
Prompt_Engineering is a sound way to learn prompting techniques by running code, if you have an OpenAI key and are happy working in a Python 3.11 virtual environment. It is a weak fit if you need provider-neutral examples, current LangChain idioms in every notebook, or code you can lift into a product without a licence check. Before using it, read LICENSE and pin a commit, since there are no releases.
Frequently asked questions
How do I learn prompt engineering with the Prompt_Engineering repository?
Set up a Python 3.11 virtual environment, install requirements.txt, and work through the 22 notebooks in all_prompt_engineering_techniques/, which run from basic prompt templates to chain-of-thought, self-consistency and tree-of-thought.
Can I use Claude with the Prompt_Engineering notebooks?
Not as shipped. The Prompt_Engineering requirements list openai and langchain-openai and no other provider package, so using another model means adapting the notebook code yourself.
Does Prompt_Engineering cover RAG?
Retrieval-augmented generation is covered in the author's separate RAG Techniques repository, which has more than 40 notebooks, rather than in Prompt_Engineering.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nirdiamant-prompt-engineering)Star history chart for your README
[](https://hysenlabs.com/projects/nirdiamant-prompt-engineering)Was this useful?