FoundationPose: the recommended container comes from a personal account
[CVPR 2024 Highlight] FoundationPose: Unified 6D Pose Estimation and Tracking of Novel Objects
At a glance
- What is it?
- FoundationPose is a unified model for estimating and tracking the six-degree-of-freedom pose of an object it has never seen, given either a CAD model or a few reference photographs, with no retraining. The setup instructions are unusually specific about hardware and unusually relaxed about provenance: the recommended container is pulled from an individual's registry account, the weights live on a file-sharing service under timestamped folder names, and the first run compiles extensions online.
- Who is it for?
- FoundationPose fits a robotics or computer-vision team that needs pose for an object it does not have training data for, since a CAD model or a handful of photographs is the entire per-object cost and nothing is retrained. Three things to settle first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
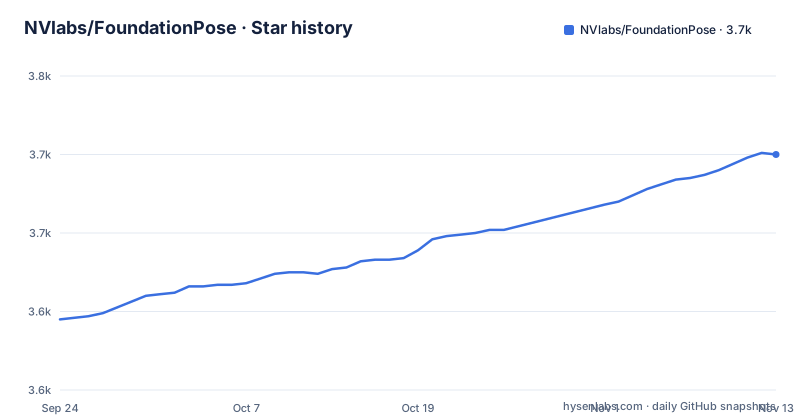
- NVlabs/FoundationPose3,700 ★ · +105
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| NVlabs/FoundationPose | 3.6k | 3.7k |
105 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The recommended install pulls an image from an individual account and re-tags it
The first setup option is the one marked as recommended, and it is three commands:
cd docker/
docker pull wenbowen123/foundationpose && docker tag wenbowen123/foundationpose foundationpose  # Or to build from scratch: docker build --network host -t foundationpose .
bash docker/run_container.sh
The first line is the finding. The image is pulled from a personal registry account, then given a local name with the tag command, so that the rest of the instructions can refer to a short name. The alternative in the same comment is to build from source yourself, which needs the host network flag.
Then the hardware caveat, which is handled the same way. For more recent cards, one named in the file, the file says to refer to an issue, and the short version is to pull a different image, again from an individual account, with a tag indicating a specific CUDA version, and then modify the shell script so it uses that image instead of the default one.
So the documented path to a working environment involves at least two images neither of which is published under the project's own namespace, and the fix for newer hardware is an edit to a script rather than a flag.
The container has no compiled extensions until you build them inside it
The second thing the setup tells you is that the image is not the whole environment.
If it is the first time you launch the container, you need to build extensions, and the command for that has to be run inside the container rather than on the host. Later, once that is done, you can enter the container with an interactive execution command instead of rebuilding.
So the container's first run is a build, not a run. That matches what the rest of the documentation says about the first execution of the demo being slower because of online compilation, which is the same property stated from the other direction: this code compiles parts of itself when it first needs them.
Two build scripts live at the root of the repository, one named for the container path and one for the local path, so the same compilation step is wired twice. And there is a separate script whose name says it checks the environment, which suggests the author expected the setup to be fragile enough to need a diagnostic command.
For a research repository that is a reasonable posture. For a dependency you want to run in CI it is the thing to budget for.
The requirements file is an install script written in comments
The dependency file is the most useful document in the repository, because its first lines are instructions rather than packages.
The comments say to install the framework first with a CUDA build that matches your driver, giving a specific wheel index as the example that works on most recent cards. Then to install two GPU extensions from source, noting that the CUDA compiler is needed and that the toolkit location has to be exported. And only then this file.
The local setup section repeats the same order in prose, across five numbered steps, and explains one flag that would otherwise look optional: the no-build-isolation flag is required so the extension build can see the framework version you already installed. Two of the five steps are optional and both belong to the model-free path: one is a step from the earlier work in the same repository, and the other is a separate library whose version has to match your framework and toolkit.
The package list itself is organised into four groups, and the reasoning is visible in the headings. Numerics and input, configuration and serialisation, vision and three-dimensional work, then an inference group whose heading records that the framework is installed separately. One package in the last group is marked optional with a note that its import is guarded in the code.
The weights are not in the repository, and they are named by timestamp
The data preparation section is four steps, all pointing at the same file-sharing service, and two of them are optional.
The first is the one that matters. Download all the network weights and put them in a weights directory, and then note the detail that trips people up: the refiner needs one specifically named folder and the scorer needs another, each named by a timestamp rather than by a version number.
So the weights are not versioned by the project. They are a set of dated artefacts, and choosing the wrong folder does not produce a version mismatch, it produces a model that does not load.
The second step downloads demo data into a demo data directory. The third is optional and large: the training dataset. The fourth is optional and only needed for the model-free few-shot version: preprocessed reference views.
What the repository does not contain, then, is any weight at all. Four downloads, two of them large, all from one account's shared folders, with no checksum listed anywhere in the visible instructions.
Estimation runs on the first frame, then tracking takes over the rest of the video
The demo section explains what actually happens when you run it, and the mechanism is worth stating because it explains why the approach works on an unseen object.
The paths are set in the argument parser by default, and you change the scene by passing different arguments. On the demo data the scene is a robot manipulating a mustard bottle. Pose estimation is conducted on the first frame, and then it automatically switches to tracking mode for the rest of the video.
So there is a single model doing two jobs, with the switch happening on its own after one frame. That is the whole claim of the paper expressed as a runtime behaviour: no per-object training step, because the initial estimate comes from the model and everything after it is tracking.
You can point it at another object with the same arguments and no retraining, and the file uses a power tool as the example.
Two operational notes. The visualisations are written to a directory named in the argument parser, so that is where you look for output. And the first execution can be slower because of online compilation, which is the same first-run cost the container instructions describe.
Two citation requests, and a leaderboard claim dated to March 2024
The citation section asks for two references rather than one, and the second one is a different paper.
The first entry is this work, presented at a 2024 conference, with four named authors. Then a paragraph: if you find the model-free setup useful, please also consider citing an earlier paper from 2023, again with four of the same authors plus others, on neural tracking and reconstruction of unknown objects.
That earlier work is not a formality. The tree contains a directory named after it, and the local install steps describe a compilation step belonging to it as part of the optional model-free path. So the second citation points at code that is actually in the repository and that you will build if you use half of the project's functionality.
The other claim worth dating is the one near the top: first place on a public leaderboard for model-based novel object pose estimation, as of a stated month in 2024. That is a snapshot assertion with a date attached, and the date is more than two years before the last commit to this branch. It tells you what was true at the time of writing and nothing about the current ranking.
ROS users are pointed at a different repository, and the filenames are inconsistent
One line near the top of the file is more useful than most of the setup instructions.
For the robot operating system version, the file says to check a separate project, which it says enjoys faster inference through a specific runtime and a speed-up in a compiled language.
So if you came here for ROS, you are being redirected, and the reasons given are performance. That is the author telling you this repository is not the ROS path, which saves you the hours the rest of this article would otherwise cost.
The smaller details are the same kind of message. Two of the root filenames break their own conventions, one Python module starting with a capital letter and the readme itself in lower case. The data preparation list is numbered four times and every item keeps the same number, which means the list does not tell you which step is which if you are looking for one out of order.
The default branch was pushed on 29 April 2026, and the project publishes no releases, so there is no version to pin and no changelog entry to check whether a step changed.
Editorial conclusion
FoundationPose fits a robotics or computer-vision team that needs pose for an object it does not have training data for, since a CAD model or a handful of photographs is the entire per-object cost and nothing is retrained. Three things to settle first. Provenance: the recommended environment is a container image from an individual account rather than the organisation's, the weights come from a file-sharing folder rather than the repository, and both are re-tagged or re-pointed by editing a shell script. Hardware: the documented path assumes a specific CUDA toolkit, two extensions compile from source against the installed framework, and there is a separate image for newer cards. And scope: this is a research implementation with two citation requests and a leaderboard claim dated March 2024, so treat the numbers as a starting point rather than a current ranking.
Frequently asked questions
What is FoundationPose used for?
It estimates and tracks the six-degree-of-freedom pose of novel objects without retraining, given either the object's CAD model or a small number of reference images. On the demo data it estimates on the first frame and then switches to tracking for the rest of the video.
How does FoundationPose run without retraining for a new object?
The file says the model can be applied at test time to a novel object as long as its CAD model is given or a small number of reference images are captured, and you can point it at another object by changing the arguments, with no need to retrain.
Where do I get the FoundationPose weights?
They are not in the repository. They are downloaded from a shared folder and placed in a weights directory, and the refiner and the scorer each need a specifically named folder identified by a timestamp.
Which container image does the FoundationPose setup use?
The recommended route pulls an image from an individual registry account and re-tags it locally, with an alternative to build from source. For more recent graphics cards the file points at an issue and at a second custom image, to be used by editing the start script.
Does FoundationPose support ROS?
Not from this repository. The file says that for the robot operating system version you should use a separate project, which it says benefits from faster inference through a specific runtime and a compiled language speed-up.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-foundationpose)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-foundationpose)Was this useful?