OmniVinci: an omni-modal model whose pip metadata belongs to another project
OmniVinci is an omni-modal LLM for joint understanding of vision, audio, and language.
At a glance
- What is it?
- NVlabs/OmniVinci is an open omni-modal LLM for joint vision, audio and text understanding, published with a 9B checkpoint and a technical report, while the pyproject.toml in the same repository still declares the package as vila and points its homepage at a different lab's project.
- Who is it for?
- OmniVinci is worth reading if you are building anything that needs audio and video understood together, because the cross-modal result is large and the mechanism is specific: alignment, relative grouping, and absolute time embedding are separate named components rather than one fusion block. Two things should temper that.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 75 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
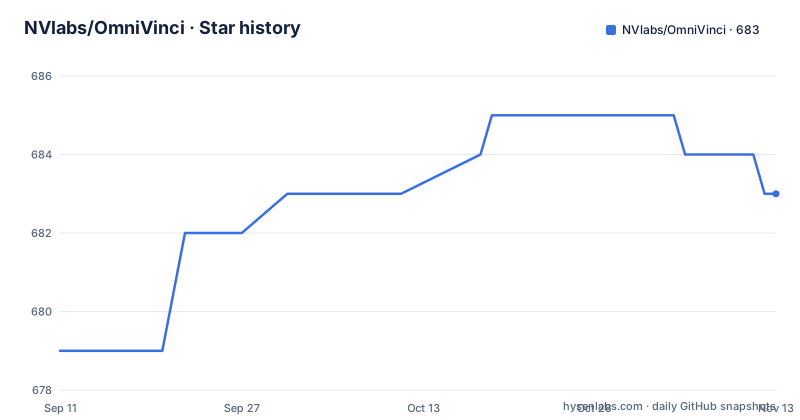
- NVlabs/OmniVinci683 ★ · +4
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NVlabs/OmniVinci | 679 | 683 |
4 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The packaging metadata is still VILA's, not OmniVinci's
The `pyproject.toml` in this repository declares `name = "vila"` at version `1.5.0`, with the description `nvOmni`. Its project URLs point at `https://hanlab.mit.edu/projects/vila` as the homepage and `https://github.com/NVlabs/VILA/issues` as the bug tracker, and its four console scripts are `vila-run`, `vila-eval`, `vila-infer`, and `vila-upload`, each mapped into an `llava.cli` module. None of that describes OmniVinci. The consequence is concrete rather than cosmetic: a `pip install .` in a clone of this repository installs something called vila, and any bug you file goes to a tracker for a different repository. Everything else in the tree is OmniVinci's own: `environment_setup.sh`, `example_infer.py`, `example_mini_audio.py`, `example_mini_image.py`, `example_mini_video.py`, an `assets/` directory, and `omnivinci_technical_report.pdf`.
Runtime dependencies are pinned with exact versions down to torch 2.3.0
The dependency list is nearly all exact pins: `torch==2.3.0`, `torchvision==0.18.0`, `transformers==4.46.0`, `accelerate==0.34.2`, `bitsandbytes==0.43.2`, `numpy==1.26.4`, `scikit-learn==1.2.2`, `decord==0.6.0`, and `pytorchvideo==0.1.5`, with `pydantic<2,>=1` holding the old major version line. Three entries carry more risk than the others. `ring_flash_attn==0.1.1` is a compiled attention kernel rather than a wheel anyone can resolve casually. `s2wrapper` is not on an index at all, it is a direct git reference to `github.com/bfshi/scaling_on_scales`. And the configuration pins a `triton` nightly built from an internal Visual Studio artifact feed rather than from PyPI. Add optional groups for training (`deepspeed==0.9.5`, ninja, wandb) and evaluation, and this is an environment with very little give in it.
trust_remote_code means the code that runs is fetched, not cloned
The documented route is the Hugging Face repository, not this one:
huggingface-cli download nvidia/omnivinci --local-dir ./omnivinci --local-dir-use-symlinks False
cd ./omnivinci
Then the environment comes from the project's own script, `bash ./environment_setup.sh omnivinci`, which is described as based on the NVILA codebase, so the README and `pyproject.toml` describe two different installations and you are meant to use the script. Inference then loads the model through transformers with remote code enabled:
model_path = "./"
video_path = "xxx.mp4"
generation_kwargs = {"max_new_tokens": 1024, "max_length": 99999999}
load_audio_in_video = True
num_video_frames = 128
audio_length = "max_3600"
`AutoConfig.from_pretrained` and `AutoModel.from_pretrained` are both called with `trust_remote_code=True`, so the Python that defines the model is downloaded from the hub and executed locally at `torch.float16`. That is how a custom architecture is loaded at all, and it is also the part of this setup to read twice, since the code that runs is the code in the checkpoint repository.
The two single-modality columns are near ties
The comparison table has six columns and only some of them move. Qwen2.5-Omni against OmniVinci reads as follows: Omni-Dailyomni 47.5 to 66.5, Omni-Worldsense 45.4 to 48.2, Audio-MMAU 71.0 to 71.6, Audio-MMAR 56.7 to 58.4, Vision-MVBench 70.3 to 70.6, and Vision-Video-MME without subtitles 64.3 to 68.2. The three figures the abstract highlights are the Dailyomni, MMAR, and Video-MME gains, and the largest margins in the table are indeed in the two omni columns. The single-modality columns are a different story: 0.6 points on MMAU and 0.3 on MVBench. So the claim that modalities reinforce one another is carried by the cross-modal benchmarks, while the evidence that either modality alone got better is thin. The token comparison is also in the table's favour and worth noting: 0.2T training tokens against 1.2T, described as a six times reduction.
Temporal position is encoded twice, relatively and absolutely
Three architectural components are named, and the interesting split is inside the temporal pair. `OmniAlignNet` strengthens alignment between vision and audio embeddings in a shared omni-modal latent space, which is the representation-level piece. `Temporal Embedding Grouping` captures relative temporal alignment between the vision and audio signals, which is how the model knows one event follows another. `Constrained Rotary Time Embedding` encodes absolute temporal information inside the omni-modal embeddings, which is how the model knows when something happened. Relative and absolute are separate problems, and having a named component for each is a defensible design rather than a single fusion block. The data side runs through a curation and synthesis pipeline that produces 24M single-modal and omni-modal conversations, and the paper reports downstream demonstrations in robotics, medical AI, and smart factory.
There is one release, and it is a line in the README
The repository has no GitHub releases. The only release record is a news entry dated 2025 Oct 19 announcing OmniVinci-9B with joint understanding of vision, audio, and text. The technical report is a PDF checked into the root rather than a versioned artefact, and the paper itself is arXiv 2510.15870, presented at ICLR 2026. The last push to `main` is 2026-08-31, so the code has moved about ten months past the model announcement without a tag to distinguish the states. There are twenty-eight named authors on the README, with corresponding, core contribution, and equal advisory roles marked, and a model card on Hugging Face under `nvidia/omnivinci`. Anyone pinning a dependency on this work is pinning a moving branch and a single announced checkpoint.
Editorial conclusion
OmniVinci is worth reading if you are building anything that needs audio and video understood together, because the cross-modal result is large and the mechanism is specific: alignment, relative grouping, and absolute time embedding are separate named components rather than one fusion block. Two things should temper that. The single-modality benchmark columns are near ties, so the reinforcement story rests on the cross-modal columns. And the repository is a paper drop rather than a maintained package: no GitHub releases, one news line, four example scripts, a technical report PDF, and packaging metadata that still belongs to VILA. If you use it, install from the Hugging Face repository and the `environment_setup.sh` path the README documents, and read every pinned dependency in `pyproject.toml` before you decide whether your CUDA and torch versions can satisfy it.
Frequently asked questions
What does omni mean in AI?
Here it means one model handling vision, audio, and language jointly rather than in separate stages. OmniVinci describes a shared omni-modal latent space, 24M single-modal and omni-modal conversations in its training mix, and one checkpoint that takes video with audio as input.
How do I install and run the OmniVinci model?
Download the checkpoint with `huggingface-cli download nvidia/omnivinci`, then run `bash ./environment_setup.sh omnivinci`, which the project says is based on the NVILA codebase. Inference loads it with AutoConfig and AutoModel using `trust_remote_code=True` at `torch.float16`.
What are the OmniVinci-9B inference defaults?
The documented example sets `num_video_frames = 128`, `audio_length = "max_3600"`, `load_audio_in_video = True`, and a generation config of 1024 new tokens with a maximum length of 99999999. Audio-only and image-only examples live in `example_mini_audio.py` and `example_mini_image.py`.
How does OmniVinci compare with Qwen2.5-Omni on the published table?
It scores higher in all six columns: 66.5 to 47.5 on Omni-Dailyomni, 48.2 to 45.4 on Omni-Worldsense, 71.6 to 71.0 on Audio-MMAU, 58.4 to 56.7 on Audio-MMAR, 70.6 to 70.3 on Vision-MVBench, and 68.2 to 64.3 on Vision-Video-MME without subtitles, using 0.2T training tokens against 1.2T.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-omnivinci)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-omnivinci)Was this useful?