clawsweeper: proposal-only review, a guarded apply, and a bot that records when it writes its own labels
ClawSweeper scans all issues and PRs and suggest what we can close, and why. It runs every PR / Issue once a week.
At a glance
- What is it?
- ClawSweeper is a maintenance bot for a family of repositories, and the part worth reading is the set of limits it states about itself: review is proposal-only, apply is guarded, the model never holds write credentials while reviewing, and every mutation is rechecked against live state immediately before it happens. It refuses to run as a service for other people's projects, and its largest documented feature is proposing closure of very large pull requests before doing any work on them.
- Who is it for?
- Read this as a worked example of a bot designed around its own blast radius, because that is what most of the documentation is about. Four of its safety properties are stated in the first screen of the page, the state model avoids spamming issue trackers by keeping one record on disk and one edited comment per item, and there is a size ceiling that stops the bot spending model budget on a diff nobody can read.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
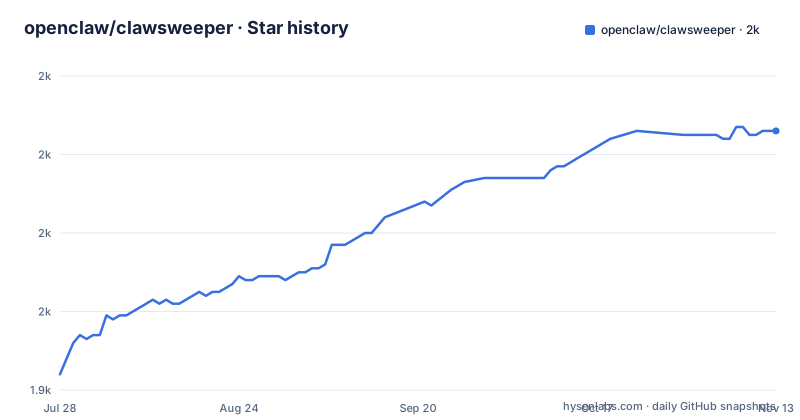
- openclaw/clawsweeper2,006 ★ · +62
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| openclaw/clawsweeper | 1.9k | 2k |
62 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four safety properties, stated on the first screen
The documentation makes its central claim in negative form: ClawSweeper is not a generic auto-close bot. Four properties follow, and they are the whole architecture stated in one paragraph.
Review is proposal-only, which means the model's output is a recommendation rather than an action. Apply is guarded, which means acting on a recommendation goes through a separate step with its own checks. The model never gets write credentials during review, so a compromised or confused model has nothing to mutate with. And every mutation is rechecked against live target state immediately before it happens, so a decision made against state from an hour ago is not applied to state from now.
Those four are not independent. The first two split judgement from action. The third removes the credentials that would make judgement dangerous. The fourth handles the case where the world moved between the two. A bot that did only the first two would still be dangerous with a stale snapshot, and a bot with a fresh snapshot but write credentials would be dangerous in a different way.
The page also describes the review input as advisory rather than decisive. Related issue and pull request context, linked closing pull requests, existing local reports, optional crawl clusters and opt-in live search are gathered to support duplicate and superseded reasoning, and the page states plainly that this context is not a standalone close decision. The root-cause assessment that gets persisted is typed and proposal-only too, and it does not dispatch repair, suppress jobs, mutate siblings, close or merge.
For a maintainer, that means the output of a review is a document you read, not a change you discover later.
Four production targets, two owner namespaces, and a refusal to review third parties
The hosted instance names its targets explicitly. The dashboard Worker's production targets are four repositories in the openclaw organisation, plus a separate filesystem safety repository. Beyond those, additional public repositories in two namespaces can be handled through configured profiles or a conservative generic fallback, and the mechanism is event dispatch and scheduled fanout.
Then the paragraph that makes this an unusually well-behaved bot: the hosted instance is not a public review service and does not provide free reviews for third-party repositories. Anyone who wants it for their own project is told to fork the repository, deploy it in their own organisation, and configure that self-hosted instance for their own repositories.
So the deliverable is the code, not the service. The hosted deployment exists for four repositories and two owner namespaces, and the escape hatch is a fork under your own credentials rather than a sign-up form. That is the opposite of the usual bot pattern, where a maintainer invites the bot into a repository and the bot's operator accumulates write access across many projects.
The project also keeps its vision and boundaries in a separate document that the page links from the top, and points readers to a documentation index organised by task and audience, explicitly telling them to use the index rather than read the whole page. Seven or more separate documents are referenced from here alone, covering live proof, review comment format, related issue discovery, work lanes, the oversized pull request close policy and the repair automation guide.
So the readme is an index rather than a manual, which is the right shape for something this much machinery and also a reason the behaviour is hard to judge from the readme alone.
One record on disk, one comment edited in place, and markers you cannot see
The state model is the part of this design that is most obviously deliberate, and it starts from a problem every review bot creates: if a review runs on a schedule and posts its output as a comment, the issue fills up with repeated comments from the same bot.
The solution has three parts. Each review writes one durable markdown record at a path built from the repository slug and the item number, containing the decision, the evidence, the proposed maintainer-facing comment, runtime metadata and a GitHub snapshot hash. And ClawSweeper syncs one marker-backed public review comment per item, editing it in place rather than posting repeated completed reviews.
Coordination is handled without adding visible noise. Scheduled workers use a separate temporary status comment as a lease, while command-triggered exact reviews rewrite their existing acknowledgement and use the durable queue claim as their lease, so that path adds no second visible comment at all. Exact-review workers verify queue ownership before generating and again during finalisation, and temporary lease comments are removed after publication.
The fourth part is the one that matters most for automation. Pull request comments include hidden verdict and action markers, so the trusted repair and automerge flows can continue without scraping the visible prose. That is a deliberate decoupling: the human-readable comment can be reworded freely without breaking the machine path, and the machine state is not inferable from what a person reads.
A changed input invalidates the evidence. The contributing guide explains when to use the re-review command and why a changed head or pull request body needs fresh evidence, which is the same principle as the snapshot hash: the review described a specific state, and a different state is a different item.
It writes labels, so it records when it wrote them
Here is a bug this project found in itself and fixed in a way worth copying.
For open issues that have complete, current, kept-open reviews, ClawSweeper projects selected review conclusions into advisory GitHub labels so a maintainer can filter on them. The states it exposes include reproduction on the current main branch, reproduction from source, linked open pull requests, queueable fixes, verified small bugs that are suitable for a good first issue label, missing information, and a need for product or security review. The page is careful that these are advisory only and do not trigger repair, merge or close behaviour.
The problem is that writing a label to a GitHub issue changes the issue's updated timestamp. So the scheduler, which decides what needs attention based on recent activity, would see the bot's own writes as fresh target-side activity and review the item again. The bot would then be generating work because it had labelled something.
The fix is recorded in the durable report: label-only syncs write a labels-synced timestamp, so the activity check can tell the difference between a maintainer touching an issue and the bot touching it. That is a small field and a large amount of care, because the failure mode it prevents is the worst kind for an automated reviewer: a self-sustaining loop where the bot's output is the input that keeps the bot running.
It is also worth noting what the labels are for. They are a filtering aid for humans and project views, deliberately decoupled from behaviour, which is the same separation the rest of the design keeps between advice and action.
Above 50,000 changed lines it proposes closure before doing any work
The single most concrete rule in the documentation is a size ceiling with a specific number in it. The oversized pull request close lane proposes closing pull requests above fifty thousand changed lines, and it does so before hydration, before scanning, and before model review.
Read that ordering carefully, because it is the point. A bot that fetches a fifty thousand line diff, builds a tree listing for it, extracts the body, asks a model to review it and then decides, has already spent the fetch, the buffer and the tokens before it discovers the diff is unusable. The lane refuses to do any of that, which bounds the cost of the worst case in the system.
There is an exemption, and it is a maintainer action rather than a configuration setting: a size acceptance label lets a specific pull request through. So the escape hatch is per item and deliberate, which is the right granularity. A global threshold bump would be a change that affects every repository; a label on one pull request is a decision somebody made and can be found later.
The same reasoning shows up elsewhere. Pull request checkout preparation captures only the recursive tree's entry types, object IDs, sizes and a truncation flag from the GitHub command line client, with the stated reason that path and URL metadata would otherwise exhaust the response buffer. The existing checkout size limits and the rejection of incomplete or malformed trees are preserved rather than replaced.
That is the pattern worth naming: the size limit is not one rule, it is a limit on lines, a limit on tree metadata, and a rule that a truncated or malformed response is a rejection rather than a partial success.
Pull request text can never supply a download URL
ClawSweeper will fetch images and videos attached to a pull request, and it does so carefully enough to state one hard prohibition.
Media proof preparation recognises image and video filename extensions and GitHub attachment URLs, including legacy repository asset links. Attachments are fetched with GET and classified by the response content type. Images are saved locally, and videos are probed and converted into contact sheets, which is what lets a model look at a screen recording without downloading gigabytes of video into a prompt.
Then the rule: pull request patches and supplemental body excerpts never supply host download URLs.
That is a security boundary stated as a fact about the product rather than as a warning, and the reason is not hard to see. A pull request body is attacker-controlled text from a fork contributor. If a bot accepted a URL from that text and fetched it, then anyone who could open a pull request could make the bot request an arbitrary address on the network the bot runs on, and attach whatever came back to a review comment. The media route exists; the patch route does not.
The same thinking appears in the reverse direction. When the bot asks a maintainer for proof that a bug is real, it can request a Web UI or Telegram demonstration and evaluate the result in that same review turn, and it preserves validation, rendering, media publication and retraction for those historical artifacts. So human proof is a first-class input to a review, with a lifecycle, and it comes through channels the bot controls rather than through a link in a diff.
It is also worth noting that advisory review context explicitly does not dispatch repair, suppress jobs or mutate siblings, so gathering context from related items cannot turn into an action on them.
The model gets no write credentials, and readiness is not merge authority
The contributing guide contains the sentence that explains the rest of the design, and it is a negative one: readiness is not merge authority.
What that rules out is a specific and tempting shortcut. A bot that can tell a pull request is ready has everything it needs to look like an authority on whether the pull request should merge. Those are different claims. Readiness is a statement about the review's own state, and treating it as permission collapses a proposal into a decision, which is exactly what the proposal-only design refuses to do elsewhere.
The credential arrangement supports the same line. Codex never gets write credentials during review, and repair of pull requests runs through a bounded review and fix loop, and only for pull requests that opted in. There is a mode that reviews local branch ranges with repository and GitHub access kept local while only the model service is contacted remotely, so the code under review does not have to leave the machine for a review to happen.
Maintainers drive the bot through four comment commands, review, fix, autofix and automerge, plus a re-review command for when the evidence is stale. Those commands can be acknowledged through an optional GitHub App webhook before the GitHub Actions fallback starts, so the interactive path is fast when the app is installed and still works when it is not.
So there are two independent brakes on the same action: the model cannot write, and a human command is required. Neither of them is a technical control in the sense of a signature check; they are role boundaries, and they hold because the deployment respects them.
Three build targets, three state stores, and a release list out of date order
The code is split three ways at build time, and the split follows the trust boundary rather than the feature list. The main build compiles the review and apply path, a repair build compiles the code that modifies pull requests, and a dashboard build compiles the interface. There is a combined node build that runs the first two and an all build that runs all three, and four TypeScript configuration files exist at the top level, one of which is a strict variant for the dashboard with no build script among the visible ones.
The scripts also reveal two entry points rather than one. Most commands run a single compiled file, including plan, review, apply-decisions, apply-artifacts, audit, reconcile and status. Local review runs a different compiled file. And the repair subsystem has its own directory of scripts, including a validation pass over all jobs, a containment preflight, a policy gate and a policy run, so the thing that can change a pull request has its own gate and its own smoke test.
State is split three ways as well, and this is the part worth arguing about. Canonical review records go to a Cloudflare Worker, action ledgers and assets go to R2, and the remaining operational state goes to a separate repository named for the project's state. So the durable record of a decision, the binary artifacts, and the operational bookkeeping live in three different systems with three different failure modes.
Two smaller things at the top level. The changelog is maintained as a directory of fragments alongside the changelog file itself, which is how changes get written without contending for one file. And the releases are listed out of date order, with the two May releases above the June one, while the manifest in the repository carries a version one patch ahead of the newest published tag. The branch was pushed on 2026-10-02, so the newest release is several months behind the source.
Editorial conclusion
Read this as a worked example of a bot designed around its own blast radius, because that is what most of the documentation is about. Four of its safety properties are stated in the first screen of the page, the state model avoids spamming issue trackers by keeping one record on disk and one edited comment per item, and there is a size ceiling that stops the bot spending model budget on a diff nobody can read. That design is worth studying whether or not you run it. Two things decide whether you can. First, scope: the hosted instance names four production repositories and two owner namespaces, and the documentation is explicit that it is not a service for third-party projects, so using it on your own repository means forking it and running your own instance with your own credentials. Second, model trust: the model reviews without write access, apply re-fetches live state before acting, and a readiness signal is explicitly not permission to merge, which is the right chain but means a human is still the last step on every change. Read the vision and boundaries document before the readme, since the readme is mostly an index to it. And if you are tempted by the autofix and automerge commands, note that both are described as guarded and that repair applies only to pull requests that opted in.
Frequently asked questions
What does ClawSweeper actually do to a repository?
It reviews open issues and pull requests on a schedule and on exact events, writes one durable markdown record per item containing the decision, evidence and a GitHub snapshot hash, and keeps a single marker-backed review comment per item that it edits in place. Review is proposal-only, apply is guarded, and every mutation is rechecked against live state immediately before it happens.
Can I use the hosted ClawSweeper instance for my own project?
No. The page states the hosted instance is not a public review service and does not provide free reviews for third-party repositories, and the instruction is to fork the repository, deploy it in your own organisation, and configure that instance for your own repositories.
What is the 50,000 changed line rule in ClawSweeper?
Pull requests above 50,000 changed lines are proposed for closure before hydration, scanning or model review, and a maintainer can exempt an individual pull request with a size acceptance label. It is a cost and safety limit rather than a review of that diff.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openclaw-clawsweeper)Star history chart for your README
[](https://hysenlabs.com/projects/openclaw-clawsweeper)Was this useful?