LabelLLM publishes six ports and four sets of default passwords
The Open-Source Data Annotation Platform
At a glance
- What is it?
- LabelLLM is OpenDataLab's multimodal annotation platform: configurable task tools for audio, image and video, task management with progress and quality control, and AI pre-annotation that a person then corrects. The deployment is one `docker compose up`, and the file that does it publishes the cache, the database, the object store and both application services on host ports with their default passwords still in place.
- Who is it for?
- LabelLLM fits a small team that needs one place to run annotation tasks across audio, image and video, and that can host it on a machine it controls.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 136 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
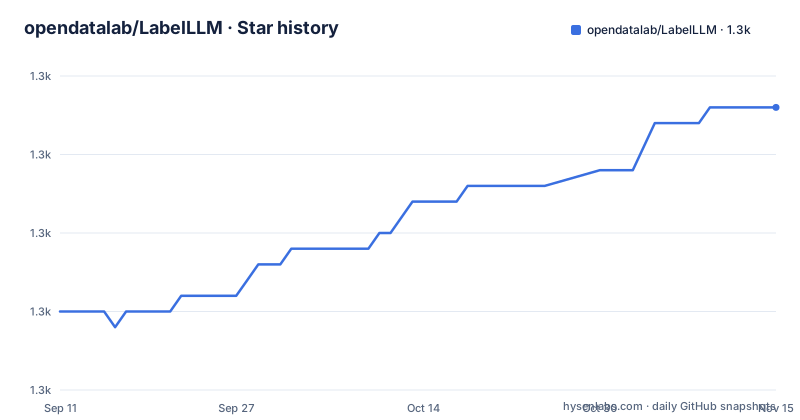
- opendatalab/LabelLLM1,293 ★ · +13
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| opendatalab/LabelLLM | 1.3k | 1.3k |
13 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The setup instructions publish credentials you are meant to replace
Step four of the local deployment gives you a login for the object store console: username `user`, password `password`. Step five is more direct. It tells you to create a new access key and then lists two values inline, an Access Key of `MekKrisWUnFFtsEk` and a Secret Key of `XK4uxD1czzYFJCRTcM70jVrchccBdy6C`, before explaining where they come from.
The explanation is that the built-in pair lives in `backend/.env`, and that you can either copy those values or create a new access key and update the file. So the page is doing the right thing in spirit: it tells you the pair is a default and points at the file to change.
The problem is that the default is printed in a public README, which means anyone who has read it can try those credentials against any deployment that was not changed. For a service whose job is to hold annotation data, that is the first thing to fix, before anything else in this article.
There are two credential systems to keep straight while you do it: the web login for the operator and labeler interfaces, and the API key pair the backend uses. Both default to something published.
Five services, six published ports, none restricted to loopback
The Compose file is the whole deployment, and it is worth reading as a network exposure list rather than as configuration. Five services run: Redis, MongoDB, MinIO, the backend and the frontend.
Four of them publish their internal port on the host. Redis publishes 16280 for 6379. MongoDB publishes 16019 for 27017. MinIO publishes both 9000 and 9001. The backend publishes 16666 for its own 8080, and the frontend publishes 8086 for port 80. The whole set comes up with:
docker compose upNone of the port mappings carries a host address, which in Compose means every interface. So a single-machine install is listening on Redis, MongoDB and the object store as well as on the two application ports, and the first three were never meant to be reachable from anywhere but the compose network.
The credentials travel with it. MongoDB is initialised with a root username of `root` and a root password of `mypassword`, and MinIO is configured with `user` and `password` plus a default bucket name.
The images are also old: Redis 5.0, MongoDB 4.2, and a Bitnami MinIO image tagged by year. That combination is a project that has not revisited its dependency base in a while, which is fine for a local tool and worth knowing before you expose it.
The documented way to collaborate is to publish it on your network
Once the stack is up, the page sends you to two paths on the same frontend port. One is the supplier side, which is the labeling interface for people doing the work. The other is the operator side, and it comes with the username `admin`. So a single container serves both roles, distinguished by path and by account.
Then comes the instruction that matters: replace localhost with the corresponding IP address to share it with other team members so they can use it directly without repeated deployment.
That is a reasonable convenience and it is also the moment this deployment stops being a local tool. Combined with the published credentials from the previous section and the six unbound ports, the documented sharing step is what turns a development stack into something exposed. A team following the page exactly will end up with an annotation platform, a database, a cache and an object store reachable from the office network, all on their defaults.
The same section carries the one governance rule that is spelled out: the first account registered becomes the administrator by default, and subsequent accounts need privileges granted for the operator side. The page then asks you not to forget that first account and password, which is the only account problem it warns about.
The documentation is in the wiki, and the README is a landing page
Almost nothing technical is in the repository's own README. The user manuals are wiki pages: one for the operation side, one for labeler, and a frequently asked questions page. There are video tutorials for the product and for the deployment, and configuration documentation lives in a readme inside the backend directory and another inside the frontend directory. Release notes are a file at the root.
So the repository is four entries plus the wiki, and the README is the marketing surface: an introduction paragraph naming the audience as independent developers and small to medium research teams, four bolded feature headings, and three product characteristics that are three adjectives.
That shape is legible enough to comment on. The only mechanism described with any specificity is AI-assisted annotation, which supports pre-annotation loading that users refine and adjust according to actual needs. The rest are nouns: flexible configuration, multimodal support across audio, image and video, and a task management system offering real-time monitoring of progress and quality control.
The English is also visibly translated, with a misspelled section heading, a button label that misspells manual, and annotation spelled two different ways in the introduction. That is normal for a project maintained in Chinese, and the Chinese README is a wiki page in its own right, but it does mean the repository tells you very little about what the system actually does.
The citation points at the parent platform, not at this tool
The citation block on the page is a BibTeX entry for the OpenDataLab platform paper, titled as empowering general artificial intelligence with open datasets, published as an arXiv preprint in 2024 with six authors.
That paper is about the platform. LabelLLM is one tool in it, alongside the two other projects the links section names: LabelU, described as another multimodal labeling artifact from the same organisation, and MinerU, a document extraction tool.
So there is no paper for this tool to cite, and the citation block is doing double duty as an attribution for the wider effort. That is a reasonable thing to do and worth knowing if you are looking for the method behind the pre-annotation feature, because the paper will describe the platform rather than this application.
The links also place the tool in a family. LabelU is the general multimodal annotation product, and LabelLLM is the one aimed at LLM data preparation, which is why its feature list is organised around task configuration and pre-annotation rather than around drawing tools.
China-specific mirror advice and three video links
The deployment section contains a piece of advice that only makes sense for one audience. If you are in China, it suggests adding a registry mirror to the Docker daemon configuration, giving a mirror URL and a link to that project's documentation, so the initial image pull is faster. It also warns that the first installation may take some time and asks for patience and a good internet connection.
The operating system advice is narrower still: run it on Linux, and if the installation gives you trouble, the answer is the frequently asked questions wiki page.
Alongside that there are three video links, one of which is a deployment tutorial, plus the project's own video channels on YouTube and Bilibili and an invitation to an official social group for technical communication.
None of this is a criticism. It is a project whose primary audience is in China, documented accordingly, with the deployment knowledge living in video and wiki rather than in the repository. The practical consequence for anyone else is that the questions this page does not answer are the ones the wiki does.
A pre-1.0 codebase with no releases and a three month gap
The repository is small and conventional: a gitignore, a licence file, the README, a backend directory, a frontend directory, a Compose file and a release notes file. The primary language is TypeScript, which matches a web frontend paired with a separately built backend, and the default branch is main.
There are no GitHub releases. The last push is dated 2026-07-02, which is about three months before this writing. The project is not archived.
That combination is worth reading carefully rather than as a red flag. A platform demoed through a hosted address, documented in a wiki, and deployed by Compose into Redis, MongoDB and MinIO has no reason to cut releases, and the release notes file at the root is where its history lives. But the three services it depends on are pinned several major versions back, so the cost of running it is not the annotation tooling, it is keeping an old MongoDB and an old Redis alive on whatever host you choose.
The licence is Apache-2.0, and the hosted demo is on a separate address from the documentation, which is the usual arrangement for a project whose users arrive from a demo and deploy themselves.
Editorial conclusion
LabelLLM fits a small team that needs one place to run annotation tasks across audio, image and video, and that can host it on a machine it controls. Verify five things before anyone else opens it: that you have changed the login on the first port, the built-in access key pair, the database root password and the object store credentials, since all four are published in the setup instructions or the Compose file; that the ports for the cache and the database are not reachable from a network you do not control, because publishing them is unnecessary for a single-machine install; which account is the administrator, since the first one registered is; that your team reaches it through a tunnel or a private network rather than by replacing localhost with an IP; and which version you are running, since there are no releases and the last push is dated 2026-07-02. Apache-2.0 licensed.
Frequently asked questions
How do I run LabelLLM locally?
Clone the repository or download the zip, install Docker and start the Docker service, then run `docker compose up` in the project directory and open localhost:9001. The page recommends Linux and points to the FAQ if the install fails, and warns that the first installation can take a while.
What are the default credentials for LabelLLM?
The setup instructions give username user and password password for localhost:9001, and print a built-in Access Key and Secret Key pair that can also be found in backend/.env or replaced by creating a new access key. The first account registered becomes the administrator by default.
Which ports does the LabelLLM Compose file publish?
Six, across five services: Redis on 16280, MongoDB on 16019, MinIO on 9000 and 9001, the backend on 16666 mapping to 8080, and the frontend on 8086 mapping to 80. None of the mappings is restricted to a host address, so they bind every interface by default.
What can LabelLLM annotate?
Audio, image and video under one platform, with task-specific tools that are configurable to a project's parameters, a task management system offering real-time monitoring of annotation progress and quality control, and AI-assisted annotation through pre-annotation loading that users refine and adjust.
Where is the LabelLLM documentation?
In the project wiki rather than the repository: separate manuals for the operation side and for labelers, a frequently asked questions page, and video tutorials including one for deployment. Configuration details live in backend/README.md and frontend/README.md, and release notes are at the repository root.
Is LabelLLM's database reachable from outside the machine?
It is published that way by default. The Compose file maps MongoDB to host port 16019 and Redis to 16280 in addition to the application ports, and sets the MongoDB root password and the MinIO credentials to simple values in the file itself. Restricting or removing those mappings is the first change to make before sharing the deployment.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opendatalab-labelllm)Star history chart for your README
[](https://hysenlabs.com/projects/opendatalab-labelllm)Was this useful?