OpenRefine: the four-step workflow, two launchers, and a README that stops there
OpenRefine is a free, open source power tool for working with messy data and improving it
At a glance
- What is it?
- OpenRefine is a Java application for loading, cleaning, reconciling, and web-augmenting messy data from a browser on your own machine. What the repository actually tells you is mostly about running it, licensing it, and funding it, so the feature detail lives in a separate manual and a wiki.
- Who is it for?
- OpenRefine fits researchers, archivists, and anyone who has to make a messy file defensible without uploading it somewhere. Skip it when your work needs a guarantee: a support window, a compatibility table, or an assurance that master and your build behave the same.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
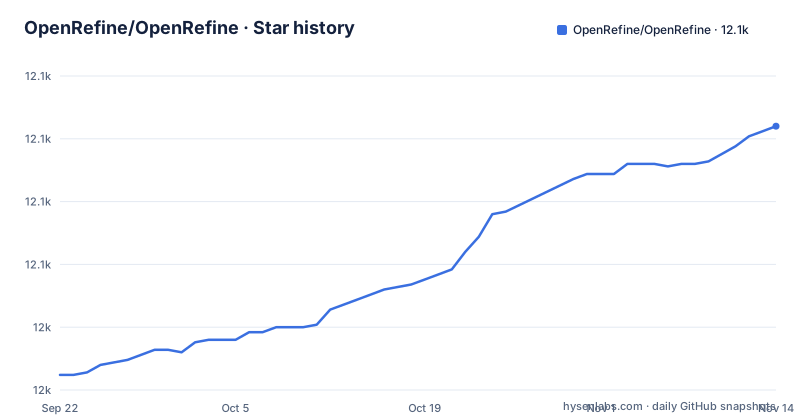
- OpenRefine/OpenRefine12,105 ★ · +99
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| OpenRefine/OpenRefine | 12k | 12.1k |
99 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Running from source pulls in three toolchains before any data loads
Three requirements sit between a clone and a running application: JDK 11 or newer, Apache Maven, and Node.js 18 or newer. The launcher is one of two files in the repository root, `./refine` on Mac OS and Linux and `refine.bat` on Windows, so the same checkout produces a different entry point depending on the platform. The Node.js requirement is the one that catches people out. This is a Java application with a web interface, and building it from source still expects a JavaScript runtime on the machine, so a team with no Node.js installed still has to install something before the first dataset opens. Running from source is therefore not the lightweight path for people who dislike installers. It is a full build path, and the alternative is the releases page, which ships prepared builds instead.
Snapshot downloads assume a GitHub login and CI literacy
Development builds are not served from a plain download page. To get one you log in to GitHub, open the snapshot release workflow page, take the first item carrying a green tick or check mark, scroll down to the Artifacts section, and find the version that matches your operating system. Four assumptions are baked into that flow: that you can authenticate to GitHub, that you know the exact OS label to look for, that you can read a list of continuous integration runs, and that a development version is what you actually want. Someone who wanders down this path by accident ends up running an untagged build over real data with no stability statement attached to it. Versioned builds live on the releases page instead, where the newest entry is 3.10.1.
master moves faster than the versioned releases
The branch of record is master, and the most recent push to it is 2026-11-02, while the tagged releases stop earlier: 3.10.0 on 2026-02-26, 3.10.1 on 2026-03-04, and a 3.10-beta2 on 2026-02-10 before both. That leaves roughly eight months between what you can read in the repository and what you can download. Two consequences follow. Documentation and extension code you inspect on master describe a build you do not have, and an extension written against master can assume behavior the released build lacks. If reproducibility matters more than novelty, take 3.10.1 and treat master as a development surface you read rather than run. The repository is not archived and the branch does move, so the gap is a fact of the current calendar, not a sign of abandonment.
Dependency notices live in per-module licenses folders
The tree explains the shape of the code and, unusually for a project of this size, the shape of its licensing audit. `main/` holds the web application, `extensions/` holds the extension modules, `modules/` and `server/` sit alongside them, `packaging/` deals with builds, `conf/` with configuration, and `benchmark/` with performance work, with `pom.xml` at the root as the Maven entry point. `refine.ini` is the launcher configuration sitting next to the two launcher scripts, and directories named `.idea/` and `vscode` alongside an `IDEs/` folder suggest contributors are expected to work inside an editor rather than only from a shell. Licensing is handled with the same explicitness: the project license is in `LICENSE.txt`, and information about the open source libraries OpenRefine depends on lives in `licenses` folders under `/main/webapp/` and inside each extension, which is one of the easier places to check what a build pulls in.
The privacy promise holds until a web step runs
The pitch is a browser interface over your own computer: load data, understand it, clean it up, reconcile it, and augment it with data coming from the web, with the comfort and privacy of your own machine as the stated benefit. Read closely, that promise has a boundary that the README does not spell out. Any step that augments from the web, or reconciles against a service, has to make an outbound request, so the file stays local while the queries do not, and nothing in the documentation says what is transmitted to those services or whether the requests are logged. For a public dataset that distinction changes nothing. For internal records, names, or anything you would not paste into a search engine, you need to decide which reconciliation service you point at before you start, and you should read that code yourself rather than assume.
Facets, clustering, and the extension API are documented elsewhere
What the README does not contain is the feature list. There is no section on facets, no mention of clustering, no description of the reconciliation protocol, no catalog of transformations, and no documentation of the extension API. The links point outward instead: a user manual at openrefine.org/docs and a FAQ living in the GitHub wiki. That is a deliberate division, and it works if you are willing to read two sources, but it makes the README useless as a feature reference. Anyone skimming it for capabilities comes away with the shape of the workflow and nothing about what any individual step does. Extensions are equally thin in the repository: the `extensions/` directory exists, and beyond that there is no registry, no compatibility table against version 3.10, and no statement of which extension version pairs with which release.
Three product names explain most stale tutorials
The history explains why older material uses words you will not find in the repository. The software was created by Metaweb Technologies, originally written and conceived by David Huynh, and Metaweb was acquired by Google in July 2010, at which point the product was renamed Google Refine. In October 2012 it was renamed OpenRefine as it transitioned to a community-driven project. Anything written before late 2012 will say Google Refine, and search results, wiki pages, and forum threads from that era can all describe an interface that no longer matches what you download. The current stewardship has its own shape: since 2020 the project has been fiscally sponsored by Code for Science and Society, and it is maintained by a small core team that relies on grants plus community support.
Governance files exist, support windows do not
What the repository carries is process rather than promises. At the root sit `GOVERNANCE.md`, `CONTRIBUTING.md`, `CODE_OF_CONDUCT.md`, `SECURITY.md`, `AGENTS.md`, and a `funding.yml`, alongside a machine-readable funding manifest at openrefine.org/funding.json, a donation path at openrefine.org/donate, and a store at store.openrefine.org. The README gives no support policy for past versions, a stated long-term-support branch, or a compatibility statement tying extensions to a release. The practical reading for an adopter is that you are depending on a small team whose money comes from grants, so your own timeline matters more than a vendor's. If your work needs a guaranteed fix window, that guarantee has to come from your process, and keeping the exact build you ran is the cheapest version of it.
Editorial conclusion
OpenRefine fits researchers, archivists, and anyone who has to make a messy file defensible without uploading it somewhere. Skip it when your work needs a guarantee: a support window, a compatibility table, or an assurance that master and your build behave the same. Before committing, read the user manual for the features, since the README only gives the four-step shape of the workflow, and choose your reconciliation service deliberately, because that is where local data meets the network.
Frequently asked questions
What is OpenRefine used for?
It is a Java-based power tool that loads data, helps you understand it, cleans it up, reconciles it, and augments it with data coming from the web. All of that runs in a web browser on your own computer.
How do I install OpenRefine?
Download a prepared build from the OpenRefine releases page. Running from a clone needs JDK 11 or newer, Apache Maven, and Node.js 18 or newer, then `./refine` on Mac OS and Linux or `refine.bat` on Windows.
Is OpenRefine safe to use?
The project frames it as running in a web browser on your own computer, with the privacy of that machine as the benefit. Steps that reconcile or augment from the web make outbound requests, and the README does not document what those requests contain.
Is OpenRefine better than Excel?
No comparison with Excel is published. What is documented is the workflow of loading, understanding, cleaning, reconciling, and web-augmenting data, plus the extension modules that live under the `extensions/` directory.
Does OpenRefine use AI?
No AI or machine learning capability is described in the README. The stated capabilities are loading data, understanding it, cleaning it, reconciling it, and augmenting it with data coming from the web.
Is OpenRefine free and open source?
Yes to both. It is described as a free, open source power tool, licensed under the BSD license in `LICENSE.txt`, with information about dependent open source libraries kept in `licenses` folders under `/main/webapp/` and inside each extension.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openrefine-openrefine)Star history chart for your README
[](https://hysenlabs.com/projects/openrefine-openrefine)Was this useful?