What OpenVINO's setup.py and pyproject.toml actually commit you to
OpenVINO™ is an open source toolkit for optimizing and deploying AI inference
At a glance
- What is it?
- A C++ inference runtime that reads models from PyTorch, TensorFlow, ONNX and JAX, compiles them onto a short, Intel-centered device list, and ships as a Python wheel with a pinned dependency set. Read below for the packaging ceilings, the device menu, and the parts of the Python binding the project stops type checking.
- Who is it for?
- OpenVINO fits a team that has settled on x86 or ARM CPUs, an Intel integrated or discrete GPU, or an Intel NPU, and that wants one runtime reachable from C++, Python, C or NodeJS. The terms to settle before committing are all visible in the packaging: Python 3.11 is the floor, numpy is capped below 2.6.0, telemetry arrives by default, and each wheel carries one baked-in architecture label.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
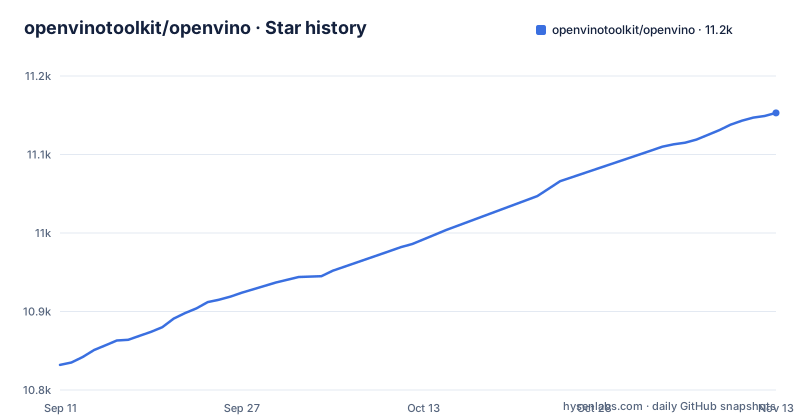
- openvinotoolkit/openvino11,153 ★ · +321
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| openvinotoolkit/openvino | 10.8k | 11.2k |
321 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One device string, three target classes, four language bindings
The device selection in every worked example is the same single string. `ov.convert_model(model, example_input=(example,))` produces a model, `core.compile_model(ov_model, 'CPU')` names a target, and that string is the whole choice at that point. The documented target classes are CPU on x86 and ARM, GPU on Intel integrated and discrete parts, and AI accelerators written up as Intel NPU. Nothing in that list names a non-Intel GPU, so an AMD card has no supported destination in the documented targets. The language surface is much wider than the hardware surface: APIs exist in C++, Python, C and NodeJS, a separate GenAI API covers optimized model pipelines, and the repository carries sample trees for all four languages under samples/c, samples/cpp, samples/js and samples/python. An accelerator outside that list has no stated option in the README, so check the supported devices page before choosing hardware.
pip install -U openvino pulls telemetry and a numpy ceiling
Quick installation is one shell line, and the README also points to a distributions page for the other packaging routes.
pip install -U openvinoThe metadata in pyproject.toml draws the boundaries. requires-python is set to >=3.11 and the classifiers stop at 3.14, so Python 3.10 and older sit outside the declared range rather than being merely discouraged. Two runtime dependencies ship by default: numpy capped at <2.6.0, and openvino-telemetry at 2023.2.1 or newer. The numpy ceiling is a hard resolution constraint, so an application that needs a newer numpy cannot share one interpreter with OpenVINO, and the telemetry package is present in a plain install rather than something you opt into. Building from source adds four build requirements, including cmake held at or below 4.4.4 and a patchelf pin that only applies on Linux x86_64. A prebuilt wheel skips that toolchain entirely, which is the practical difference between the two routes.
The wheel carries an architecture label baked at build time
The wheel is not a thin wrapper around a shared library. setup.py sets WHEEL_PACKAGE_DIR to openvino, WHEEL_LIBS_INSTALL_DIR to openvino/libs and WHEEL_LIBS_PACKAGE to openvino.libs, so the compiled runtime is carried inside the Python package and unpacked beside it. The native library directory is bin on Windows and lib everywhere else, and the architecture label is chosen from platform.machine(): intel64 for x86_64 or AMD64, ia32 for X86 or i686, arm, arm64, and riscv64. Because that label is fixed during the build, one wheel does not serve every machine type. Two consequences follow for a reader. A wheel built for one machine type will not load on another, and riscv64 has its own branch in setup.py even though the documented device line stops at x86 and ARM CPUs. Build output goes to a directory named after the interpreter, and the tag gains a t suffix on a free-threaded build.
convert_model wants an example tensor, inference is keyed by port
Conversion and inference are two separate commits, and each has its own shape requirement.
import openvino as ov
import torch
import torchvision

# load PyTorch model into memory
model = torch.hub.load("pytorch/vision", "shufflenet_v2_x1_0", weights="DEFAULT")

# convert the model into OpenVINO model
example = torch.randn(1, 3, 224, 224)
ov_model = ov.convert_model(model, example_input=(example,))

# compile the model for CPU device
core = ov.Core()
compiled_model = core.compile_model(ov_model, 'CPU')

# infer the model on random data
output = compiled_model({0: example.numpy()})
The PyTorch sample hands convert_model a tensor, torch.randn(1, 3, 224, 224), so the converter has something to trace. The TensorFlow sample calls ov.convert_model(model) with no example at all, leaving the converter to read what it can from the object. Inference is then addressed by port number, not argument order: the dictionary passed at call time uses the input port identifier as its key. In both samples the single input is addressed with the key 0. In both samples, inference is called on the compiled model rather than on the converted one.
The type checker is pointed away from the largest Python surface
The type checking configuration states which parts of the Python binding go unchecked. The pyright block includes src/bindings/python/src but excludes pyopenvino, and its ignore list names ops.py, the data dispatcher, utils/types.py, utils/decorators.py, frontend/frontend.py, _ov_api.py, _op_base.py, utils/node_factory.py, and the tensorflow, pytorch and jax frontend packages. Several report flags are turned off, including reportMissingModuleSource, reportMissingImports and reportIncompatibleMethodOverride. That is a deliberate trade against the size of the surface, and it has a direct effect: an editor or a CI type check stays silent about the op definitions, the Python API wrapper and the framework frontends, so a mistake in those files is caught by running the code rather than by reading diagnostics. Formatting is configured separately, with black set to line-length 160, which is worth knowing before you run any formatter over contributed code. The net result is that static checking covers the bindings layer while the conversion layer is verified at execution time.
GenAI and the C++ dependency graph live outside the pip package
What pip install -U openvino does not deliver is the generative layer. The GenAI API has its own installation page, its samples live in a different repository, openvinotoolkit/openvino.genai, and the notebooks sit in openvino_notebooks covering a chatbot, YOLOv11 optimization, text to image, a LLaVa multimodal assistant and Whisper speech recognition. C++ consumers are not served by pip at all. The top level of the repository carries conanfile.txt, conan.lock and vcpkg.json beside CMakeLists.txt, cmake/, thirdparty/ and install_build_dependencies.sh, with Jenkinsfile describing the build. Third-party licensing is explicit rather than implied, since licensing/runtime-third-party-programs.txt, licensing/onetbb_third-party-programs.txt and licensing/onednn_third-party-programs.txt travel with the LICENSE file and are named in the build metadata.
Three releases in six weeks, and what stays undocumented
The release cadence is tight. Version 2026.4.0 landed on 2026-09-16, 2026.4.1 on 2026-10-01, and 2026.3.1 on 2026-08-26, and the last push to the repository is dated 2026-11-02 with no archived flag. That pace is a fact to absorb when planning upgrades: 2026.4.1 arrived about two weeks after 2026.4.0, so a pinned version can age quickly. The Benchmarks link in the README points at an Intel model hub page rather than at results stored in the repository, and both worked examples feed random data to shufflenet and MobileNetV2, so the worked examples demonstrate no accuracy outcome. Contributor files such as AI_USAGE_POLICY.md, CODE_OF_CONDUCT.md, SECURITY.md and CONTRIBUTING.md address people writing to the project, not people integrating it.
Editorial conclusion
OpenVINO fits a team that has settled on x86 or ARM CPUs, an Intel integrated or discrete GPU, or an Intel NPU, and that wants one runtime reachable from C++, Python, C or NodeJS. The terms to settle before committing are all visible in the packaging: Python 3.11 is the floor, numpy is capped below 2.6.0, telemetry arrives by default, and each wheel carries one baked-in architecture label. Anyone expecting an AMD or other non-Intel accelerator, or expecting pip to bring a GenAI pipeline, finds neither here. Check the supported devices and system requirements pages for your exact part, and read the release notes across the 2026.3 and 2026.4 lines, since 2026.4.1 followed 2026.4.0 by about two weeks.
Frequently asked questions
What is OpenVINO used for?
It is a toolkit for optimizing and deploying deep learning inference, covering computer vision, automatic speech recognition, generative AI, and natural language processing with large and small language models.
Is OpenVINO owned by Intel?
The package author in pyproject.toml is listed as OpenVINO Developers with the address [email protected], the license is Apache-2.0, and the README links its Benchmarks entry to an Intel model hub page.
Is OpenVINO only for Intel?
Not entirely. CPU inference is documented for x86 and ARM, but GPU support is listed as Intel integrated and discrete GPUs and accelerators as Intel NPU, so hardware coverage stops at Intel for those two classes.
Which Cpus support OpenVINO?
The device list names CPU on x86 and ARM. setup.py maps build machine types onto intel64, ia32, arm, arm64 and riscv64 labels, but no RISC-V device is claimed in the documented device list.
how to install openvino
The README gives pip install -U openvino for a quick install, and links to an install-openvino documentation page for the other distribution formats, including the ones published on PyPI, npm, conda-forge and Homebrew.
how to use openvino in audacity
Audacity and noise suppression do not appear in the README's installation, tutorial or generative AI sections. The examples it points to are the OpenVINO notebooks, the openvino.genai samples, and the C++ and Python sample trees in the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openvinotoolkit-openvino)Star history chart for your README
[](https://hysenlabs.com/projects/openvinotoolkit-openvino)Was this useful?