LMFlow: one pip line, eleven extras, and a 2025 rewrite
An Extensible Toolkit for Finetuning and Inference of Large Foundation Models. Large Models for All.
At a glance
- What is it?
- OptimalScale's LMFlow puts finetuning, DPO, RAFT, LoRA merging and vLLM or SGLang inference in one Apache-2.0 tree, but the base install carries almost none of the interesting backends, and the 2025 rewrite left the older code on a separate branch.
- Who is it for?
- Use LMFlow when you want finetuning, DPO, RAFT, and vLLM or SGLang inference inside a single Apache-2.0 tree and you are willing to read the extras table before you install. Skip it if you need a tagged release to plan around, because the newest tag is v1.0.0 from 2025-07-11 while the last commit landed 2026-08-10, and pin datasets and cpm_kernels exactly before you let pip touch an existing environment.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 97 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
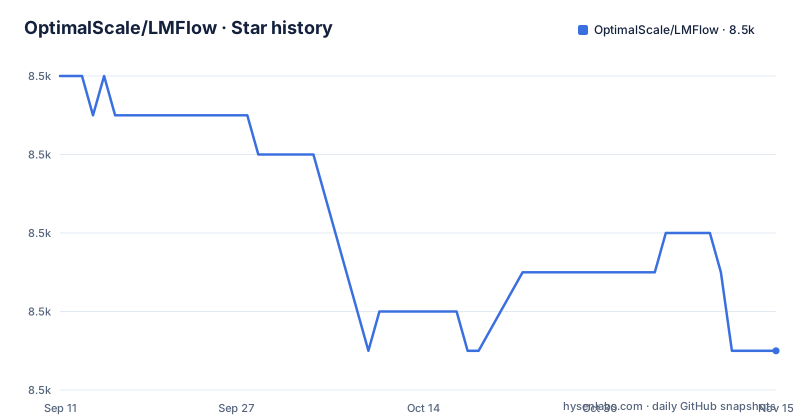
- OptimalScale/LMFlow8,481 ★ · -7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| OptimalScale/LMFlow | 8.5k | 8.5k |
-7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
setup.py names the package lmflow while PyPI ships lmflow-finetune
Installation is one PyPI line, and the naming around it is inconsistent. The 2023-06-07 news entry tells you to run pip install lmflow-finetune, while setup.py declares name="lmflow" with the description LMFlow: Large Model Flow. and package_dir={"": "src"}, so the import you write is lmflow even though the distribution you download is lmflow-finetune.
pip install lmflow-finetuneThe version is not written in setup.py, and the dependency list is not written there either. Both are pulled out of files at build time:
folder = os.path.dirname(__file__)
version_path = os.path.join(folder, "src", "lmflow", "version.py")

__version__ = None
with open(version_path) as f:
    exec(f.read(), globals())

req_path = os.path.join(folder, "requirements.txt")
install_requires = []
if os.path.exists(req_path):
    with open(req_path) as fp:
        install_requires = [line.strip() for line in fp]
So the dependency floor you get is whatever requirements.txt says on the commit you installed. Your first run is a script chosen from examples/, and nothing in the package picks it for you: finetune.py, inference.py, and chatbot.py are the three you will meet first, chatbot_gradio.py puts the same conversation in a browser, and the multimodal chatbot has Python entry points, vis_chatbot.py and vis_chatbot_gradio.py, plus a shell script, scripts/run_vis_chatbot_gradio_minigpt4.sh. Each script takes its own flags.
The extras table is where the real feature list lives
Base requirements.txt has torch, transformers, peft, accelerate, datasets, evaluate, bitsandbytes, wandb, sentencepiece, pydantic, einops, tensordict, tokenizers, pyarrow, packaging, numpy, and cpm_kernels, and nothing else. Everything else sits in extras_require:
extra_require = {
    "multimodal": ["Pillow"],
    "vllm": ["vllm>=0.8.0"],
    # pybase64 is imported eagerly by sglang.utils but not declared as a hard
    # dep upstream; without it `import sglang` raises ModuleNotFoundError.
    "sglang": ["sglang", "pybase64"],
    "ray": ["ray>=2.22.0"],
    "gradio": ["gradio"],
    "flask": ["flask", "flask_cors"],
    "flash_attn": ["flash-attn>=2.0.2"],
    # rich is lazy-imported by trl's DPOTrainer; not declared in trl 0.11.x.
    "trl": ["trl>=0.11,<0.12", "rich"],
    "deepspeed": ["deepspeed>=0.14.4"],
    "develop": ["pytest"],
    "dev": ["ruff", "pytest", "pre-commit"],
}
Two entries carry comments about a dependency the upstream package forgot, which is a fair signal that these extras are maintained by hand. The consequence for a reader is blunt: the base install runs a plain finetune and stops there. dpo_train.py, dpov2_train.py, iterative_dpo_train.py, vllm_inference.py, and sglang_inference.py all assume you asked for the matching extra.
Three exact pins decide what you are allowed to upgrade
Most dependencies carry a floor, but three carry a ceiling of one version:
packaging
numpy
datasets==3.6.0
pyarrow>=15.0.0
tokenizers>=0.13.3
peft>=0.10.0
torch>=2.0.1
wandb
sentencepiece
transformers>=4.31.0
cpm_kernels==1.0.11
evaluate==0.4.0
bitsandbytes>=0.40.0
pydantic
accelerate>=0.27.2
einops>=0.6.1
tensordict
datasets==3.6.0, cpm_kernels==1.0.11, and evaluate==0.4.0 are written with double equals, so pip will pull a newer release of any of them down or refuse to install. That matters in a shared environment where another project needs a different datasets. The trl extra also stops below 0.12, at trl>=0.11,<0.12. wandb sits in the base list, so it is installed whether or not you want experiment tracking.
The 2025 rewrite left the pre-Accelerate code on its own branch
The most important line in the news list is dated 2025-07-09 and reads as a warning rather than a feature: LMFlow had a major update with full Accelerate support and extensive streamlining, and anyone who wants the previous version is told to check out v0.0.10 or the v0.0.10 branch. Two days later the v1.0.0 tag appeared, so main and the released tag are the rewritten tree, while everything people wrote tutorials against in 2023 and 2024 lives one branch away:
git checkout v0.0.10That split is the main hazard for anyone arriving from a blog post. A script written for the older tree may not match the rewritten one, so check which tree it targets. Decide which tree you are targeting before you write a single flag, and note that accelerate>=0.27.2 is a base dependency now, so the distributed training story of the new tree arrives through an ordinary pip requirement rather than an extra.
Nine scripts pick the alignment method and nothing ranks them
The examples directory is a menu rather than a pipeline. finetune.py does supervised finetuning. dpo_train.py, dpov2_train.py, and iterative_dpo_train.py are three separate preference-optimization entry points. reward_modeling.py trains a reward model and rm_inference.py scores with one. raft_align.py runs Reward rAnked FineTuning, proposed on 2023-04-10 as more efficient than conventional PPO-based RLHF, with its paper at arXiv 2304.06767. multistage_finetune.py chains stages, and merge_lora.py folds an adapter into its base model. Custom optimizers arrive through a separate shell script, scripts/run_finetune_with_custom_optim.sh, announced 2024-06-30. Conversation templates, added 2024-04-25, work by putting a flag such as --conversation_template into the shell script you are already running, with Llama-3, Phi-3, and chatml preset.
Inference is three backends and the hosted demo is one GPU
Serving is split the same way. inference.py sits beside vllm_inference.py, which targets vllm>=0.8.0, and sglang_inference.py targets the sglang extra, which needs pybase64 alongside it because sglang.utils imports that package eagerly and without it the import raises ModuleNotFoundError. speculative_inference.py pairs with the speculative decoding guide under scripts/speculative_decoding/README.md, announced 2023-09-11, and tool_inference.py covers tool use. benchmarking.py and evaluation.py sit next to them for measurement. The hosted multimodal demo is the part with a stated ceiling: it runs on a single GPU, so when several users arrive at once you get queuing or application busy messages and you are told to wait and try again. Judge your own throughput from a vLLM or SGLang run on your hardware, and treat the public endpoint as a demonstration.
Memory and context tricks sit in side scripts, not in the default run
The headline numbers in the news list come from separate documents that the base finetune path does not pick up. LISA, added 2024-03-27, enables 7B training in 24G memory without offloading. Flash Attention-2 support from 2023-08-07 is explained in readme/flash_attn2.md and needs the flash-attn>=2.0.2 extra. Long context for LLaMA models through position interpolation, covering Linear and NTK scaling, sits in readme/Position_Interpolation.md. Speculative decoding has its own README under scripts/speculative_decoding/. Hymba support from 2024-12-02 lives under experimental/Hymba. The consequence for a reader skimming the announcements is that the 24G memory figure belongs to LISA, not to every finetune. You have to find each document, and the ones under experimental/ carry no stability promise.
Last commit 2026-08-10, newest tag from July 2025
The repository is not archived and the last push is dated 2026-08-10, so work is still landing. The release record tells a different story about cadence: v1.0.0 on 2025-07-11, v0.0.8 on 2024-06-19, v0.0.4 on 2023-08-09. That is roughly a year of commits past the newest tag, with the news list ending at the 2025-07-09 rewrite note, so a year of fixes exist only on main. Pin a commit hash rather than trusting a tag to be recent. The test setup has the same caveat: pytest collects tests/ and declares gpu, slow, and online markers, so a clean local run that skips marked tests tells you nothing about the training or vLLM paths. Lint coverage is uneven too, since the ruff configuration excludes the RAFT trainer and aligner along with chatbot_gradio.py:
[tool.ruff]
target-version = "py39"
line-length = 120
exclude = [
    "tests/utils/test_data_utils.py",
    "tests/pipeline/test_memory_safe_vllm_inferencer.py",
    "tests/models/test_hf_decoder_model.py",
    "src/lmflow/pipeline/utils/raft_trainer.py",
    "src/lmflow/pipeline/raft_aligner.py",
    "examples/chatbot_gradio.py",
]
Editorial conclusion
Use LMFlow when you want finetuning, DPO, RAFT, and vLLM or SGLang inference inside a single Apache-2.0 tree and you are willing to read the extras table before you install. Skip it if you need a tagged release to plan around, because the newest tag is v1.0.0 from 2025-07-11 while the last commit landed 2026-08-10, and pin datasets and cpm_kernels exactly before you let pip touch an existing environment.
Frequently asked questions
Is LMFlow part of Databricks?
No. LMFlow is OptimalScale's own finetuning and inference toolbox for large foundation models, released under the Apache-2.0 license.
Is LMFlow free to use?
The repository ships an Apache-2.0 LICENSE file, and setup.py publishes the package as lmflow with the description LMFlow: Large Model Flow. The 2023-06-07 news entry points at PyPI through pip install lmflow-finetune.
What is better than LMFlow?
No document in the repository compares LMFlow against another finetuning toolkit. What it does point to is a backend choice: examples/ carries vllm_inference.py, sglang_inference.py, and inference.py side by side, while setup.py keeps vllm, sglang, ray, and deepspeed in extras instead of the base requirements.
How much does LMFlow cost?
LMFlow is released under the Apache-2.0 license. What it does fix is the software bill: requirements.txt pins datasets==3.6.0, cpm_kernels==1.0.11, and evaluate==0.4.0 exactly, and the extras add vllm>=0.8.0, trl>=0.11,<0.12, deepspeed>=0.14.4, flash-attn>=2.0.2, and ray>=2.22.0 on top of the base list.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/optimalscale-lmflow)Star history chart for your README
[](https://hysenlabs.com/projects/optimalscale-lmflow)Was this useful?