optuna-examples indexes 21 machine learning frameworks, and six directories in its own tree are not on the index
Examples for https://github.com/optuna/optuna
At a glance
- What is it?
- A repository that is one long index of example scripts for the Optuna hyperparameter tuner, organised by problem setup rather than by API. Three of the listed examples are not scripts in the repository at all, the pruning section mostly repeats files already listed above it, and the root dependency file serves a single notebook.
- Who is it for?
- Start here if you want to see Optuna applied to a library you already use, because the framework coverage is the value and most of these files are short enough to read in one sitting. Three things to know before you pick one.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
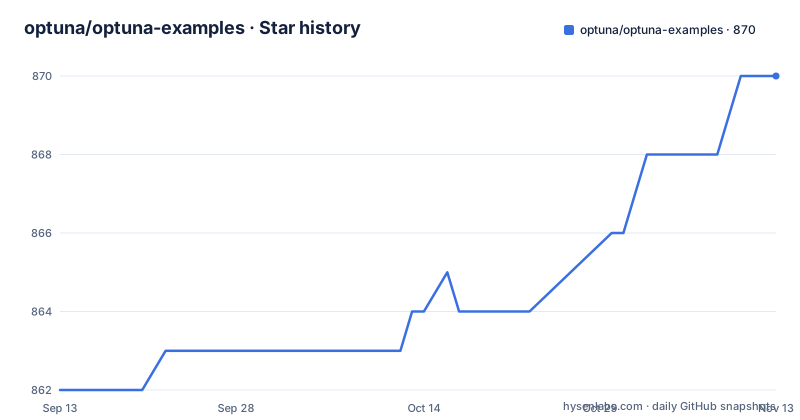
- optuna/optuna-examples870 ★ · +8
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| optuna/optuna-examples | 862 | 870 |
8 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first example sets two termination criteria in one call
The page opens with the smallest complete program, and it contains more teaching than it appears to.
import optuna

def objective(trial):
    x = trial.suggest_float("x", -100, 100)
    return x ** 2

if __name__ == "__main__":
    study = optuna.create_study()
    # The optimization finishes after evaluating 1000 times or 3 seconds.
    study.optimize(objective, n_trials=1000, timeout=3)
    print(f"Best params is {study.best_params} with value {study.best_value}")
The objective is a quadratic with a single float parameter over a symmetric range, which means the search is trivially unimodal and the result is predictable. That is the point: nothing here depends on the objective being hard.
The detail worth noticing is that `optimize` receives both `n_trials=1000` and `timeout=3`. The comment states the finish condition as evaluating a thousand times or three seconds, whichever comes first, so the very first thing a reader sees is two independent stop conditions on one call.
And the callout immediately under it acknowledges that two is not always enough. Three examples are offered for cases the first one does not cover: an objective function with additional arguments, for when you need to pass something besides the trial object; manually providing trials with a sampler, for forcing particular parameter values to be sampled; and a callback to control the termination criterion, described as being for when you want a criterion other than `n_trials` or `timeout`.
So the page teaches the two-criteria case and then immediately points at the three-criteria case. The first example is a summary of the API, not just a starting point.
Six directories in the tree have no entry on the page
The machine learning section is the largest one, with twenty one entries, and it is where the shape of the repository becomes clear. Each framework has its own directory and its own file.
The list runs from Catalyst, CatBoost, Dask-ML and FastAI through Haiku, Keras, LightGBM and the LightGBM Tuner, then PyTorch in five variants including Ignite, Lightning and a distributed data parallel version, then RAPIDS, Scikit-learn, a Scikit-learn OptunaSearchCV variant, Scikit-image, SKORCH, Hugging Face Transformers, Tensorflow in both estimator and eager forms, and XGBoost. Reinforcement learning sits outside the section with a single entry for a Stable-Baselines agent.
Now compare that with the top-level directories. Alongside the ones the page names there are `comet/`, `openml/`, `pruners/`, `spark/`, `tensorboard/` and `tfkeras/`, and none of the six has an entry in any category on the page.
That is the practical warning. The page is an index, not a manifest, and six directories exist in the tree that a reader working from the page alone would never find. `pruners/` is the most confusing of them, because there is a Pruning section on the page whose examples all live elsewhere. If you are looking for the pruning examples, searching the tree will show you both.
The non-ML categories are much smaller by comparison. Basic black-box optimisation has three files, multi-objective has two, samplers has two, terminator has two, and the MLOps platform section has one file each for an experiment tracker and a configuration framework.
The pruning section mostly lists files the page already showed you
Pruning is the only feature that gets two entries in this repository, and the second one is a different kind of thing.
The first is a hand-written example, described as demonstrating how to implement pruning logic with Optuna, and it uses scikit-learn. That is the file to read if you want to understand what pruning is, because it is the only one written by hand.
The second group is integration modules, described as being available for a list of libraries and providing simpler interfaces to use pruning. The list has twelve entries. Catalyst, CatBoost, FastAI, PyTorch, PyTorch Ignite, PyTorch Lightning and its distributed data parallel variant, and Tensorflow all point at files that already appeared in the machine learning list one section above, so the same nine files are listed twice under two headings.
The files that are genuinely specific to pruning are a smaller set: a dedicated Keras integration file, a dedicated LightGBM integration file, a Tensorflow estimator integration file, and two XGBoost integration files, one of which is the cross validation version. Those four directories are where the feature lives, and the other entries are pointers to the same scripts.
The duplication is not a mistake so much as two different questions. The machine learning section answers which framework do I use, and the pruning section answers which framework has a pruning integration. Those are different answers and they are not the same list, which is why the overlap is large but not complete.
Three of the listed examples are not Python files in this repository
The page describes itself as a list of example codeblocks, and a few of them are neither a script nor local.
The visualisation section has two entries and both are Colab notebooks rather than files you run. One opens the notebook for visualising a study, the other opens a notebook for visualising a study with HiPlot. Both are hosted notebooks that fetch the notebook out of this repository's branch and run it in the browser, so they need no local environment at all.
The distributed section has a similar exception. Alongside the Dask script and the Ray joblib backend, optimising on Kubernetes is a link to a README, not to a script. So of the three distributed backends, one is a Python file, one is a Python file, and one is a set of instructions.
That pattern is worth noticing because it tells you what kind of material this repository actually holds. The vast majority is a flat directory of short single-file scripts, one per framework, each doing one thing: build an objective, wrap a training call, hand the result to the study. The exceptions are the cases where a working example needs a cluster, a browser or a set of deployment steps, and there the page links out.
A related note sits near the top, pointing at a separate repository for the Optuna Dashboard and at a single local file, `./dashboard/run_server_simple.py`, described as a quick start using in-memory storage. In-memory storage is the point of that example: it is there so you can see the dashboard appear without setting up a database first.
The root requirements file serves one notebook and does not depend on Optuna
The dependency situation in this repository is unusual, and it is worth understanding before you copy an example.
The root requirements file has three entries and a comment explaining its scope.
# Used in quickstart.ipynb
jupyter
plotly
scikit-learn
So the entire declared dependency set exists to run a single notebook, `quickstart.ipynb`, which is itself at the repository root. Everything else, all twenty one machine learning examples plus the framework-specific pruning integrations, requires a library that no manifest here installs.
Optuna itself is not in the list either. That is correct for this repository, which is a set of examples for the library rather than a package that depends on it, and it means the assumption is that you already have Optuna installed in whatever environment you are working in.
The other configuration file reinforces that this is not a distributable project. The `pyproject.toml` has no project table at all; it contains two tool sections and nothing else.
[tool.black]
line-length = 99
target-version = ['py37']
with an exclusion regex listing the usual build and virtual environment directories, and an isort section using the black profile with a line length of 99, `force_single_line`, `force_sort_within_sections` and `order_by_type` off. A `setup.cfg` sits alongside it, and a pre-commit configuration is committed at the root.
The formatting target of `py37` is the detail that ages fastest. It is a target for the formatter, not a runtime requirement, and it says the style baseline was set years ago and left alone, which is consistent with a repository that changes when the ecosystem requires it rather than on a schedule.
Distributed means Dask, Kubernetes instructions, and Ray's joblib backend
Three backends, three shapes of example, and one of them is a different framework wearing the same name.
The Dask entry optimises on a Dask cluster from a Python file, and the Ray entry uses Ray's joblib backend, so that one is about running an already-parallel workload under Ray rather than about Optuna having a Ray scheduler. The joblib backend is a specific integration point: the point is that the objective becomes a joblib task and Ray executes it.
Kubernetes has no script here at all. That entry is a README, which means the material for a cluster deployment lives as prose, and it is a reasonable choice, since a Kubernetes example is mostly manifests and a description of how the workers are addressed.
The two feature sections next to it are the ones that change how you structure a study rather than where it runs. Under samplers there is a warm starting CMA-ES example, which is about seeding one covariance matrix adaptation run from the previous study's state, and a simulated annealing sampler written as a user-defined sampler, which is the example to copy when the built-in search spaces do not fit your problem. Under terminator there are two entries, the terminator on its own and the terminator combined with OptunaSearchCV.
The MLOps section adds an experiment tracker integration and a Hydra configuration example. Both are the kind of thing that shows you the seam between Optuna and a tool you already run, which is where the practical value of this page usually is.
The external projects list is where the repository stops being the subject
The final section is not examples at all. It is a list of other projects that use Optuna, and it is the longest link list on the page.
The entries include the Hugging Face Trainer's hyperparameter search, Allegro Trains, a crystal structure refinement project built on Bayesian optimisation, Catalyst, CuPy, Hydra's Optuna sweeper plugin, Mozilla's speech recognition work, the neptune.ai experiment tracker, a scikit-learn compatible LightGBM estimator built around Optuna, a distributed Optuna implementation, the PyKEEN knowledge graph library, and a reinforcement learning baselines collection.
Two things are notable about that list. The first is that several of the entries are libraries also present as local examples, Catalyst and Hydra among them, which tells you the local example and the external integration are maintained by different people in different places. The second is the mix of domains: speech recognition, crystallography, knowledge graphs, reinforcement learning and GPU array programming, none of which is what the machine learning section of the page suggests you should expect.
The list then stops partway through its last entry, on a link whose text begins with the words Hyperparameter Optimization and then ends, so the final project on that list is not identified in full.
After that the page is finished. There is no contributing or support section visible in what is written, although a contributing document and a pre-commit configuration are both committed at the root, and there are no GitHub releases. The last push to the default branch is recorded as 2026-09-29.
Editorial conclusion
Start here if you want to see Optuna applied to a library you already use, because the framework coverage is the value and most of these files are short enough to read in one sitting. Three things to know before you pick one. Nothing here is installed for you: the root requirements file serves a single notebook and does not even depend on Optuna, so each framework example needs its own library. Not every directory in the tree appears in the index, so search the repository rather than trusting the page as a complete list. And the examples that show a feature rather than a framework, the custom terminator, the enqueued trial and the additional argument pattern, are the ones most likely to change how you structure real code, which is why they are the ones the page puts in a callout.
Frequently asked questions
What is the smallest complete Optuna example?
It creates a study, then calls `study.optimize(objective, n_trials=1000, timeout=3)` on an objective that suggests one float between minus one hundred and one hundred. That call sets two independent stop conditions, finishing on whichever of a thousand evaluations or three seconds arrives first.
Which machine learning frameworks does optuna-examples cover?
Twenty one entries covering Catalyst, CatBoost, Dask-ML, FastAI, Haiku, Keras, LightGBM and the LightGBM Tuner, PyTorch with Ignite, Lightning and a distributed data parallel variant, RAPIDS, Scikit-learn, Scikit-learn OptunaSearchCV, Scikit-image, SKORCH, Hugging Face Transformers, Tensorflow in estimator and eager forms, and XGBoost. Reinforcement learning is a separate entry for a Stable-Baselines agent.
How do I learn Optuna pruning from optuna-examples?
The hand-written example is `./basic/pruning.py`, described as showing how to implement pruning logic with Optuna using scikit-learn. The rest of the pruning section lists framework integration modules, most of which point at the same files already listed under the machine learning section.
Can I run the optuna-examples in a browser?
Two of the listed examples are Colab notebooks that run remotely rather than scripts in the repository: one for visualising a study and one for visualising a study with HiPlot. There is also a dashboard quick start file using in-memory storage, so no database setup is needed to see the dashboard.
What does the requirements.txt in optuna-examples install?
Three packages, and the comment in the file says they are used in the root `quickstart.ipynb`: jupyter, plotly and scikit-learn. Optuna itself is not listed, and the twenty one framework examples need their own libraries, which no manifest here installs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/optuna-optuna-examples)Star history chart for your README
[](https://hysenlabs.com/projects/optuna-optuna-examples)Was this useful?