LLM Engineer's Handbook: what the repository pins and what it leaves open
The LLM's practical guide: From the fundamentals to deploying advanced LLM and RAG apps to AWS using LLMOps best practices
At a glance
- What is it?
- The official repository of the Packt book by Paul Iusztin and Maxime Labonne ships a ZenML pipeline, a RAG app, AWS deployment code and one disabled ETL task. Reading pyproject.toml and docker-compose.yml tells you more about running it than the README does.
- Who is it for?
- Work through this repository if you want the book's pipeline shape in your own codebase and you are prepared to own the version drift: torch is pinned at 2.2.2, zenml at 0.74.0, and the dev group with pytest is left out of the container image. Do not expect versioned releases: the repository publishes none, and its last push was on 2026-04-22.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
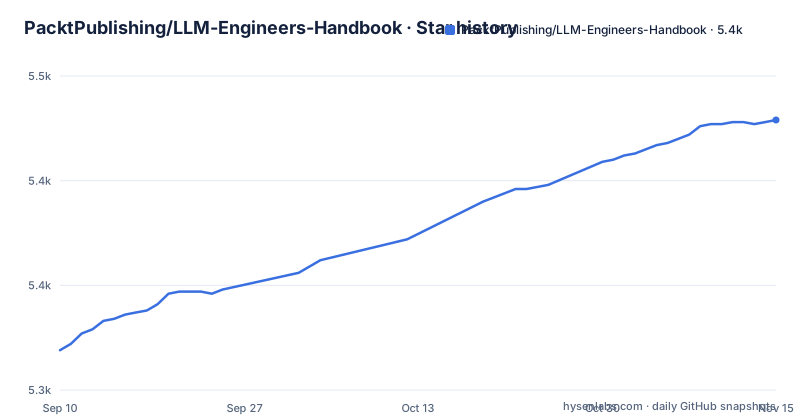
- PacktPublishing/LLM-Engineers-Handbook5,429 ★ · +110
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| PacktPublishing/LLM-Engineers-Handbook | 5.3k | 5.4k |
110 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Clone, then pin Python 3.11.8 through pyenv
Two commands put the repository on disk, and everything after them depends on which Python answers.
git clone https://github.com/PacktPublishing/LLM-Engineers-Handbook.git
cd LLM-Engineers-Handbook
Python 3.11 is required, and the README offers two routes. Option A checks a global interpreter with python --version and expects 3.11.x. Option B goes through pyenv, which is the recommended one: confirm pyenv --version reports 2.3.36 or later, then install the exact interpreter.
pyenv install 3.11.8A .python-version file in the repository root records the pin, so pyenv applies it as soon as you enter the directory. The rest of the toolchain is stated as ranges rather than left open: Poetry between 1.8.3 and 2.0, Docker at 27.1.1 or newer, AWS CLI at 2.15.42 or newer, Git at 2.44.0 or newer, with pyenv itself marked optional. Take the pyenv route unless your global interpreter is already 3.11, because pyproject.toml asks for python = "~3.11" and the Poetry resolver will refuse anything else. When an install does break, the README sends you to the repository's Issues page to look for someone who hit the same wall, which tells you where to look but not that the setup path is scripted.
compose publishes Mongo and Qdrant with the credentials in the repository
Two services do the storage work, and docker-compose.yml starts both of them on host ports.
  mongo:
    image: mongo:latest
    container_name: "llm_engineering_mongo"
    environment:
      MONGO_INITDB_ROOT_USERNAME: "llm_engineering"
      MONGO_INITDB_ROOT_PASSWORD: "llm_engineering"
    ports:
      - 27017:27017
  qdrant:
    image: qdrant/qdrant:latest
    ports:
      - 6333:6333
      - 6334:6334
Both volumes are named, mongo_data and qdrant_data, so tearing the stack down keeps your embeddings and your crawled documents on disk. That also means the data outlives the containers, and the containers are the easy half to throw away. Both images track :latest, both sit on a bridge network called local, and both carry restart: always. The published ports are the part to notice, since 27017, 6333 and 6334 are reachable from any process on the machine while compose runs. The credentials are the second part: the pair llm_engineering repeated twice is committed to the repository and repeated in .env.example, which is harmless on a laptop and wrong on a shared host or a VM. Change the pair and the matching DATABASE_HOST before either service is exposed anywhere.
.env.example ships placeholder keys and one fixed AWS region
Every credential the code reads has a named slot in .env.example, and the defaults are placeholders rather than working values.
OPENAI_MODEL_ID=gpt-4o-mini
OPENAI_API_KEY=str
HUGGINGFACE_ACCESS_TOKEN=str
COMET_API_KEY=str
USE_QDRANT_CLOUD=false
AWS_REGION=eu-central-1
Three defaults are already decided for you here. The model id is gpt-4o-mini, so every example runs on a small model and changing that is a config edit rather than a code edit. USE_QDRANT_CLOUD is false, which keeps the vector store in the local compose file instead of a hosted cluster. AWS_REGION is eu-central-1, so objects and logs land in Frankfurt unless you change it. AWS credentials are split into AWS_ARN_ROLE, AWS_ACCESS_KEY and AWS_SECRET_KEY, matching the aws dependency group that brings sagemaker, s3fs, kubernetes and the Hugging Face inference toolkit.
tools/run.py is the entry point, and one ETL task prints a refusal
Work reaches the pipeline through a single module, and the task list in pyproject.toml shows exactly how.
run-digital-data-etl-maxime = "poetry run python -m tools.run --run-etl --no-cache --etl-config-filename digital_data_etl_maxime_labonne.yaml"
run-digital-data-etl-alex = "echo 'It is not supported anymore.'"
Read that second line twice. One ETL variant is not a stub waiting for you to finish it, it is a command that prints a sentence and exits, so any walkthrough pointing at that data source stops there. The four scripts under tools/ divide the labour: run.py starts ZenML pipelines, ml_service.py brings up the REST inference server, rag.py exercises the retrieval module, and data_warehouse.py moves MongoDB data in and out through JSON files. Inside llm_engineering the import direction runs infrastructure, then model, then application, then domain, which keeps FastAPI, Qdrant and MongoDB out of the business logic but also means the domain layer has to be written before anything renders. Around those scripts sit the definitions: pipelines/ holds the ZenML pipelines that act as the entry point for all ML work and coordinate the data processing and model training stages, steps/ holds reusable components for tasks such as data loading and preprocessing, configs/ holds the YAML files that control how pipelines and steps execute, and code_snippets/ keeps examples that run outside the package entirely.
The image installs a browser before Poetry, and skips the dev group
The Dockerfile starts from python:3.11-slim-bullseye and grows a browser before it grows a dependency set. A Chrome package is added from its own apt repository, followed by build-essential, gcc, python3-dev, libglib2.0-dev and libnss3-dev. The browser is not decoration here, because data collection uses selenium with chromedriver-autoinstaller and a headless browser is what lets those crawlers run at all.
ENV POETRY_VERSION=1.8.3
RUN pip install --no-cache-dir "poetry==$POETRY_VERSION"
RUN poetry config installer.max-workers 20
Poetry arrives by version from an environment variable, virtualenvs are disabled inside the image, and dependencies are installed from the copied lock file with --no-root. The --without dev flag is the part that bites anyone testing in a container: ruff, pre-commit and pytest sit in the dev group, so the release image carries no test runner and no linter. A build that passes in Docker and fails on your machine is often that difference rather than your code. The layer order is worth noting as well: WORKSPACE_ROOT is /app/, the lock file and pyproject.toml are copied and installed before the source tree, and the rest of the code lands last. Edit a Python file and only that layer rebuilds; edit pyproject.toml and the whole dependency set reinstalls, torch included.
tests/ holds worked examples, not a regression suite
The README describes the test directory as a few sample tests written as examples and used by the CI pipeline. The wiring is GitHub Actions in the .github directory, with those samples running under it as a demonstration of the format rather than as a gate on pipeline behaviour. The consequence is concrete. If you fork this to run your own ETL config or change the embedding model, nothing tells you that an edit to a step in steps/ still emits the same artifact shape, and your feedback loop is running the pipeline and reading the output. A .pre-commit-config.yaml and ruff.toml exist in the root, so formatting drift gets caught automatically while behaviour drift does not. The setup knowledge lives in the book rather than in the repository: Chapter 2 is where each tool gets walked through and Chapters 10 and 11 hold the step by step guides, which means reading this code tells you the shape of the system and the exact dependency set, while which values belong in the AWS role or how the ZenML server should be reached in your own environment stays in the chapters.
Exact pins for torch and ZenML, and one public model
The dependency set is pinned tightly enough that its age matters. torch is 2.2.2 exactly and zenml is 0.74.0 with the server extra, while langchain sits at ^0.2.11, langchain-community at ^0.2.11, langchain-openai at ^0.1.3 and opik early at ^0.2.2. A caret range floats forward, so poetry.lock is the file that actually decides what you run. Keep it and your runs reproduce; regenerate it and the same commands give you a different stack each month. The last push to main was on 2026-04-22 and the repository publishes no releases at all, so a commit hash is the only version marker you can point at. The README also warns that code here can move ahead of the printed book, and points the other direction for the trained artifact: a final model is published on Hugging Face as mlabonne/TwinLlama-3.1-8B-DPO. The repository is MIT; the book itself is a separate purchase from Packt or Amazon.
Editorial conclusion
Work through this repository if you want the book's pipeline shape in your own codebase and you are prepared to own the version drift: torch is pinned at 2.2.2, zenml at 0.74.0, and the dev group with pytest is left out of the container image. Do not expect versioned releases: the repository publishes none, and its last push was on 2026-04-22. Before starting, open poetry.lock and check that the pinned zenml and langchain versions still install on your machine, then replace the committed Mongo credentials in docker-compose.yml before that host leaves localhost.
Frequently asked questions
Is there a PDF version of the LLM Engineer's Handbook available?
The repository links the book on Amazon and on Packt, and it identifies itself as the official code repository for the title by Paul Iusztin and Maxime Labonne. The README points to Amazon and Packt as the places to find the book.
What does the LLM Engineer's Handbook repository contain?
ZenML pipelines under pipelines/ and steps/, a domain layered Python package under llm_engineering/, four utility scripts in tools/ (run.py, ml_service.py, rag.py, data_warehouse.py), YAML pipeline configs, sample tests, plus a Dockerfile and docker-compose.yml for MongoDB and Qdrant.
Which model does the LLM Engineer's Handbook produce?
A final trained model is published on Hugging Face as mlabonne/TwinLlama-3.1-8B-DPO. The project itself covers data collection and generation, an LLM training pipeline, a simple RAG system, AWS deployment, monitoring and a testing and evaluation framework.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/packtpublishing-llm-engineers-handbook)Star history chart for your README
[](https://hysenlabs.com/projects/packtpublishing-llm-engineers-handbook)Was this useful?