ERNIE: ten model variants, four accelerator test suites, one dated toolkit line
The official repository for ERNIE 4.5 and ERNIEKit – its industrial-grade development toolkit based on PaddlePaddle.
At a glance
- What is it?
- The ERNIE repository holds the open weights for the ERNIE 4.5 family and ERNIEKit, the toolkit for training them. The model table is the clearest part: eight mixture-of-experts variants with either 47B or 3B active parameters plus a 0.3B dense model, split into language, vision-language and dense categories. The rest is a training stack whose release notes stop at v1.5 in November 2025.
- Who is it for?
- ERNIE suits a research team that wants Apache 2.0 weights for a mixture-of-experts language or vision-language model, with a toolkit that supports SFT and LoRA on the same framework the models were trained on. It does not suit you if you train on a different framework, because ERNIEKit is built on PaddlePaddle and the install target is a PaddlePaddle GPU wheel, and it does not suit you if you need a toolkit release newer than v1.5.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 113 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
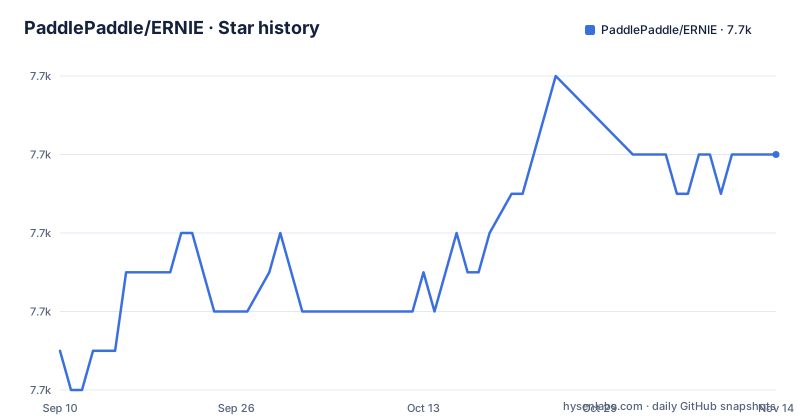
- PaddlePaddle/ERNIE7,740 ★ · +5
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| PaddlePaddle/ERNIE | 7.7k | 7.7k |
5 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eight of the ten models are mixture-of-experts with 47B or 3B active
The introduction describes ERNIE 4.5 as a new family of large-scale multimodal models comprising 10 distinct variants.
They are mixture-of-experts models with 47B and 3B active parameters, the largest having 424B total parameters, plus a 0.3B dense model. So the count splits three ways: language models, vision-language models, and a dense pair.
The architecture note is the part with a design decision in it. For the MoE structure they propose a novel heterogeneous modality arrangement, which supports parameter sharing across modalities while also allowing dedicated parameters for each individual modality. The stated advantage is to enhance multimodal understanding without compromising, and even improving, performance on text-related tasks.
That is the claim to check against your own workload. A shared expert pool with per-modality specialists means a multimodal model does not have to give up text quality, which is the usual trade-off, and the README reports the largest language model pre-training reached 47% Model FLOPs Utilization.
All models are publicly accessible under Apache 2.0, including pre-trained weights and inference code.
The model table is organised by category, modality and context
The README's table has five columns and the grouping is what makes ten variants legible.
Large Language Models, text in, text out: ERNIE-4.5-300B-A47B-Base, ERNIE-4.5-300B-A47B, ERNIE-4.5-21B-A3B-Base and ERNIE-4.5-21B-A3B.
Vision-Language Models, text, image and video in, text out: ERNIE-4.5-VL-424B-A47B-Base, ERNIE-4.5-VL-424B-A47B, ERNIE-4.5-VL-28B-A3B-Base and ERNIE-4.5-VL-28B-A3B.
Dense Models, text in, text out: ERNIE-4.5-0.3B-Base and ERNIE-4.5-0.3B.
All ten variants, MoE and dense, share a 128K context window.
Two patterns are worth naming. Every size comes as a Base and a non-Base pair, which is the base pretraining checkpoint and the instruction-tuned counterpart. And the naming encodes the shape: 300B-A47B means 300B total with 47B active, 21B-A3B means 21B total with 3B active, so the second number is what you pay at inference time.
That is the number that decides whether the model fits your serving budget, and it is the one people miss when they read only the first.
ERNIEKit versions add one model family at a time
The recent updates section is a version history where each entry adds a specific capability, and the pattern is worth reading as a roadmap.
v1.0 in June 2025 is announced as the toolkit for developing with the latest ERNIE models. v1.1 in September adds SFT and LoRA support for the ERNIE-4.5-VL series.
v1.2 in September adds a WebUI for training and conversation with the ERNIE 28b and 424b VL models, query-response format support in training data, and command-line tool support for Iluvatar GPU hardware. Its bug fixes are named with issue numbers: a pipeline-parallel plus recompute plus mixture-of-experts bug, a checkpoint save bug, and a LoRA 128k training bug.
v1.3 in September adds SFT and function call training for ERNIE-4.5-21B-A3B-Thinking, and a speed optimisation for multimodal video data processing.
v1.4 in October adds SFT for PaddleOCR-VL-0.9B, and a padding-free dataflow strategy that packs data within a batch into one sequence to avoid padding, reducing GPU memory use and speeding up training.
v1.5 in November adds SFT and function call training for ERNIE-4.5-VL-28B-A3B-Thinking.
So the toolkit arrived after the weights, one model family per release. If you need a specific variant trained, the version that supports it is named in this list.
The install target is a PaddlePaddle GPU wheel and a FastDeploy wheel
The Makefile is where the framework choice becomes concrete, and it runs pip installs for two prebuilt wheels, the GPU requirements, pytest and allure-pytest before the local package.
install:
	pip uninstall paddlepaddle-gpu -y
	pip install https://paddle-qa.bj.bcebos.com/paddle-pipeline/Release-TagBuild-Training-Linux-Gpu-Cuda12.6-Cudnn9.5-Trt10.5-Mkl-Avx-Gcc11-SelfBuiltPypiUse/latest/paddlepaddle_gpu-0.0.0-cp310-cp310-linux_x86_64.whl
	pip install https://paddle-qa.bj.bcebos.com/paddle-pipeline/FastDeploy_ActionCE/SM80_90/release/2.2/latest/fastdeploy_gpu-0.0.0-py3-none-any.whl
	pip install -r requirements/gpu/requirements.txt
Three things follow from those lines. The framework is PaddlePaddle, installed as a purpose-built GPU wheel for CUDA 12.6, cuDNN 9.5, TensorRT 10.5, MKL and AVX, built for GCC 11, and it is a CPython 3.10 Linux x86_64 wheel. Inference goes through FastDeploy, pinned to a 2.2 release for SM80 and SM90 hardware.
That is a narrow install target stated honestly. It is a specific Python version, a specific Linux architecture, a specific CUDA stack, and a prebuilt wheel hosted on paddle-qa.bj.bcebos.com rather than on PyPI.
The install also uninstalls paddlepaddle-gpu first, so the wheel replaces rather than merges, and then installs the project itself with `pip install -e.`
Four accelerator suites, and lint runs only on changed files
The test targets are the clearest statement of what hardware the project supports.
`gpu_ci_test` runs pytest against `tests/gpu/`, `xpu_ci_test` against `tests/xpu/`, and `npu_ci_test` against `tests/npu/`, each writing an Allure report into `result` with the repository root on `PYTHONPATH`. The pyproject test paths list a fourth: `tests/iluvatar_gpu/`.
So four accelerators: GPU, XPU, NPU and Iluvatar GPU, and the Iluvatar one appears in the pytest configuration rather than in the Makefile, which means it is collected but has no dedicated make target.
The lint target is more clever than it looks. It shells out to `python tools/codestyle/get_modified_files.py` over a list of directories, and if any Python files were modified it runs pre-commit on exactly those files, printing the file list first. If nothing changed it prints that no library .py files were modified and does nothing.
So linting costs nothing on a clean tree, and the default target runs lint plus the GPU and XPU suites rather than all four.
Version comes from a file in the package, not from the manifest
`setup.py` reads its version out of the package instead of hardcoding it, and the mechanism is a regex over erniekit/version/env.py.
The requirements are read from `requirements/gpu/requirements.txt` through a helper that reads the file whole, and the version is extracted from `erniekit/version/env.py` with the pattern `{}` `\W*=\W*` `"([^"]+)"` applied to a `VERSION` line.
The console script is a single entry point, `erniekit = erniekit.cli:main`, collected into a list before setup runs.
Two observations. The package name in setup is `erniekit` while the repository is ERNIE, so the toolkit and the models are distributed under different names, and the version lives in a module inside the package rather than in the packaging metadata, which means the environment file is the single source of truth and has to be kept in step with the toolkit releases named in the updates section.
The repository root follows the same split: `ernie/` for the models, `erniekit/` for the toolkit, plus `cookbook/`, `data_processor/`, `docker/`, `docs/`, `examples/`, `requirements/`, `tests/` and `tools/`.
Deployment is a different repository, and the default branch is release/v1.5
The link row at the top of the README points deployment at a separate repository, FastDeploy, described as the deploy target with its own badge.
So inference is not ERNIEKit's job. ERNIEKit trains, FastDeploy serves, and the Makefile installs both for local work.
The default branch for this repository is `release/v1.5`, which matches the newest toolkit release named in the updates section, dated November 2025. That branch choice is the practical consequence of the versioning pattern: the repository tracks a toolkit line, and the branch tells you which one.
There is one published release for the models themselves, `ernie-4.5`, tagged ERNIE 4.5 Open-source on 2025-06-30, and the last push to the default branch was on 2026-07-24.
The rest of the surface is documentation and examples: a blog link for ERNIE 4.5, a cookbook directory, a papers link, a training document at `docs/erniekit.md`, the ERNIE Bot site, a Hugging Face organisation under baidu, and AI Studio. The examples directory splits into auto_parallel, configs, data, pre-training and scripts.
Editorial conclusion
ERNIE suits a research team that wants Apache 2.0 weights for a mixture-of-experts language or vision-language model, with a toolkit that supports SFT and LoRA on the same framework the models were trained on. It does not suit you if you train on a different framework, because ERNIEKit is built on PaddlePaddle and the install target is a PaddlePaddle GPU wheel, and it does not suit you if you need a toolkit release newer than v1.5. Verify three things before you start: which of the ten variants fits your hardware, since the largest is 424B total parameters, whether your accelerator is one of the four the test suites cover, GPU, XPU, NPU or Iluvatar GPU, and which ERNIEKit version you need, because the per-model training support arrives version by version.
Frequently asked questions
What is ERNIE?
It is the official repository for ERNIE 4.5 and ERNIEKit. ERNIE 4.5 is a family of ten large-scale multimodal models comprising eight mixture-of-experts models with 47B or 3B active parameters, the largest having 424B total parameters, and a 0.3B dense model. All models including pre-trained weights and inference code are publicly accessible under Apache 2.0. ERNIEKit is the development toolkit built on PaddlePaddle.
Which ERNIE 4.5 models are available?
Ten variants under a 128K context window. Language models with text in and text out are ERNIE-4.5-300B-A47B-Base, ERNIE-4.5-300B-A47B, ERNIE-4.5-21B-A3B-Base and ERNIE-4.5-21B-A3B. Vision-language models taking text, image and video and returning text are ERNIE-4.5-VL-424B-A47B-Base, ERNIE-4.5-VL-424B-A47B, ERNIE-4.5-VL-28B-A3B-Base and ERNIE-4.5-VL-28B-A3B. The dense pair is ERNIE-4.5-0.3B-Base and ERNIE-4.5-0.3B.
How do I train an ERNIE 4.5 model with ERNIEKit?
ERNIEKit is installed from the repository, whose Makefile installs a PaddlePaddle GPU wheel for CUDA 12.6 and cuDNN 9.5 and a FastDeploy 2.2 wheel before installing the project in editable mode. Training support arrives by version: v1.1 added SFT and LoRA for the ERNIE-4.5-VL series, v1.3 added SFT and function call training for ERNIE-4.5-21B-A3B-Thinking, v1.4 added SFT for PaddleOCR-VL-0.9B and a padding-free dataflow strategy, and v1.5 added SFT and function call training for ERNIE-4.5-VL-28B-A3B-Thinking.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-ernie)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-ernie)Was this useful?