Paddle Lite: the opt tool, the kernel split, and the gaps in the CI matrix
PaddlePaddle's high-performance deep learning inference engine for mobile and edge devices.
At a glance
- What is it?
- Paddle Lite loads only models saved by PaddlePaddle's save_inference_model, rewrites them with the opt tool, and splits its runtime into a graph analysis stage and a deployable kernel stage. The README's quick start gives no install command, and the newest tag in its release feed is v2.14-rc from 2024-07-19.
- Who is it for?
- Pick Paddle Lite when your models are trained in PaddlePaddle and your target is a phone, an embedded board, or a vendor NPU that appears in the CI table. You get an opt tool, three language APIs, and a runtime you can trim down to kernels alone.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
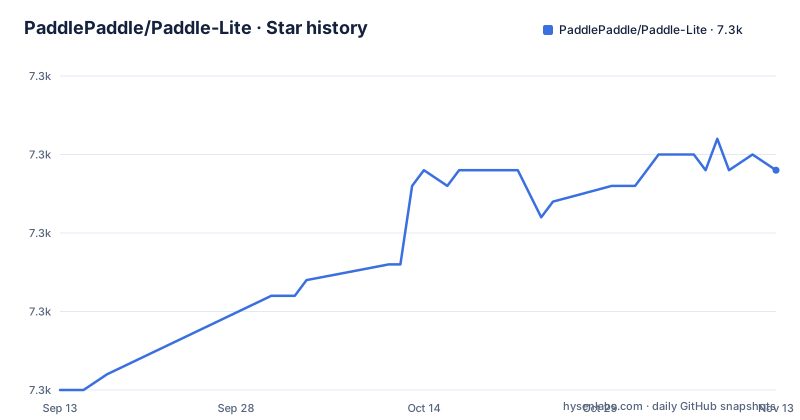
- PaddlePaddle/Paddle-Lite7,289 ★ · +14
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| PaddlePaddle/Paddle-Lite | 7.3k | 7.3k |
14 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Only models from save_inference_model will load
Paddle Lite reads exactly one model format: the PaddlePaddle inference model written by the save_inference_model API. There is no importer inside the runtime for a Caffe graph, a TensorFlow saved model, or a PyTorch export, and nothing in the repository converts one for you. If the weights came out of Caffe, TensorFlow or PyTorch, the README sends you to a separate project, X2Paddle, and the conversion has to happen before Paddle Lite ever opens the file.
That boundary decides who this engine fits. A team already training in PaddlePaddle can hand a saved inference model straight to the opt tool. A team with a PyTorch pipeline inherits a conversion step it has to maintain, and checking that a converted graph still behaves like the original belongs to you. Treat X2Paddle as part of your build rather than as an optional convenience, because a silent rewrite inside the converted graph is the kind of defect that surfaces as a wrong answer on device and nowhere else.
The opt tool rewrites the graph before a kernel ever runs
Handing a Paddle model straight to Paddle Lite without the opt step is the unusual path. The opt tool applies three families of change: quantization, subgraph fusion, and kernel selection. Fusion merges operators so fewer kernel launches cross the boundary between them. Kernel selection picks the implementation that matches the hardware list you compiled against.
The same tool prints the operators it found inside the model and reports how much of that model a given hardware platform can actually run. That makes it the first thing to run in a new project, and the fastest way to learn that an operator your graph depends on is not supported on the device in your hand.
Two quantization paths are documented separately, static offline and dynamic offline, on pages of their own. So the decision is which one your accuracy budget tolerates, not which toggle is shorter to type.
Analysis Phase and Execution Phase deploy as two pieces
The architecture divides into an Analysis Phase and an Execution Phase, and the divide is a deployment decision rather than a diagram convention.
The Analysis Phase holds the MIR (Machine IR) modules, which operate on the model's compute graph and rewrite it against a specific hardware list through operator fusion and computation pruning.
The Execution Phase touches kernel execution and nothing else. Because it does not depend on the graph rewriting stage, it can be deployed on its own, which is the route to the very small footprint builds that mobile apps need. A team shipping a pre-optimized model has a real reason to carry only the execution half and leave the analysis tools out of the shipped binary. A team that still tunes per device has to carry the analysis stage too, and that stage is where the hardware lists, the fusion decisions and the pruning rules live.
Prebuilt libraries stop at Android, iOS, x86 and macOS
There are three routes to a working binary, and each one charges differently.
The cheapest is a prebuilt release library. Official downloads cover Android, iOS, x86 and macOS, and the project tells you to take the precompiled library from the release page first, with the latest precompiled build in the release feed as the alternative. That route fixes your toolchain for you and gives up your ability to target anything outside that list.
The second route is the Docker unified build environment, recommended specifically to dodge the tedious work of assembling a native toolchain by hand. The third is manual: match the host and target CPU architecture and operating system yourself, then follow the source compile guide.
Notice the gap in the first route as well. The feature list names embedded Linux and Windows among the supported platforms, but the README names prebuilt libraries only for Android, iOS, x86 and macOS, so check the release page before planning a source build for those targets.
The CI matrix is the honest map of what gets built
The continuous integration matrix in the README is the most informative table in the file, because it is the only place the hardware story is stated per platform.
Four build targets run across the top: x86 Linux, ARM Linux, Android with GCC or Clang, and iOS. Sixteen backends run down the side, from 32 and 64 bit CPU through OpenCL, Metal, Huawei Kirin NPU, Huawei Ascend NPU, Kunlunxin XPU and Kunlunxin XTCL, Qualcomm QNN, Cambricon MLU, VeriSilicon TIM-VX for Rockchip, Amlogic and NXP parts, Android NNAPI, MediaTek APU, Imagination NNA, Intel OpenVINO and the Eeasytech NPU.
Cells are blank or marked with a dash, and the table never defines what the dash means. The pattern is consistent enough to read as out of scope: Android NNAPI is blank only under the Android column and dashed everywhere else, and OpenCL, Huawei Kirin NPU, Qualcomm QNN and MediaTek APU follow that same shape, while Metal is blank only under iOS. Only three accelerator rows stay live under both Linux columns, Huawei Ascend NPU, Kunlunxin XPU and Kunlunxin XTCL, while Intel OpenVINO and Cambricon MLU are live under x86 Linux alone. If your part is not in that table, the runtime may still exist, but nothing here is testing it in CI.
A push in April 2026, a release tag from July 2024
The repository is not archived, and the last push landed on 2026-04-27 on develop, which is the default branch. So the source tree is still moving.
The release record tells a flatter story. The three most recent releases are v2.14-rc dated 2024-07-19, v2.13-rc dated 2023-03-27, and v2.12 dated 2022-11-18. The newest tag in that feed is a release candidate, and it predates the last commit by roughly twenty months.
For a runtime people link into an APK or an IPA, that distance matters twice. The prebuilt library you download is not built from the current develop tree, so anything fixed on develop after July 2024 is not in the binary you ship unless you build it yourself. And v2.14-rc is a candidate, so pinning an app to it is a decision about which candidate. Check what the release page actually holds before you choose between a download and a source build.
The README prints no install command at all
The README's quick start prints no install command: no pip install, no cmake invocation, no gradle line. Getting started is four steps, and three of them are links: prepare a PaddlePaddle model, run it through the opt tool, fetch a prebuilt library or build from source, then start from one of the C++, Java or Python examples.
The only line that can be written down without inventing anything is the one that fetches the repository itself.
git clone https://github.com/PaddlePaddle/Paddle-Lite.git
cd Paddle-Lite
Past that point everything is a documentation site. The named entry points are the prebuilt release library page and the Docker build environment page under paddlepaddle.org.cn/lite, the source compile page, and one demo guide per backend, from Arm and x86 through OpenCL, Metal, Android NNAPI and each vendor NPU. The API references are separate pages too, one each for C++, Java, Python and CV image processing.
What the repository does hand you is a root CMakeLists.txt, a cmake/ directory, a lite/ directory, a third-party/ directory and a tools/ directory, alongside .clang-format, .clang-tidy, a .pre-commit-config.yaml and a Travis configuration. That is a legible layout and not one documented invocation, so the build decision lands on your team. Check the release page first, since a prebuilt library can remove the problem outright.
Editorial conclusion
Pick Paddle Lite when your models are trained in PaddlePaddle and your target is a phone, an embedded board, or a vendor NPU that appears in the CI table. You get an opt tool, three language APIs, and a runtime you can trim down to kernels alone. Skip it when your models arrive as TensorFlow or PyTorch checkpoints. Before committing, open the release page and confirm that your accelerator has a live cell in the CI matrix and that v2.14-rc is the tag you actually want to pin.
Frequently asked questions
What is PaddlePaddle, and how does Paddle Lite use it?
PaddlePaddle is the deep learning framework that produces the models Paddle Lite runs. Paddle Lite accepts only the inference model saved by the save_inference_model API, so a model trained in another framework has to be converted with X2Paddle before the runtime will open it.
How do I install Paddle Lite?
The README's quick start links to the docs site rather than printing an install command. Prebuilt release libraries cover Android, iOS, x86 and macOS. Anything else means the Docker unified build environment or the manual source compile guide, both linked from paddlepaddle.org.cn/lite.
What are Paddle and Paddle Lite used for?
Paddle Lite is positioned as an inference engine for mobile, embedded and edge hardware, and it is used inside Baidu's own products. It covers Android, iOS, embedded Linux, Windows, macOS and Linux hosts, and exposes C++, Java and Python APIs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-paddle-lite)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-paddle-lite)Was this useful?