OSSInsight: the TypeScript monorepo behind a 10-billion-event GitHub analytics site, with SQL generated from plain-English questions
Analysis, Comparison, Trends, Rankings of Open Source Software, you can also get insight from more than 10 billion with natural language (powered by LLM). Follow us on Twitter: https://twitter.com/ossinsight
At a glance
- What is it?
- pingcap/ossinsight is the source of ossinsight.io, a site that analyses GitHub event data for repositories, developers, rankings and AI tooling. You use it mostly as a website, and contribute to it through curated collection files.
- Who is it for?
- Use OSSInsight when you want to compare repositories, track an ecosystem through curated collections or ask ad hoc questions of GitHub history. Do not treat this repository as a library or a data download, and treat its blog figures as the site's own analysis.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
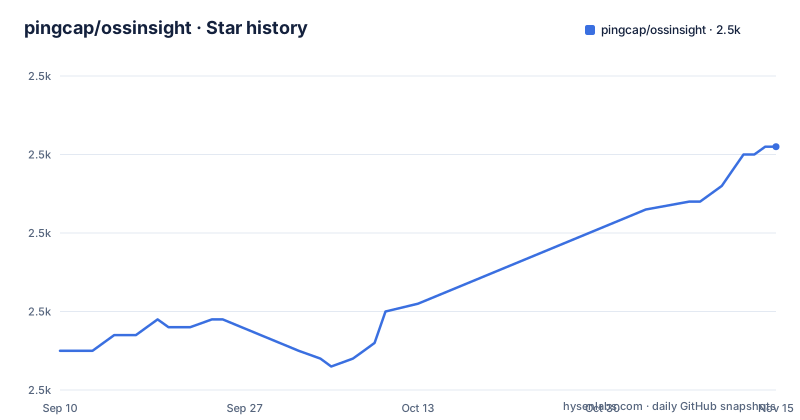
Star history
- pingcap/ossinsight2,531 ★ · +26
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| pingcap/ossinsight | 2.5k | 2.5k |
26 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is the site's source, not a package you install
OSSInsight describes itself as the analytics engine for the AI-native open source ecosystem, analysing 10+ billion rows of GitHub event data. The top level of the repository shows what that means in practice: apps, packages, etl, configs, scripts, a memory directory, and a pnpm workspace driven by turbo. It is the code behind ossinsight.io.
The consequence is that the main way to use OSSInsight is a browser. There is no library entry in the package.json, which names the project ossinsight-monorepo and marks it private. If you were hoping to import a client and query the dataset from code, nothing here advertises that.
What you do get is the ability to read how the site is built, and to contribute collections through a pull request, which the project invites.
Data Explorer writes the SQL, so you should read it
Data Explorer lets you ask questions about GitHub data in natural language. It generates SQL, queries the data and presents the results visually. The examples are projects similar to facebook/react and where the contributors of kubernetes/kubernetes come from.
The description credits an LLM for this feature. That means the query is generated, and a generated query can misread your question. Check the SQL that is shown against what you meant, particularly for questions that depend on a definition such as active contributor or company, where there are several reasonable readings.
The project also supplies a list of popular questions at ossinsight.io/explore, which is a quicker start than writing your own. For anything you plan to publish, a result from a generated query deserves a second look at the query before the number goes into a slide.
Repository and developer pages measure different things
Repository Analytics reports stars, forks, issues, commits, pull requests, contributors, languages and lines of code. It also breaks down the geographic and company distribution of stargazers, issue creators and PR creators. Examples are React, TiDB and PyTorch.
Developer Analytics looks at a person. It covers contribution time distribution, stars, languages and trends, plus commits, pull requests, code line changes, code reviews and issues. The project frames the results as insights about productivity, work cadence and collaboration, and the example is torvalds.
Treat those as activity measures, not quality ratings. A high commit count says a person or project is active in the data, nothing more. Comparison is a URL pattern: a path such as analyze/pytorch/pytorch with the vs parameter set to tensorflow/tensorflow compares two projects side by side on any metric, and the same works for Vue and React.
Collections decide what a ranking covers, and you add one with a YAML file
Collections are curated lists of repositories in a technical field, ranked by GitHub metrics. The README names more than 60 curated collections, from databases to Web3, DevOps and AI safety. Popular ones include AI Agent Frameworks, Open Source Database, Web Framework and JavaScript ORM.
Adding one means submitting a pull request to etl/meta/collections/ with this format:
id: <collection_id>
name: <collection_name>
items:
  - owner/repo-1
  - owner/repo-2
The consequence for readers is that a ranking only ranks what a curator listed. A repository missing from a collection simply does not appear, so an absent project is not evidence that it is small. When a comparison of ecosystems matters to you, check the list in the YAML to see what was included and who chose it.
It publishes llms.txt, OpenSearch and Schema.org data for machine readers
The site is built to be read by models as well as people. It serves /llms.txt as a structured site description for LLMs and /llms-full.txt with full documentation in an LLM-friendly format. There is an OpenSearch file at opensearch.xml for machine-readable search integration.
Every page carries Schema.org structured data, with types named in the README such as TechArticle, CollectionPage, BreadcrumbList and FAQPage.
The practical effect is that an agent or crawler can find the structure of the site without scraping layout, and that search engines get explicit page types. It does not make an API. These files describe the site; they do not promise a stable programmatic interface to the dataset, so do not build a pipeline on scraped pages and assume the format will hold.
Local development needs pnpm 10.29.3 and Node 20.9 or newer
package.json fixes the toolchain. The packageManager field is [email protected], the engines field requires node >=20.9.0, and the dev tools are turbo ^2.7.1 and typescript ^5.2.2. There is also a pnpm override for @tanstack/react-query at ^5.90.21.
The scripts split by target. dev and dev:web run pnpm --filter web dev. dev:docs and dev:all start the docs site, alone or together with web, through turbo. start, start:web, start:docs and start:all mirror them for built output, and build, lint and check-types run through turbo for all workspaces.
The consequence is that an older Node, or npm in place of pnpm, will not match what the project expects. Note also that these scripts start the web and docs apps. The data pipeline lives in the etl directory, so running the website locally is a separate concern from reproducing the 10 billion row dataset.
Featured findings are the site's own numbers, and the only releases are 2022 sample data
The featured analysis table states several figures: karpathy/autoresearch with 54K stars in 19 days and a 1,085 to 1 fork-to-contributor ratio, and 57K AGENTS.md repositories against 21K CLAUDE.md. These are claims from the project's blog posts, based on its dataset, and I have not checked them against GitHub independently.
The release list is not a version history. The two entries are sample-data, titled Sample Data for TiDB MCP Server, from 2022-08-18, and sample, from 2022-06-27. So there is no tagged release of the application to pin, and the live site is whatever is deployed.
The last push was on 2026-09-08, the repository is not archived and the license is Apache-2.0. Pingcap is the organisation behind it, and TiDB appears as a repository example in the analytics pages.
Editorial conclusion
Use OSSInsight when you want to compare repositories, track an ecosystem through curated collections or ask ad hoc questions of GitHub history. Do not treat this repository as a library or a data download, and treat its blog figures as the site's own analysis. Before relying on a ranking, check that the repository is in the collection you are reading and read the SQL that Data Explorer generated.
Frequently asked questions
What is OSSInsight?
OSSInsight is an analytics site for open source that analyses more than 10 billion rows of GitHub event data, covering repositories, developers, collections and rankings.
How do I add a collection to OSSInsight?
Submit a pull request to etl/meta/collections/ with a YAML file giving an id, a name and a list of owner/repo items.
Can OSSInsight compare two repositories?
Yes. The Compare Projects feature puts two projects side by side on any metric, for example PyTorch against TensorFlow or Vue against React.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pingcap-ossinsight)Star history chart for your README
[](https://hysenlabs.com/projects/pingcap-ossinsight)Was this useful?