PyKEEN says Python 3.10, ships classifiers from 3.11, and has sat on a dev suffix since April 2025
🤖 A Python library for learning and evaluating knowledge graph embeddings
At a glance
- What is it?
- A knowledge graph embedding library whose quickstart is one function call, whose dataset table puts a 21777 triple graph next to one with 26 million, and whose build backend is still a pre-1.0 release.
- Who is it for?
- PyKEEN is worth the time if you are evaluating embedding models rather than training one for production, because the pipeline function, the interchangeable APIs and the thirty seven built in datasets remove three weeks of plumbing, and the rank based evaluation it defaults to is the right default for link prediction. Three things to check before you commit.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
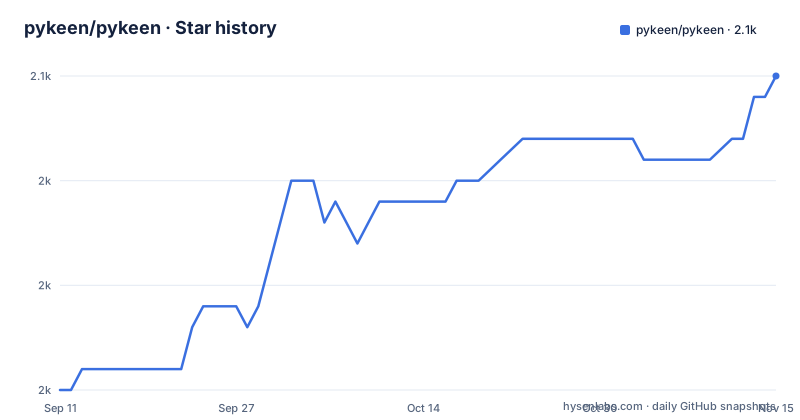
Star history
- pykeen/pykeen2,050 ★ · +15
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| pykeen/pykeen | 2k | 2.1k |
15 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version in the tree has carried a dev suffix since April 2025
The project configuration declares its version as `1.11.2-dev`. The newest tag is v1.11.1, published on 2025-04-24. Before that came v1.11.0 in October 2024 and v1.10.2 in February 2024.
The default branch was pushed on the same day this article was written. So the gap between the newest release and the newest commit is about eighteen months, during which the tree has carried the next patch number with a development suffix on it.
That is normal for a research library with a small maintainer base, and it has a concrete consequence for anyone following the quickstart. The example in the readme trains a model and evaluates it with whatever the newest tag does, not whatever is on the default branch. Anyone who installs from the registry and reads the documentation on the site is looking at two different pieces of software, and the documentation site itself is built per version, so the two can be pointed at different things.
The development status classifier in the same file says five, production and stable. That classification is about the package as released, and it sits next to a dev suffix without either one contradicting the other in a way a reader would notice.
The readme says Python 3.10 and the classifiers start at 3.11
The installation section says the latest stable version requires Python 3.10 or newer. The project configuration's classifier list declares four specific versions: 3.11, 3.12, 3.13 and 3.14, followed by a general marker for Python 3 only.
There is no 3.10 in that list. One of the two statements is out of date, and the classifier list is the one a packaging index reads when it decides whether to offer you the package, so a user on 3.10 gets a version resolution problem rather than a clear message.
The build system is worth noting in the same breath. The backend is no longer setuptools. It is the build backend from a different package manager, declared with a lower bound of 0.11.2 and an upper bound below 1.0. So the package that builds the library is itself a pre-1.0 dependency, pinned to a range rather than to a floor, which is a dependency that will move under you at the next resolution.
Everything else in the configuration is conventional and careful. The topic classifiers reach beyond artificial intelligence into chemistry, bioinformatics, mathematics and information analysis, which tells you who the authors think is using this.
The dataset table puts a small graph next to one with 26 million triples
Thirty seven datasets are built in, and each row of the table carries its entity count, relation count and triple count. Reading the visible rows tells you more about the library than the feature list does.
The CN3l family has 3206 entities, 42 relations and 21777 triples. CoDEx large has 77951 entities, 69 relations and 612437 triples. BioKG has 105524 entities, 17 relations and 2067997 triples. The clinical knowledge graph has 7617419 entities, 11 relations and 26691525 triples.
So the built in benchmarks span four orders of magnitude in triple count, and the two biomedical datasets have fewer relations than the text benchmarks do. A reader who picks a dataset by subject matter, which is what the names invite, is making a resource decision they have not been told about: whether a training run finishes in an afternoon or over a weekend.
The table also states its own citation policy, which is unusually careful. Each dataset is credited to the paper describing it, or failing that to the first paper that used it with embedding models, or failing that to the dataset's own address. Three datasets in view cite an arXiv identifier, two cite a conference or journal DOI, and one cites a direct PDF.
A dataset request is a templated issue assigned to one maintainer
Adding a dataset is the contribution the project most obviously wants, and the readme hands you the mechanics rather than describing them. The link it gives is not a generic new issue button. It is a pre-filled address that selects an issue template named for dataset requests, applies a label for new datasets, assigns the issue to a specific maintainer by handle, and writes a title of the form Add followed by the dataset name in brackets.
Everything about the request is decided before you type a word except the name. That is a well run process, and it is also the clearest statement of how the project is organised: one person owns the dataset list, the form collects the same fields every time, and a contributor never has to guess what a good request looks like.
The counts in the navigation bar sit alongside the table, and they are of three different kinds. Thirty seven datasets, five inductive datasets, which are the ones meant for settings where the entities at prediction time were not all seen during training, and forty models. The implementation section adds training modes, evaluators and metrics to that list without numbers, which is the one place the readme stops counting.
For scale, the repository has just over two thousand stars and a hundred and twenty three open issues, which is a maintenance load worth knowing about before you file one.
One function is the quickstart and it chooses the loop for you
The whole entry point is four lines:
from pykeen.pipeline import pipeline

result = pipeline(
    model="TransE",
    dataset="nations",
)
A model name and a dataset name, both strings. What comes back is an instance of a result dataclass carrying the trained model, the training loop that ran it and the evaluation, so nothing is hidden behind a returned metric you cannot reach.
The readme also says which choices the function makes when you do not make them. The default training approach is the stochastic local closed world assumption, and the default evaluation is rank based. Both defaults are the right ones for link prediction and both are decisions you are not told you are making.
The extensibility contract is three sentences and they are what the package is really for. Every model has the same API, so anything from the models module drops in. Every training loop has the same API, so a training loop drops in. And you can build your own triples factory from a public class, which is how a private graph gets in.
There is a small inconsistency in that paragraph. The example loop it names for swapping is the local closed world training loop, while the default the same section describes is the stochastic variant of it. Both exist, and the readme points at the one you do not get by default.
Two authors share one mailbox and the keywords credit a template
The project configuration lists four authors and two maintainers. Two of the authors share the project's own mail address rather than an individual one, while the other two have personal addresses, and the maintainers are drawn from those same four.
That is a small thing, but in a research library it tells you something about continuity. When the person who answers the issue tracker and the person who appears on the paper are not the same, the shared address is the address that survives a graduation.
The keyword list is more unusual. It opens with a placeholder keyword whose inline comment asks that it be kept in order to credit the cookiecutter template the project was scaffolded from, and the next entry begins the name of that same template. The first thing a search index sees when someone looks for this package is the name of the generator that built its skeleton.
The archive and citation side is more conventional. There is a DOI badge pointing at an archive record, a citation file in the root, and a contributors file listing who has worked on it. A library that archives releases and asks for citations has decided that it is infrastructure rather than a script.
The badges name the hyperparameter search and the deep learning dependency
The badge row at the top of the readme is short and each one means something. A continuous integration badge points at a workflow file whose name is simply common, so the build for every environment runs through one configuration rather than several. There is a licence badge, the archive DOI, the code of conduct, and a linter badge.
Two of them are the interesting ones. One names Optuna, which is how the library does hyperparameter search across the forty models it ships, and one names PyTorch Lightning, which is what the neural models run on. Both appear in the badge row rather than in a requirements list, so the practical dependencies of the project are partly advertised on its front page and partly declared in files a reader has to go looking for.
The repository layout follows the same shape. A source directory rather than a flat package, a tests directory, a tox configuration for multi environment runs, a pre-commit configuration, a readthedocs configuration for the documentation site, a separate benchmarking directory at the root, and a notebooks directory. One inconsistency in an otherwise tidy tree: the changelog is a reStructuredText file while the readme, the contributors file and the contributing guide are all Markdown.
The documentation is published per version, which is why the version gap in the first section matters more here than it would in a project with one set of docs.
Editorial conclusion
PyKEEN is worth the time if you are evaluating embedding models rather than training one for production, because the pipeline function, the interchangeable APIs and the thirty seven built in datasets remove three weeks of plumbing, and the rank based evaluation it defaults to is the right default for link prediction. Three things to check before you commit. The release you install will be a year and a half older than the tree, so read the changelog for what changed since. The datasets differ in size by four orders of magnitude, so choose on triple count rather than on subject matter. And the interpreter support disagrees with itself, so test on the exact version you deploy on. For a project of this size, two maintainers, a templated dataset request process and an archived DOI, the operational risk is attention rather than architecture.
Frequently asked questions
How do I train a knowledge graph embedding model with PyKEEN?
Call the pipeline function with a model name and a dataset name, for example TransE on nations. It returns a result object holding the trained model, the training loop and the evaluation. By default it trains with the stochastic local closed world assumption loop and evaluates with rank based metrics.
Which Python versions does PyKEEN support?
The readme says the latest stable release requires Python 3.10 or newer. The classifier list in the project configuration names 3.11, 3.12, 3.13 and 3.14 with no 3.10 entry, so the two statements disagree.
How many datasets ship with PyKEEN and how big are they?
Thirty seven built in, plus five inductive ones. The sizes differ by four orders of magnitude: the visible rows run from the CN3l family at 21777 triples to the clinical knowledge graph at 26691525, and the biomedical sets have only 17 and 11 relations respectively.
How do I use my own triples in PyKEEN?
By building a triples factory from the public class in the triples module and passing it in. The readme lists that as one of three extensibility points, alongside dropping in any model and dropping in any training loop, since both have a common API.
How do I request a new dataset in PyKEEN?
Through a templated issue link in the readme that selects the dataset request template, applies a new dataset label, assigns the issue to a maintainer by handle and pre-fills the title with the dataset name. The project also lists where to find the datasets documentation and the citation policy it follows.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pykeen-pykeen)Star history chart for your README
[](https://hysenlabs.com/projects/pykeen-pykeen)Was this useful?