AIMET's headline accuracy table is a simulation table, and its dependency list lives outside pyproject.toml
AIMET is a library that provides advanced quantization and compression techniques for trained neural network models.
At a glance
- What is it?
- AIMET quantizes trained ONNX and PyTorch models for edge deployment, and the README is mostly a capability table plus two result tables. What the repository adds is the build machinery: a CMake and CUDA compiled wheel whose name, version and dependencies are all filled in by a local packaging plugin.
- Who is it for?
- AIMET fits teams that already have a trained PyTorch or ONNX model and need INT8 weights for a specific target, and it does not fit anyone looking for a pure Python install: the wheel is compiled through scikit-build-core and CMake with CUDA targets pinned at build time.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
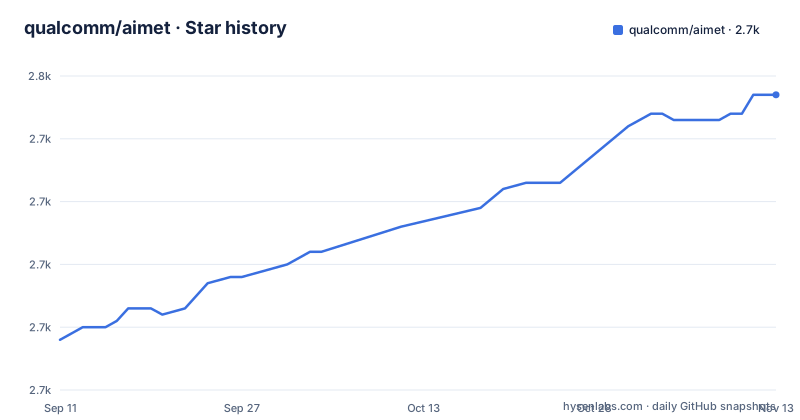
- qualcomm/aimet2,747 ★ · +39
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| qualcomm/aimet | 2.7k | 2.7k |
39 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The framework split has exactly one hole, and it is OmniQuant on ONNX
Distribution runs through two PyPI packages, aimet-onnx and aimet-torch, and the post-training quantization table carries a separate column for each. Eight of the nine techniques are marked as supported in both columns. One is not: OmniQuant, which optimizes quantized weights, is supported under PyTorch and unsupported under ONNX. That single gap is the whole of the framework asymmetry in the table. Quantization aware training is narrower still, since it is offered through aimet-torch alone, and the README points anyone who wants to combine it with the advanced post-training techniques at a separate workflow page. A pipeline built on ONNX has to plan around OmniQuant, and any quantization aware training work is a PyTorch decision from the start.
Two rows of the technique table describe themselves in the same words
The What does it do column is short enough that its overlaps show. AdaRound is described as rounding quantized weights; OmniQuant, seven rows later, is described as optimizing quantized weights. Two separate techniques, one line of wording apart. Batch normalization appears twice more in the same column: BatchNorm Folding folds batchnorm to bridge the gap between simulation and on-target, and BatchNorm re-estimation re-estimates batchnorm statistics. Cross Layer Equalization sits between those two rows and rescales the weight to reduce range imbalance, which is the preparation step for folding. The visualization section closes the loop by offering weight ranges as a way to judge whether a model is even a candidate for Cross Layer Equalization before you apply it. Compression has three entries of its own: Spatial SVD is a tensor decomposition that splits one large layer into two smaller ones, Channel Pruning removes redundant input channels from a layer and reconstructs the weights, and a per-layer compression-ratio selection step decides how hard each layer gets compressed instead of applying one ratio to the model. Per-layer compression sensitivity is the visual feedback offered for that decision.
The accuracy table is labeled INT8 Simulation and mixes two metrics
The results section claims that the data-free method applied to MobileNet-v2 and ResNet-50 loses less than 0.9 percent of accuracy down to 8-bit, automatically and with no training data. The table under that claim carries three rows and a single pair of column headers, FP32 and INT8 Simulation. The values are MobileNet v2 top1 71.72 percent against 71.08, ResNet 50 top1 76.05 percent against 75.45, and DeepLab v3 mIOU 72.65 percent against 71.91. Two of those rows are classification accuracy and the third is a segmentation metric, so the columns are not one measurement. The word Simulation in the header is the load-bearing part: nothing in the table was measured on hardware.
The one hardware claim has no table, and the AdaRound table opens fifteen columns
The speed argument is stated in prose instead. Integer inference is called significantly faster than floating point, models are said to run 5x to 15x faster on the Qualcomm Hexagon DSP than on the Qualcomm Kyro CPU, and 8-bit models are said to have a 4x smaller footprint than 32-bit ones. No table accompanies those three numbers. The AdaRound section does the opposite: it names a single ADAS object detection model as challenging to quantize to 8-bit and says AdaRound recovers accuracy to within 1 percent of the FP32 figure. The HTML table that follows declares a configuration header spanning fifteen columns, and the file ends partway into the first cell of that header row, so the per-configuration figures behind that claim are not present.
Name, version and dependencies are all marked dynamic and filled in by a plugin
pyproject.toml declares five fields dynamic: name, dependencies, version, optional-dependencies and description. Each one is supplied at build time by a provider plugin living at packaging/plugins/local, so the file a reader would open to find the dependency list does not contain the dependency list. The build backend is scikit_build_core, and the build requirements pin scikit-build-core[wheels]==0.11.1 alongside build, pybind11 and cython>=3.0. Two more flags are worth knowing before a local build: experimental is true and strict-config is false, with logging.level set to DEBUG. sdist.cmake is false and build-dir is build, so the CMake path is only exercised for wheels.
The wheel targets three CUDA architectures and calls itself a Python 3.10 stable ABI
The build is compiled, not pure Python. CMake is required at minimum-version 3.26, the build type is RelWithDebInfo, and CUDA is configured with three architecture values, 70, 75 and 80, plus --threads=8 as the CUDA flag. Those three values are the whole GPU target list in the file, compiled into the artifact at build time. On the Python side requires-python is >=3.10 and wheel.py-api is set to cp310 with the comment that the stable ABI means the wheel works with Python 3.10 and later. Two wheel lists are deliberately empty, wheel.packages and wheel.license-files, which is consistent with a scikit-build-core project where the package layout comes from CMake rather than from setuptools.
Two CI systems, four style configs, and a license declared three ways
The root carries both .github/ and Jenkins/, alongside a top-level NightlyTests/ directory, so two automation systems coexist in one repository. Style is configured four ways: .clang-format for C++, .pylintrc, .ruff.toml, and a .pre-commit-config.yaml paired with a license header template, plus repolint.json and .omniscanignore. The pytest section is strict by design, with xfail_strict set to true, pytest-xdist and pytest-extra-durations declared as required plugins, and addopts carrying --strict-markers, --strict-config and --dist=loadgroup with a comment about not parallelizing tests inside one xdist group; that array then ends on an opening quote and a hyphen with nothing after it. Licensing is inconsistent across sources: repository metadata reads NOASSERTION, pyproject.toml declares BSD-3-Clause, a LICENSE file sits in the root, and the project URL points at github.com/quic/aimet while the repository is at github.com/qualcomm/aimet.
Editorial conclusion
AIMET fits teams that already have a trained PyTorch or ONNX model and need INT8 weights for a specific target, and it does not fit anyone looking for a pure Python install: the wheel is compiled through scikit-build-core and CMake with CUDA targets pinned at build time. Read the technique table for the OmniQuant gap before planning an ONNX pipeline, treat the published accuracy figures as simulation numbers, and settle the license question yourself, since the repository metadata, pyproject.toml and the root LICENSE file do not agree.
Frequently asked questions
Which AIMET packages are published on PyPI?
aimet-onnx and aimet-torch. Quantization aware training is offered through aimet-torch, and the README directs anyone building the newest code from source to a Docker environment page.
Does AIMET offer the same quantization techniques for ONNX and PyTorch?
Not quite. In the post-training quantization table, OmniQuant is marked as supported for PyTorch and not supported for ONNX, while the other eight techniques are supported in both columns.
Were the AIMET accuracy figures measured on a device?
The published table's second column is headed INT8 Simulation, and the separate claim that models run 5x to 15x faster on the Qualcomm Hexagon DSP than on the Qualcomm Kyro CPU appears in prose without an accompanying table.
What license does AIMET declare?
Three sources disagree in shape rather than in wording: repository license metadata reads NOASSERTION, pyproject.toml declares BSD-3-Clause, and a LICENSE file sits in the repository root.
How strict is the AIMET test configuration?
pytest is configured with xfail_strict set to true, pytest-xdist and pytest-extra-durations as required plugins, and addopts including --strict-markers, --strict-config and --dist=loadgroup so that tests inside a single xdist group are not parallelized.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qualcomm-aimet)Star history chart for your README
[](https://hysenlabs.com/projects/qualcomm-aimet)Was this useful?