QwenLM/Qwen: the first Qwen codebase, and the note that sends you to Qwen2
The official repo of Qwen, a chat and pretrained large language model proposed by Alibaba Cloud.
At a glance
- What is it?
- QwenLM/Qwen holds the first-generation Qwen weights, quantization script and finetuning tutorials for sizes from 1.8B to 72B, and its own README says the repository is no longer actively maintained. Useful for reproducing that first release; new work belongs in the Qwen2 tree.
- Who is it for?
- Use QwenLM/Qwen if you are reproducing the first Qwen release or need its GPTQ and finetuning scripts against already published weights; skip it for anything new, because the last push was 2026-03-05 and the README points new work at QwenLM/Qwen2. Before shipping anything built on these weights, open the root NOTICE and the two Tongyi Qianwen agreement files to see which terms cover your use.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
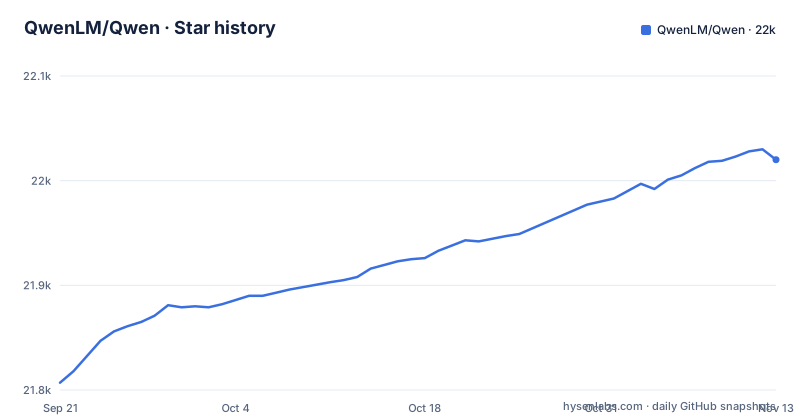
Star history
- QwenLM/Qwen22,020 ★ · +213
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| QwenLM/Qwen | 21.8k | 22k |
213 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first block of the README sends you to a different repository
The opening block of README.md is an Important note that does two things: it names QwenLM/Qwen2 as the place to follow and share experience, and it states that this repo "is no longer actively maintained, due to substantial codebase differences." The last push to this branch landed on 2026-03-05.
So read everything below as a record of how the first Qwen release was built and shipped, not as a place to report a bug. run_gptq.py, finetune.py and the scripts under examples/ target first-generation Qwen and the transformers range pinned in requirements.txt. If another project in the same environment needs a transformers newer than that range, put Qwen in its own virtualenv rather than relaxing the pin.
Qwen-14B caps at 8K while the other three sizes report 32K
The size table is where this repository is most precise and least even. Max Length reads 32K for Qwen-1.8B, 32K for Qwen-7B, 8K for Qwen-14B and 32K for Qwen-72B, so the 14B model is the one that breaks the pattern. Pretrained token counts climb from 2.2T for 1.8B to 2.4T for 7B and 3.0T for both 14B and 72B, and the release dates run 23.08.03, 23.09.25, then 23.11.30 for the two newest sizes.
Two consequences follow for anyone choosing a row. If a prompt plus its answer exceeds 8K tokens, 14B is the wrong size even though it carries the second largest parameter count here. And System Prompt Enhancement is marked present on 1.8B and 72B but absent on 7B and 14B, so a system prompt that behaves well on the smallest model is no evidence that it behaves the same way on the middle two.
The GPU columns price one thing only: a 2048-token Int4 completion
Every size ships a plain, an Int4 and an Int8 variant on both Hugging Face and ModelScope. run_gptq.py at the repository root is the entry point for the GPTQ path, and the repository summary also names KV cache quantization.
Read the memory columns with their headers attached. Minimum GPU Usage of Generating 2048 Tokens (Int4) is 2.9GB for 1.8B, 8.2GB for 7B, 13.0GB for 14B and 48.9GB for 72B. Minimum GPU Memory Usage of Finetuning (Q-Lora) is 5.8GB, 11.5GB, 18.7GB and 61.4GB in the same order. The first column is measured for generating 2048 tokens with Int4 weights and the second for Q-LoRA finetuning; for 72B, 48.9GB is the floor for a short generation while 61.4GB is the floor for tuning it.
requirements.txt pins a transformers ceiling and one exact package
Installation is a checkout plus one requirements file. There is no setup.py and no package name among the top-level entries, so nothing installs by name; the dependencies are declared in requirements.txt:
pip install -r requirements.txtThat file has six requirement lines, and two of them decide how far you can move your environment:
transformers>=4.32.0,<4.38.0
accelerate
tiktoken
einops
transformers_stream_generator==0.0.4
scipy
The transformers ceiling of 4.38.0 is the one that bites. pip resolves to an older transformers inside that window, and transformers_stream_generator is held at an exact 0.0.4, so a wheel cached by another project will not satisfy it. Once the environment matches, cli_demo.py is the local entry point and web_demo.py serves a browser interface, with its own requirements_web_demo.txt kept separate from the main file.
Five root scripts are the entire interface, and there is no version to pin
The root of the repository is the whole user interface: cli_demo.py for a terminal session, web_demo.py for a browser, openai_api.py as the file whose name marks the API entry point, run_gptq.py for quantized weights, finetune.py for tuning, and utils.py underneath them. There is no console script and no packaged distribution, so every invocation is a path into a checkout.
There is also no GitHub release for this repository, which means no version number to pin in a deployment; you pin a commit. Hardware material is split across ascend-support/ and dcu-support/, so the deployment notes for one accelerator family are not the notes for another.
Token budgets need qwen_extra.tiktoken before you trust any count
Counting tokens before you spend them is not optional here, because the context ceilings in the size table are denominated in tokens and they differ per model. requirements.txt pulls in tiktoken, and the examples directory carries qwen_extra.tiktoken and qwen_extra_vocab.txt beside add_merges.py and tokenizer_showcase.ipynb, while tokenization_note.md sits at the root with Japanese and Chinese copies next to it.
The alignment stage is unreleased, the language focus is narrow, the scores are unnamed
Three limits are stated by the repository itself and are worth reading before planning around it. The chat models are described as aligned with human preference based on SFT and RLHF, with the parenthetical "not released yet", so the alignment stage cannot be reproduced from this tree. You get the resulting weights on Hugging Face and ModelScope.
Pretraining covered up to 3 trillion tokens of multilingual data "with a focus on Chinese and English", so for any other language this repository publishes no coverage figure to plan against. And the base models are said to reach competitive performance on benchmark datasets without a score in the summary, while an eval/ directory exists in the tree if you want to measure something yourself.
Qwen2 is the alternative, and the split is a codebase split, not a scale one
The real alternative is named inside the repository itself: QwenLM/Qwen2, with the stated reason being substantial codebase differences. That makes this a division along code structure rather than model size, and the difference has a practical shape. The quantization path here is run_gptq.py, the tuning path is finetune.py with full-parameter, LoRA and Q-LoRA tutorials, and the agent and tool examples live under examples/, including react_demo.py and transformers_agent.md. All of it is written against first-generation Qwen and the 4.32 to 4.38 transformers window.
A second route sidesteps the hardware question altogether. The README links an Alibaba Cloud API at dashscope.aliyun.com and a hosted Qwen-72B-Chat demo on ModelScope, so a team unwilling to plan around a 61.4GB tuning floor can read the served path instead of running the checkpoints itself.
Editorial conclusion
Use QwenLM/Qwen if you are reproducing the first Qwen release or need its GPTQ and finetuning scripts against already published weights; skip it for anything new, because the last push was 2026-03-05 and the README points new work at QwenLM/Qwen2. Before shipping anything built on these weights, open the root NOTICE and the two Tongyi Qianwen agreement files to see which terms cover your use.
Frequently asked questions
Is Qwen AI better than ChatGPT?
The repository makes no comparison to ChatGPT. Its own claim is that the base models were pretrained on up to 3 trillion multilingual tokens and reach competitive performance on benchmark datasets, without naming any score in the summary.
Is it safe to use Qwen AI?
Its root carries LICENSE, NOTICE, Tongyi Qianwen LICENSE AGREEMENT and Tongyi Qianwen RESEARCH LICENSE AGREEMENT, so those files rather than the Apache-2.0 identifier alone are what you need to read.
What is Qwen AI mainly used for?
The chat models are described as able to chat, create content, extract information, summarize, translate, code and solve math problems, and to use tools, play as agents or play as code interpreters. Tool Usage is marked for all four sizes, from 1.8B to 72B.
Is Qwen AI totally free?
The code carries an Apache-2.0 license and the weights are published on Hugging Face and ModelScope, but the repository has no GitHub releases and states no cost for the hosted API it links. What inference costs depends on which path you take.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen)Was this useful?