reasoning-from-scratch: chapter notebooks on a Qwen3 base, and two dependency lists that disagree
Implement a reasoning LLM in PyTorch from scratch, step by step
At a glance
- What is it?
- The official code repository for a Manning book on improving LLM reasoning, where the main chapters are built to run on consumer hardware and only chapters 5 and 6 want a GPU. The manifest declares seven dependencies and the requirements file declares five, the version lives in a Python attribute while the only release tag is v1.0, and the Python ceiling is 3.15 with the chat interface extra stopping one release earlier.
- Who is it for?
- This repository is a good fit for learning the shape of reasoning methods rather than for building a product on top of one, and the readme is unusually clear about what that means, since the stated goal is a small but functional reasoning model for educational purposes, developed on top of a pre-trained base rather than from nothing. Two practical notes.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
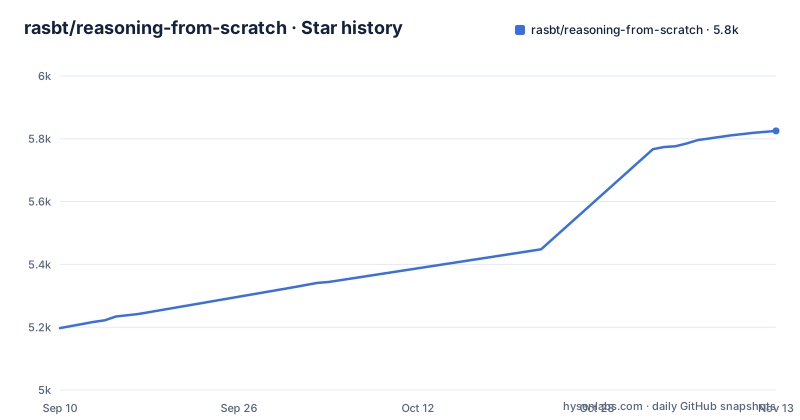
- rasbt/reasoning-from-scratch5,825 ★ · +628
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| rasbt/reasoning-from-scratch | 5.2k | 5.8k |
628 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One release tag, and the version number lives in a Python attribute
The repository has a single release, v1.0, published 2026-05-18.
The version itself is not written in the manifest. There is a dynamic version block that reads the number out of the package:
[tool.setuptools.dynamic]
version = { attr = "reasoning_from_scratch.__version__" }
That attribute lives in a package directory of the same name, and the manifest declares its version as dynamic rather than literal. That is the setuptools way of saying the package is the single source of truth.
Now line up the three version numbers a reader will meet. The only release tag is v1.0. The requirements file asks for the package itself at 0.1.2 or newer, with the name written with dashes rather than underscores. And the package attribute is whatever it is set to.
Nothing here is broken, but for a repository whose purpose is to be read, there are more places to look for the version than a repository needs.
The manifest lists seven dependencies and the requirements file lists five
The two dependency declarations do not agree, and the difference is not cosmetic.
The manifest declares seven runtime dependencies: jupyterlab at 4.4.7 or newer, torch at 2.10 or newer and below 3, tokenizers, nbformat, setuptools, sympy and matplotlib.
The requirements file has five lines:
reasoning-from-scratch >= 0.1.2
setuptools>=61.0
sympy>=1.14.0  # For verifier in ch03
torch >= 2.10, < 3
tokenizers >= 0.21.2
So jupyterlab, nbformat and matplotlib are absent from the file version. Those are exactly the packages you need to open and run the notebooks this repository is made of, which makes the requirements file the wrong entry point for the intended use.
Two smaller details. The torch bound is the same range written differently, with spaces in the file and without in the manifest. And the file's first line requires the project itself, which means installing from it pulls the published package rather than the working tree you just cloned.
Python has a ceiling at 3.15, and the chat interface stops at 3.14
The manifest's Python requirement is a range with a hard upper bound: 3.10 or newer and below 3.15. The classifiers agree, listing 3.10 through 3.14.
For a teaching repository this is a deliberate-looking choice rather than an oversight, and it has a cost. When a new Python release appears, this project does not support it until someone edits the bound and adds a classifier, and nobody is obliged to do that on your schedule.
One optional dependency carries its own, narrower ceiling. The extras group holds two packages: a datasets library at 4.1.1 or newer, commented as being for the evaluation appendix and MMLU, and a chat interface library at 2.8.3 or newer, commented as being for the chat appendix, with a marker restricting it to Python versions below 3.14.
So there are three tiers of support to reason about: the base install, an extra that adds an evaluation dataset, and an extra that adds a chat interface which is unavailable on the newest Python the project otherwise claims to support.
Chapters 2 to 4 run on a CPU, chapters 5 and 6 want a GPU
The hardware section is the most practical paragraph on the page, and it is specific.
The code in the main chapters is designed to mostly run on consumer hardware within a reasonable timeframe and does not require specialized server hardware, with the stated reason that this keeps the material accessible to a wide audience. The code also uses a GPU automatically if one is available.
Then the split: chapters 2 to 4 work well on both CPUs and GPUs, and for chapters 5 and 6 it is recommended to use a GPU if you want to replicate the results in the chapter.
Read against the table of contents, those two chapters are the self-refinement chapter on inference-time scaling and the reinforcement learning chapter. So the practical reading order is that you can do the text generation, evaluation and inference-time scaling work without a GPU, and the reinforcement learning work is where a card starts to matter. There is a separate setup tips document referenced for additional recommendations.
Chapter 1 has no code, and the appendices do not share a notebook path
The table of contents is careful about which entries carry code. Chapter 1, on understanding reasoning models, is marked as having no code. Chapter 2 through chapter 8 each have two notebooks, a main one and an exercise solutions one, and they live under a numbered subfolder inside each chapter directory.
The appendices are less uniform. Appendix A, references and further reading, has no code. Appendix B says the solutions are in each chapter's subfolder rather than in an appendix of its own. Appendix C on the base model's source code has a main notebook. Appendix D on using larger models and Appendix E on batching and throughput both have main notebooks that do not sit in the numbered subfolder the chapters use. Appendix G, the chat interface, is a directory link rather than a notebook.
So the paths are consistent for the eight chapters and then stop being consistent across the appendices. For a repository whose audience follows links from a table, that is the kind of inconsistency that produces a support question about one specific appendix.
Two books, one pre-trained base, and a mirrored set of large scale methods
The framing is stated plainly. The book takes a hands-on approach, starting with a pre-trained base model and adding reasoning capabilities step by step in code, and the stated reason is that reasoning is easy to misunderstand if you only hear the term and read about it in theory.
The base is a pre-trained open-source Qwen3 model, and the methods applied on top of it are inference-time scaling, reinforcement learning and distillation. The readme says the book mirrors the approaches used in large-scale reasoning models such as DeepSeek R1 and GPT-5 Thinking, and that it also includes code for loading the weights of existing pretrained models.
It is also explicit that the book is standalone and focused on methods to improve reasoning, and that anyone who wants to understand how a conventional base model is implemented should read the author's earlier book on building a large language model from scratch, with its own repository.
That division is the single most useful thing about the scope. Appendix C still includes the Qwen3 LLM source code, but explaining how a conventional base model is implemented is left to the earlier book.
The notebooks are tested on three operating systems, and pytest is told where not to look
Three workflow badges sit above the table of contents, one each for Linux, macOS and Windows test runs. Running notebooks on three platforms is a real constraint for a repository whose entire content is notebooks, because anything that touches paths or subprocesses has to work in all three.
There is a troubleshooting guide linked from the same block, and a tests directory in the tree.
The test configuration is the interesting part. The pytest options set a single excluded directory, and the excluded name is run_notebook_diffs.
The lint configuration is narrow in the same spirit: four rule groups selected, which is the pycodestyle error subset plus the pyflakes checks. For a book codebase aimed at readability rather than style policing, that is a proportionate choice.
The clone command is deliberately shallow, and the book is a printed one
The download instructions offer two routes: a ZIP download button, or one command:
git clone --depth 1 https://github.com/rasbt/reasoning-from-scratch.gitThe depth of one flag means no history, which is the right call for a repository whose value is its current state and which is meant to be followed alongside a book rather than studied as a project. It also means you cannot read the history of the notebooks to see how an approach changed between editions.
The book itself is a print product. The readme notes it is printed in color, gives an ISBN, and links the publisher's site and an Amazon page. The readme also notes that chapter 2 carries tips on installing Python, managing packages and setting up a coding environment, which tells you the setup burden is treated as part of the material rather than as an appendix.
So the code is open under the Apache 2.0 licence and the text is not distributed with it. That is the ordinary arrangement for a technical book, and it is the reason a reader wanting the explanations has to buy the book while anyone can run the notebooks.
Editorial conclusion
This repository is a good fit for learning the shape of reasoning methods rather than for building a product on top of one, and the readme is unusually clear about what that means, since the stated goal is a small but functional reasoning model for educational purposes, developed on top of a pre-trained base rather than from nothing. Two practical notes. Install from the manifest rather than the requirements file, because the two do not list the same packages and the file version omits the notebook tooling you need to open the chapters. And read the hardware split before planning your time, because chapters 2 through 4 will run on a CPU while chapters 5 and 6 are the ones that want a GPU. If you want to see how a base language model itself is built, the readme points at the author's earlier book instead, although Appendix C includes the Qwen3 LLM source code. And if you are looking for a free copy, this is a printed book with an ISBN, so the code is public and the text is not.
Frequently asked questions
What is reasoning-from-scratch and what does it contain?
It is the official code repository for the book Build a Reasoning Model (From Scratch), and it holds the chapter code and exercise solution notebooks. The work takes a pre-trained open-source Qwen3 base and applies reasoning methods on top of it, covering inference-time scaling, reinforcement learning and distillation.
Do I need a GPU to run the code in reasoning-from-scratch?
Not for most of it. The main chapters are designed to run on consumer hardware within a reasonable timeframe and use a GPU automatically if one is available. Chapters 2 to 4 work well on CPUs and GPUs; for chapters 5 and 6 a GPU is recommended if you want to replicate the chapter's results.
Which Python versions does reasoning-from-scratch support?
The manifest requires Python 3.10 or newer and below 3.15, with classifiers for 3.10 through 3.14. The optional chat interface extra additionally carries a marker restricting it to Python versions below 3.14.
Which base model does the reasoning-from-scratch book build on?
A pre-trained open-source Qwen3 base, with Appendix C containing the base model's source code. The repository also includes code for loading the weights of existing pretrained models, and says the methods mirror those used in large-scale reasoning models such as DeepSeek R1 and GPT-5 Thinking.
Do the requirements file and the manifest in reasoning-from-scratch list the same dependencies?
No. The manifest declares seven dependencies including jupyterlab, nbformat and matplotlib, while the requirements file has five lines and omits those three. It also begins by requiring the reasoning-from-scratch package itself at 0.1.2 or newer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rasbt-reasoning-from-scratch)Star history chart for your README
[](https://hysenlabs.com/projects/rasbt-reasoning-from-scratch)Was this useful?