chefboost: trees that compile to Python and fall through to Yes
A Lightweight Decision Tree Framework supporting regular algorithms: ID3, C4.5, CART, CHAID and Regression Trees; some advanced techniques: Gradient Boosting, Random Forest and Adaboost w/categorical features support for Python
At a glance
- What is it?
- A teaching-oriented decision tree library for ID3, C4.5, CART, CHAID, regression trees, boosting and random forests, with native categorical support. Its artefacts are Python if statements you can import, and its install requirements are read with a bare split call.
- Who is it for?
- chefboost earns its place when you need a tree you can read, print and hand to a colleague, because the model is source code rather than a pickle alone, and categorical columns work without encoding. Two habits are worth forming before you rely on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
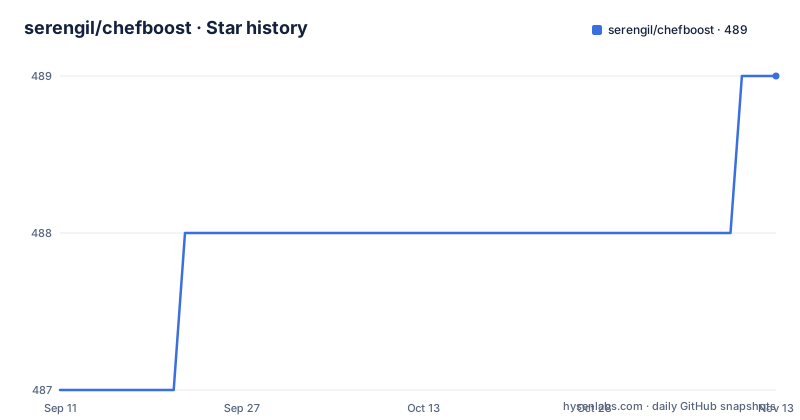
- serengil/chefboost489 ★ · +2
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| serengil/chefboost | 487 | 489 |
2 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The homepage field points at a tutorial video
The repository metadata is where the small inconsistencies start. The homepage is recorded as a YouTube watch link carrying a playlist identifier and an index of three, so the canonical address for the project is one tutorial video rather than a site, and the README links a second YouTube playlist alongside a PyPI page and a Zenodo DOI. The package version in setup.py is 0.0.19, a number that says development rather than release, and no GitHub release has ever been published. The description in the packaging is also narrower than the one on the page: it names gradient boosting, random forest and AdaBoost and stops there, while the README leads with ID3, C4.5, CART, CHAID, regression trees and native categorical support. The repository is not archived and the last recorded push is 2026-05-13, so the code moves without any of it being versioned.
install_requires is a bare split of the requirements file
The packaging reads its dependency list the way it reads its long description, with the file content handed straight to setuptools:
with open("requirements.txt", "r", encoding="utf-8") as f:
    requirements = f.read().split("\n")
There is no comment stripping, no blank filtering and no validation, so whatever the file contains, including a trailing newline, becomes an entry in install_requires. The file itself is four lines with floors only: pandas 0.22.0, numpy 1.14.0, tqdm 4.30.0 and psutil 5.4.3, and no upper bounds anywhere. Two things follow. There is no scikit-learn dependency, which tells you the algorithms are implemented in the package rather than delegated, and the floor for pandas and numpy is years behind any release you would install today, so a modern environment gets whatever satisfies the floor. python_requires is 3.6, a version long out of support.
Every generated branch ends in a catch-all return
A trained tree is written out as a Python function, which is the feature that makes this library readable. The sample on the page is the golf dataset rendered as nested if statements:
def findDecision(Outlook, Temperature, Humidity, Wind):
   if Outlook == 'Rain':
      if Wind == 'Weak':
         return 'Yes'
      elif Wind == 'Strong':
         return 'No'
      else:
         return 'No'
   elif Outlook == 'Sunny':
      if Humidity == 'High':
         return 'No'
      elif Humidity == 'Normal':
         return 'Yes'
      else:
         return 'Yes'
   elif Outlook == 'Overcast':
      return 'Yes'
   else:
      return 'Yes'
Read the else branches. Every one of them returns a class rather than signalling that the input was not seen in training, so an outlook or a humidity value that never appeared in the data is classified silently, and in this sample the default is yes. A caller cannot tell a confident prediction from a fallback unless it inspects the training data itself. That is a reasonable default for a teaching tool and a wrong one to inherit into a scoring service.
Two different directories are named for the same artefact
The page describes where trees land twice, in two different ways. Under outcomes it says built trees are stored as Python if statements in the tests/outputs/rules directory. Under the prediction examples it says decision rules will be stored in an outputs/rules folder, and the restore snippet points at a module name of outputs/rules/rules. The model section adds a third instruction: restoration requires the .py and .pkl files to be stored under outputs/rules. Read together, the artefact directory is relative, and whether it resolves to tests/outputs/rules or outputs/rules depends on where you run from. Since a tree is a file rather than an in-memory object, that difference decides whether a prediction call finds your model at all, with the path used in training not necessarily the path used later.
restoreTree imports the model as a Python module
The transfer learning story is three lines. Name the module, restore it, call the decision function directly:
module_name = "outputs/rules/rules" #this will load outputs/rules/rules.py
tree = chef.restoreTree(module_name)
prediction = tree.findDecision(['Sunny', 'Hot', 'High', 'Weak'])
The consequence is worth being explicit about. The trained model is a Python file that gets imported, so restoring one is executing generated code on your interpreter, and the trained model's behaviour is now coupled to whatever that file imports and to the Python version running it. The upside is real: the artefact is diffable, greppable and reviewable, and you can hand someone a rules file instead of a model object. The saved-and-loaded path takes a different route, with a pickle alongside the rules file, which means a model has two representations and both are required to restore it.
The sample configurations are small, and the learning rate is 1
Three configurations are offered for the ensemble methods, and all three are deliberately minimal:
config = {'enableGBM': True, 'epochs': 7, 'learning_rate': 1, 'max_depth': 5}
config = {'enableRandomForest': True, 'num_of_trees': 5}
config = {'enableAdaboost': True, 'num_of_weak_classifier': 4}
Seven boosting epochs at a learning rate of 1 is the number to look at, since that rate applies each tree's contribution at full strength. Five trees makes the forest an illustration of averaging rather than a forest tuned for accuracy, and four weak classifiers for AdaBoost is a small committee, described on the page as stumps that aim for a minimum score of 50 percent before the misclassified cases are upweighted. Predictions combine the members by summing the tree outputs for boosting and averaging them for the forest. Treat these as readable defaults for a demo, not as tuned values.
Each algorithm picks a different split metric, and the choice is a config key
Five regular trees sit behind one configuration key, and the split criterion differs between them by design. ID3 maximises information gain over entropy, C4.5 switches to the gain ratio, CART uses gini, CHAID tests chi square, and the regression tree splits on standard deviation. Switching algorithms is one string in the config dictionary, with the sample shown as an algorithm of C4.5 fitted with a target label of Decision. What does not change is the interface and, more usefully, the input handling: the page states that numeric and nominal features and target values are both handled without pre-processing, which is the capability the alternatives usually need an encoder for. That is the argument for the library, and it is also why the generated code above reads as plain equality comparisons instead of threshold arithmetic.
The lint target demands a perfect score and the tests run from their own directory
The build surface is a Makefile with two recipes. Tests run as cd tests followed by pytest over that directory with warnings disabled, which is why the generated trees land under tests/outputs rather than at the repository root. Linting runs pylint over the package directory with --fail-under=10, and since pylint scores out of ten that is the maximum, so any deduction fails the gate. The configuration for it is committed as a .pylintrc, and a .vscode directory ships alongside, which is an editor preference file left in the repository rather than left to the contributor. The package itself lives in a chefboost directory with a legacy scripts directory and an icon directory beside it, and installation is a single command from PyPI.
Editorial conclusion
chefboost earns its place when you need a tree you can read, print and hand to a colleague, because the model is source code rather than a pickle alone, and categorical columns work without encoding. Two habits are worth forming before you rely on it. Treat the generated if statements as a specification rather than as production code, because every branch ends in a catch-all return rather than an unknown marker. And pin your own dependency versions, since the library declares floors set years apart from any current release. For anything measured rather than explained, this is a teaching tool first.
Frequently asked questions
What is chefboost and which algorithms does it implement?
A lightweight Python decision tree framework: ID3, C4.5, CART, CHAID and regression trees, plus gradient boosting, random forest and AdaBoost. It handles numeric and nominal features and target values without pre-processing, and it is MIT licensed.
How do I install and import chefboost?
Run `pip install chefboost`, which installs the library and its prerequisites: pandas, numpy, tqdm and psutil. Then import it with `from chefboost import Chefboost as chef`, and fit with a pandas DataFrame and a config dictionary.
What format does chefboost save a trained tree in?
As Python if statements written to a rules directory, with a findDecision function you can call directly, and a pickled model alongside it. `chef.restoreTree` imports the rules file as a module and returns an object with a findDecision method.
Which split metric does each chefboost algorithm use?
ID3 uses entropy and information gain, C4.5 uses entropy and the gain ratio, CART uses gini, CHAID uses chi square, and the regression tree uses standard deviation. The algorithm is selected with a config key such as {'algorithm': 'C4.5'}.
Are the chefboost default configurations tuned for accuracy?
No, they are illustrative. The samples are seven boosting epochs at a learning rate of 1 with a maximum depth of 5, five trees for the random forest, and four weak classifiers for AdaBoost, with stumps described as aiming for a minimum 50 percent score.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/serengil-chefboost)Star history chart for your README
[](https://hysenlabs.com/projects/serengil-chefboost)Was this useful?