DeepCTR: TensorFlow CTR models as composable layers, with TensorFlow left to you
Easy-to-use,Modular and Extendible package of deep-learning based CTR models .
At a glance
- What is it?
- DeepCTR packages published click-through rate models as reusable TensorFlow layers with fit and predict interfaces plus an estimator path for TFRecord input. It installs almost nothing: TensorFlow is not a dependency, h5py is pinned to an exact old version on older Pythons, and the last release came after a three and a half year gap.
- Who is it for?
- Use DeepCTR when you are already committed to TensorFlow, you want a published CTR architecture as a starting point rather than from scratch, and your data is small enough that sample files and fit and predict are enough. Do not expect it to choose a TensorFlow version for you or to carry you to production scale, because TensorFlow is absent from its install requirements and the bundled examples are sample-sized.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 35 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
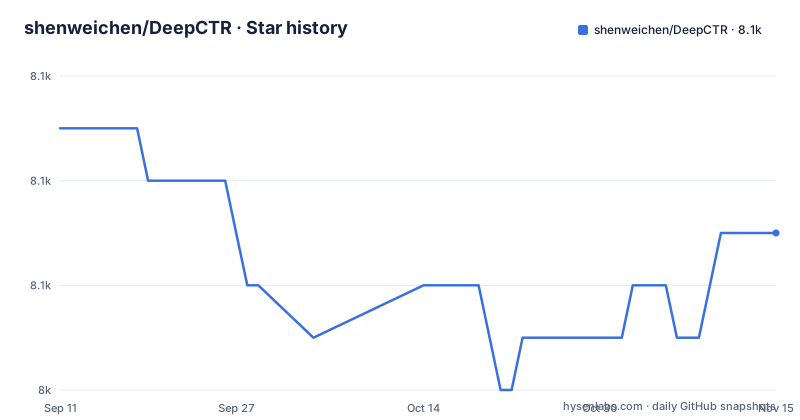
- shenweichen/DeepCTR8,051 ★ · -2
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| shenweichen/DeepCTR | 8.1k | 8.1k |
-2 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
DeepCTR does not install TensorFlow for you
The installation section makes its decision explicit before it gives any command: DeepCTR does not pin or install TensorFlow. You install a TensorFlow build that matches your Python, NumPy, CPU or GPU, and operating system first, then install DeepCTR.
pip install tensorflow
pip install deepctr
The order in that snippet is the whole point, and the two lines are not interchangeable.
The consequence is that the second command succeeds on its own and produces a package you cannot import until the first one is done. More importantly, the version choice moves to you, and the project then constrains the range: DeepCTR is compatible with both tf 1.15 and tf 2.x. So you pick the TensorFlow build and then have to check that what you picked falls inside a span that starts at a release from 2019.
For the NumPy side, the instruction is to follow TensorFlow's own requirement when a conflict is reported, using `numpy<2` where the selected TensorFlow release needs it. DeepCTR does not arbitrate that either.
install_requires is three packages, and one is pinned exactly
The dependency list is short enough to print in full. Here it is from setup.py.
REQUIRED_PACKAGES = [
    'requests',
    'h5py>=3.7.0; python_version>="3.9"',
    'h5py==2.10.0; python_version<"3.9"'
]
Three entries, and the first is unversioned. The other two are the same library selected by an environment marker on the Python version.
The asymmetry between `>=` and `==` is the part worth sitting with. On Python 3.9 and newer you get any modern h5py from 3.7.0 upwards. On Python 3.8 and older you get exactly 2.10.0, no flexibility at all.
That exact pin is also where the environment fragility concentrates, because an old h5py constrains NumPy, and NumPy is exactly what TensorFlow also constrains. If you land on an older interpreter, you inherit a three-way negotiation between packages, and the README's advice to defer to TensorFlow's requirement is the guidance it offers for resolving it.
python_requires says 3.7 while the classifiers skip 3.8 and 3.9
Two pieces of version metadata disagree about which interpreters are supported, and they disagree in a way that is easy to miss.
setuptools.setup(
    name="deepctr",
    version="0.9.4",
    author="Weichen Shen",
The install floor is declared separately as `python_requires=">=3.7"`, so pip will install on 3.7 and everything above. The classifier list, though, names Python 3, then 3.7, then jumps to 3.10, 3.11 and 3.12. There is no 3.8 entry and no 3.9 entry.
So the packaging metadata makes no claim about two interpreters that pip will happily install onto, and the boundary that decides which h5py branch you get is 3.9, one of the two versions that went unclassified.
The practical consequence is modest but real. If you are on 3.8 you take the exact h5py 2.10.0 pin with nothing in the metadata telling you that combination was ever tested, and on 3.9 you get the modern branch while also being unlisted. Read the version claim as a floor rather than as a support matrix.
Mixing the private Keras namespace breaks model loading
The compatibility notes contain one warning that deserves to be read as a rule rather than a tip.
Use public `tensorflow.keras` APIs in your own code and examples. Avoid mixing `tensorflow.python.keras` with `tensorflow.keras`, because `tensorflow.python.*` is private TensorFlow API and can break model serialization or optimizer and metric loading across TensorFlow versions.
The mechanism is straightforward once stated. Code written against the private namespace resolves to a different module path than code written against the public one, and anything that saves a model or reloads an optimizer or a metric has to agree on that path. Change TensorFlow versions and the two can stop agreeing.
The consequence for you is that older tutorials and blog posts become a hazard. A snippet that imports from `tensorflow.python.keras` will often appear to work, and then fail at save or restore time rather than at import time, which is the worst place to discover it. If you are porting examples from elsewhere, the import line is the first thing to check.
Two interfaces for two different sizes of job
DeepCTR offers a tf.keras.Model-like interface for quick experiment and a tensorflow estimator interface for large scale data and distributed training. These are two distinct APIs, and choosing between them is an early decision rather than a later optimisation.
The keras-like path gives you `model.fit()` and `model.predict()`, which is the fast route to a working baseline and the reason most people arrive here.
The estimator path is the one aimed at real volume. The examples directory reflects that split directly: there are separate runners for the pandas estimator case and the TFRecord estimator case, and the Criteo sample ships as both a text file and a pair of TFRecord files, train and test, with a generator script to produce them.
The consequence is that the framework does not hide the choice. If your data already lives in TFRecord files, the estimator path is the one to read first. If it is a pandas frame of modest size, the fit and predict path will get you to a number far sooner, and the distributed story can wait until it is a real constraint.
Three and a half years between v0.9.3 and v0.9.4
The release history has a shape worth noting before you pin anything. v0.9.2 was published on 2022-10-16 and v0.9.3 on 2022-11-10, three weeks later. Then nothing until v0.9.4, published on 2026-04-16.
That is a gap of about three and a half years followed by a single release, and the version is still below 1.0 after all of it. The last push to the repository was 2026-10-11, so the branch has moved since.
One detail explains how a gap like that can be closed quietly. The version string is written literally into setup.py rather than read from a separate file, so cutting a release means editing that line by hand, and nothing in the repository derives the version from the commit history.
The consequence for a user is that, if you are upgrading from anything earlier, it is worth checking what changed in the packaging before you assume a behaviour is unchanged.
Travis configuration and GitHub Actions both sit in the tree
The repository carries two continuous integration definitions, which is a small piece of housekeeping evidence about how the project has been maintained.
The top level contains a `.travis.yml`, which is the configuration file for the older hosted CI service. Alongside it sits a `.github/` directory, and the README's badges point at two GitHub Actions workflows, one named `ci.yml` and the other `ci2.yml`, plus a coverage report and a code grade badge.
So the `.travis.yml` is likely a leftover from a previous setup, and the README's CI badges point at the two workflows in `.github/`.
The consequence is that a contributor reading the repository root gets two signals about how to test, and only one of them is current. The practical route is to read the workflow file to find out what the CI actually executes. The same root holds a `.readthedocs.yml` for the documentation build, which is where the hosted docs at deepctr-doc.readthedocs.io come from.
What DeepCTR cannot do for you, and what that costs
Four limits are worth stating together, because together they decide whether this is your library.
It does not choose or carry TensorFlow. TensorFlow is absent from install requirements, so the dependency graph you inherit is the one you assemble, and the compatibility statement spans from tf 1.15 to tf 2.x. Upgrading TensorFlow is your risk, and the private-API warning shows exactly where that risk surfaces.
It does not demonstrate production scale. The bundled data is sample-sized: Criteo, Avazu, MovieLens and a census income sample, with a shell script to run everything. Nothing here tells you how to feed it a real feature store.
It is TensorFlow only. For PyTorch there is a separate project, DeepCTR-Torch, alongside DeepMatch for matching tasks. Two repositories rather than one abstraction.
And the catalogue is of published work. Every row in the models table pairs an architecture with a paper, and the entries start at CIKM 2015. Anything the table does not list is yours to implement on top of the layers.
Editorial conclusion
Use DeepCTR when you are already committed to TensorFlow, you want a published CTR architecture as a starting point rather than from scratch, and your data is small enough that sample files and fit and predict are enough. Do not expect it to choose a TensorFlow version for you or to carry you to production scale, because TensorFlow is absent from its install requirements and the bundled examples are sample-sized. Before pinning a version, read what changed in v0.9.4, which came after a long quiet period, and keep all model code on the public tensorflow.keras API, since mixing in the private tensorflow.python namespace is the failure mode the project calls out by name.
Frequently asked questions
How do I install DeepCTR?
DeepCTR does not pin or install TensorFlow. Install a TensorFlow build matching your Python, NumPy, CPU or GPU and operating system first with pip install tensorflow, then run pip install deepctr.
Which Python versions does DeepCTR support?
setup.py declares python_requires=">=3.7", so pip installs on 3.7 and above. The classifiers name Python 3, 3.7, 3.10, 3.11 and 3.12, with no entry for 3.8 or 3.9, which are also the boundary for the h5py dependency marker.
What does DeepCTR depend on?
Three packages: requests, and h5py selected by environment marker, at 3.7.0 or newer on Python 3.9 and up, or exactly 2.10.0 below 3.9. TensorFlow is deliberately not among them.
Does DeepCTR work with PyTorch?
No. DeepCTR is built on TensorFlow and exposes tf.keras.Model-like interfaces plus a tensorflow estimator interface. A separate project, DeepCTR-Torch, covers the PyTorch case, and DeepMatch covers matching tasks.
Which TensorFlow versions does DeepCTR support?
The README states compatibility with both tf 1.15 and tf 2.x. The newest release is v0.9.4, published on 2026-04-16, following v0.9.3 from 2022-11-10, and setup.py hardcodes the version string 0.9.4 rather than deriving it.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shenweichen-deepctr)Star history chart for your README
[](https://hysenlabs.com/projects/shenweichen-deepctr)Was this useful?