Archived with MIT, an ee directory on its own licence, and a Postgres password in the compose file
Context layer platform in your infrastructure
At a glance
- What is it?
- Skald is a RAG platform with a plug and play API, seven SDKs in seven repositories, and a self hosting story built on pgvector. The repository was archived on 2026-05-31. What is left behind is unusually transparent about its licensing split and its defaults, including a database password in the trial compose file and analytics libraries in a product you are told to run yourself.
- Who is it for?
- Skald is worth reading for its licensing arrangement rather than its code, because it does the awkward thing honestly: an MIT repository with a separately licensed enterprise directory, a companion repository with that directory removed, and a statement that the hosted service runs the fully open build. Two things to weigh before you adopt it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
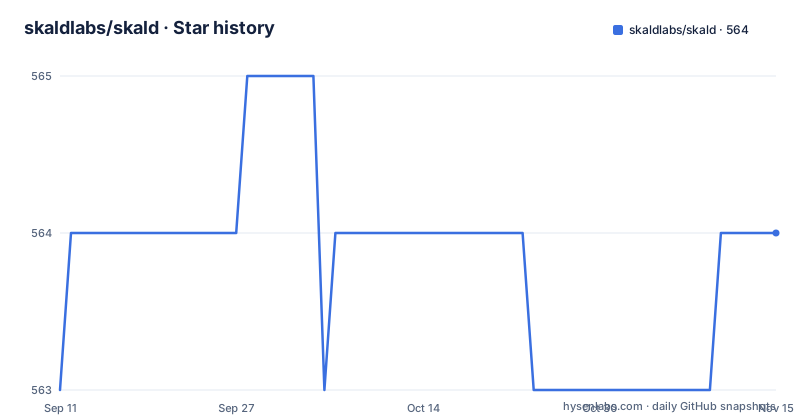
Star history
- skaldlabs/skald564 ★ · +1
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| skaldlabs/skald | 563 | 564 |
1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Archived in May, with a feature list still offering to build your SDK
The repository is archived, and the last commit is dated 2026-05-31. There are no releases, no tags, and 26 open issues against 565 stars and 38 forks.
Archival does not neutralise the readme, so the document still contains a claim that cannot be met. Under features, the line about developer experience promises SDKs for every major language and then says that if yours is missing you should open an issue and they will build it. Seven SDKs are already linked in the badge row, across Python, Node, Go, Ruby, PHP, C#, an MCP server and a CLI, each in its own repository rather than in this one.
The distinction between the platform and the SDKs matters for anyone adopting it now. This repository holds the server: a `backend/`, a `frontend/`, an `embedding-service/`, three Compose files, an Nginx configuration, an init directory mounted into the database container, and an `ee/` directory. The clients live elsewhere, so an archived platform with a live SDK ecosystem is a different maintenance situation from an archived client, and the readme does not say which of the eight linked repositories are still maintained.
Other dated signals in the same document. The retry instructions in the Node example reference response codes that a version gate would define, and the roadmap sentence in the feature description still promises configurable chunking as an upcoming item. None of that is wrong in a readme, all of it is only useful with the archival date next to it.
MIT for the tree, a separate licence for ee, and the cloud running the FOSS build
The licensing section is the most carefully written part of the readme and the reason to read this repository at all.
The repository is available under MIT, with one stated exception: the `ee` directory, which has its own licence file. That is an unusual and honest shape. Rather than claiming the whole tree is MIT and quietly shipping closed files, the document points at a second licence and tells you where it lives. The tree is consistent with that: there is a root `LICENSE`, an `ee/` directory, a `docker-compose.ee.yml` alongside the plain and self hosted Compose files, and a separate repository for the fully open variant.
That last part is the sentence worth stopping on. If you need only free and open source code, there is a `skald-foss` repository containing everything from this one with the `ee` directory removed, described as fully featured, and the document states that the cloud offering actually runs that build. Enterprise Edition is then positioned for on premises deployments.
So the hosted product is the open build, the proprietary directory is aimed at people running it themselves, and the split is drawn on a line that is visible in the tree rather than buried in a feature comparison. For a buyer that removes the usual ambiguity: the thing you would deploy to learn from is the same code the vendor runs.
For anyone who already deployed before archival, the practical consequence is that the enterprise directory's terms still govern what they are running, and the MIT covering the rest of the tree does not reach into it.
The trial path starts Postgres with the password 12345678 on a published port
The try it instructions are three commands:
git clone https://github.com/skaldlabs/skald
cd skald
echo "OPENAI_API_KEY=<your_key>" > .env
docker-compose up
Two things to notice about the third and fourth. Writing the environment file with `echo` truncates anything already there, so a `.env` you had configured gets replaced rather than merged, and the tree does ship both `.env.example` and `.env.prod.example` as reference files. And the only configuration the quick start asks for is a model provider key, which is the direct opposite of the no third party services claim the document makes further down.
That claim is real but conditional. You can deploy with no third party dependencies at all, including no external model provider, and the document is clear about the price: you host your own inference server and use a local embeddings service, which is provided in a Compose profile the document calls `local`. So there are two configurations, one where you need an external key and one where you run an inference server and an embedding service yourself, and the quick start only covers the first.
The database side is worth reading before you start it. The Compose file uses a pgvector image on PostgreSQL 17, which is where vector storage lives, and it sets the database name, the user and a password written literally as `12345678`, then publishes the container's port 5432 to the host. A local init directory is mounted into the database entry point, so schema and extensions are applied on first boot.
That is fine on a laptop and wrong on a machine with forwarded ports. The password is in the repository, the port is on the host interface rather than loopback, and nothing in the readme tells you to change either before starting.
Configurable chunking appears in the sentence that says chunking is soon
The feature description sets out what can be tuned: configurable vector search parameters, reranking, models, query rewriting, chunking, and more. Then it qualifies the list. Chunking is annotated as forthcoming.
So the sentence promises tunability and marks one of the five named knobs as not yet delivered. That is honest, and it lands in a specific place: chunking is the single most consequential parameter in a retrieval pipeline, since it determines what a retrieved span of text actually contains, and a system that ingests documents well but chunks them on a fixed strategy cannot be tuned past whatever that strategy assumes.
The ingestion description is consistent with chunking existing but not being exposed. Ingestion is listed as covering document parsing, chunking strategy, summaries, tagging, embedding generation and vector storage, while retrieval covers query rewriting, vector search, model chat, chat history and source references. So the pipeline is complete, the strategy is chosen for you, and the document does not say whether the fixed strategy is exposed for reading, only for changing.
The Node example shows the shape of what is exposed. A chat call takes a query and a `rag_config` object with reranking enabled, so the configuration is per request rather than per deployment, and the document does not say whether that object persists or whether every call must repeat it.
The other claims on that page are broader: evaluation tooling for a custom engine, filtering applied to every query, and source references on answers. Those are the parts a reader can verify by running them.
Analytics libraries ship inside a product you are told to run yourself
The frontend dependency list includes two services that phone home. `posthog-js` is a product analytics client and `@sentry/react` is an error reporting client, both in the application bundle rather than behind a flag or an environment check.
That sits oddly against the product's pitch. The headline is production ready RAG in your infrastructure, the deploy story is a Compose file on your own machine, and one of the selling points is running with no third party dependencies at all. Those are two analytics services whose only destination is someone else's server.
To be fair to the design, this is the normal consequence of shipping a UI that is both hosted and self hosted from one codebase, and many self hostable projects make the same choice. The distinction is that nothing visible in the readme mentions either library. The no third party services section is framed entirely as a substitution problem, replacing the model provider and the embedding service, and does not mention telemetry. So a reader deciding whether Skald can run with no external calls has to find the analytics question in the manifest rather than in the documentation.
There is also `react-markdown` with `remark-gfm` and `react-syntax-highlighter` in the same list, which is a reasonable stack for rendering answers with citations, and `@radix-ui` primitives throughout with a `components.json` at the root, which is the shadcn convention. Those are choices worth having. The two analytics clients are the ones to decide about.
Everything else in the frontend is ordinary: routing, form handling with resolvers, theming, date handling, toasts, icons, and axios.
The deploy script points at a fly.toml the tree does not list
The root manifest is private, at version 0.0.1, and describes the frontend rather than the platform. There is no publish configuration because nothing here is published: the server is deployed with Compose and the UI is deployed to Fly.io, with a script that reads:
flyctl deploy -c ui.fly.toml -a skald-platform-ui --remote-onlyTwo observations. The script names a config file, `ui.fly.toml`, which does not appear among the top level entries of the repository tree, so running the documented deploy from a fresh clone fails on a missing file. And the app name is hardcoded to `skald-platform-ui`, so a fork cannot deploy to its own Fly.io app without editing the script.
The rest of the tooling is conventional and well chosen. Node 18 or newer is required, pnpm holds the lockfile, mise pins tool versions, husky is wired through a prepare script, and lint staged runs eslint and prettier on JavaScript and TypeScript files plus prettier on JSON. Node and tooling are declared in a `mise.toml` rather than left to whatever is on the machine.
One gap in that tooling: the lint script is scoped to `eslint frontend`, so the backend and the embedding service are outside it. Type checking is a build step rather than a separate script, and the build runs the TypeScript project references before Vite.
The tree also carries a `mock_data/` directory and a Python script named for pushing mock documents, which is how you get content into a fresh install for evaluation, and editor configuration directories for Cursor and VS Code alongside a `CLAUDE.md`.
Editorial conclusion
Skald is worth reading for its licensing arrangement rather than its code, because it does the awkward thing honestly: an MIT repository with a separately licensed enterprise directory, a companion repository with that directory removed, and a statement that the hosted service runs the fully open build. Two things to weigh before you adopt it. It is archived, so the 26 open issues and any dependency bumps are yours to carry, and the promise to build an SDK in your language on request cannot be met by a project that no longer accepts work. And the analytics libraries in the frontend are a deliberate choice you may want to change, since PostHog and Sentry in a build you are told to run in your own infrastructure is a different proposition from the same libraries in a hosted service. If you deploy the FOSS build, verify what it sends before you point it at anything private.
Frequently asked questions
Is Skald still maintained?
No. The repository is archived and its last commit is dated 2026-05-31, with 26 open issues and no releases or tags. The readme still offers to build an SDK for any language on request, which a project that no longer accepts work cannot deliver.
What licence does Skald use, and what is the ee directory?
The repository is MIT except for the `ee` directory, which carries its own licence. A companion `skald-foss` repository contains the same code with that directory removed, and the readme states the cloud offering runs that fully open build while Enterprise Edition is aimed at on-premises deployments.
Can Skald run without any third party services?
Yes, but you then host your own LLM inference server and use the local embeddings service the project provides in a Compose profile called `local`. The quick start does not cover that path, since it writes an external model provider key into a `.env` file and starts the stack.
Which database does Skald use for vector storage?
pgvector on PostgreSQL 17, started from the Compose file. That file also sets a fixed database password and publishes port 5432 on the host, and mounts a local init directory into the container entry point to apply schema on first boot.
Which Skald SDKs exist and where do they live?
Seven clients are linked across separate repositories: PyPI, npm for Node, GitHub for Go, RubyGems, Packagist for PHP, GitHub for C#, plus an MCP server and a CLI on npm. The platform repository itself is private at version 0.0.1 and publishes nothing.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skaldlabs-skald)Star history chart for your README
[](https://hysenlabs.com/projects/skaldlabs-skald)Was this useful?