skrub reads its version from a text file while setuptools_scm sits in the build requires
Machine learning with dataframes
At a glance
- What is it?
- skrub is a Python library for machine learning with dataframes, BSD-3-Clause, maintained by five named authors and shipping to PyPI as 0.11.0. The packaging metadata has a few things worth reading closely: a static version file next to a setuptools_scm requirement, ten runtime dependencies of which one has no version floor, and a documentation stack pinned below Sphinx 9 for a reason spelled out in a TODO.
- Who is it for?
- skrub suits teams already working in the scikit-learn and pandas ecosystem who want dataframe oriented machine learning without hand rolling the preprocessing steps, and its bundled documentation means you can read examples offline after install.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
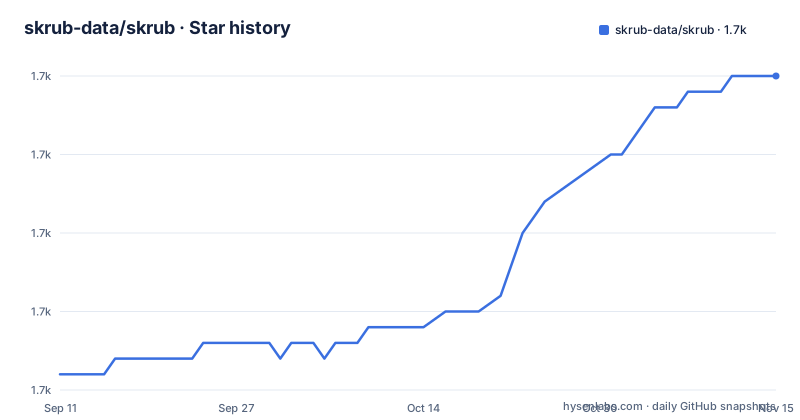
- skrub-data/skrub1,670 ★ · +19
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| skrub-data/skrub | 1.7k | 1.7k |
19 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version comes from a file, not from a tag
The build system asks for two tools and then uses only one of them for the version:
[build-system]
requires = ["setuptools>=77.0.3", "setuptools_scm[toml]>=8"]
build-backend = "setuptools.build_meta"
The project table marks the version dynamic, and the value is resolved from a plain file in the package:
[tool.setuptools.dynamic]
version = { file = "skrub/VERSION.txt" }
So `setuptools_scm` is a declared build requirement while the shipped number comes from `skrub/VERSION.txt`, read at build time. That matters when you are reasoning about what a release is: the number in the wheel is whatever that file said when the build ran, and the repository root carries `RELEASE_PROCESS.rst` to say how a release is put together. The recent tags on the releases page are plain numbers, `0.11.0`, `0.10.1` and `0.10.0`, with no `v` prefix, which matches a project that tracks its version by hand in a file rather than by tagging convention.
None of that is a defect on its own. It is simply a different mechanism from the one the build requirement suggests, and knowing which one is live tells you where to look when two builds of the same commit report different versions.
Ten runtime dependencies and one without a floor
The dependency list is short and almost entirely pinned with a lower bound:
dependencies = [
  "numpy>=1.23.5",
  "pandas>=1.5.3",
  "scikit-learn>=1.5.2",
  "scipy>=1.9.3",
  "jinja2>=3.1.2",
  "matplotlib>=3.6.1",
  "requests>=2.27.1",
  "pydot",
  "cloudpickle>=3.0",
  "joblib>=1.4.0",
]
`pydot` is the single entry with no version constraint. In an otherwise careful list that is the kind of line worth asking about before you lock a build, because the resolver is free to take whatever it finds first.
The set itself says something about what the library does. Four entries are the numeric and dataframe stack, and then there are five that are not modelling libraries at all: jinja2 for templating, pydot for graph description files, matplotlib for figures, cloudpickle for serialising objects, and joblib for parallelism. A dataframe machine learning tool that pulls in a template engine and a graph writer is producing artifacts, not only fitting models, and requests is there for the same reason.
Those floors are also old relative to the Python the project claims. numpy 1.23 and pandas 1.5 are the era of the 1.x series, while the classifiers reach Python 3.14.
The documentation and examples travel inside the package
The README spends two sentences on where to read, and they point somewhere unusual: the documentation and examples are bundled with the package itself, under `skrub/_docs`. After installing, you find the directory with two lines:
import skrub
print(skrub.__docs_dir__)
That is the whole mechanism, and it is a deliberate choice rather than a convenience. A wheel that carries its own examples can be read on a machine with no network, on a laptop in an environment where building the docs is not possible, and by anyone reviewing what a release actually contains.
The website holds the rest. The examples gallery sits under `https://skrub-data.org/stable/auto_examples`, there is a separate learning materials index for people who want the narrative version, and the README's own homepage is `https://skrub-data.org/`. Installing instructions are also on the site rather than in the README, which says only that skrub installs via `pip` or `conda` and links the page for detail.
In the repository, the sources live in `doc/` and the packaged copy lives in `skrub/_docs`, so there are two locations to keep in mind when you go looking for a missing example.
The doc stack runs examples in Pyodide and pins Sphinx below 9
The development extras are where the project's real shape shows. The documentation group pulls in the usual sphinx stack, and then adds two things that stand out: `jupyterlite-sphinx` with `jupyterlite-pyodide-kernel`, which runs the example notebooks in the browser through Pyodide, and `sphinx-llms-txt`, which emits an llms.txt view of the documentation.
There is also a deliberate pin with the reason written next to it:
  # TODO: unpin sphinx when incmpatibility with autosummary-accessors is fixed:
  # https://github.com/xarray-contrib/sphinx-autosummary-accessors/issues/165
  "sphinx<9",
The comment names the exact upstream issue, misspelling included, and the package involved is `sphinx-autosummary-accessors`, which is itself listed in the same extras. So the doc build is blocked on a third party extension rather than on anything in skrub, and the pin carries the link needed to remove it.
That combination has a cost worth knowing about: the examples run in a browser kernel, which means they cannot touch your filesystem or your network, so anything the gallery shows has to be self contained. It also means the docs are testable in CI in a way a plain notebook build is not.
Python 3.11 is the floor and the classifier list already reaches 3.14
`requires-python` is set to `>=3.11`, and the classifier list names 3.11, 3.12, 3.13 and 3.14. The other classifiers describe a console oriented, operating system independent library for a science and research audience, and the development status is recorded as `5 - Production/Stable`.
Read those two facts next to the dependency floors and you get the interesting tension. The package claims to support Python 3.14 while accepting numpy as old as 1.23.5 and pandas as old as 1.5.3. Those releases predate recent Python versions by years, so on a fresh 3.14 environment the resolver will not pick them, and the floors are only meaningful for someone on an older interpreter or an older locked set. They function as a compatibility statement rather than as a target.
Five authors are named in the project metadata: Riccardo Cappuzzo, Jerome Dockes, Guillaume Lemaitre, Vincent Maladiere and Gael Varoquaux. The tree is a conventional scientific Python layout with `skrub/` as the package, `doc/` for sources, `build_tools/`, and a `pixi.lock` beside `pyproject.toml`, so there is a pinned pixi environment in addition to the pip and conda routes the README mentions.
CircleCI, Codecov, black and a blame ignore list
The tooling in the tree is worth a quick pass because it tells you what the project considers non negotiable. CI lives in `.circleci/` and the badge row points at CircleCI with the `main` branch, so the primary continuous integration run is CircleCI rather than GitHub Actions. Coverage is a separate concern with `codecov.yml` and `.coveragerc` at the root and a Codecov badge in the README, and there is a `Zenodo` badge wired to a DOI rather than a version.
Two files point at how the history is managed. `.git-blame-ignore-revs` exists, which is the standard way to keep release or formatting commits out of blame views, and it pairs with `CHANGES.rst` as the changelog and `RELEASE_PROCESS.rst` as the release procedure. `.pre-commit-config.yaml` is present, and the README carries a black code style badge, so formatting is enforced before a commit lands rather than at review time.
Alongside those sit the governance files: `CODE_OF_CONDUCT.md`, `CONTRIBUTING.rst` and `LICENSE.txt`. The licence is BSD-3-Clause, declared in the project table and named in `license-files = ["LICENSE.txt"]`, so the file and the metadata agree. The readme itself is `README.rst`, not Markdown, matching the reStructuredText used elsewhere in the project.
One Zenodo DOI for citations, and a contributing section that asks you to spread the word
The citation instruction is short: if you use skrub in a scientific publication, cite the Zenodo record, whose DOI is 10.5281/zenodo.22231586. That same DOI is the target of the Zenodo badge. So the archive is the citation path, while the release tags carry bare version numbers, and the two are separate identifiers for the same software.
The contributing section opens in an unusual order. The first thing it asks is that you spread the word, and it also invites you to star the repository. Only after that does it turn to the substance: use cases and challenges are wanted in the Discussions section, bugs and enhancements go through the issue tracker, and direct contributions are explained on a contributing page on the website. There is a Discord server link as well.
So the project asks for three different things in descending order of effort, publicity first, discussion second, code third. Nothing in the README explains what good looks like for a pull request, which is what the contributing page on the site is for.
Editorial conclusion
skrub suits teams already working in the scikit-learn and pandas ecosystem who want dataframe oriented machine learning without hand rolling the preprocessing steps, and its bundled documentation means you can read examples offline after install. Check three things first: that the dependency floors in pyproject.toml, which reach back to numpy 1.23 and pandas 1.5, still resolve against your environment, whether pydot without a lower bound is acceptable in a locked build, and which version you actually get, since the number comes from a file rather than from a tag.
Frequently asked questions
What is skrub, the Python library?
A Python library that facilitates machine learning with dataframes, released under BSD-3-Clause. The project metadata names five authors and requires Python 3.11 or newer, with classifiers for 3.11 through 3.14 and a development status of Production/Stable.
How do I install skrub?
The README says skrub installs via pip or conda and sends you to the installation instructions page on the website for detail, without spelling out a command. The current release is 0.11.0, and the homepage is https://skrub-data.org/.
Where are the skrub documentation and examples?
Bundled inside the package, under `skrub/_docs`, so you can read them without a network. After installing, run `import skrub` and `print(skrub.__docs_dir__)` to find the directory. The website also hosts an examples gallery and separate learning materials.
How do I cite skrub in a paper?
Through its Zenodo record, DOI 10.5281/zenodo.22231586, which is also what the Zenodo badge in the README points at. Release tags carry bare version numbers such as 0.11.0 rather than a v prefix.
What does skrub depend on at runtime?
Ten packages: numpy, pandas, scikit-learn, scipy, jinja2, matplotlib, requests, pydot, cloudpickle and joblib. Nine carry a lower bound, and pydot is the one entry with no version constraint.
Which Python versions does skrub support?
Python 3.11 and newer, with classifiers for 3.11, 3.12, 3.13 and 3.14. The dependency floors are considerably older, including numpy 1.23.5 and pandas 1.5.3, so on a new interpreter the resolver will pick newer releases than those minimums.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skrub-data-skrub)Star history chart for your README
[](https://hysenlabs.com/projects/skrub-data-skrub)Was this useful?