TextBlob: pip install is half the setup, and the corpora arrive separately
Simple, Pythonic, text processing--Sentiment analysis, part-of-speech tagging, noun phrase extraction, translation, and more.
At a glance
- What is it?
- TextBlob wraps common NLP tasks in one object built on NLTK, but the install is two steps because the corpora come from a second command. Version numbering is the other trap: GitHub releases stop in 2013 while the package declares 0.20.1.
- Who is it for?
- Use TextBlob for quick scripting where a tag list, a noun phrase list and a per-sentence polarity are enough, on Python 3.10 or later. Do not choose it when you need a model family beyond Naive Bayes and Decision Tree, or when you want its dependency surface to stay small, since the transitive weight of NLTK comes with it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
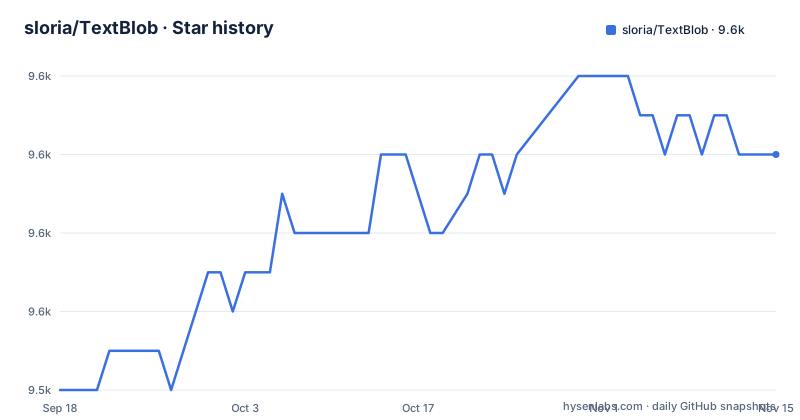
- sloria/TextBlob9,554 ★ · +6
| Repository | 2026-09-18 | 2026-11-15 |
|---|---|---|
| sloria/TextBlob | 9.5k | 9.6k |
6 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
pip install -U textblob is half the setup, then download_corpora fetches the models
The install is two commands, and the second one is the part people skip:
$ pip install -U textblob
$ python -m textblob.download_corpora
The first pulls the package. The second runs a module inside the package as a script, and that is what pulls the language resources the analyzers need. Nothing about the first command tells you this is coming, so a fresh environment will install cleanly and then behave oddly on first use of tagging, sentiment or lemmatization, which is where corpora are read. The upside of the split is that the corpora are downloaded once per machine rather than vendored into the wheel, so the install stays small. The downside is that a container image, a CI job or a colleague's laptop each need that second command run before the library is usable.
One runtime dependency, nltk>=3.9, and Python 3.10 as the hard floor
The packaging metadata is small enough to read in one screen, and the dependency list is a single entry: nltk>=3.9. That is the whole runtime requirement set, and it is the floor to check first, since requires-python is 3.10 or later and the classifiers cover Python 3.10 through 3.14. So a project still on 3.9 is excluded outright, and a project on 3.13 or 3.14 is inside the declared range. The second-order consequence is that TextBlob's footprint is not really one package, it is NLTK plus whatever NLTK brings, and TextBlob adds nothing to that except its own layer. For anyone with a dependency policy that inspects transitive trees, this is the line to look at rather than the friendly one-line install, and for anyone choosing between libraries the practical question is whether you already have NLTK in the environment.
pattern is named as a companion, but it is not a declared dependency
The front page says TextBlob stands on the giant shoulders of NLTK and pattern and plays nicely with both. The metadata says otherwise. The dependencies array holds nltk>=3.9 and nothing else, so pattern appears in documentation and in the project keywords without being installed for you. Read that as a fact about the packaging rather than a mistake to report: if any behavior you rely on comes from pattern, it has to be installed separately and version-matched by you, and nothing in the front page says which feature depends on which of the two. The same asymmetry shows up with the model extensions. Adding new models or languages is listed as a feature, done through extensions, which means the language and model coverage you get out of the box is exactly what the single declared dependency brings, and everything wider is code you add.
One blob object exposes tags, noun phrases and sentences as separate views
The API in the front page example is short enough to take in at a glance:
blob = TextBlob(text)
blob.tags  # [('The', 'DT'), ('titular', 'JJ'),
#  ('threat', 'NN'), ('of', 'IN'), ...]

blob.noun_phrases  # WordList(['titular threat', 'blob',
#            'ultimate movie monster',
#            'amoeba-like mass', ...])

for sentence in blob.sentences:
    print(sentence.sentiment.polarity)
# 0.060
# -0.341
Three views over the same text, with tags as part-of-speech pairs and noun phrases returned as a WordList of chunk strings. The sentiment access is the one to read carefully, because the example walks blob.sentences and prints each sentence's polarity, giving 0.060 for the first sentence and -0.341 for the second. A single number for the whole document is not something this example demonstrates, so aggregating a score across sentences is your code, not a documented property. The rest of the feature list covers tokenization, word and phrase frequencies, n-grams, parsing, inflection and lemmatization, and spelling correction.
Classification names two model families, and everything wider is an extension
TextBlob covers a broad surface, but the modeling surface is narrow and stated. Classification is offered as Naive Bayes and Decision Tree, and those are the only families named. Sentiment analysis, part-of-speech tagging and noun phrase extraction are the headline tasks, with tokenization splitting text into words and sentences, word and phrase frequency counting, parsing, n-grams, inflection covering pluralization and singularization, lemmatization, spelling correction, and WordNet integration. The stated route to anything else is extensions, described as a way to add new models or languages. So for a reader the dividing line is clear. Anything inside that list works out of the box once corpora are present, and anything beyond it, including a different classifier or a language the bundles do not cover, is a model you add and wire up yourself.
GitHub releases stop at 0.7.0 in 2013 while the package declares 0.20.1
The release history on the repository is not the version history you get. The published releases are 0.7.0 from 2013-09-26, 0.6.3 from 2013-09-15 and 0.6.3-alpha from 2013-09-14, while the project metadata declares version 0.20.1. That gap is the first thing to know before judging activity, and it cuts both ways: the releases page makes a living library look abandoned, while the metadata says otherwise. The last push to the default branch dev was 2026-11-01, and the default branch being dev rather than main means a clone gives you the development line. Changelog information is not on the releases page at all, it is linked from the documentation site, so that is the place to look for what actually changed between the version you have and the one you want.
A src layout with flit, uv dependency groups, tox and renovate as the maintenance surface
The tree shows a modernized project even though the release tags look old. Source lives under src/, and the build backend is flit_core with an upper bound of flit_core<5, which is why the project metadata rather than a setup.py carries the name and version. The source distribution is configured to include tests/, CHANGELOG.rst, CONTRIBUTING.rst, tox.ini and NOTICE, so those files travel with the package instead of living only in the repository. Development is grouped rather than flattened: separate dependency groups for docs, lint, tests and dev, with dev as the default, and the dev group pulls in tox, pyright and ruff on top of pytest and numpy. Around that sit tox.ini, uv.lock, renovate.json for dependency updates, a pre-commit configuration, and .konchrc for the konch REPL. Documentation builds need sphinx, sphinx-issues and PyYAML, which is the group a docs contributor needs.
Editorial conclusion
Use TextBlob for quick scripting where a tag list, a noun phrase list and a per-sentence polarity are enough, on Python 3.10 or later. Do not choose it when you need a model family beyond Naive Bayes and Decision Tree, or when you want its dependency surface to stay small, since the transitive weight of NLTK comes with it. Before you start, run the corpora download, read the changelog on the documentation site rather than the GitHub releases page, which stops at 0.7.0 in 2013, and remember that the default branch is dev.
Frequently asked questions
How do you use TextBlob for sentiment analysis?
Create a TextBlob from your text and walk its sentences, reading sentence.sentiment.polarity on each one. In the front page example, worked over a paragraph about The Blob, the printed values are 0.060 and -0.341, one per sentence rather than one for the document.
How do I install TextBlob?
Run pip install -U textblob, then run python -m textblob.download_corpora to fetch the language resources the analyzers need. The package requires Python 3.10 or later and its only runtime dependency is nltk>=3.9.
What is TextBlob in Python NLP?
It is a Python library for processing textual data with a simple API for common natural language processing tasks: part-of-speech tagging, noun phrase extraction, sentiment analysis and classification. It stands on NLTK and pattern and is described as playing nicely with both.
What does TextBlob use sentiment analysis for?
Sentiment analysis is one of the listed features, alongside part-of-speech tagging, noun phrase extraction, classification with Naive Bayes and Decision Tree, tokenization, n-grams, parsing, spelling correction and WordNet integration. Scores are read per sentence through sentence.sentiment.polarity.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sloria-textblob)Star history chart for your README
[](https://hysenlabs.com/projects/sloria-textblob)Was this useful?