Three entrypoint names, and the file extension decides the algorithm
Automagically synchronize subtitles with video.
At a glance
- What is it?
- ffsubsync shifts a subtitle file so it lines up with the audio, and it does that with voice activity detection unless the reference you give it is itself a subtitle file. It installs as a Python package, ships a Docker image with ffs as its entrypoint, exposes run() for embedding in your own UI, and has a browser build that does the same work with ffmpeg.wasm and never uploads anything.
- Who is it for?
- Take ffsubsync when you have a video and an out-of-sync subtitle file and you want the offset found for you, and when you are happy to have ffmpeg on the machine for the CLI, or to use the browser build, which decodes with ffmpeg.wasm and needs no install. Leave it if your reference is going to be a very long remote file over a flaky connection and you do not want to think about which of the three remote flags to reach for.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 114 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
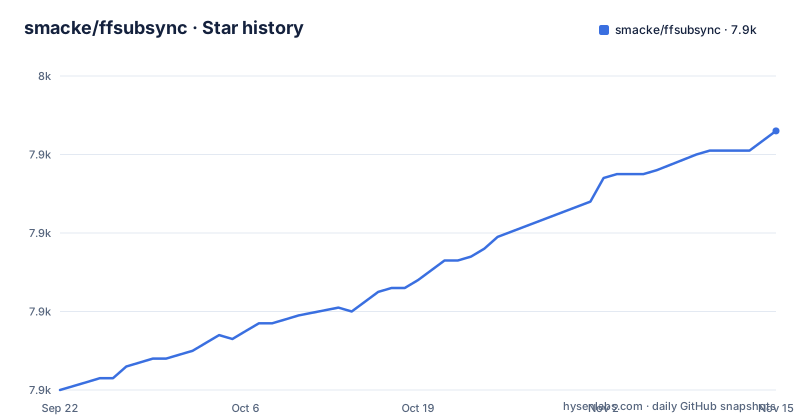
- smacke/ffsubsync7,946 ★ · +66
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| smacke/ffsubsync | 7.9k | 7.9k |
66 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three names for one program, and the extension picks the algorithm
The Usage section opens by solving a problem before explaining anything. It says ffs, subsync and ffsubsync all work as entrypoints, and the example is:
ffs video.mp4 -i unsynchronized.srt -o synchronized.srtThree console scripts, one program. That is a compatibility decision rather than a feature. setup.py registers all three against the same target, so a script written against any of them keeps working.
The interesting decision comes next, and it is one line in the README: ffsubsync uses the file extension to decide whether to perform voice activity detection on the audio or to directly extract speech from an srt file.
So there are two algorithms and the filename selects between them. Give it a video or an audio file and it has to listen, running a voice activity detector over the audio to find where speech actually is. Give it an srt file and it does not listen at all, it reads the timings that are already there. That is why the second form works:
ffsubsync reference.srt -i unsynchronized.srt -o synchronized.srtThe README's scenario for it is specific and worth repeating: you have a correctly synchronised subtitle file in a language you do not read and an unsynchronised one in your own language, so the timings exist and only need transferring.
Auto-detection writes .synced.srt and then skips its own output
Omit the input flag and the tool starts looking for the file itself. The README's description: if you omit -i, ffsubsync auto-detects input subtitles sitting next to the reference that share its name, so you can simply run:
ffs video.mp4The behaviour it then describes is careful in a way that small tools usually are not. It picks up files like video.srt and video.en.srt from the reference's directory and writes the synced result for each to a <name>.synced.srt alongside it, so the originals are left untouched.
And then the part that makes re-running safe: previously-synced *.synced.srt outputs are skipped.
That is the detail worth pausing on. Without it, a second run would find video.synced.srt, treat it as another input, and produce video.synced.synced.srt. Skipping its own output means the command is idempotent in practice even though it is doing directory listing rather than explicit input.
If you do want the originals replaced, there is a flag for it: add --overwrite-input to overwrite the detected files in place instead. And the auto-detection has two boundaries: it is skipped when subtitles are piped in on stdin, and it is local-only, so it is skipped for remote references.
A remote reference streams, which is why three flags exist
The reference does not have to be a local file. The README says the reference can also be a remote URL, that anything ffmpeg can read directly works as a video or audio reference, and that remote subtitle files work as a reference too:
ffs "https://example.com/video.mp4" -i unsynchronized.srt -o synchronized.srt
ffs "https://example.com/reference.srt" -i unsynchronized.srt -o synchronized.srt
Supported protocols are http(s), rtmp, rtsp and ftp.
And then the cost is stated plainly: processing streams the reference over the network, so it depends on connection stability, and for large or flaky sources downloading first is more reliable.
That sentence is the reason three flags exist in the rest of the section, each attacking the stream from a different direction.
The first truncates it. --max-duration-seconds N processes only the first N seconds, measured from --start-seconds, which the README notes is especially helpful for remote references because ffmpeg stops reading, and therefore downloading, once that duration is reached:
ffs "https://example.com/video.mp4" -i unsynchronized.srt -o synchronized.srt --max-duration-seconds 600The second avoids holding the stream open at all. --extract-audio-first copies the remote audio track to a local temp file with no re-encode and runs detection on that instead. It is ignored for local references and composes with the duration flag.
--multi-segment-sync samples the whole reference instead of the first N seconds
Truncating a long reference is fast and wrong in a specific way, and the third flag exists to fix that.
The README's framing: for long references where --max-duration-seconds would miss desync that only shows up later, --multi-segment-sync instead samples several short segments spread across the whole reference and runs speech detection on just those.
ffs "https://example.com/video.mp4" -i unsynchronized.srt -o synchronized.srt --multi-segment-syncThe important sentence is the one explaining why this is not a different algorithm. Only the sampled audio is extracted, and for remote references downloaded, but because each segment keeps its true position on the timeline, the usual framerate-ratio and offset search is unchanged. So a framerate mismatch is still detected and corrected.
That is a well-designed compromise. You download a fraction of the file, you lose no information about where in the timeline the speech was, and the offset arithmetic still runs over the whole reference.
Three parameters tune it and their defaults are given. --segment-count N defaults to 8. --skip-intro-outro skips the first 30 seconds and the last 60, which the README says often lack dialogue. And --parallel-workers N defaults to 4 and overlaps segment downloads.
One boundary: it applies to video and audio references only, so the srt-as-reference path never uses it.
The browser build is ffmpeg.wasm, and nothing is uploaded
The README leads with a browser version, and the framing is that it is the primary one rather than a demo.
You can now sync subtitles entirely in your browser, with no Python, no ffmpeg and nothing to install. Your files never leave your machine and nothing is uploaded. There is a link at smacke.github.io/ffsubsync.
The technical note is what makes that claim work: the browser version syncs against either a correctly-synced reference subtitle or a video or audio file, and audio is decoded in-browser with ffmpeg.wasm, with large files read lazily and never uploaded.
That is the same design as the command line tool. Two reference kinds, one being a subtitle file and one being media, and ffmpeg doing the decoding in both cases. Only the ffmpeg changes, from a binary on your path to a WebAssembly module in the page.
The README ends that section by pointing at the alternative: for bulk or scripted use, install the command-line tool below. The repository layout backs the split, with a web/ directory for the browser build and ffsubsync/ for the package.
Three encoding detectors and a WebRTC voice activity detector
The dependency list in requirements.txt is short and two things in it are unusual.
First, there are three separate encoding detectors: chardet, charset_normalizer and faust-cchardet. That is three ways of guessing what a subtitle file's encoding is, which suggests subtitle files in the wild arrive in enough encodings that one detector is not trusted. The chardet entry is conditional on Python 3.7 and above, and pysubs2 is likewise split, one version below 3.7 and another from 1.2.0 at 3.7 and up.
Second, the voice activity detector is webrtcvad-wheels. The detection that finds where speech is in the reference is the WebRTC algorithm, which is why it arrives as a wheel package rather than as a compiled extension you build.
The rest is ordinary: ffmpeg-python to call the binary, numpy with a floor of 1.12.0, srt at 3.0.0 or later for the subtitle format itself, rich and tqdm for terminal output, typing_extensions, and auditok pinned to the exact version 0.1.5, the only exact pin in the file.
One dependency is deliberately not here. setup.py declares an extras group named torch with a comment saying it is the optional dependency for the silero and fused voice activity detection backends, so the heavyweight detector is something you opt into rather than something everyone installs.
Python 3.14 in the container, 3.10 in the classifiers, 3.6 in the README
Three places state a supported Python version and they do not agree, which is worth knowing before you pick an image tag.
The container is built FROM python:3.14-slim. The setup.py classifiers list Python 3.6 through at least 3.10. The README says the package is compatible with Python 3.6 and above.
So the container Python may sit ahead of the versions the package declares, which means the Docker image is not evidence that a given Python works.
The Dockerfile itself is a good piece of engineering and has two details worth naming. It runs ffs --version during the build, which verifies that the installed console script actually starts before the image is finished. And it splits into a builder stage that installs into a virtual environment and a runtime stage that copies only that environment across, with WORKDIR set to /video, which is the directory the run instructions tell you to mount into.
The entrypoint is the shortest line in the file:
ENTRYPOINT [ "ffs" ]So the container takes the same arguments the command line takes, and mounting your working directory is the whole setup.
One more detail for reproducible builds: the build argument FFSUBSYNC_VERSION. Left empty, the image installs from the current working tree; set it and it installs that exact version from PyPI instead, which is how you pin a container without writing a Dockerfile.
Editorial conclusion
Take ffsubsync when you have a video and an out-of-sync subtitle file and you want the offset found for you, and when you are happy to have ffmpeg on the machine for the CLI, or to use the browser build, which decodes with ffmpeg.wasm and needs no install. Leave it if your reference is going to be a very long remote file over a flaky connection and you do not want to think about which of the three remote flags to reach for. Verify three things. Decide whether the reference is a subtitle file or a media file, because the extension is what tells ffsubsync whether to run voice activity detection or to read the timing directly out of an srt. Check that your Python version is covered, since the container is built on python:3.14-slim while the package classifiers list 3.6 through at least 3.10 and the README says compatible with Python 3.6 and above. And remember that re-running is safe only because previously synced *.synced.srt outputs are skipped, so add --overwrite-input if you actually want the originals replaced.
Frequently asked questions
how to use ffsubsync
Install ffmpeg and then pip install ffsubsync, then run ffs video.mp4 -i unsynchronized.srt -o synchronized.srt. Omit the -i flag and it auto-detects subtitles sitting next to the reference that share its name, writing each result to a <name>.synced.srt alongside it and skipping outputs it already synced. Add --overwrite-input to replace the originals instead.
how to install ffsubsync
ffmpeg has to be on the machine first, with brew install ffmpeg on macOS and on your path for Windows. Then pip install ffsubsync, or pip install the git URL for the latest version. There is also a prebuilt image at ghcr.io/smacke/ffsubsync, run with the directory mounted into /video, and a browser version at smacke.github.io/ffsubsync that needs no install at all.
subsync vs ffsubsync
They are the same program. setup.py registers three console scripts, ffs, subsync and ffsubsync, all pointing at the same main function, and the README says all three work as entrypoints. The name you type does not change the behaviour.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smacke-ffsubsync)Star history chart for your README
[](https://hysenlabs.com/projects/smacke-ffsubsync)Was this useful?