HPC-Ops: tuned for one specific part, shipped as modules for three architectures, and every performance claim sits in a section you cannot see
High Performance LLM Inference Operator Library
At a glance
- What is it?
- A CUDA operator library for LLM inference from a large cloud vendor's model infrastructure team, covering attention, mixture of experts, matrix multiplication, sampling and fused communication. The visible page is six kernel write-ups with no install command and no benchmark table, and adding a new GPU architecture means editing the same list in four files across two build systems.
- Who is it for?
- Use HPC-Ops if you are serving on the hardware it was tuned for and can read the six kernel write-ups, because that is where the value is: each one explains a specific latency problem and the mechanism chosen for it. Four things to check before you plan around it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
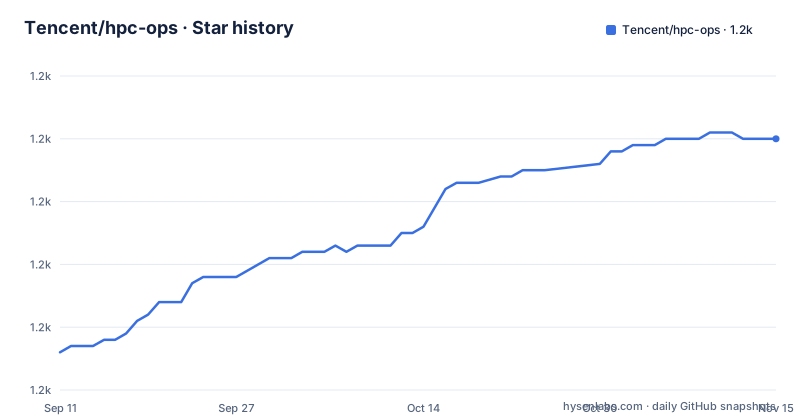
- Tencent/hpc-ops1,190 ★ · +34
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Tencent/hpc-ops | 1.2k | 1.2k |
34 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The page names six sections and shows three of them
The navigation row promises six things: why the library exists, updates, performance, an operator catalogue, a quick start and a roadmap. The visible text delivers the first two and stops partway through the second, inside a paragraph about the sampler, mid-word. So the reader gets the project's argument for itself and six detailed kernel write-ups from a single month, and nothing else. No install command, no hardware matrix beyond one sentence, no list of what is actually in the library, no benchmark table, no roadmap. That is a strange shape for a documentation page and an entirely normal one for a release announcement: this reads as the write-up that accompanied a launch, not as the reference a new user would be pointed at.
Tuned for one part, shipped for three architectures
The claim and the build disagree about scope. The headline bullet says the kernels are tailored for one specific accelerator, and that they deliver leading performance powering large-scale production inference. The build system supports three architecture targets, and the comment in the configuration is explicit that a build for several of them produces several shared objects in one package with the loader picking one at import time. A local build with nothing specified targets whatever is in the machine; a release wheel covers all three, and the stated reason is that a wheel is a release artefact rather than a local build. So the two newest targets are compiled and shipped on the strength of a tuning effort described for the older one, and nothing visible on the page states which architectures were actually benchmarked.
Adding an architecture means four edits in two build systems
The architecture list appears three times by name, in the packaging script, in the makefile and in the CMake configuration, and each copy carries the same comment: the same list is in the others, and adding one also needs a matching evaluation block in a header. So the total is four files across two build systems and two languages. The makefile comment also documents the build layout in detail: each architecture gets its own build directory, which exists so that building one architecture, then another, then the first again reuses the first one's objects instead of overwriting a shared temporary directory. That is a small, careful decision that pays for itself every time someone iterates, and it sits directly above a build list that has to be kept in step by hand in four places.
The clearest idea on the page is splitting FP32 into two BF16 halves
One of the six write-ups explains a technique worth reading on its own. Some matrix multiplications need BF16 activations but FP32-sensitive weights, and the two obvious options are both bad: naive FP32 falls back to ordinary cores because the tensor cores do not do FP32 natively, while using BF16 or the reduced-precision path directly costs accuracy or costs a conversion. The library's answer is to split each FP32 weight into a high BF16 part and a low BF16 residual at a fixed scale, then compute the result as one fused linear combination of two BF16 tensor multiplications, with both inside a single kernel, input movement shared once, accumulators living in registers and the final value written once. That is the whole philosophy of the library in one paragraph: keep the tensor cores full and pay for the extra precision in arithmetic rather than in memory.
It removes a modern technique on purpose
Another write-up describes the mixture of experts path fusing routing, the two matrix multiplications around the activation, quantization, and the weighted reduction into one pipelined execution, reading the original tokens through routing indices so the separate gather stage and its extra memory traffic disappear. Inside that description there is a removal rather than an addition. For the low-latency regime, the asynchronous copy path drops warp specialization, which increases how many thread blocks stay resident per multiprocessor and moves latency hiding out of a software pipeline inside a block and into hardware scheduling across blocks. Then a chained dependency feature links the stages to reduce launch gaps. Taking a technique out of a modern template library for a specific regime is a confident choice, and it is the kind of thing that only shows up when someone actually profiled the latency case rather than the throughput case.
The same operation has two physically different implementations
Tensor parallel inference usually runs the all-reduce, then adds the residual, then normalises, as three separate stages around what is really one logical operation. This library fuses all three into interconnect-native kernels and then splits that fusion in two. A high throughput mode uses hardware multicast for large token shapes of the kind prefill produces, while a low latency mode uses a point-to-point design split across two kernels with the chained dependency overlapping the stages for the small token shapes decode produces. Both use a two-shot communication schedule rather than a ring, and both keep the normalisation inside the collective. So the choice is not a tuning constant, it is two different transports selected by shape, which is the right answer and also the part most likely to behave differently on hardware you did not write it for.
The sampling path collapses a chain of small kernels into two
The last visible write-up covers what happens after the tokens come out. A decode step normally chains a long series of small operations across the vocabulary dimension, a repetition penalty, temperature scaling, top-k, top-p, a softmax, a random draw and a penalty mask update, each reading and writing global memory. The page says that in small batch serving this fragmented chain becomes a visible share of the latency, and that the library collapses the whole pipeline into two kernels with a faster temperature-only path dispatched automatically when the request shape allows it. The penalty mask stays on the graphics processor, small batches use fine-grained parallelism across blocks, and small top-k cases get a local sort and merge. The sentence describing that last optimisation is the one the page cuts off, which is a shame, since it is the sort of detail the other five entries all give.
Editorial conclusion
Use HPC-Ops if you are serving on the hardware it was tuned for and can read the six kernel write-ups, because that is where the value is: each one explains a specific latency problem and the mechanism chosen for it. Four things to check before you plan around it. The visible page contains no install command, no benchmark numbers and no operator list, so you will be reading the source and the configuration to know what you are getting. The performance claims name five other projects as comparison points and then qualify that with where applicable, and the table that would settle it is not on the page. The library says it is tailored to one specific Hopper part while the wheel ships modules for three architectures, so confirm your exact device is covered rather than its generation. And note that a local build uses the architectures present in your machine while a release wheel builds all three, which changes both your build time and what you end up testing.
Frequently asked questions
Which GPU architectures does HPC-Ops build for?
Three, and the list is kept by hand in the packaging script, the makefile, the CMake configuration and a header, so adding one means editing all four. A local build defaults to the architectures present in the machine, while a release wheel covers all three.
Which hardware were the HPC-Ops kernels tuned for?
One specific accelerator, named in the feature list, along with the claim that they power large-scale production inference. The build also ships modules for two newer architectures, and the visible page does not say which ones were benchmarked.
What does the HPC-Ops route matrix multiplication do?
It splits each FP32 weight into a high BF16 component and a low BF16 residual at a fixed scale, then computes the result as one fused linear combination of two BF16 tensor core matrix multiplications, keeping both in one kernel and the intermediate accumulators in registers.
What kernels does the HPC-Ops mixture of experts path fuse?
Routing, the gate and up projection, activation quantization, the down projection and the top-k weighted reduction, reading original tokens through routing indices so the separate gather stage and its extra memory traffic are removed.
How does HPC-Ops handle the all-reduce plus normalization step?
It fuses the all-reduce, the residual add and the root mean square normalisation into interconnect-native kernels, with a high throughput mode using hardware multicast for prefill-like shapes and a low latency mode using a point-to-point two-kernel design with chained overlap for decode-like shapes.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-hpc-ops)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-hpc-ops)Was this useful?