SuperSonic's pipeline, and the two moves that keep the LLM away from joins and invented terms
SuperSonic is the next-generation AI+BI platform that unifies Chat BI (powered by LLM) and Headless BI (powered by semantic layer) paradigms.
At a glance
- What is it?
- SuperSonic is a Java platform that puts a curated semantic layer between a business user's question and the database, so natural language becomes a semantic query statement first and SQL second. The interesting parts are the retrieval components, the rule based fast path, and what the repository page leaves unstated.
- Who is it for?
- SuperSonic is a fit for a team that already thinks in metrics and dimensions and can afford to curate semantic models, because that curation is what makes the natural language path work. It is a poor fit if you expect an LLM to query arbitrary tables for you, since nothing reaches the warehouse without a defined model first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
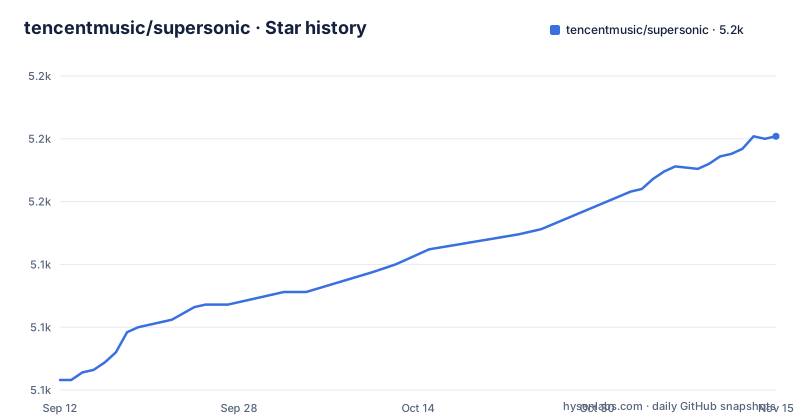
Star history
- tencentmusic/supersonic5,176 ★ · +97
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| tencentmusic/supersonic | 5.1k | 5.2k |
97 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Chat BI answers questions against metrics, not tables
A business user types a question, and the first thing that exists is not SQL. The question has to be expressed against curated semantic models: the definition of a metric, a dimension or a tag, along with its meaning and its relationships. Those models are built through the Headless BI interface, which the project assigns to analytics engineers. The pipeline produces a semantic query statement, and the Semantic Translator converts that statement into SQL executable against physical data models.
The project gives two reasons for routing around raw text to SQL. First, data semantics such as business terms and column values go into the prompt, which is meant to reduce hallucination. Second, the generation of advanced SQL syntax, joins and formulas among them, moves off the LLM and onto the semantic layer, which is meant to reduce complexity. The motivation section is blunt about the starting point: Text2SQL approaches have shown promising results, but their reliability falls short for large-scale real-world applications.
The consequence is that accuracy is bounded by the models, not by the model. A metric nobody defined cannot be asked for.
Schema Mapper does the retrieval, and Chat Memory supplies the examples
The Knowledge Base extracts schema information periodically from the semantic models and builds a dictionary and an index to facilitate schema mapping. The Schema Mapper then identifies references to schema elements, metrics, dimensions, entities and values, inside a user query, by matching the query text against that knowledge base. Retrieval therefore happens once against your curated schema.
It happens a second time against your own history. Chat Memory encapsulates a collection of historical query trajectories that can be recalled to facilitate few-shot prompting, so the model sees how your team has phrased similar questions before.
Neither of those replaces the semantic model. If your models are thin, the Schema Mapper has little to match against, and Chat Memory only reinforces the phrasing your team already uses. One detail is worth noting for anyone debugging a wrong answer: schema information is extracted periodically, so the index is a snapshot, and a model you just edited is not reflected in it the instant you save it.
Rule based parsers and correctors are the demo and test path
The Semantic Parser understands user queries and generates the semantic query statement. It is described as a combination of rule based and LLM based parsers, each of which deals with specific scenarios. The Semantic Corrector checks the validity of that statement and corrects it when necessary, and it is a combination of rule based and LLM based correctors in the same way.
The rule based parser is called out separately in the feature list, where it is said to improve efficiency in certain scenarios, with demonstration and integration testing given as the examples.
That matters when you judge what you are looking at. A demonstration or an integration test is exercising the rule path, and it is not evidence about how the LLM path behaves on your own schemas, even though the same interface serves both. And because the parser and the corrector are each a combination of two approaches, the project's own framing is that each one deals with specific scenarios.
Java SPI is the extension seam, and the modules show where it sits
SuperSonic is designed to be extensible and composable, allowing custom implementations to be added and configured with Java SPI. The repository is a Maven project, with pom.xml at the root, and its top level directories line up with the components described: chat/ for the Chat BI side, headless/ for the semantic layer, auth/ for authentication, evaluation/ and benchmark/ for measurement, common/ for shared code, launchers/, webapp/ for the frontend, and docker/ plus assembly/ for packaging. The daemon script referenced for local runs lives at assembly/bin/supersonic-daemon.sh.
What the repository page does not give you is the extension contract itself. It does not name the SPI interfaces, does not describe the service registration mechanism, and does not say which of those modules are meant to be replaced outright rather than extended. Chat Plugin shows the shape of the idea: given a list of configured plugins with descriptions and sample questions, an LLM selects the most suitable one. Writing your own means finding that contract in the source or on the documentation site.
Dataset, column and row access control, with the mechanics left out
One line covers it: built in support for three level data access control, at dataset level, column level and row level.
Everything else is unstated. The page does not say where those rules are configured, whether SuperSonic evaluates them or pushes them down to the underlying warehouse, or whether one semantic model can carry different rules for different business users. It also does not say how access control interacts with the Chat BI path, where a free text question is matched to dimensions and values by the Schema Mapper and a metric name has to line up with a permission before any SQL is emitted.
If your requirement is that one team sees revenue and another does not, that is exactly the case those three levels exist for, and this page is not where the answer lives. Read the documentation site before you promise a tenant isolation story.
Docker Compose on port 9080, or a prebuilt binary from a 2024 release
Before starting, the README says to configure a deployment-specific JWT signing secret with `export SUPERSONIC_JWT_SECRET="$(openssl rand -hex 64)"`; the startup check rejects missing, malformed, short, or published default secrets. The Docker path asks for Docker and docker-compose, then a single download of the compose file:
wget https://raw.githubusercontent.com/tencentmusic/supersonic/master/docker/docker-compose.ymldocker-compose up -dAfter that, http://localhost:9080 in a browser.
The local build path takes the latest prebuilt binary from the release page and starts a standalone Java service with a script:
assembly/bin/supersonic-daemon.sh startBoth paths ship sample semantic models and chat conversations as a starting point. Check the dates before you commit to either. The most recent tagged releases are v0.9.8 from 2024-11-01, v0.9.6 from 2024-08-24 and v0.9.4 from 2024-07-01, while the last push to master was on 2026-10-15. The compose file is fetched from master, so the container route and the release binary are not the same code, and anyone pinning a build should say which of the two they mean.
The shared playground is wiped every weekend
There is a public playground at http://117.72.46.148:9080 where you register and try the product as a new user. Two warnings come with it: do not modify system configurations, and the host is restarted regularly every weekend to reset configurations.
That makes it a demonstration, not a service. Anything you model there is gone on the next restart, and the address is a bare IP address with a port rather than a domain, so there is no name to bookmark and nothing to point a record at. The sensible use is to size up the interface, the sample models and the natural language phrasing the parser recognises.
The moment you care about persistence, move to the compose file or the binary. Everything past that point is left to you: the repository page says nothing about hardening, transport security or backups, and it says nothing about how data source credentials are supplied.
Editorial conclusion
SuperSonic is a fit for a team that already thinks in metrics and dimensions and can afford to curate semantic models, because that curation is what makes the natural language path work. It is a poor fit if you expect an LLM to query arbitrary tables for you, since nothing reaches the warehouse without a defined model first. Before deploying it, check three things the repository page does not answer: how the three access control levels are configured and where they are enforced, which SPI interfaces you would implement to replace a built in component, and which release you actually want, since the newest tagged release is v0.9.8 from 2024-11-01 while master was last pushed on 2026-10-15. Treat the shared playground at port 9080 as a demo that is wiped every weekend, and plan your own persistence, credentials and backups before pointing real data at it.
Frequently asked questions
What is SuperSonic and what does it combine?
It is described as an AI plus BI platform that unifies Chat BI, powered by an LLM, with Headless BI, powered by a semantic layer. The stated goal is for natural language questions to reach the same curated and governed semantic models that traditional BI uses, with Text2SQL gaining context from those models.
How do I run SuperSonic locally?
First set a JWT signing secret with export SUPERSONIC_JWT_SECRET="$(openssl rand -hex 64)", since startup rejects a missing one. Then two paths are given. With Docker: fetch docker/docker-compose.yml from master using wget, then run docker-compose up -d. Or download the latest prebuilt binary from the release page and run assembly/bin/supersonic-daemon.sh start. Both end at http://localhost:9080 in a browser.
Can I plug my own components into SuperSonic?
That is the intended extension model, through Java SPI: custom implementations are added and configured that way. The built in pieces such as the semantic parser, corrector, chat plugin and chat memory are organised the same way, and Chat Plugin uses an LLM to select the most suitable plugin from the configured list based on descriptions and sample questions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencentmusic-supersonic)Star history chart for your README
[](https://hysenlabs.com/projects/tencentmusic-supersonic)Was this useful?