graphrag-local-ollama inherits Microsoft's author list and installs jupyter in the image
Local models support for Microsoft's graphrag using ollama (llama3, mistral, gemma2 phi3)- LLM & Embedding extraction
At a glance
- What is it?
- This is a local-model adaptation of Microsoft's GraphRAG with five query modes and a Docker path. Its package metadata still lists thirteen Microsoft authors, its requirements file pins the whole development toolchain, and the Dockerfile installs all of it into the runtime.
- Who is it for?
- graphrag-local-ollama suits someone who wants GraphRAG-style global question answering over a private corpus without paying an API provider, and who will read its output rather than trust it. It does not suit anyone who needs a clean fork boundary, because the packaging metadata still belongs to the upstream project, or who wants a slim production image, because the Dockerfile installs the test and notebook toolchain.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
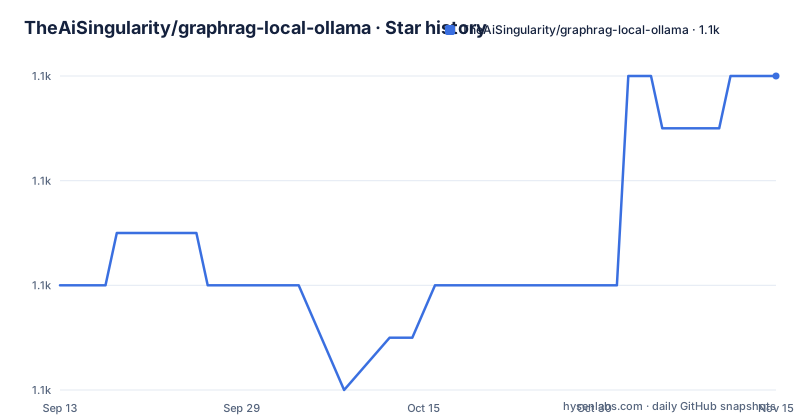
- TheAiSingularity/graphrag-local-ollama1,112 ★ · +4
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| TheAiSingularity/graphrag-local-ollama | 1.1k | 1.1k |
4 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The author list in the manifest is Microsoft's
The project describes itself as an adaptation of Microsoft's GraphRAG for models downloaded with Ollama, and the packaging metadata shows how completely the upstream project was carried over.
The Poetry block lists thirteen authors. Twelve carry `@microsoft.com` addresses, with names including Alonso Guevara Fernández, Andrés Morales Esquivel, Chris Trevino, David Tittsworth, Gaudy Blanco Meneses, Ha Trinh, Kate Lytvynets, Rodrigo Racanicci and Sarah Smith. Only Mónica Carvajal has no corporate domain. None of them appear to have anything to do with this fork.
The version field is stranger still. It reads `0.1.1`, and a comment directly above it says maintainers should not change it by hand and should use the release script instead. A dynamic-versioning block below enables git-based versioning with a bump setting, so the literal value is a placeholder that a build overwrites.
The release machinery is present too, with a semversioner directory at the root, `semversioner==2.0.3` pinned in requirements, and a release script under `scripts/`. For anyone reading the package metadata off a built artefact, the authors are the upstream ones.
The image installs pytest, pyright and jupyter
There are two dependency manifests with opposite philosophies, and the container build picks the wrong one for production.
The Poetry block uses caret ranges: `environs = "^11.0.0"`, `datashaper = "^0.0.49"`, `openai = "^1.35.7"`, `numpy = "^1.25.2"`. The requirements file uses exact pins for all of it, plus the development toolchain: `pytest==8.2.0`, `pyright==1.1.368`, `ruff==0.5.0`, `coverage==7.5.4`, `jupyter==1.0.0`, `ipykernel==6.29.4`, `nbconvert==7.16.3`, `poethepoet==0.26.0`, `semversioner==2.0.3` and `update-toml==0.2.1`.
The Dockerfile copies that requirements file and installs it wholesale into a `python:3.11-slim` image. So the shipped image carries a type checker, a linter, a test runner, a coverage tool and a notebook stack.
One pin has a reason recorded next to it. `scipy==1.12.0` carries the comment that version 1.13.0 was a footgun. That is the sort of note worth keeping, and it is the only one in a list of forty-two exact pins.
GRAPHRAG_API_KEY ships as the literal string ollama
The compose file configures the graph service with two environment variables, and one of them is a placeholder rather than a secret:
      - OLLAMA_HOST=http://ollama:11434
      - GRAPHRAG_API_KEY=ollama
That is the mechanism behind the project's claim of escaping costly hosted models. Ollama has no authentication, so the client library still demands a key and receives the word ollama. The file also mounts `settings.yaml` into the container, so model names and the LazyGraphRAG toggle are configured outside the image, and it pulls `.env` through `env_file` after the compose file has already set its own values.
The Ollama service publishes 11434 to the host and has a healthcheck against `/api/tags` every ten seconds, and the graph service waits for that healthcheck rather than for a fixed delay.
The place this needs attention is the moment somebody points the stack at a real endpoint. A key that reads `ollama` will fail at request time rather than at configuration time, and the error will point at the provider rather than at the compose file.
Enabling Lazy quietly weakens DRIFT
The five query modes are not independent, and the documentation says so in a note that is easy to skim past.
Lazy mode, described as inspired by Microsoft's LazyGraphRAG, skips community summarization at index time and generates summaries during the query instead. The stated result is roughly 99% faster indexing, with the trade-off that a first query is slower than standard global search because the work moved to query time. It is switched on by a single key in `settings.yaml`:
lazy_graph_rag: trueNow read the DRIFT note. DRIFT decomposes a question into scored sub-questions using community reports as context, answers each through the entity graph, generates follow-ups from the answers with a priority queue and a depth limit, then reduces the intermediate answers into one response. And the note says DRIFT works best when community reports are available, so if Lazy was used during indexing the primer step will have limited context, while the search loop still operates normally.
So the two features trade against each other. Lazy buys indexing speed by removing exactly the artefact DRIFT's primer depends on.
The README opens with Contributing and an orphan sentence
The document does not start where you expect. The first heading is the contributing section, which invites pull requests and points at a contributing guide. Under it sits a single unlabelled line asking for support for llama integration. Only after that does the actual title appear, followed by the description of the project.
Whatever process assembles that README put the contribution material first, and the leftover sentence has no heading, no context and no explanation of what llama integration would mean here given that Ollama already serves llama-family models by name.
The rest of the structure is conventional: a paper link with the abstract pasted in, a feature list, then one section per query mode, a web UI section, and a JSON and JSONL input section. The feature list claims eleven items, including full UTF-8 support with chunking that is aware of Chinese, Japanese, Korean, Arabic and Cyrillic text, which is a stronger claim than a project that ships an English paper abstract would normally need to make.
Two screenshots dated 2024-07-09 sit at the repository root, with spaces in their filenames.
The pasted abstract has words fused together
The research paper section reproduces the GraphRAG abstract in full, and the text has the fingerprint of a raw PDF extraction.
Spaces are missing at line-wrap boundaries throughout. The passage says retrieval-augmented generation enables large language models to answer questions, with no space before the word to. It refers to global questions directed at an entire text corpus, then writes such as. Prior methods appear as a single fused token. The approach uses an LLM to build a graph-based text index, with scales and with fused. Given a question becomes a single token, and to generate a partial response becomes another.
One accent has been split off its letter as well: naive arrives with its diacritic detached and attached to the following character.
None of this changes what the method is. It does mean the section is a wall of unbroken text rather than the readable summary it is presumably meant to be, and that anyone citing from this page would be citing a corrupted copy. The abstract also predates the two query modes the project added, so it describes the upstream approach rather than this fork's feature set.
GPU acceleration is a block you have to add yourself
The Docker path is advertised as one command, and it is, with three caveats that are all stated in passing.
The first is compute. The note under the quick start says GPU support is added by putting `deploy.resources.reservations.devices` into the ollama service in the compose file. That is a manual edit, and until you make it the Ollama container runs on CPU. Nothing in the quick start says so before you start it.
The second is models. The quick start has you copy `.env.example` to `.env`, start the stack, drop documents into `./input/`, and run a query. Indexing starts on container start, but nothing in that sequence says you must pull your Ollama models first, and nothing in the container mounts the model volume, so the models have to be in the `ollama` service rather than on your host.
The third is the web interface, which is a separate path. It installs `requirements-ui.txt`, runs `app.py`, and serves on port 7860 with four tabs. The graph visualiser needs pyvis, which is a UI-layer dependency rather than a runtime one.
Editorial conclusion
graphrag-local-ollama suits someone who wants GraphRAG-style global question answering over a private corpus without paying an API provider, and who will read its output rather than trust it. It does not suit anyone who needs a clean fork boundary, because the packaging metadata still belongs to the upstream project, or who wants a slim production image, because the Dockerfile installs the test and notebook toolchain. Before you adopt it, settle three things. Confirm the Python range, which stops below 3.13, and confirm your Ollama models are pulled before indexing starts. Decide which query mode you actually need, because Basic needs no community reports while DRIFT degrades if you indexed with Lazy enabled. And fix the credentials before you point it anywhere real, since the compose file ships `GRAPHRAG_API_KEY` set to a placeholder string. The last push to main was on 2026-05-08.
Frequently asked questions
Which query modes does graphrag-local-ollama offer?
Five: Global, Local, DRIFT, Basic and Lazy. Basic is vector-similarity retrieval that takes the ten most similar entities and needs no community reports, DRIFT decomposes a question into scored sub-questions and iterates, and Lazy skips community summarization at index time and computes it during the query.
How do I run graphrag-local-ollama without a Python environment?
Copy `.env.example` to `.env`, run `docker-compose up --build`, drop documents into `./input/` where indexing starts on container start, then query with `docker-compose run graphrag python -m graphrag.query --root /app --method global "What are the main themes?"`. GPU acceleration is not on by default and has to be added to the ollama service.
What does graphrag-local-ollama need from Ollama?
An Ollama service reachable through `OLLAMA_HOST`, which the compose file points at the ollama service on port 11434 with a healthcheck against `/api/tags`, and a `GRAPHRAG_API_KEY` that the compose file sets to the placeholder string ollama. Model names and chunk size live in `settings.yaml` or the Settings tab of the web UI.
Does the graphrag-local-ollama Docker image include test and notebook tooling?
It does. The Dockerfile copies `requirements.txt` and installs it wholesale, and that file pins pytest, pyright, ruff, coverage, jupyter, ipykernel, nbconvert, poethepoet and semversioner next to the runtime libraries, so the image carries the whole development toolchain.
Who is credited as author of graphrag-local-ollama?
The package metadata lists thirteen authors, twelve of them at `@microsoft.com`, carried over from the upstream GraphRAG project this one adapts. The version field is produced by poetry-dynamic-versioning from git rather than typed in, with a comment instructing maintainers to use the release script instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/theaisingularity-graphrag-local-ollama)Star history chart for your README
[](https://hysenlabs.com/projects/theaisingularity-graphrag-local-ollama)Was this useful?