wdoc: a RAG tool that widens its own search until the candidates stop being relevant
Summarize and query from a lot of heterogeneous documents. Any LLM provider, any filetype, advanced RAG, advanced summaries, scriptable, etc
At a glance
- What is it?
- A hand-written document question answering tool that chunks, embeds, and then keeps re-running retrieval while more than nine in ten candidates look relevant, capped at five hundred. Its install hook downloads Chromium and deliberately upgrades yt-dlp to a pre-release.
- Who is it for?
- wdoc is worth reading if you build retrieval pipelines, because its retrieval loop and its two-model screening step are the most transferable parts here, and the project is candid that it wants testing rather than praise. Two things to check before you deploy it.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
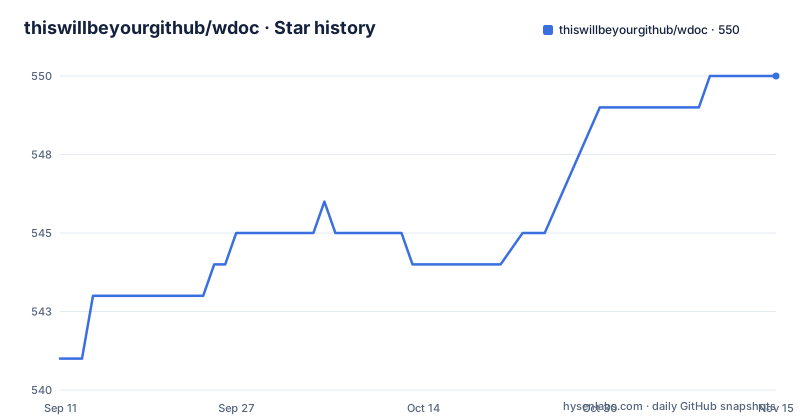
- thiswillbeyourgithub/wdoc550 ★ · +9
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| thiswillbeyourgithub/wdoc | 541 | 550 |
9 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The retrieval loop repeats while more than 90% of candidates look relevant
The one-paragraph quick guide describes the pipeline better than any feature list could, and the example command is the whole thing in one line:
link="https://situational-awareness.ai/wp-content/uploads/2024/06/situationalawareness.pdf"

uvx wdoc[full] --path=$link --task=query --filetype="online_pdf" --query="What does it say about alphago?" --query_retrievers='basic_multiquery' --top_k=auto_200_500
The path is parsed with heuristics that guess the right loader, the text is chunked and embedded, and the query is embedded directly while the default model also writes alternative queries that get embedded separately. Retrieval then pulls two hundred candidates, and the decisive step is step five: each candidate goes to a cheaper model that decides whether it actually answers the question. If more than ninety percent of the two hundred pass that screen, the tool runs the search again with a higher ceiling and keeps going until the candidates start to look irrelevant or the cap of five hundred is reached. That threshold is the design: rather than trusting a fixed recall number, it spends more retrieval whenever the screening says the corpus has not been exhausted.
Two models, one for recall and one for screening
The reason a hundred and fifty screened candidates are affordable is stated in the feature list: the tool uses both an expensive and a cheap model to push recall as high as it can, because it can afford to fetch a lot of documents per query through embeddings. So the default small model, named in the walkthrough as an OpenRouter-hosted DeepSeek flash variant, is not the model that writes your answer. It is the model that answers a much narrower question, whether one chunk is relevant, two hundred times per query. The expensive model does the aggregation, and the aggregation is done in batches to produce a single answer that cites the exact portion of the source document it came from. The feature list is explicit that this is a deliberate trade: get the author's line of reasoning instead of a set of nebulous takeaways, and get an indented markdown answer with sources instead of invented prose.
The install hook downloads Chromium and upgrades yt-dlp to a pre-release
The packaging script defines a post-install command that runs after every install, and what it does is worth reading before you pip install this in a locked-down environment. It first shells out to a Playwright install, which downloads a browser. It then tries to import yt_dlp, and if that import succeeds, it upgrades yt-dlp to its pre-release channel, with a comment explaining why: extractor fixes for video platforms often land in pre-releases before the stable pin catches up. If the openparse package is importable, it also runs that package's download step. Two details make this more tolerable than it sounds. Every step is wrapped so a failure prints an error rather than aborting your install, and the yt-dlp upgrade is conditional on the extra actually being present, which keeps video support optional. It is still an install that reaches the network and moves a pinned dependency to an unstable version.
The plain package only ships PDF and URL loaders
The installation advice in the page is a warning as much as a recommendation: when in doubt use the all-extras invocation, because the plain package ships only the PDF and URL or web loaders. Everything else lives in optional extras, with video, audio, Anki, office formats and Logseq named as the members of that list. The full variant bundles all of them so you do not have to reason about a missing dependency, which is a sensible default for a tool whose pitch is handling any file type at once. The other installation shape is a Docker deployment with a Gradio web interface, and that one is labelled experimental rather than recommended. The project is also careful about how it is extended: it describes itself as both a tool and a library, and points at an existing Open-WebUI tool built from it as proof.
The documentation is a Claude Code skill in three files
Instead of a documentation tree, this project ships a skill directory with three files and calls it the comprehensive reference. The orientation file gives a quick sense of the tool, the reference file holds the full tables of command-line arguments, environment variables, supported file types and the Python API, and the examples file holds copy-pasteable shell and Python recipes. The skill is packaged so that an agent can read the same reference a person would. Alongside it sit a Read the Docs site, a DeepWiki badge, a shell completions directory and an examples document linked from the walkthrough. It is a lot of parallel documentation for one tool, and the split is deliberate rather than accidental: the tables that change with every release are generated or maintained as reference material, while the page you are reading is the narrative.
A script bumps the default model, so the documented default can move under you
The repository root contains a script for bumping default models and a version-bump configuration, which tells you something important about how this project treats its own defaults. The walkthrough names a specific hosted model as the default screening model, and a script exists to update default model identifiers as a batch operation. So the number in the documentation is true when written and is expected to change without a release note. The release cadence supports that reading: three releases inside ten weeks in the summer, with a 5.2.2 published the same day as the last push. If you pin a model for reproducibility, pin it explicitly in your own configuration rather than inheriting the default, because the default is a moving target by design.
AGPL-3.0 on a tool meant to be deployed and embedded
The licence is the Affero General Public License, and the shapes this tool is meant to take are a container you deploy for a team, a library you import, an interface you embed in another front end, and an Open-WebUI tool someone else wrote. That combination is worth a conversation with someone who reads licences, because copyleft with a network clause has consequences for modified deployments that are exposed to users, and this article is not the place to work out what they are. Two related points come from the project itself. It claims support for virtually any model provider, including local ones, with extra layers of security for values it calls very secret, which tells you the intended deployment is one where API keys live on your own machine. And the origin story matters for expectations: the author is a psychiatry resident who built it to get a definitive answer from many sources at once.
Sixteen file types, and the author asks you to test it rather than praise it
The status section is unusually direct for a personal project. It describes itself as usable and tested, still under active development, with tens of planned features, and then makes three requests: that people test it because user testing is the quickest way to find the many small bugs, that an issue be opened before a pull request because there may be work in the pipeline, and that the main branch is treated as the more stable one while the dev branch carries more features. That branch policy is the sort of thing worth knowing before you depend on it, since it means the branch with the newest features is also the less tested one. The file type claim is that fifteen are already implemented and the aim is to query all of them at once, with semantic search, an opinionated summary feature and a preliminary web search path through DuckDuckGo as the extras on top of retrieval.
Editorial conclusion
wdoc is worth reading if you build retrieval pipelines, because its retrieval loop and its two-model screening step are the most transferable parts here, and the project is candid that it wants testing rather than praise. Two things to check before you deploy it. The licence is AGPL-3.0 on a tool whose normal shape is a container or an embedded integration, so take advice on what that implies before exposing a modified deployment. And the install hook performs network fetches, including a Chromium download and an intentional upgrade to a yt-dlp pre-release, so install it where that is acceptable rather than in an environment you would rather keep sterile.
Frequently asked questions
What is wdoc used for?
Summarising, searching and querying large collections of heterogeneous documents, with answers that cite the exact portion of the source they came from. It is built mainly on LangChain and LiteLLM and claims fifteen or more file types implemented, queryable at the same time.
How do I install wdoc with all file types?
Use `uvx wdoc[full]`. The plain package ships only the PDF and URL loaders, with video, audio, Anki, office formats and Logseq in optional extras, and the full variant bundles them all so a missing dependency is not something you have to diagnose.
How does wdoc decide how many documents to retrieve?
It starts with two hundred candidates and has a cheaper model screen each one for relevance. If more than ninety percent of them look relevant, it searches again with a higher ceiling and repeats until the candidates stop being relevant or it reaches five hundred.
Does installing wdoc download anything or change my dependencies?
Yes. The post-install hook runs a Playwright install that downloads a browser, and if the video extra is present it upgrades yt-dlp to its pre-release channel so extractor fixes arrive early. Failures in those steps are caught and printed rather than aborting the install.
Which branch of wdoc should I track?
The project states that the main branch is more stable than the dev branch, and that the dev branch offers more features. It also asks that an issue be opened before a pull request, since there may be improvements already in progress.
What license is wdoc released under, and can I deploy a modified version?
The repository is licensed under AGPL-3.0, and the project is meant to run as a deployed container, an imported library, or an embedded tool such as the Open-WebUI integration it links. What that implies for a modified deployment exposed to users is a question for someone who reads licences rather than for this page.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thiswillbeyourgithub-wdoc)Star history chart for your README
[](https://hysenlabs.com/projects/thiswillbeyourgithub-wdoc)Was this useful?