toml-lang/toml: a specification, not a parser
Tom's Obvious, Minimal Language
At a glance
- What is it?
- The TOML format has a home repository that ships prose and an ABNF grammar instead of code, so it is the reference for parser authors and the wrong place to look for a library. Its two hard limits, a mandatory top level table and no document boundary, decide what you can and cannot write in it.
- Who is it for?
- If you are writing or auditing a parser, this is the repository to read, and toml.md and toml.abnf are the files that matter rather than the README. If you are configuring an application, you do not need it at all, and the wiki is where the useful links sit.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
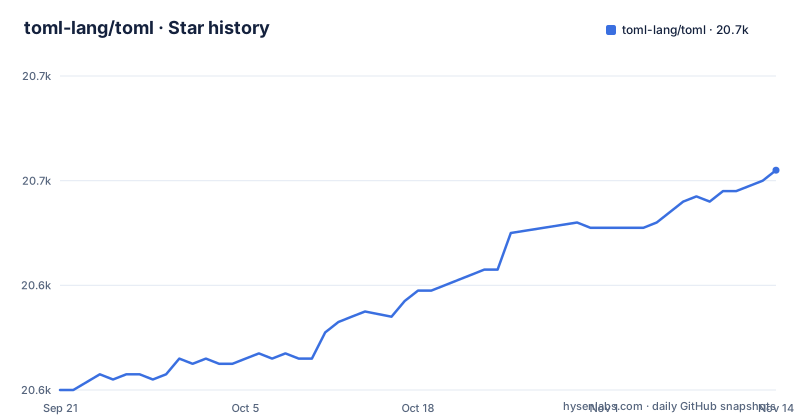
- toml-lang/toml20,662 ★ · +42
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| toml-lang/toml | 20.6k | 20.7k |
42 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository ships toml.md and toml.abnf, not an importable library
Cloning this repository gives you no package to install, no module to import, and no build step. The top level files describe what the project is: toml.md for the specification prose, toml.abnf for the grammar, CHANGELOG.md for version history, plus docs/, scripts/, logos/, and formatting files such as .pre-commit-config.yaml and .prettierrc.toml. The license is MIT and the default branch is main.
That shapes who should be reading it. If you want a TOML reader for a particular language, nothing here supplies one. The audience is the people who write those readers: library maintainers, language server authors, and anyone who has to settle an argument about what counts as a valid document. For the released text to implement against, the repository points to https://toml.io, which is where you should go when you need something stable. The git history here is the place to watch a specification that is still moving, and the wiki is the place to find the code.
A hash table is mandatory at the top, which bans bare arrays and top level floats
Every TOML document is required to have a hash table at the top, and the specification names the two things this rules out. Top level arrays are not permitted and neither are top level floats, so a document can nest data as deeply as it likes inside its keys but cannot begin with a bare list.
The effect lands on serialization rather than on parsing. If your program holds a list of records and you want to write it out directly, TOML offers no way to express that. You have to hang the list under a key and accept a wrapper the reader has to know about, or choose a format whose root can be an array. The same wall appears when floating point data already sits at the top of your structure. The framing in the specification is that TOML is explicitly intended as a configuration file format, so parsing is easy, but it is not intended for serializing arbitrary data structures. Configuration has a shape, a table at the root, and that constraint is the price of the format.
Nothing marks the start or end of a document, so streaming has to be negotiated by the application
There is no standard identifying the start or end of a TOML file, and the specification says so directly. No part of the syntax gives you a boundary to frame a protocol around, which matters the moment a document leaves a single process. Sending TOML over a socket, writing it to a queue, or slicing it out of a stream all need a place where one document ends and the next begins, and the format does not supply one.
The answer the specification gives is to negotiate it at the application layer. In practice that means a length prefix, a sentinel value, a record separator, or a parser that consumes incrementally and reports back when it has a complete document. None of those belong to TOML and none are specified here. A reader who assumes the format is self describing ends up owning the boundary themselves, and that is exactly the kind of detail two components can quietly disagree about, since one side's idea of where a document stops is invisible to the other.
Comments and optional indentation are what you get for choosing it over JSON
Comments are the concrete reason to reach for TOML instead of JSON in a file that people edit, and the example document uses one on its first line and another beside a date value. TOML and JSON are both simple and use ubiquitous data types, which is what makes either easy for machines. TOML and YAML both emphasize human readability, including comments that make the purpose of a given line easier to understand. The difference the specification draws is that TOML combines the two, allowing comments unlike JSON while preserving simplicity unlike YAML.
Indentation is the second affordance, and it is strictly optional. Tabs and spaces are allowed but not required, so nesting is expressed by table headers rather than by the shape of the text. That keeps diffs small when a value changes, because a reindented block never rewrites the whole file. The cost is that a human has to read the headers to know the structure, and a formatter will not tell them whether a line landed in the table they meant.
# This is a TOML document.

title = "TOML Example"

[owner]
name = "Tom Preston-Werner"
dob = 1979-05-27T07:32:00-08:00 # First class dates

[database]
server = "192.168.1.1"
ports = [ 8000, 8001, 8002 ]
connection_max = 5000
enabled = true

[servers]

  # Indentation (tabs and/or spaces) is allowed but not required
  [servers.alpha]
  ip = "10.0.0.1"
  dc = "eqdc10"

  [servers.beta]
  ip = "10.0.0.2"
  dc = "eqdc10"

[clients]
data = [ ["gamma", "delta"], [1, 2] ]

# Line breaks are OK when inside arrays
hosts = [
  "alpha",
  "omega"
]
Nested arrays carry no element type, so string pairs sit beside integer pairs
Look at the clients table in the example. One key holds an array of two arrays, a pair of strings followed by a pair of integers. A second key holds an array of two strings spread across four lines, because line breaks are fine inside arrays. Nothing in the syntax records what those inner arrays are supposed to contain. There is no schema in the format, so a consumer that assumes the inner arrays are strings will meet integers in the same value and has no warning coming.
This is the gap between readable and validated. TOML maps unambiguously to a hash table and parses into data structures in a wide variety of languages, which makes the syntax easy to implement, but unambiguity is not a type contract. The check that a connection limit is a number and a port list is a list of ports happens after parsing, against knowledge of what each key means, and that knowledge lives in your application rather than in the document. If a key is supposed to hold hostnames, the format accepts a list of numbers without complaint, and the error surfaces later, somewhere else.
INI has no standardized format and its nesting collapses after a level or two
INI files are the format most often set beside TOML, since both are plain text key and value files used for configuration, and the specification is blunt about where INI falls short. There is no standardized format for INI. Different projects extend it their own way, so a file written for one tool can mean something else entirely to another. There is also no graceful handling of more than one or two levels of nesting, which is the direction configuration trees tend to grow.
For anyone converting an existing INI file, both of those are decisions rather than trivia. If your current INI has been carrying a private dialect of section syntax, that dialect has to be translated by hand, because there is no spec to validate the translation against. And if the file has already grown past a couple of levels, the conversion stops being a mechanical rename of sections into table headers. The servers table in the example shows the target shape, with servers.alpha and servers.beta nested under servers, and the deeper your original nesting runs, the more of that translation you will be doing by eye.
main carries unreleased spec text while the 1.1.0 release is dated 2025-12-24
This repository holds the in-development version of the specification, and that distinction matters as soon as you start implementing. Released versions live at https://toml.io. The most recent release listed here is 1.1.0, dated 2025-12-24, and it sits nearly five years after 1.0.0, dated 2021-01-12. An earlier tag, 1.0.0-rc.3, is dated 2020-10-07.
So there are two texts to choose from and they are not the same text. The repository is not archived and its last push landed on 2026-11-02, which is after the 1.1.0 release, so the specification keeps moving past the newest tag. Implement against main and you may write a parser for wording no release has blessed. Implement against 1.1.0 and you may find a proposal in the tracker that the parsers already in the wild have not adopted. The workable move is to pick one text, record which one in your own documentation, and be able to explain why your parser rejects a document that main would accept.
Validators, implementations, and a test suite live in the wiki rather than in this repository
It is worth naming what is absent here, because a search for a TOML tool usually lands on this page. There is no validator binary, no reference implementation, and no test runner you can point at your own parser using these files. What exists instead is a pointer. The official wiki at https://github.com/toml-lang/toml/wiki catalogs projects using TOML, implementations, validators, a language agnostic test suite for TOML decoders and encoders, editor support, encoders, and converters.
That catalog is the real answer to how you check a parser, and it is maintained as wiki pages rather than as code here. Two consequences follow for an implementer. A conformance claim you want to make publicly depends on the test suite from the wiki, since the README does not document a command for running checks against the grammar in toml.abnf. And because the wiki is a community list, the particular validator or test suite you choose is your own to defend, which means the useful cases are the ones that fail, not the documents your reader already agreed with.
Editorial conclusion
If you are writing or auditing a parser, this is the repository to read, and toml.md and toml.abnf are the files that matter rather than the README. If you are configuring an application, you do not need it at all, and the wiki is where the useful links sit. Verify two things first: which version of the specification your parser targets, because main and the 1.1.0 release are not the same document, and whether your data fits the format at all, because a bare top level array and a top level float cannot be written in TOML. Neither restriction is a bug to argue about. They are the boundary the format draws around configuration data, and working inside them is cheaper than working around them.
Frequently asked questions
What is the point of a TOML file?
TOML is a minimal configuration file format meant to be easy to read because its semantics are obvious. It is designed to map unambiguously to a hash table and to be easy to parse into data structures in a wide variety of languages.
Why use TOML instead of YAML?
TOML and YAML both emphasize human readability, including comments that make the purpose of a line easier to understand, but the specification says TOML differs by preserving simplicity. TOML and JSON are both simple and use ubiquitous data types, and TOML is the one that allows comments.
What does TOML stand for?
Tom's Obvious, Minimal Language, by Tom Preston-Werner, Pradyun Gedam, and others. The same repository also holds the in-development specification text and an ABNF grammar file named toml.abnf.
What are the differences between INI and TOML files?
There is no standardized format for INI, and INI does not gracefully handle more than one or two levels of nesting. TOML nests with table headers such as [servers.alpha] and always has a hash table at the top level of the file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/toml-lang-toml)Star history chart for your README
[](https://hysenlabs.com/projects/toml-lang-toml)Was this useful?