finagle: monthly releases claimed, last tag in 2024, and a default branch of snapshots
A fault tolerant, protocol-agnostic RPC system
At a glance
- What is it?
- The RPC system behind Twitter's high-concurrency JVM services, split across thirty-one module directories with uniform client and server APIs across protocols, where the project states it does not follow semantic versioning, points at a changelog for breaking changes instead, and keeps its stable release on a branch other than the default one.
- Who is it for?
- finagle suits a Scala team running high-concurrency JVM services that want one client and server API across several wire protocols, and that values runtime toggles over shipping builds to change behaviour. It does not suit you if you rely on semantic versioning to reason about upgrades, because the project states it does not follow it and records breaks in a changelog instead.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 94 days ago.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
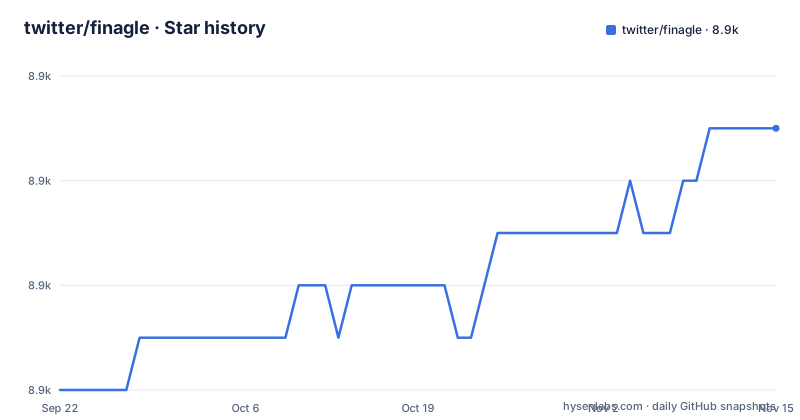
- twitter/finagle8,871 ★ · +5
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| twitter/finagle | 8.9k | 8.9k |
5 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The stated cadence and the tag history do not agree
The release section says releases are done on an approximately monthly schedule. The tag history says something different: the recent versions are 24.5.0 from May 2024, 23.11.0 from November 2023 and 22.12.0 from December 2022. Those three span roughly a year and a half. So the sentence describing the cadence and the record of what actually shipped do not line up, and for anyone planning an upgrade rhythm the tag history is the more reliable of the two. The readme separately states that the project is used in production and is being actively developed, and the repository is not archived, so the gap is more likely an artefact of how releases are cut than a statement about maintenance.
Semantic versioning is explicitly not followed
This is stated rather than implied, and it comes with a consolation. While semver is not followed, the changelogs are described as detailed, with sections covering public API breaks and changes in runtime behaviour. The version numbers give it away: the pattern is year and month rather than major, minor and patch, so a build called 24.5.0 is not comparable to a 23.11.0 in the way a semantic version would be. The practical consequence is that the safety net is the changelog rather than the number. An upgrade can break your code, and the digit sequence will not warn you, so the file to read before every bump is the change log, and the sections to read first are the two the project calls out.
The default branch is weekly snapshots, not the stable release
Branch conventions here are unusual and worth knowing before you clone. The readme says the release branch of the repository contains the latest stable release, while weekly snapshots are published to the develop branch, and that pull requests should in general be submitted against develop. The repository's default branch is develop. So a plain clone gets you a weekly snapshot rather than the latest stable release, and the stable artifact lives on a branch whose name is easy to mistake for a fork target. Contributing and consuming are deliberately different workflows on different branches, which is fine for a project with this release discipline but means picking the wrong one for a production dependency is a plausible mistake with no error to tell you.
Thirty-one modules, and the directory names are the feature list
With no feature section on the front page, the tree is the documentation. Thirty-one directories named for the library's own concerns separate out protocol implementations, among them modules for HTTP and its second version, a multiplexing transport, Thrift and its multiplexed variant, and clients for MySQL, PostgreSQL, Redis and Memcached. Alongside those sit infrastructure modules for the network layer, service discovery and request partitioning, and a whole observability cluster covering statistics, logging, a structured log sink, tracing bridges and an OpenCensus tracer. Then come cross-cutting modules for the core, experimentation, runtime toggles, tunables, gRPC context, plus example, integration and benchmark modules. Taking the core and one protocol rather than the whole stack is a supported shape, not a workaround.
Toggles and tunables are modules, which is the architectural tell
Two module names describe an approach to behaviour that most libraries leave to deployment. One is a toggle module and the other is a tunable module, sitting alongside an experimentation module rather than being absorbed into the core. What that signals is that changing runtime behaviour is a supported pattern in this codebase, not something bolted on afterwards. It matters for adoption because it changes who can flip a flag: if you can change a parameter at runtime, then a feature can be enabled per host without a new build going out, and a risky behaviour can be turned off quickly.
Two build systems, and scripts that manage the Netty version
The repository root carries both a Bazel build definition and an sbt build definition with a bundled launcher and a project directory, so the same sources are buildable two ways. That is ordinary for a library consumed both from source and from published artifacts, and the sbt launcher being committed means a contributor does not need a globally installed build tool. More telling are two shell scripts sitting beside them, one for linking the Netty version and one whose name ties it to Netty snapshot environments. So the dependency on the network layer is managed by scripts in the repository rather than only by a version declaration, which is the sort of coupling that matters when you are pinning a build across a long-lived service.
The adopter list is a short selection, not a census
The front page names six organisations using the library, including Twitter, Pinterest and ING Bank. It then points to a more complete list held on the release branch and invites organisations to add themselves by sending a pull request. That is the shape of the claim: the visible roster is a sample maintained by hand, and the fuller record lives elsewhere in the repository. So it is reasonable evidence that the library is used in production, but it should not be read as a complete picture of who depends on it or how they depend on it.
Editorial conclusion
finagle suits a Scala team running high-concurrency JVM services that want one client and server API across several wire protocols, and that values runtime toggles over shipping builds to change behaviour. It does not suit you if you rely on semantic versioning to reason about upgrades, because the project states it does not follow it and records breaks in a changelog instead. Before depending on it, read the changelog for the version you are moving to rather than the version number, and decide whether you want the stable branch or the weekly snapshots that sit on the default one.
Frequently asked questions
What is Twitter Finagle?
An extensible RPC system for the JVM, used to construct high-concurrency servers. It implements uniform client and server APIs across several protocols, is designed for high performance and concurrency, and most of its code is protocol agnostic so that implementing a new protocol is simpler.
What is Finagle, the library?
The same system, split across thirty-one module directories covering protocol implementations, infrastructure, observability and cross-cutting concerns. Artifacts are published to Maven Central under a Twitter group with a Scala version suffix in the artifact name, and documentation is split between a user guide and generated API documentation.
What does Finagle do for a server?
It provides the client and server plumbing for high-concurrency JVM services: uniform APIs across protocols, observability modules for statistics, logging and tracing, service discovery and partitioning, and modules for changing runtime behaviour through toggles and tunables without shipping a new build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/twitter-finagle)Star history chart for your README
[](https://hysenlabs.com/projects/twitter-finagle)Was this useful?