openllmetry-js: OpenTelemetry spans for LLM calls, with the import order that bites
Sister project to OpenLLMetry, but in Typescript. Open-source observability for your LLM application, based on OpenTelemetry
At a glance
- What is it?
- The TypeScript sibling of OpenLLMetry adds instrumentations for LLM providers, vector databases, and agent frameworks on top of OpenTelemetry, so traces land in whatever backend you already run. Ten destinations are listed as tested, three providers are not there yet, and the root package is a private monorepo shell sitting at version 0.0.1.
- Who is it for?
- This suits a team already running OpenTelemetry who want LLM calls to appear in the same trace as everything else, and who would rather not adopt a vendor-specific SDK just to get prompts and completions into their existing dashboard. It is a poor fit if you need a provider that is still marked as planned, and a poor fit if you are on an older version, since the change that stopped the SDK collecting its own telemetry landed in 0.21.1.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 150 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
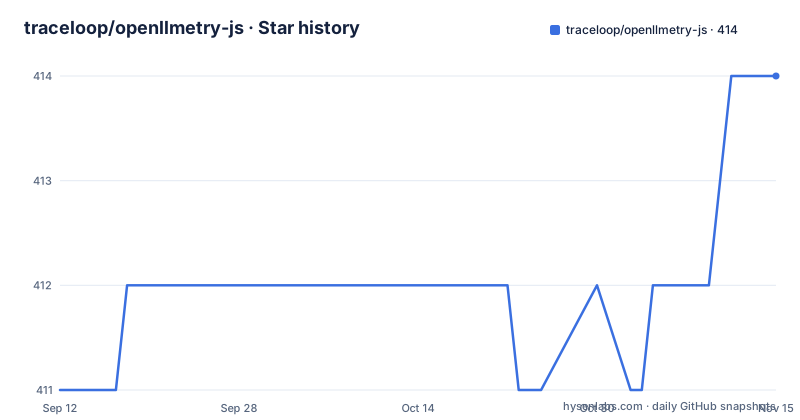
- traceloop/openllmetry-js414 ★ · +3
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| traceloop/openllmetry-js | 411 | 414 |
3 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two lines of setup, and the import order is the part that bites
The whole quick start is one install and two lines:
npm install --save @traceloop/node-server-sdkimport * as traceloop from "@traceloop/node-server-sdk";
traceloop.initialize();The instruction attached to that snippet is the one that causes the most confusion. The SDK has to be imported before any LLM module. Instrumentations that patch a provider's client work by wrapping the module as it loads, so an LLM import that is evaluated first means the wrapper never sees it, and you get an application with no LLM spans and no error to explain why.
That constraint is why the SDK is presented as a line you add at the top of your entry point rather than as something you initialise lazily inside a function. It also means that in a project with many entry files, each one needs the import in the right position.
There is one option worth knowing about before you start debugging. Running locally, you may want to turn off batching so traces show up as they happen:
traceloop.initialize({ disableBatch: true });After initialisation, the remaining decision is where to export, which is a separate configuration step rather than part of the call.
The SDK is a convenience layer, and the instrumentations stand on their own
There are two ways in, and the documentation is clear that the SDK is the easier one rather than the required one. The project ships standard OpenTelemetry instrumentations for LLM providers and vector databases, plus a Traceloop SDK that makes getting started easy while still outputting standard OpenTelemetry data. If you already have OpenTelemetry instrumented, you can add any of the instrumentations directly and skip the SDK entirely.
That distinction matters more than it sounds. The SDK is a convenience: it sets up a provider, a processor, and an exporter so that a new user sees traces without assembling a telemetry pipeline by hand. The instrumentations are the actual product, and they are ordinary OpenTelemetry instrumentation packages, which means they compose with whatever pipeline you already have rather than replacing it.
The stated motivation for building on OpenTelemetry at all is that it lets the output connect to existing observability solutions, and that is the reason the project is worth using even if you have no interest in the vendor behind it. Spans for a model call land in the same trace as a database query and an HTTP request, which is what makes cost and latency attributable to a specific step rather than to a request as a whole.
The semantic conventions the project defines are now part of OpenTelemetry itself, and the repository links the community discussion document on LLM semantic conventions for anyone who wants to follow or influence that work.
Ten destinations are listed as supported and tested, which is the compatibility statement
The export list is explicit about what has actually been tested rather than what should work in principle. Ten backends are marked supported: Traceloop, Dynatrace, Datadog, New Relic, Honeycomb, Grafana Tempo, HyperDX, SigNoz, Splunk, and the OpenTelemetry Collector.
The Collector being on that list is the one that generalises. If your backend is not in the ten, the Collector is the path to it, since a Collector can receive OpenTelemetry data and forward it to a destination that is not itself OpenTelemetry aware. The documentation points to the exporting guide for per-destination instructions rather than trying to keep configuration snippets in the repository.
The split between tested and expected is also present in the instrumentation coverage, and the documentation is upfront that the specific technologies are used to demonstrate concepts while the techniques themselves are not tied to them. In practice, the tested list is the one to plan against, because it is the list where somebody has confirmed the traces arrive intact.
Worth noting for anyone already invested in a backend: the value of this project is not the exporter, since the exporter is standard OpenTelemetry. The value is the span shape around a model call, and that shape is what the ten integrations have in common.
Three providers and two vector databases are still marked as planned
The coverage list uses two markers, a check and an hourglass, and the difference matters when you are choosing whether to adopt this.
Supported LLM providers are OpenAI, Azure OpenAI, Anthropic, Cohere, Vertex AI on GCP, and Bedrock on AWS. Marked as in progress are Replicate and HuggingFace. So the two major cloud platforms and the two largest model providers are covered, and the open hosting platforms are not.
Vector databases split differently. Pinecone, Chroma, and Qdrant are supported, while Weaviate and Milvus are marked as planned. That is worth checking carefully, because a team standardising on Weaviate or Milvus is in the unsupported column, and the practical consequence is that retrieval calls will not appear as spans even though the model calls around them will.
Frameworks are the narrowest category, with LangChain and LlamaIndex supported and nothing else listed. If your agent code calls a provider client directly rather than through one of those two, the provider instrumentation still covers the call, which is the more important half.
Beyond the LLM-specific instrumentations, the project relies on what OpenTelemetry already instruments upstream, so database calls, API calls, and the rest of a Node application are covered by the base library rather than by anything here.
The SDK stopped collecting its own telemetry at 0.21.1
There is a short section with an unusual amount of consequence in it. The project no longer logs or collects any telemetry in the SDK or in the instrumentations, and the instruction is to make sure you bump to version 0.21.1 and above.
That is a privacy change, and it is the kind that matters for a library whose whole job is to observe an application. An observability SDK that also reports back about itself is a second-order concern that a security review will find, and removing it is the right resolution. It also means older versions on your lockfile are not just outdated, they behave differently in a way that matters for compliance.
The practical consequence for an upgrade is that 0.21.1 is a floor, not just a version number. If you are consolidating dependencies and something in your graph pins an older release, you have a decision to make rather than a routine bump.
The release cadence around it is brisk. Three of the visible tags are 0.25.0, 0.26.0, and 0.27.0, with 0.25.0 and 0.26.0 three days apart and 0.27.0 about six weeks after that. The newest is 0.27.0 from 2026-05-29, and the last push to the repository is 2026-06-18, so the branch is a little ahead of the newest tag.
The root package is a private monorepo shell, and the version there is meaningless
The `package.json` at the repository root is not the package you install. Its name is the repository name, its version is 0.0.1, and it is marked private. The version that matters is the one on the published SDK, currently 0.27.0.
What the root file is for is orchestration. The build scripts run Nx across the workspace, one to build everything and one to build only what a change affected. A third script regenerates the evaluator models through a shell script in the scripts directory, and the dev dependencies for that include an OpenAPI parser and a TypeScript generator for schemas, which is how the provider and model metadata is kept current rather than hand written.
The workspace itself is pnpm based, with a workspace file and a lock file, and it also carries Lerna and Nx configuration alongside a shared TypeScript config and an ESLint flat config. So there are two orchestrators present in a monorepo, which is more tooling than a package this size strictly needs and is worth knowing if you are trying to work out why a build is slow.
Two version-control details are unusual enough to mention. A Husky directory and a commitlint config sit at the root alongside a conventional changelog tool configured for commitizen, so commit message format is enforced by a hook. And a file named for a v1 branch readme sits beside the main one, which is a marker that the OpenTelemetry 1.x line is still supported somewhere alongside whatever the current line is.
Editorial conclusion
This suits a team already running OpenTelemetry who want LLM calls to appear in the same trace as everything else, and who would rather not adopt a vendor-specific SDK just to get prompts and completions into their existing dashboard. It is a poor fit if you need a provider that is still marked as planned, and a poor fit if you are on an older version, since the change that stopped the SDK collecting its own telemetry landed in 0.21.1. Before you install, check three things: that your provider and your vector database are on the supported list rather than the planned one, since Replicate, HuggingFace, Weaviate, and Milvus are all still marked as in progress; that you can place the SDK import before every LLM module import in your entry file; and which export path you want, since batching is on by default and the traces will not appear immediately on a local run. The newest release is 0.27.0 from 2026-05-29 and the last push was 2026-06-18.
Frequently asked questions
What is OpenLLMetry?
It is a set of extensions built on OpenTelemetry that give observability over an LLM application, instrumenting calls to model providers and vector databases while still emitting standard OpenTelemetry data. This repository is the TypeScript implementation, maintained by Traceloop under the Apache 2.0 license.
What observability tools work with openllmetry-js?
Ten destinations are listed as supported and tested: Traceloop, Dynatrace, Datadog, New Relic, Honeycomb, Grafana Tempo, HyperDX, SigNoz, Splunk, and the OpenTelemetry Collector. Because the output is standard OpenTelemetry, the Collector is the route to a backend that is not in that list.
Why do I get no LLM spans after installing openllmetry-js?
The most common cause is import order. The SDK has to be imported before any LLM module, because the instrumentations wrap the provider client as it loads. On a local run, batching also hides traces, and traceloop.initialize({ disableBatch: true }) turns that off so spans appear immediately.
Does openllmetry-js send any data back to Traceloop?
No. The project states that it no longer logs or collects any telemetry in the SDK or in the instrumentations, and instructs users to make sure they are on version 0.21.1 or above, which is where that behaviour changed.
Which providers and vector databases does openllmetry-js not support yet?
Replicate and HuggingFace are marked as in progress among the LLM providers, and Weaviate and Milvus are marked as in progress among the vector databases. Pinecone, Chroma, and Qdrant are supported, as are OpenAI, Azure OpenAI, Anthropic, Cohere, Vertex AI, and Bedrock.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/traceloop-openllmetry-js)Star history chart for your README
[](https://hysenlabs.com/projects/traceloop-openllmetry-js)Was this useful?