Graphtage: dictionary keys always come back sorted, and every formatting example diffs a file against itself
A semantic diff utility and library for tree-like files such as JSON, JSON5, XML, HTML, YAML, and CSV.
At a glance
- What is it?
- Graphtage compares tree-like files semantically rather than line by line, across ten formats, and its matching cost varies by orders of magnitude depending on which strategy you pick. The documentation that explains the output options demonstrates all four of them with an input that produces no edits at all.
- Who is it for?
- Graphtage suits anyone comparing structured configuration files where line based diff is unreadable, and it is strong on that job: ten formats, cross format comparison, and match constraints written as Python expressions.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
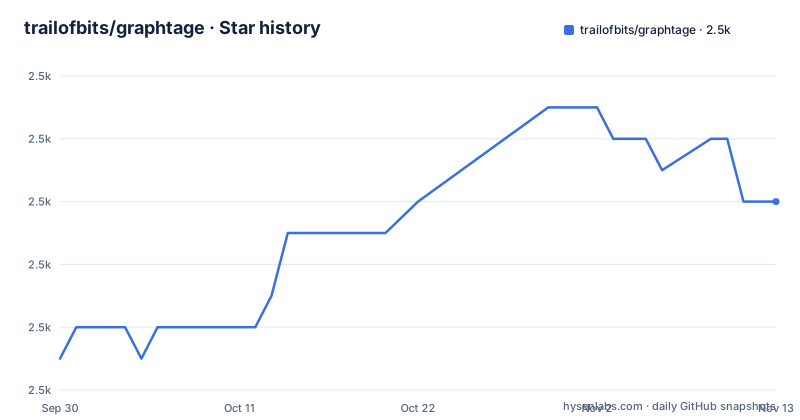
- trailofbits/graphtage2,492 ★ · +5
| Repository | 2026-09-30 | 2026-11-13 |
|---|---|---|
| trailofbits/graphtage | 2.5k | 2.5k |
5 Stars in the last 44 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every output formatting example diffs a file against itself
Four options control how the diff is laid out: no option, `--join-lists` or `-jl`, `--join-dict-items` or `-jd`, and `--condensed` or `-j`, which applies both. The four JSON blocks in the file show the same transformation in each case.
They also all show the same input. The text introducing them states that the file `{"foo": [1, 2, 3], "bar": "baz"}` is being diffed against itself, and none of the four blocks carries an edit mark. So the section teaches the layout options accurately and shows nothing about what any of them does to a real change.
The options themselves are unambiguous once described. The default pretty-prints with as many line breaks and indents as it can, joining lists suppresses the break after list items, joining dict items suppresses the break after key and value pairs, and condensed does both. What a reader cannot learn from these blocks is how an edit renders in each layout.
Two further options are about what gets printed rather than how: `--only-edits` or `-e` prints a list of edits instead of applying them, and `--edit-digest` or `-d` does the same with more concise, more readable context.
Your key order is discarded on the way in
Graphtage sorts the keys of every dictionary it reads, so the output orders keys alphabetically no matter how the input files order them. This is stated plainly and it applies to every format, because the analysis runs on an intermediate representation of the trees that is deliberately divorced from the file types.
That design is what makes cross format comparison work at all: you can diff a JSON file against a YAML file, and the output format can differ from both inputs, defaulting to the format of the first file and changing through `--format`. The cost of that flexibility is that a diff of two files with identical content in different key orders shows nothing, and a real change is rendered in an order you did not choose.
If key order is meaningful in your data, this is the first thing to check before reading a Graphtage diff as authoritative.
Three dictionary strategies with very different costs
By default Graphtage matches the values of key and value pairs that share a key, then tries to match all possible pairs of whatever elements remain. Matching two dictionaries against each other is the expensive part, and there are three strategies for it.
`--dict-strategy match` tries every pair of keys and values between the two dictionaries and produces a match of minimum edit distance. `--dict-strategy none` attempts nothing unless the keys are exactly equal. `--dict-strategy auto`, the default, matches values for identical keys first and then falls back on `match` for whatever is left. The short form is `-ds`, and `--no-key-edits` or `-k` is equivalent to `none`.
The file acknowledges the cost directly: the strategies are labelled most and least computationally expensive, and the note about matching dictionaries being hard comes with the observation that it becomes onerous for input files with huge dictionaries. A pull request is referenced as holding examples of how the three change the output, so the decision is visual rather than something to reason about in advance.
Unordered list matching skips CSV rows and XML or HTML children
`--ignore-list-order` treats list elements as an unordered collection, so moving an element is not an edit. Duplicates still count: `[1, 1, 2]` matches `[2, 1, 1]`, and neither matches `[1, 2, 2]`.
Two exceptions are named, and they are the ones you are most likely to hit. The rows of a CSV file and the children of an XML or HTML element stay ordered, and those two node types ignore `--no-list-edits` as well. So for those structures the option silently has no effect.
It also cannot be combined with `--no-list-edits` or `--no-list-edits-when-same-length`, because those two only apply to ordered lists. The second of them is the milder form: it behaves normally for lists of different lengths and like the stricter option for lists of the same length, which is an odd asymmetry to remember but a sensible one.
Thirty seconds against seven tenths, and a warning
This is the one place the file publishes a measurement. Two lists whose elements all match each other cost nothing to compare, however long they are. Comparing two lists that differ is more expensive, and the cost grows faster than the ordered comparison.
The stated figures are specific: matching 30 dictionaries where every element differs took about 30 seconds in one measurement, against 0.7 seconds without the option. That is roughly forty times for thirty elements, and the gap widens from there, which is exactly the shape you would expect from a combinatorial search.
Two things make this tolerable in practice. Graphtage logs a warning when a comparison is large enough for the difference to matter, so the tool tells you rather than leaving you to notice. And the cheaper alternatives exist as flags, so the expensive path is opt-in even though it is the default for dictionary remainders.
A missing dependency in fickling is patched with a conditional pin
The dependency list carries a comment that is worth reading in full, because it documents a defect in someone else's package.
    # Graphtage itself needs nothing from typing_extensions. fickling does: fickle.py imports
    # typing_extensions.Buffer on Python < 3.12 without declaring the dependency, so importing
    # graphtage.pickle fails on 3.10 and 3.11 unless something else installs it.
    "typing_extensions; python_version < '3.12'",
So the pickle support depends on a third party library that does not declare a dependency it needs on older interpreters, and Graphtage works around it by declaring the package only for Python below 3.12. The marker means nothing extra is installed on 3.12 and later, where the import is not needed.
That is a correct fix for a real problem and also a signal: pickle support rests on a chain the project does not control, and the comment is the only warning that this is the case.
The repository uses uv while the instructions use pip
Installation is one command.
$ pip3 install graphtageThat puts two commands on your path: `graphtage` for the diff itself, and `graphtage-git-diff`, the external diff driver, wired to `graphtage.git:main` in the package metadata. Working on Graphtage itself means installing the `dev` extra, which adds pytest, Ruff and Sphinx.
The repository itself does not use pip. Its tree carries a `uv.lock` rather than a pip requirements file, so the project's own dependency management runs through a different tool from the one it tells users to install with. That is not a problem, but it does mean the locked development environment and the documented consumer install are two separate things.
The build backend is hatchling with a floor of 1.21.0, the version number is dynamic rather than written in the file, and there is a `bindist/` directory at the root next to a `test/` directory.
Two and a half years between releases, and a research audience classifier
The release history has a gap in it. v0.3.1 is dated 2024-01-08. The next two tags, v0.4.0 and v0.5.0, are dated 2026-09-09 and 2026-09-16, a week apart. So the project went from an eleventh patch release to a new minor line after an interval of about twenty one months.
The branch was last pushed on 2026-09-24, so work is current, and the version is declared as dynamic in the package file rather than hard coded. The classifiers say Development Status 4, Beta, which matches a 0.x line.
The audience classifier says Science and Research, and the repository carries a citation file for that purpose. That is an odd label for a general purpose command line diff, and it is a clue about who the tool was built for: comparing large generated trees where a line based diff is unusable. The licence is LGPL-3.0-or-later, stated in the package metadata and matched by the classifier for the same licence.
Editorial conclusion
Graphtage suits anyone comparing structured configuration files where line based diff is unreadable, and it is strong on that job: ten formats, cross format comparison, and match constraints written as Python expressions. Before relying on it, understand that your output key order is not your input key order, that unordered list matching does not apply to CSV rows or to XML and HTML children, and that the default dictionary strategy can cost far more than the alternatives on large files. The unpinned Ruff and Sphinx bounds in the development extra and the exact pin on the documentation theme are worth knowing about if you build the docs yourself.
Frequently asked questions
What file formats can Graphtage compare?
JSON, JSON5, XML, HTML, YAML, TOML, INI, CSV, plist and Python pickle. The type of each input is inferred from its extension, or you can state it with a from and a to flag per format, or with a MIME type instead. Because the analysis runs on an intermediate representation, you can also diff a JSON file against a YAML file and format the output as something else entirely.
How do I install Graphtage and what does it add to my path?
Run pip3 install graphtage, which needs Python 3.10 or later and is tested against 3.10 through 3.14. You get two commands: graphtage for the diff utility and graphtage-git-diff, the external diff driver for git. To work on the project itself, install the dev extra, which adds pytest, Ruff and Sphinx.
Why does Graphtage reorder the keys in its output?
It sorts the keys of every dictionary it reads, so the output is alphabetical regardless of how the input files order them. That is what lets the output format differ from the input format, which is also why you can diff a JSON file against a YAML file. If key order carries meaning in your data, check that before treating a diff as authoritative.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trailofbits-graphtage)Star history chart for your README
[](https://hysenlabs.com/projects/trailofbits-graphtage)Was this useful?