ExLlamaV2 is archived: matching its extension to PyTorch
A fast inference library for running LLMs locally on modern consumer-class GPUs
At a glance
- What is it?
- ExLlamaV2 is a Python and CUDA inference library for running quantized LLMs on consumer GPUs, with an EXL2 format that mixes quantization levels inside one model and a dynamic generator with batching, prompt caching and KV cache deduplication. The README opens by declaring the project archived with development continuing on ExLlamaV3, and the recommended way to serve it is someone else's server.
- Who is it for?
- ExLlamaV2 fits someone who has a specific quantized model in EXL2 form, understands that the library compiles a Torch C++ extension against their local PyTorch, and is willing to serve it through TabbyAPI rather than build an API themselves. It does not fit someone starting fresh, since the README states the project is archived for now with development on ExLlamaV3.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
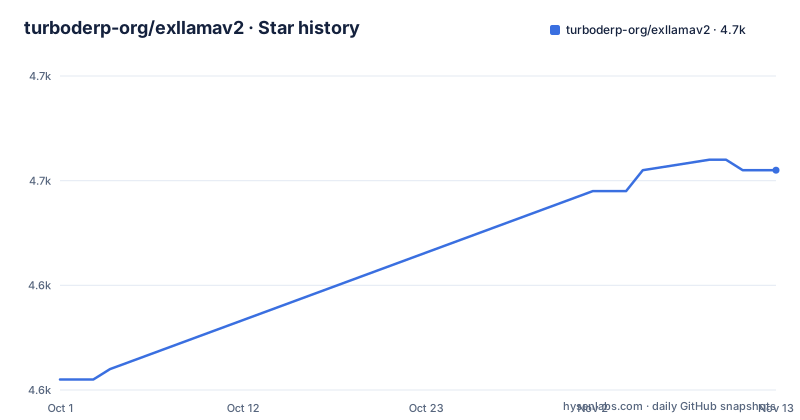
- turboderp-org/exllamav24,651 ★ · +20
| Repository | 2026-10-01 | 2026-11-13 |
|---|---|---|
| turboderp-org/exllamav2 | 4.6k | 4.7k |
20 Stars in the last 43 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first line of the README says the project is archived
Before anything else, there is a note at the top of the file: this project is archived for now, and development continues on ExLlamaV3, with a link to that repository.
Everything after that note describes ExLlamaV2, an inference library for running local LLMs on modern consumer GPUs.
So the state of this code is specific rather than general. It is not deprecated in the sense of being broken, and it is not finished. It is a version line that its author has moved past, with a successor named.
The commit history does not contradict that in a simple way. The three most recent releases are v0.3.2 in July 2025, v0.3.1 in May 2025 and v0.3.0 in May 2025, all in the 0.3 line, while the last push to the repository is dated 2026-03-04. So commits continued well after the last tag, which is the pattern of a project receiving fixes or maintenance without cutting new releases.
That is the first thing to weigh before reading the feature list. The features are still documented, but you are reading the documentation of a successor's predecessor.
Installing means compiling a Torch C++ extension against your PyTorch
There are three installation methods, and they differ in exactly one thing: when the CUDA extension gets built.
From source, the sequence is:
git clone https://github.com/turboderp/exllamav2
cd exllamav2
pip install -r requirements.txt
pip install .
By default this compiles and installs the Torch C++ extension named `exllamav2_ext` that the library relies on. You can skip that step with an environment variable:
EXLLAMA_NOCOMPILE= pip install .What that produces is called the JIT version. The Python components install without building the extension, and the extension is built the first time the library is used, then cached in `~/.cache/torch_extensions` for later runs.
From a release, you get prebuilt wheels containing the extension binaries, and the matching rules are stated bluntly: match your platform, your Python version, shown as `cp` in the filename, and your CUDA version. Crucially, you must also match the prebuilt wheel to your PyTorch version, because a PyTorch upgrade can change the extension ABI and make an existing wheel incompatible.
From PyPI, `pip install exllamav2` gives you the same JIT version described above.
So the choice is compile now, compile on first use, or download a binary that must match your PyTorch exactly.
That ABI constraint is the whole reason method 2 is fragile
The PyTorch ABI statement deserves more attention than one sentence usually gets, because it determines how you upgrade.
A Torch C++ extension is compiled against a specific PyTorch build. Its binary interface depends on the PyTorch build. The README warns that upgrades can break extension compatibility; use a matching wheel or rebuild and test the extension when changing PyTorch.
A wheel filename carries all four constraints at once. The example URL given is a v0.0.12 wheel tagged cu121 for cp311 on linux_x86_64, so the CUDA version, the Python ABI tag, the platform and implicitly the PyTorch build are all baked into the name.
Two more details from that section. The `py3-none-any.whl` file is the JIT version, which builds the extension on first launch, and the `.tar.gz` can also be installed the same way, building the extension during installation.
So there is a documented escape from the ABI problem: take the pure Python wheel and let it compile locally. It costs you a compiler and a CUDA toolkit at first launch, and it can avoid needing a prebuilt wheel matched to the new PyTorch version, provided the local source and toolchain are compatible.
The setup script builds eleven named extension sources, and has a HIP branch
The setup file is the clearest statement of what the library actually is.
The extension is registered as a `CUDAExtension` named `exllamav2_ext`, compiled from a list of source files under exllamav2/exllamav2_ext/: ext_bindings.cpp, ext_cache.cpp, ext_gemm.cpp, ext_hadamard.cpp, ext_norm.cpp, ext_qattn.cpp, ext_qmatrix.cpp, ext_qmlp.cpp, ext_quant.cpp, ext_rope.cpp, ext_stloader.cpp, and ext_sampling among them.
Those names map onto the parts of inference you would expect. ext_gemm is the matrix multiply, ext_qattn is quantized attention, ext_quant and ext_qmatrix handle the quantized weights, ext_rope is rotary position embeddings, ext_cache is the key and value cache, and ext_norm is normalization.
The flags differ by platform. On Windows the C++ flags are `/Ox`, elsewhere `-O3`, with `-ftime-report` and `-DTORCH_USE_CUDA_DSA` added to them in debug mode, and the CUDA flags are `-lineinfo` and `-O3`. There is an AMD branch too: when the detected torch version reports HIP, the CUDA flags gain `-DHIPBLAS_USE_HIP_HALF`.
Two more switches are read from the environment: `EXLLAMA_VERBOSE` and `EXLLAMA_EXT_DEBUG`. And if torch is not installed, the script prints that it cannot precompile unless torch is installed, and points at the JIT route.
EXL2 mixes quantization levels inside one model
The format is the feature that distinguishes this from a plain GPTQ loader.
ExLlamaV2 supports the same 4-bit GPTQ models as V1, and also a new EXL2 format. The format is based on the same optimization method as GPTQ and supports 2, 3, 4, 5, 6 and 8-bit quantization.
The important property is that the format allows for mixing quantization levels within a model. So different tensors in one model can sit at different bit depths.
That matters because sensitivity is not uniform across a network. A format that can vary per tensor can spend bits where they change behaviour. The performance table in the README lists EXL2 models at several bit widths per weight, including 3.0, 4.0 and 5.0 bpw for a 7B Llama2 and 2.5 bpw for a 70B Llama2, which is the granularity this feature produces.
The cost is compatibility. EXL2 is this project's format, so a model in it is not loadable by a loader that only reads GPTQ or GGUF, and the choice of format is a choice about which tools can open your weights.
One dynamic generator replaced two, and dropped FP8 caching
The generator consolidation is stated as a change in v0.1.0 and later, alongside paged attention through Flash Attention 2.5.7 or newer.
The dynamic generator supports all the inference, sampling and speculative decoding features of the previous two generators, consolidated into one API, with one exception: FP8 cache. The Q4 cache mode is still supported and is said to perform better anyway, with a link to doc/qcache_eval.md.
So the consolidation came at the cost of the FP8 cache mode, and the project's own position is that you are not losing anything by using Q4.
The new generator also brings dynamic batching, smart prompt caching, K/V cache deduplication and a simplified API, and it has one entry point with a prompt argument:
output = generator.generate(prompt = "Hello, my name is", max_new_tokens = 200)The same call takes a list for batched generation, and an asynchronous job class exists for streamed output under asyncio. The examples directory shows those shapes separately, including inference_async.py, inference_stream.py, inference_dedup.py, inference_cfg.py, inference_lora.py, inference_speculative.py and inference_tp.py, alongside bulk_inference.py, minimal_chat.py, chat.py and several multimodal examples.
The recommended server is TabbyAPI, not this repository
If you want an API rather than a library, the README points elsewhere.
TabbyAPI is named as the official and recommended backend server for ExLlamaV2, and it provides an OpenAI-compatible API for local or remote inference, with extended features including HuggingFace model downloading, embedding model support and support for HuggingFace Jinja2 chat templates. The wiki link given is a getting started page on the TabbyAPI repository.
The other integrations are named as well. ExUI is a simple, standalone single-user web UI that serves an ExLlamaV2 instance directly, with chat and notebook modes. text-generation-webui supports it through the `exllamav2` and `exllamav2_HF` loaders. lollms-webui supports it through the exllamav2 binding. And TabbyAPI itself is described as FastAPI based, OpenAI style, and compatible with SillyTavern and other frontends.
So the ecosystem is arranged with the server outside the library, which is a sensible split: the inference engine is hard to keep stable, and a thin HTTP layer in another repository is easier to change.
A small built-in alternative exists too. A console chatbot is included, run with `python examples/chat.py -m /path/to/model -mode llama -gs auto`, replacing `/path/to/model` with your model directory. The `-mode` option selects the prompt format, `raw` gives a chatlog style that works with base models, `-modes` lists the available formats and `-sp` sets a custom system prompt.
Editorial conclusion
ExLlamaV2 fits someone who has a specific quantized model in EXL2 form, understands that the library compiles a Torch C++ extension against their local PyTorch, and is willing to serve it through TabbyAPI rather than build an API themselves. It does not fit someone starting fresh, since the README states the project is archived for now with development on ExLlamaV3. Before installing, match your CUDA and PyTorch versions exactly if you take a prebuilt wheel, because the extension ABI may be incompatible after a PyTorch upgrade, and note that the newest release is 0.3.2 from July 2025 while the last commit is dated 2026-03-04.
Frequently asked questions
how to install exllamav2
There are three methods. From source, run git clone, cd exllamav2, pip install -r requirements.txt and pip install ., which compiles the Torch C++ extension by default. Set EXLLAMA_NOCOMPILE= to skip that and get the JIT version instead, which builds on first use and caches in ~/.cache/torch_extensions. From PyPI, pip install exllamav2 gives the same JIT version. From a release, take a prebuilt wheel matching your platform, Python, CUDA and PyTorch versions.
exllamav2 vs v3
ExLlamaV3 is the successor. The ExLlamaV2 README opens with a note saying the project is archived for now and that development continues on ExLlamaV3. The most recent ExLlamaV2 releases are v0.3.2, v0.3.1 and v0.3.0, all from May and July 2025, while the last commit is dated 2026-03-04.
exllamav2 vs gguf
The README does not compare the two. What it states is that ExLlamaV2 supports the same 4-bit GPTQ models as V1 plus its own EXL2 format, which is based on the same optimization method as GPTQ, supports 2, 3, 4, 5, 6 and 8-bit quantization, and allows mixing quantization levels within a model. The last point is what makes EXL2 a distinct format rather than a naming variant.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/turboderp-org-exllamav2)Star history chart for your README
[](https://hysenlabs.com/projects/turboderp-org-exllamav2)Was this useful?