The wheel exllamav3 tells you to install is v0.0.6, and the PyPI package compiles kernels on first import
An optimized quantization and inference library for running LLMs locally on modern consumer-class GPUs
At a glance
- What is it?
- A read of turboderp-org/exllamav3: six CUDA extras that all declare the same torch floor, an extension that builds twice depending on how you install, a Windows flag list written out of hard won compiler errors, and a server that lives in another repository.
- Who is it for?
- exllamav3 is worth the setup cost for anyone running quantized models locally on consumer hardware, because the pieces that normally bite, tensor and expert parallelism, cache quantization, CPU offloading for MoE models, and speculative decoding, are all in one library with a maintained extension. What to check before committing is the install path rather than the model support.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
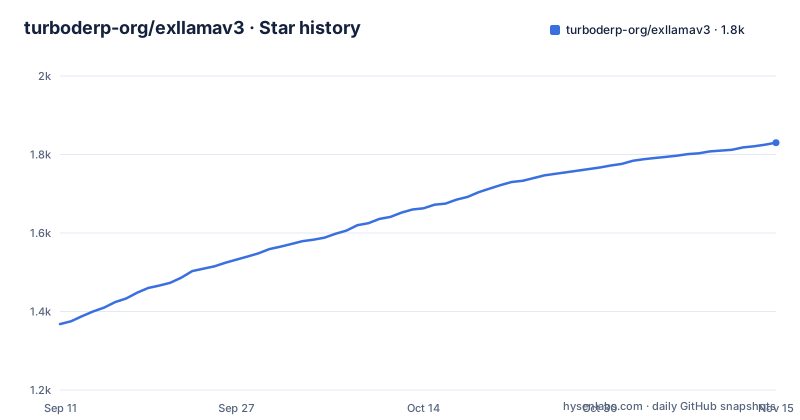
- turboderp-org/exllamav31,830 ★ · +462
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| turboderp-org/exllamav3 | 1.4k | 1.8k |
462 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The documented wheel command installs version 0.0.6
The recommended install is a prebuilt wheel from the releases page, and the example given is this single line:
pip install https://github.com/turboderp-org/exllamav3/releases/download/v0.0.6/exllamav3-0.0.6+cu128.torch2.8.0-cp313-cp313-linux_x86_64.whlRead that filename as four separate decisions. The tag is the package version, 0.0.6, which is a long way behind the 1.5.x releases the project has been cutting. `cu128` is the CUDA build. `torch2.8.0` is the torch version the extension was compiled against. `cp313-cp313` is the CPython 3.13 ABI, so it will not install on 3.10 even though that is the floor declared in the manifest. `linux_x86_64` is the platform. Nothing in that line picks any of those for you, and nothing in it fails helpfully if you are on a different combination.
The other short path is `pip install exllamav3` from PyPI, and it comes with a warning attached: that package contains no prebuilt extension and needs the CUDA toolkit plus build prerequisites, which the text names as VS Build Tools on Windows, gcc on Linux, and python development headers.
An isolated build cannot see torch, so the extension compiles on first import
This is the part of the install that costs you time, and the explanation is precise about why. Both `uv sync` and `pip install .` build in an isolated environment where your torch is not visible, so those two paths install the extension sources and compile them at first import instead. The docs put the cost at a few minutes, once per torch version, which is the important qualifier: change your torch version later and the compile happens again.
The precompiled alternative is to run `pip install --no-build-isolation .` in an environment that already has torch, or to use a release wheel. The escape hatch in the other direction is an environment variable, and the build script states both branches plainly:
precompile = "EXLLAMA_NOCOMPILE" not in os.environ
...
if precompile and not torch:
    print("Cannot precompile unless torch is installed.")
    print("To explicitly JIT install run EXLLAMA_NOCOMPILE= pip install <xyz>")
So with `EXLLAMA_NOCOMPILE` set, the install skips compilation and defers to the first import. Two other switches sit in the same block: `EXLLAMA_VERBOSE` and `EXLLAMA_EXT_DEBUG`, the latter adding debug information flags. The practical shape of all this is that a working exllamav3 environment is defined less by a package version than by the pair of a torch build and a compiled extension that match each other.
All six CUDA extras declare the same torch constraint
The package declares six flavor extras: `cu124`, `cu126`, `cu128`, `cu129`, `cu130` and `cu132`. You pick the one matching your CUDA build. What is in them is where it gets odd:
cu124 = [
    "torch>=2.6.0",
]
cu126 = [
    "torch>=2.6.0",
]
cu128 = [
    "torch>=2.6.0",
]
cu129 = [
    "torch>=2.6.0",
]
cu130 = [
    "torch>=2.6.0",
]
cu132 = [
    "torch>=2.6.0",
]
Every one of the six is the same single constraint. The extras do not select a torch version, they select an index, and the text says so directly: the flavor extra picks the index, and by default torch resolves to the latest version on that index that satisfies `>=2.6.0`. Which torch you end up with is a function of the index and the day you install.
The documented way to take control is a thin project beside your checkout, which keeps the pin out of the exllamav3 manifest:
[project]
name = "my-exllamav3-dev"
version = "0.1.0"
requires-python = ">=3.10.11"
dependencies = [
    "exllamav3[cu130]",   # select correct CUDA version
    "torch==2.13.0",      # pin the exact torch version you need
]

[tool.uv.sources]
exllamav3 = { path = "../exllamav3", editable = true }
Note the two different torch versions named in this documentation: 2.13.0 in the pin recipe, 2.8.0 in the wheel example. Nothing reconciles them, which is the point of the recipe: the pin is yours to choose, and the extras will not choose it for you.
The Windows flag list is a list of compiler errors that already happened
The extension build lives in `setup.py` while the metadata lives in `pyproject.toml`, and the build script is where the platform knowledge sits. The Windows branch reads as a sequence of fixes, each one with the failure it prevents recorded next to it:
extra_cflags += ["/Ox", "/Zc:preprocessor", "/DWIN32_LEAN_AND_MEAN", "/DNOMINMAX"]
extra_cuda_cflags += ["-DWIN32_LEAN_AND_MEAN", "-DNOMINMAX", "-Xcompiler=/Zc:preprocessor"]
`WIN32_LEAN_AND_MEAN` is the usual way to keep windows.h from dragging in the whole API surface, and the comment next to `NOMINMAX` says it is not sufficient on its own: windows.h otherwise defines function-like `min` and `max` macros that break every `std::min` and `std::max` call site parsed after the header, and the flag is applied globally so it holds regardless of include order in any translation unit. The same comment explains an absence. No standard flag is added on Windows because torch's own `cpp_extension` appends one unconditionally on that path, and a second `-std` argument is a fatal nvcc error rather than an override.
Two more details in that file are worth knowing. The CUDA flag logic is loaded by file path with `importlib` rather than imported, with the comment explaining that the package is not importable yet at that point, and the same module is shared with the JIT build. And the torch guard reads `if torch := importlib.util.find_spec("torch") is not None:`, where the walrus binds the result of the comparison, so the name `torch` holds a boolean rather than the module spec. The surrounding code then tests that boolean in the places where it means is torch installed, which is why the behavior is right even though the name holds something other than what it suggests.
The dependency list exists in two places and the two do not match
`pyproject.toml` declares the runtime dependencies as torch 2.6.0 or newer, tokenizers 0.21.1 or newer, numpy 2.1.0 or newer, rich, typing_extensions, safetensors 0.3.2 or newer, ninja, pillow, pyyaml, marisa_trie, pydantic and llguidance 1.7.0 or newer, followed by one platform marked entry: `triton-windows` when the platform is Windows.
`requirements.txt` at the top level lists exactly the same set in the same order, minus the Windows entry. That last omission is the one that matters, because of how the Windows requirement is described: the attention, cache and recurrent kernels are Triton, and ExLlamaV3 does not import without it. So a Windows install driven from `requirements.txt` rather than from the package metadata will fail at import, not at install, which is a worse place to find out.
Everything else in the list is unpinned to a floor, with four packages carrying no version constraint at all, so an environment built today and rebuilt in six months will not resolve to the same versions. Optional groups add more surface: an `eval` group pulling transformers, datasets, gguf, llama-cpp-python, human_eval pinned exactly, matplotlib, numpy, pandas, seaborn and tabulate, and an `examples` group with blessed, prompt_toolkit, pyperclip, requests and a second pydantic entry. Build requirements are setuptools, wheel and ninja, and ninja appearing in both the build and runtime lists is what the first import compile actually uses.
A library that also ships measurement scripts and a science directory
The top level of the tree is wider than a Python library usually is. Alongside the package directory `exllamav3/` there is `convert.py`, four scripts with an `sc_` prefix, `sc_measure.py`, `sc_optimize.py`, `sc_rfn_probe.py` and `sc_trace.py`, a `science/` directory, and separate trees for `eval/`, `examples/`, `doc/`, `tests/` and `util/`.
The four requirements files follow the same logic. `requirements.txt` covers the runtime, `requirements_eval.txt` the evaluation extras, `requirements_examples.txt` the example scripts, and `requirements_sam.txt` stands on its own for the segmentation path, which matches the image oriented examples in the tree such as `imgdesc.py`, `imgsearch.py`, `imgsearch_gallery.py` and `multimodal.py`.
The examples directory is also where two of the dependency choices become visible. There are scripts named `constrained_generation_llg.py` and `constrained_generation_formatron.py` sitting next to a declared dependency on `llguidance`, plus `chat_templates.py`, `chat.py`, `chat_console.py` and `chat_io.py` for the several ways a chat loop gets driven, and `banned_strings.py` and `overrides.yaml` for constraining what comes out. `examples/transformers_integration.py` is named in the feature list as the Transformers plugin.
One packaging detail closes the loop. The version is declared dynamic and read out of the package itself, `version = { attr = "exllamav3.version.__version__" }`, so what a build reports comes from the source tree rather than from a tag. The README also points at a `dev` branch for in progress features, separate from the default branch, which means the two lines can report different versions of the same library.
The server is a different repository, and the docs say so up front
The first callout in the documentation is a redirect rather than an instruction. Looking for a server is answered with TabbyAPI, named the official and recommended backend server, with the list of what it provides: an OpenAI compatible API for local or remote inference, HF model downloading, embedding model support and HF Jinja2 chat templates. Its startup script manages and installs prerequisites. None of that lives in this repository.
What stays here is the inference library, and the feature list is specific about the parts that need hardware. Quantization is EXL3, based on QTIP, plus 2 to 8 bit cache quantization. Parallel inference is flexible tensor parallel and expert parallel for consumer setups. CPU offloading lets large MoE models run on limited GPU resources, with AVX2 and AVX512 support. Generation covers continuous dynamic batching, speculative decoding and multimodal input. The integration story is broad HF model support, the Transformers plugin, and the OpenAI compatible API by way of the other project.
The practical reading is that this repository is the engine and TabbyAPI is one consumer of it, so a team deciding how to serve quantized models locally is choosing between two dependencies rather than one. The version pairs also come from different cadences: releases here are 1.5.3, 1.5.2 and 1.5.1 within the last two weeks of the recorded pushes, while the library still has to build against whatever torch and CUDA your machine already carries.
Editorial conclusion
exllamav3 is worth the setup cost for anyone running quantized models locally on consumer hardware, because the pieces that normally bite, tensor and expert parallelism, cache quantization, CPU offloading for MoE models, and speculative decoding, are all in one library with a maintained extension. What to check before committing is the install path rather than the model support. Read the wheel filename, because it encodes the CUDA build, the torch version, the Python ABI and the platform in one string, and nothing selects the right one for you. Decide early whether you accept a first import that spends minutes compiling, or whether you want the release wheel, since the PyPI package cannot precompile inside an isolated build environment. And if you were planning to serve it, the answer is that the server is TabbyAPI, maintained in a separate repository that this documentation points at rather than ships. Anyone who just wants a hosted endpoint, or who cannot install a CUDA toolchain, should look elsewhere before starting.
Frequently asked questions
exllamav3 vs ollama, how do they compare?
This repository does not compare itself with Ollama and holds no information about it. What it does name is TabbyAPI as the official and recommended backend server, providing an OpenAI compatible API for local or remote inference, plus HF model downloading, embedding model support and HF Jinja2 chat templates.
Why does importing exllamav3 take minutes the first time?
Installed from PyPI or built with `pip install .` or `uv sync`, the build happens in an isolated environment where your torch is not visible, so the extension sources are installed and compiled at first import instead. The docs put the cost at a few minutes once per torch version, and offer `pip install --no-build-isolation .` or a release wheel as the precompiled path.
What is EXL3 in exllamav3?
EXL3 is the quantization format the library is built around, described as based on QTIP, and it is paired with separate 2 to 8 bit cache quantization. The documentation opens with a link to a dedicated EXL3 quantization section rather than folding it into the feature list.
Does exllamav3 work on Windows without extra setup?
It needs the triton-windows package, declared as a dependency in the manifest for Windows, because the attention, cache and recurrent kernels are Triton and the library does not import without it. Note that this entry is not present in requirements.txt at the top level, so installing from that file on Windows leaves you without it.
How do I pin a specific torch version for exllamav3 development?
Create a thin project next to your checkout that takes exllamav3 as an editable local path with a CUDA extra, and declare the exact torch version in its own pyproject.toml. The documented example pins torch 2.13.0 with the cu130 extra and points uv at the local directory, which keeps the pin out of the exllamav3 manifest.
Can exllamav3 run a large MoE model on a small GPU?
CPU offloading is one of the listed capabilities, described as letting large MoE models run with limited GPU resources, with AVX2 and AVX512 support. Inference can also be split across devices with tensor parallel and expert parallel modes, and batched continuously during generation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/turboderp-org-exllamav3)Star history chart for your README
[](https://hysenlabs.com/projects/turboderp-org-exllamav3)Was this useful?