umbertogriffo/rag-chatbot pins a llama.cpp build number in compose and keeps two version numbers
RAG (Retrieval-augmented generation) ChatBot that provides answers based on contextual information extracted from a collection of Markdown files.
At a glance
- What is it?
- This is a local RAG stack: llama.cpp for generation, Sentence Transformers for embeddings, Chroma for storage, a FastAPI backend and a Node frontend. The interesting parts are the places where the documentation and the files disagree, including a 4096 token context window against a design built around context overflow, a CUDA version mismatch, and a Python ceiling the prerequisites do not mention.
- Who is it for?
- This project is a credible reference for a fully local RAG deployment, and its incremental indexing and its refusal to take LangChain as a dependency are the parts worth copying. Two things decide whether it runs for you: the image tag is a pinned llama.cpp build number that will not move on its own, and the embedding model is baked into the vector space, so changing it means a full rebuild.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 156 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
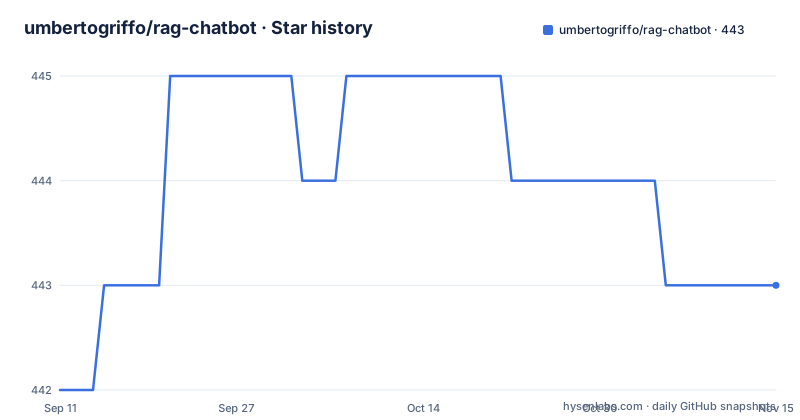
- umbertogriffo/rag-chatbot443 ★ · +1
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| umbertogriffo/rag-chatbot | 442 | 443 |
1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
pyproject says 0.7.0, the env template says 0.1.0, and Python has a ceiling
Three numbers in the configuration do not agree with each other or with the prose.
The packaging metadata declares version = "0.7.0" for a project named chatbot with the description "RAG ChatBot". The environment template that ships at the top level declares VERSION="0.1.0". A backend that reports its own version to clients would be reading the second one, so the version a consumer sees and the version of the code are different strings.
Python is the sharper mismatch. The prerequisites say Python 3.12+, which reads as a floor with nothing above it, while the dependency block says:
python = ">=3.12,<3.13"The upper bound is real, and it comes from the pinned dependency set rather than from a stated policy: torch is pinned to ~=2.10.0, transformers to ~=4.57.6, numpy to ~=2.4.4, and every other dependency uses a compatible release operator. Python 3.13 will be rejected by the resolver even though the prerequisites appear to invite it.
The same file fixes the lint rules: Ruff with a line length of 120, indent width 4, and an exclusion list covering the virtualenv, the Ruff and pytest caches, the docs directory, the frontend directory, and backend/alembic/versions. That last exclusion tells you the migration history is generated code and is not meant to be formatted. There are no GitHub releases for the repository, so pinning has to happen against a commit, and the last push on the branch is dated 2026-06-12.
The compose file hardcodes a llama.cpp build number and says so in a TODO
The inference server is a container, and the image is pinned to a build number rather than a release:
image: ghcr.io/ggml-org/llama.cpp:server-cuda-b9501Above that line is a TODO saying the image tag should be loaded from an environment variable or .env file, with a link to the Docker Compose documentation on variable interpolation. So the pin is a known rough edge left in place deliberately, and the practical consequence is that llama.cpp updates reach you only when someone edits the compose file.
The sampling and memory flags are all set in the command block, which is where the real configuration lives. Generation runs at temperature 0.6 with top-p 0.95, top-k 20 and min-p 0.00. Memory is quantised on both axes with --cache-type-k q8_0 and --cache-type-v q8_0 under a unified --kv-unified, flash attention is on, and --fit is enabled so the model fits the device. Two of those deserve attention: --fit decides the placement, and the context is set with --ctx-size 4096, which is a small budget for a system whose whole job is stuffing retrieved passages into the prompt.
Thinking is disabled at the server level through --chat-template-kwargs with enable_thinking set to false, which pairs with the MODEL_REASONING=False setting and the unused-then-present think tags in the environment file. The service reserves all NVIDIA GPUs, exposes 8080 on the host with the server bound to 0.0.0.0, and health is checked with curl against /health every 30 seconds with a 60 second start period and five retries. Two sibling files exist for the other cases, docker-compose.metal.yml for Apple Silicon and docker-compose.ci.yml for continuous integration, and the Makefile selects between them with start_llama_server_cuda and start_llama_server_metal.
The prerequisites ask for CUDA 12.4 and the pinned wheel index is cu126
The hardware requirement is stated as a GPU supporting CUDA 12.4 or later, or Apple Silicon of the M series. The torch pin points somewhere else:
[[tool.poetry.source]]
name = "pytorch"
url = "https://download.pytorch.org/whl/cu126"
priority = "explicit"
That index is the CUDA 12.6 wheel set, and it is marked explicit so it takes priority over PyPI. The dependency itself is declared twice with different sources by platform: ~=2.10.0 from the pytorch index on anything that is not darwin, and ~=2.10.0 from PyPI on darwin. So a Linux install silently asks for CUDA 12.6 wheels while the prerequisites tell you 12.4 is enough, and a Mac install never consults that index at all.
The container stack has its own version requirement, Docker 24.0.6 or later and Docker Compose 5.0.2 or later, with the NVIDIA Container Toolkit listed as optional and needed for CUDA support. That optionality is what makes the two setup paths different. make setup_cuda creates the environment, installs dependencies with NVIDIA acceleration, and starts the CUDA compose file, while make setup_metal does the same for macOS with Metal acceleration only. Both are documented as also starting the llama.cpp server locally through Docker compose, and both begin by running a migration step.
Two tested configurations are named in the disclaimer: Ubuntu 22.04.2 LTS on a Lenovo Legion 5 Pro with a 12th Gen Intel Core i7-12700H and an NVIDIA GeForce RTX 3060, and macOS Sonoma 14.3.1 on a MacBook Pro M1 from 2020. Anything else is pointed at the llama.cpp issue tracker when the models will not load.
Retrieval rewrites the question with an LLM before it searches
The pipeline has more stages than the usual picture suggests. A Memory Builder component loads Markdown pages from the docs folder, divides them into smaller sections, computes embeddings for those sections with Sentence Transformers models used for semantic search, and stores them in Chroma. Chunking uses a RecursiveCharacterTextSplitter that was taken from LangChain and refactored so that LangChain is not a dependency, which is a deliberate choice rather than an accident.
The query path then adds a step most examples skip. Because the original question is not always the best thing to retrieve with, the system first prompts an LLM to rewrite the question, and only then performs the retrieval augmented reading. The chat history is persisted and considered as context, with CHAT_HISTORY_LENGTH set to 2 in the environment template, so the last couple of turns follow a new question.
The retrieval numbers are all in that template. NUM_RETRIEVALS is 2, CHUNK_SIZE is 1000 and CHUNK_OVERLAP is 50, the embedding model is jinaai/jina-embeddings-v5-text-small-retrieval, and the uploaded file whitelist is ALLOWED_UPLOAD_EXTENSIONS=[".md"], matching the Markdown only premise. WebSocket messages are capped at 10485760 bytes for the streaming answer.
One dependency contradicts that last restriction. The pinned set includes docling with the vlm, rapidocr and easyocr extras, which is an OCR and document conversion stack, while the upload path accepts Markdown files only. The library is there for a reason the whitelist does not describe, since unstructured is also pinned with its md extra for parsing.
Two strategies for context overflow, and a 4096 token window to survive
Context overflow is treated as a first class design problem rather than an afterthought, and the document names two strategies. Create And Refine the Context synthesises a response sequentially through all retrieved contents. Hierarchical Summarization of Context generates an answer for each relevant section independently and then combines those answers hierarchically.
Only one of them is visible in the configuration. The environment template sets SYNTHESIS_STRATEGY="tree-summarization", which corresponds to the hierarchical approach, and the tree naming matches the combine answers into answers shape of that strategy. The other strategy has no key in the template, so switching to it means knowing a value the sample configuration does not show.
The reason the file discusses this at length is the window itself. The server is started with a context size of 4096 tokens, and the generation budget in the environment template is MAX_NEW_TOKENS=512, which leaves under 3600 tokens for a system prompt, two chat history turns, two retrieved chunks of up to 1000 tokens each with 50 tokens of overlap, and the question. The strategies exist because that arithmetic does not scale, and adding NUM_RETRIEVALS or CHUNK_SIZE without changing the strategy or the window is how a pipeline starts losing the middle of its context.
The default model is a quantised eight billion parameter instruct model, Meta-Llama-3.1-8B-Instruct-Q4_K_M, downloaded from a GGUF file hosted on Hugging Face, and it is served locally so nothing leaves the machine.
Incremental indexing keys on a document hash and a SQLite chunk map
Rebuilding the vector store on every document change would make the project unusable against a growing corpus, so the index is built incrementally and the mechanism is spelled out. Every chunk carries document level metadata consisting of a source document ID and a version hash. When a document changes, chunks for that document alone are regenerated, the old ones are deleted by metadata filter, and the new ones are inserted. An ingestion pipeline diffs source documents against what is already indexed using those hashes, so only changed or new documents are processed.
Deletions need their own bookkeeping, because a metadata filter cannot tell you what to remove without help. A separate mapping table from doc_id to chunk_ids is kept in a SQLite database, which is what makes targeted removal possible instead of scanning the whole store. That database is distinct from the application schema, which is handled by Alembic.
The warning attached to this design is the one that matters most for planning. If the embedding model is ever swapped, the index has to be rebuilt from scratch, because the vector spaces will not be compatible. With the default embedding model being a specific jina model version, and NUM_RETRIEVALS and chunk sizes tuned around it, that is a full re-embed of the corpus rather than a configuration change, which is why the note asks you to plan for it early.
The repository layout matches the pipeline. There is a backend directory and a frontend directory, a docs folder that the Memory Builder reads, a vector_store directory, a models directory that is mounted into the container, an experiments directory, a notes directory holding the technical write ups linked from the documentation, and a version directory alongside scripts and tests.
The Makefile declares seven phony targets and defines sixteen
The header and the body of the build file disagree:
.PHONY: check update test clean start migrate_dbOnly those seven names are declared phony. install_dependencies, install_pre_commit, setup_cuda, setup_metal, start_llama_server_cuda, start_llama_server_metal, stop_llama_server, tidy and check-formatting are all defined below without appearing in that list, so a file with one of those names would stop the target from running. The documented entry order is also enforced in prose: Setup is to be run as the init command, or after Clean.
What the init path does is worth reading as a unit. Both setup_cuda and setup_metal depend on install_dependencies, which creates a .venv in project, tells Poetry to use it, and installs without the root package; then install_pre_commit runs pre-commit install twice, once for hooks generally and once explicitly for the pre-commit hook type; then migrate_db runs, and only then does the compose file come up. So a database migration happens before any server exists.
That migration target is `cd backend && poetry run python migration.py`, a plain script, while Alembic is a pinned dependency and a backend/alembic/versions directory is excluded from formatting. Two migration paths coexist in the repository, and the Makefile calls the script one. The start target shells out to start.sh, which is documented to bring up the backend and the frontend while making sure the backend is ready before the frontend launches. tidy runs Ruff format followed by Ruff check with fix, clean removes the virtualenv, compiled Python files, __pycache__ directories and both caches, and test runs pytest with debug level logging.
Two dependency choices carry their own commentary. grpcio is pinned to exactly 1.78.0 with an inline note that 1.78.1 is used by chromadb and is yanked, so the pin is a workaround for an upstream packaging event rather than a preference. The openai client is pinned on the backend side even though generation is served by a local llama.cpp process, and the same configuration block points LLAMA_SERVER_BASE_URL at http://localhost:8080 with a timeout of 300 seconds.
Editorial conclusion
This project is a credible reference for a fully local RAG deployment, and its incremental indexing and its refusal to take LangChain as a dependency are the parts worth copying. Two things decide whether it runs for you: the image tag is a pinned llama.cpp build number that will not move on its own, and the embedding model is baked into the vector space, so changing it means a full rebuild. Before anything else, check the CUDA version your drivers actually support against the wheel index the project pins, confirm your Python is 3.12 rather than merely 3.12 or newer, and budget for the model download, since the default is an eight billion parameter GGUF fetched from Hugging Face.
Frequently asked questions
What does umbertogriffo/rag-chatbot need before it will run?
Python 3.12, Poetry 2.3.0 or later, Docker 24.0.6 or later with Docker Compose 5.0.2 or later, and either a GPU supporting CUDA 12.4 or later or Apple Silicon of the M series. The interface adds Node 22.12 or later and Yarn 1.22.
Which models does umbertogriffo/rag-chatbot use by default?
Generation uses Meta-Llama-3.1-8B-Instruct-Q4_K_M, a GGUF file downloaded from Hugging Face and served by llama.cpp locally. Embeddings use jinaai/jina-embeddings-v5-text-small-retrieval through Sentence Transformers.
Does umbertogriffo/rag-chatbot depend on LangChain?
No. The RecursiveCharacterTextSplitter class was taken from LangChain and refactored so that Markdown files can be chunked without adding LangChain as a dependency.
What happens to the umbertogriffo/rag-chatbot index if I change the embedding model?
It has to be rebuilt from scratch, because the vector spaces will not be compatible with each other. The documentation asks you to plan for that early.
How does umbertogriffo/rag-chatbot handle a full context window?
Two strategies are named, Create And Refine the Context and Hierarchical Summarization of Context. The environment template selects the hierarchical one with SYNTHESIS_STRATEGY set to tree-summarization, and the server runs with a context size of 4096 tokens.
What file types can umbertogriffo/rag-chatbot accept as a source document?
Markdown, since the Memory Builder reads Markdown pages from the docs folder and the upload whitelist in the environment template lists .md as the only allowed extension.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/umbertogriffo-rag-chatbot)Star history chart for your README
[](https://hysenlabs.com/projects/umbertogriffo-rag-chatbot)Was this useful?