The quick start omits the database the shipped compose file expects
An automated generation tool for AI video, AI anime, AI short dramas and AI motion comics.
At a glance
- What is it?
- AI Story is a self-hosted Django and Celery application that walks a story theme through script, storyboard, stills, camera moves and video, with a model per stage. The compose file in the documentation, the compose file in the repository, and the environment example each describe a different deployment.
- Who is it for?
- Use it if you intend to run the stack yourself and you already know which model service each stage should call, because the multi-model routing is the part worth having and the part least described. Before the first `up`, read `docker-compose.yml` rather than the quick start: it is the only one of the three configurations that names a database, and it will not start on an empty environment without MySQL host and password.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
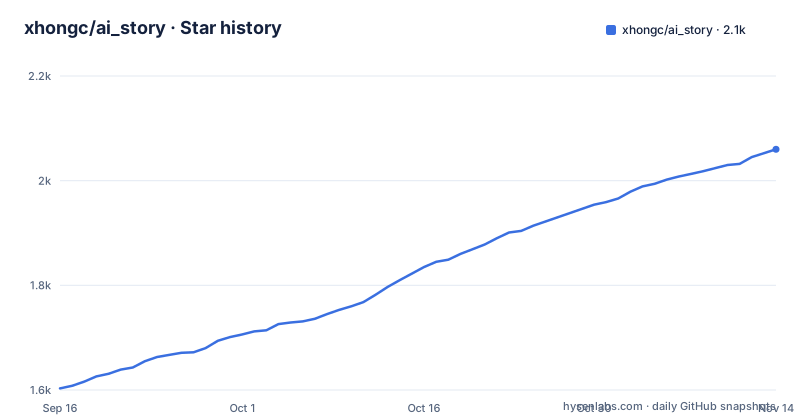
- xhongc/ai_story2,060 ★ · +457
| Repository | 2026-09-16 | 2026-11-14 |
|---|---|---|
| xhongc/ai_story | 1.6k | 2.1k |
457 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The quick start is not the compose file in the repository
The documentation tells you to create a compose file locally, and prints one:
services:

  # Redis缓存和消息队列
  redis:
    image: redis:7-alpine
    restart: unless-stopped

  # Django后端
  backend:
    image: xhongc/ai_story-backend
    restart: unless-stopped
    volumes:
      - ./data/backend:/app/backend/data
      - ./storage:/app/storage
    environment:
      - DJANGO_SETTINGS_MODULE=config.settings.production
      - REDIS_HOST=redis
    depends_on:
      - redis

  # Celery Worker
  celery:
    image: xhongc/ai_story-backend
    working_dir: /app/backend
    command: celery -A config worker -l info -P gevent
    restart: unless-stopped
    volumes:
      -
Two things stand out. It pulls a prebuilt image where the repository's own `docker-compose.yml` builds from `docker/Dockerfile` and `docker/frontend.Dockerfile`, and the celery `volumes` list ends at a single dash, so the worker mounts nothing in the printed version. The launch commands are short:
# 启动所有服务
docker-compose up -d

或者

docker compose up -d

# 创建管理员账号
docker-compose exec backend python backend/manage.py createsuperuser
Only one address is given for any of this: the frontend at `http://localhost:3000`.
Three files describe three different databases
The shipped `docker-compose.yml` passes five MySQL variables to both the backend and the worker: `MYSQL_DB_NAME`, `MYSQL_USER` defaulting to root, `MYSQL_PASSWORD`, `MYSQL_HOST` and `MYSQL_PORT` defaulting to 3306. Each is written with a default expression that expands to an empty string when the variable is unset, so a fresh checkout with no database configured passes an empty host and lets the framework decide. The environment example says something different again, with `DATABASE_URL=sqlite:///db.sqlite3` and `DEBUG=True`. The printed quick start mentions no database at all. So there are three stories: a MySQL-oriented compose file that expects you to supply credentials, an environment template pointing at a local SQLite file, and a quick start that stays silent. `mysqlclient` is a declared dependency, which means the MySQL driver is compiled during install and needs system libraries, while nothing in the quick start warns that. The compose file also starts the backend under gunicorn bound to `0.0.0.0:8010` with two gevent workers and a 3600 second timeout, a port the documentation never mentions.
Celery is pinned to a beta and Django to a 2021 release
The dependency list in `pyproject.toml` is where the project's real constraints live, and it is worth reading closely. It requires Python 3.11 or newer, then pins `celery==5.5.0b2`, which is a beta build, and `django==3.2.15` with `djangorestframework==3.14.0`, both from the older end of their lines. It also lists two JSON Web Token packages at once, `djangorestframework-jwt` at 1.11.0 and `djangorestframework-simplejwt` at 5.3.1, and the project depends on `pyjianyingdraft`, `mysqlclient`, `cython`, `gevent`, `gunicorn` and `daphne` alongside Redis, Celery beat and Celery results extensions. The style is mixed, with `==` on the framework pins and `>=` almost everywhere else. The lock file resolves that into exact versions and says how it was made: it was compiled by uv from the project file, so the two documents can drift apart whenever the project file changes and nobody recompiles. A beta queue worker behind a four-year-old Django is the combination you are signing up for when you build this.
The Celery worker only starts from one directory
One failure mode is documented with its exact error text, which saves a debugging session: the Celery service has to be started from `/app/backend`, otherwise it reports `Unable to load celery application. The module config was not found.` Both compose files honour that, setting `working_dir: /app/backend` on the worker. The rest of the worker line differs between them, though. The documentation runs `celery -A config worker -l info -P gevent`, which asks for the gevent execution pool explicitly, while the repository's compose file runs `celery -A config worker -l info` and lets the worker pick its own pool, even though the backend service in that same file is explicitly launched with `-k gevent`. The compose file also mounts `./backend` into the worker so code changes take effect without rebuilding, while the printed version mounts `./data/backend` and `./storage` on the backend service instead. Neither version mounts storage into the worker, which is where generated images and clips would land.
What answers on port 3000 is the admin panel
The compose file describes its frontend in one comment: linknow at the root, ai_story admin at `/admin`. So the address the quick start hands you, `http://localhost:3000`, is the static frontend, and the application's own interface sits under `/admin` behind a superuser you create with `manage.py createsuperuser`. The environment example shows what the pipeline talks to. Under a heading for the page agent and OpenCode there is `AGENT_SERVER_BASE_URL=http://127.0.0.1:9002`, `AGENT_SERVER_USERNAME=opencode`, an empty `AGENT_SERVER_PASSWORD`, an empty `MCP_ACCESS_TOKEN`, `AGENT_MODEL_PROVIDER_ID=opencode` and `AGENT_MODEL_ID=big-pickle`, plus a `LINKNOW_REGISTRATION_INVITE_CODE=change-me`. In other words the model calls the application makes are routed through a local agent server on port 9002 rather than issued directly to a provider, and the template ships that password and token blank. Anyone who fills those in has to decide the authentication story themselves.
Per-stage load balancing is the feature the page under-describes
The generation flow is six stages in a fixed order: theme in, script rewrite, storyboard split, image generation, camera-move planning, video generation, done, with progress shown live and any stage pausable, resumable and retryable. The interesting part is what sits underneath each stage. Every stage can hold several models, and the model configuration section offers load balancing by round robin, random, weight, or least load, alongside a connection test, usage statistics with cost analysis, and rate-limit settings. That is what makes the pipeline more than a fixed chain, and it is also the part with the least detail on how a failed call moves to the next model or what a rate limit does to a running job. The platforms named for the visual stages are Stable Diffusion, DALL-E and Midjourney for stills and Runway and Pika for video, and the text stages mention OpenAI and Claude, so the keys for all of them belong in that same configuration.
Export hands you an editor draft, and two features are unfinished
The dependency that explains the export step is `pyjianyingdraft`, and the project section describes export as video compositing and subtitle generation. Read together, the compositing stage produces an editable draft for a Chinese short-video editor rather than rendering finished video inside the app, which is consistent with a stack that has no ffmpeg dependency declared. Two features are marked incomplete by the project itself. Director mode, described as finer storyboard and video control, is labelled as still in development, and the finished-video examples are not in the repository at all: the page points you at a video account and tells you to search it. A section of suggested scenarios fills the space with one-line pitches about bedtime stories and a cat turned into a palace drama. Licensing is stated in prose rather than in a file: the page names CC BY-NC-SA 4.0, allows personal study and non-commercial use, requires the same licence for derivatives, forbids commercial use, and gives an email address for commercial authorisation. No LICENSE file sits at the top of the tree.
Editorial conclusion
Use it if you intend to run the stack yourself and you already know which model service each stage should call, because the multi-model routing is the part worth having and the part least described. Before the first `up`, read `docker-compose.yml` rather than the quick start: it is the only one of the three configurations that names a database, and it will not start on an empty environment without MySQL host and password. Read `pyproject.toml` too, since a beta Celery build and a 2021 Django are what will actually be installed. Two features are unfinished by the project's own account, the director mode is marked in development, and the licence is non-commercial share-alike stated only in prose, with a contact address for commercial authorisation.
Frequently asked questions
How do you start AI Story?
The documented path is a compose file with Redis, a Django backend, a Celery worker and a frontend, started with `docker-compose up -d` or `docker compose up -d`, then an admin account created through `docker-compose exec backend python backend/manage.py createsuperuser`. The printed compose file pulls prebuilt images while the repository's own version builds from `docker/Dockerfile`.
Does AI Story need a database to run?
The repository's `docker-compose.yml` passes MySQL settings to the backend and worker, with `MYSQL_USER` defaulting to root and `MYSQL_PORT` to 3306, and `mysqlclient` is a declared dependency. The environment example instead sets `DATABASE_URL=sqlite:///db.sqlite3`, and the quick start does not mention a database at all.
Why does the AI Story Celery worker fail to start?
The documented cause is the working directory. The worker must run from `/app/backend`, otherwise it reports `Unable to load celery application. The module config was not found.` Both compose files set `working_dir: /app/backend`, while they differ on the execution pool and on which paths get mounted.
What Python and framework versions does AI Story pin?
`pyproject.toml` requires Python 3.11 or newer, pins `celery==5.5.0b2`, a beta build, along with `django==3.2.15` and `djangorestframework==3.14.0`, and lists both `djangorestframework-jwt` and `djangorestframework-simplejwt`. `requirements.txt` resolves those into exact versions and was compiled by uv from the project file.
Is AI Story free for commercial use?
No. The page states a CC BY-NC-SA 4.0 licence, which allows personal study and non-commercial use, requires derivative works to carry the same licence, and forbids commercial use without authorisation, with an email address given for commercial licensing. The licence is stated on the page only; no LICENSE file appears at the top of the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xhongc-ai-story)Star history chart for your README
[](https://hysenlabs.com/projects/xhongc-ai-story)Was this useful?